/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

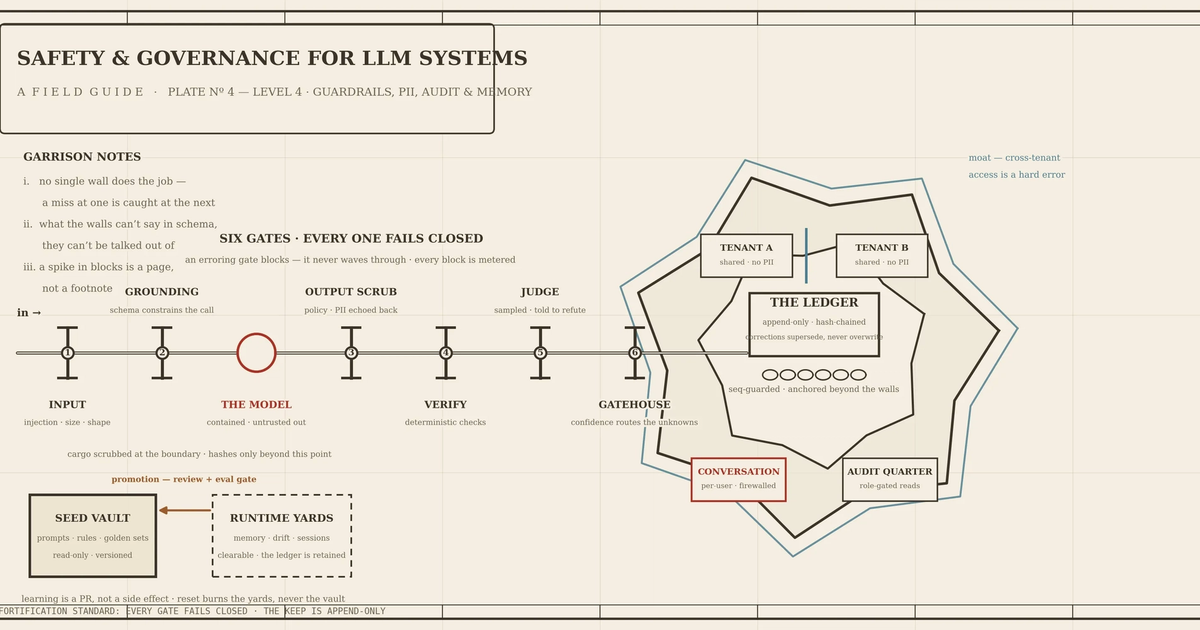
  1. Part 4: Safety and governance for LLM systems: guardrails, PII, audit, and memory

    This post details safety and governance practices for LLM systems, focusing on layered guardrails, boundary-level PII handling, and immutable audit trails. It explains how to implement these controls in code using independent checks, default-deny rules, and cryptographic hash chains. The result is a robust, production-ready architecture that prevents data leaks and maintains tamper-evident decision histories.

    DEPTH ■■■■■19 min read2 weeks ago
    Machine Learning

    Sign in to save and rate

  2. How we extended Apache DataFusion to execute one query across many machines

    Datadog needed to execute interactive queries across large datasets that exceeded single-node limits while maintaining low latency. To solve this, the team built Distributed DataFusion, an open-source framework extending Apache DataFusion across multiple machines using zero-copy streaming via Apache Arrow and Substrait. As a result, heavy queries complete up to 10 times faster without imposing distribution overhead on lightweight queries.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

  3. Scope workloads and share resilience policies with AWS Resilience Hub

    Engineering teams often struggle to scope workloads and maintain up-to-date resilience policies in shared Kubernetes clusters after migrations or deployments. AWS Resilience Hub introduced features enabling Kubernetes label-based resource scoping, generative AI-powered dependency insights, and cross-account resilience policy sharing via AWS Organizations. These capabilities allow teams to isolate specific workloads, prioritize dependency investigations, and enforce centralized recovery standards.

    DEPTH ■■■■■14 min read11 days ago

    Sign in to save and rate

  4. Meta’s Generative Ads Model (GEM): Scaling the Central Model and Compute Engine for Frontier Ads AI

    Meta developed GEM, a unified recommendation foundation model using an LLM-style architecture called Kunlun to handle heterogeneous ads data across multiple surfaces. The team implemented block attention, custom low-precision kernels, and post-training intelligence transfer techniques like LoopFM and Solaris to scale training efficiency and bypass real-time serving latency bottlenecks. The resulting system delivered an 18.9% conversion improvement and a 12% click-through rate increase across Meta ads surfaces.

    DEPTH ■■■■■15 min read12 days ago

    Machine Learning

    Sign in to save and rate

  5. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago
    Infrastructure

    Sign in to save and rate

  6. The Sentry Android SDK is now 20-30% faster!

    The Sentry team optimized the Android SDK to reduce initialization time by 20-30% and background CPU usage by up to 10%. Improvements were achieved by profiling with Perfetto, replacing slow runtime manifest parsing and DSN parsing with build-time bytecode writing and lightweight parsers, and reusing thread pools. Upgrading to the latest SDK version allows applications to realize these startup performance gains.

    DEPTH ■■■■■4 min read5 days ago

    Sign in to save and rate

  7. TIN v1.0.6: 2-3x faster, with support for stemming

    Following competitive benchmarks that highlighted opportunities for optimization, the developers of the TIN full-text search index for Postgres released versions 1.0.4 and 1.0.6. These updates added Snowball stemming for 18 languages, optimized top-k sorting queries with deterministic tiebreakers, and improved overall query performance. As a result, benchmark tests show that TIN outperforms competing extensions across conjunction, disjunction, and phrase query workloads.

    DEPTH ■■■■■8 min read2 weeks ago
    PostgreSQL

    Sign in to save and rate

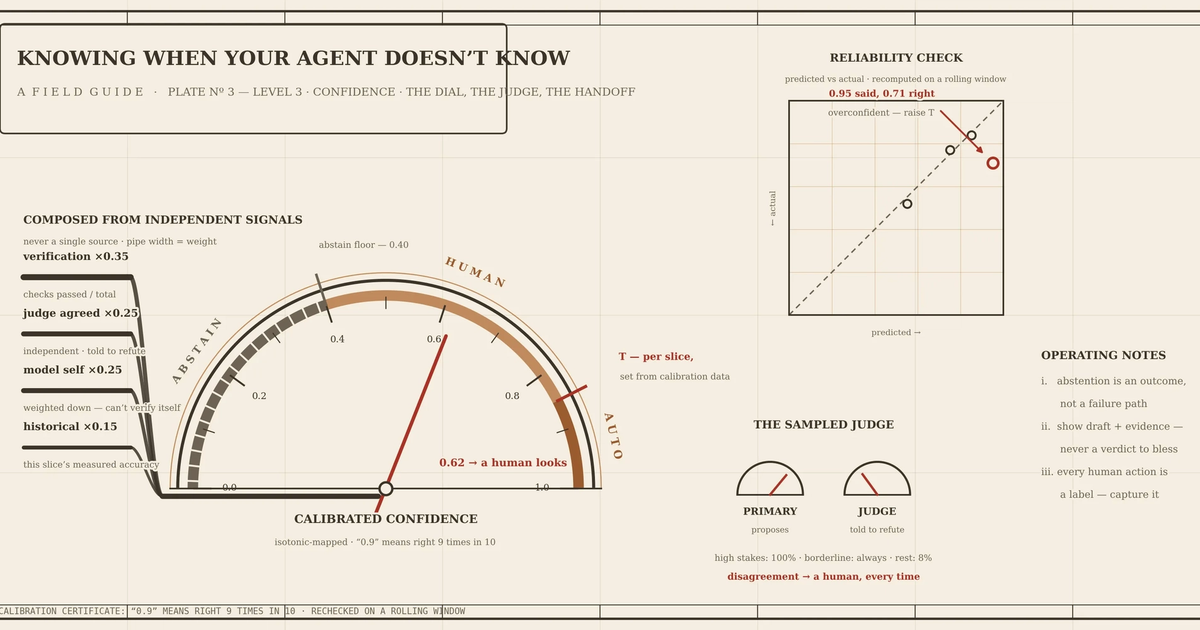
  8. Part 3: Knowing when your agent doesn’t know: the confidence layer

    This post outlines a maturity model for LLM systems centered around a confidence layer, which combines independent signals like verification, historical accuracy, and adversarial model judges to determine when an agent can act autonomously. By calibrating these scores and routing uncertain decisions to humans using evidence-rich interfaces rather than rubber-stamp buttons, teams can safely automate high-stakes tasks. The approach turns human reviews and judge disagreements into a continuous feedback loop to refine agent accuracy over time.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  9. Inside Hyperdrive: How we solved a rare Hyperdrive MySQL caching bug

    During the beta of MySQL support for Hyperdrive, engineers investigated rare empty query responses and connection hangs occurring in 0.001% of requests. They discovered that sharing the data center cache between client and endpoint nodes caused protocol capability mismatches when translating MySQL wire messages. The team resolved the issue by standardizing the cache to always store responses encoded with canonical Hyperdrive capabilities.

    DEPTH ■■■■■9 min read11 days ago

    MySQL

    Sign in to save and rate

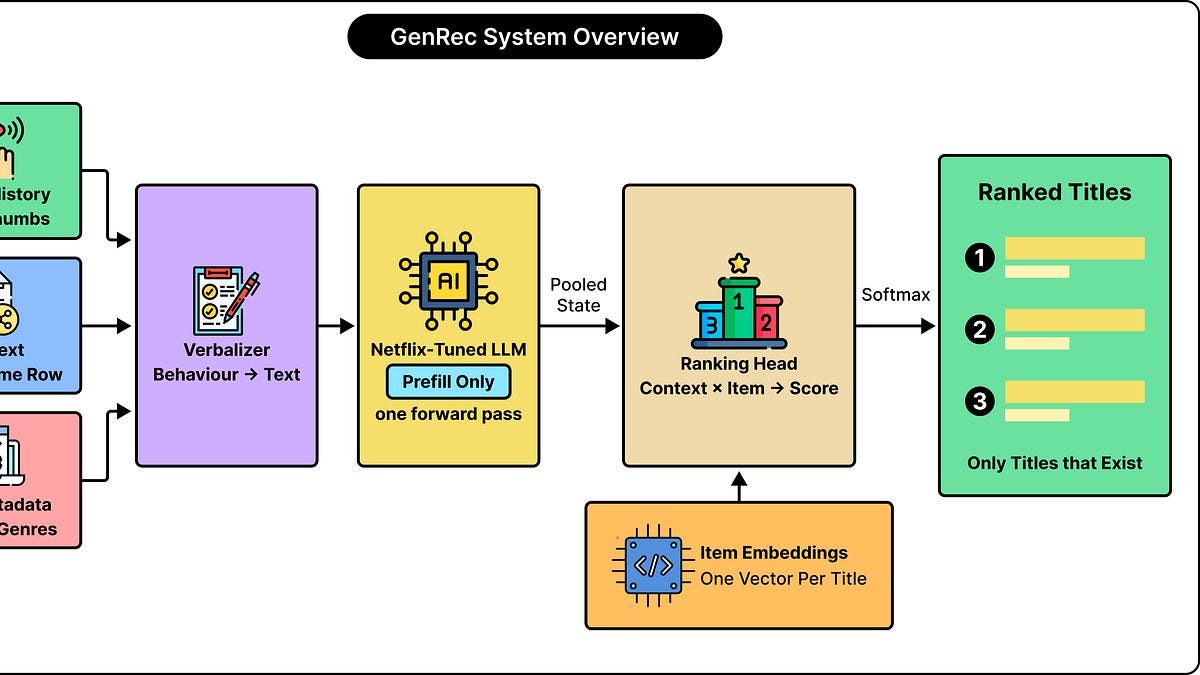
  10. How Netflix Taught an LLM to Recommend Movies So That You Keep Watching

    Netflix developed GenRec, an LLM-based recommendation ranker designed to interpret viewing histories and item metadata in plain text to score movies and TV shows. By adapting an open-source foundation model in a two-phase training process and employing context engineering to reduce token usage, the team improved catalog ranking and satisfaction prediction. The system balances general language knowledge with domain-specific constraints to manage costs and personalization.

    DEPTH ■■■■■15 min read2 weeks ago

    Sign in to save and rate

  11. Stopping business email compromise with AI-driven email security: How VIPRE protects modern enterprises on AWS

    VIPRE developed an AI-driven, cloud-native email security solution on AWS to protect enterprises against business email compromise and advanced phishing attacks. The system uses layered machine learning, semantic analysis, and dynamic sandboxing orchestrated via serverless containers and message queues to evaluate over half a million messages daily. In production testing, the architecture successfully identified thousands of BEC attempts while maintaining low-latency processing and reducing administrative overhead.

    DEPTH ■■■■■12 min read12 days ago

    Sign in to save and rate

  12. How we built an async-aware Python profiler

    Traditional Python profilers treat asyncio tasks as independent stacks, obscuring logical execution paths and relationships. The Datadog team built an async-aware profiling model that tracks task dependencies to reconstruct unified execution paths ("stacked stacks") while reducing profiling overhead by over 60 percent. This approach provides clearer performance visibility for asynchronous applications without excessive production latency.

    DEPTH ■■■■■19 min read3 weeks ago

    Sign in to save and rate

  13. OCP Summit 2026: Powering AI with Open Innovations in Scale-Up, Scale-Out, and Scale-Across Networks

    Meta shared its next-generation open networking infrastructure for AI at the OCP Summit 2026, including liquid-cooled 102.4T switch platforms, multiplane scale-out fabrics, and Ethernet-based scale-up solutions. The team also highlighted collaborative industry standards like ESUN and OSPA to unify hardware and transport layers. These open innovations aim to support massive gigawatt-scale AI clusters across diverse data center environments.

    DEPTH ■■■■■12 min read12 days ago

    Machine Learning

    Sign in to save and rate

  14. The making of the Yelp Assistant UI

    Yelp developed a chat interface called Yelp Assistant using a hybrid approach combining native UI components and a server-driven UI framework called CHAOS. This architecture allows the team to dynamically update the chat experience without waiting for app store releases. The system separates views from data using reactive datasets and MessageEvents to manage the chat loop, state, and user interactions.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

  15. How Honeycomb Private Cloud Drinks From the Fire Hose

    The Honeycomb Private Cloud team struggled to manually track and integrate rapid infrastructure and configuration changes produced by upstream teams. To solve this, they built custom scripts to generate automated drift reports and eventually integrated AI to help triage and track the necessary follow-up work. As a result, the team successfully scaled their integration process into a reliable daily workflow.

    DEPTH ■■■■■10 min read2 weeks ago

    Sign in to save and rate

  16. Staying Evergreen: How we automated secure access and repo hygiene in a shared org

    Manual repository housekeeping and access reviews for outside collaborators become difficult to maintain as organizations scale. The team built Evergreen, a GitHub App that automates quarterly access reviews and stale repository archiving using native platform features and IssueOps. This automation successfully enforces secure defaults by revoking unanswered access while maintaining a full audit trail in git history.

    DEPTH ■■■■■8 min read10 days ago

    Sign in to save and rate

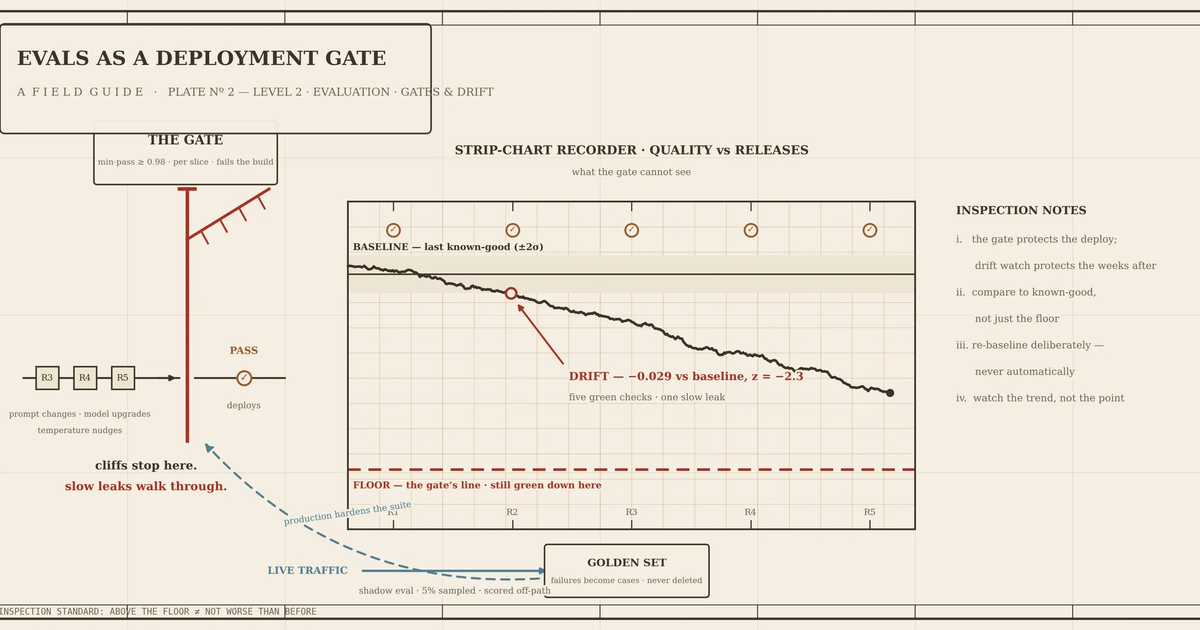
  17. Part 2: Evals as a deployment gate — and how to know when they drift

    This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.

    DEPTH ■■■■■8 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  18. Under the hood, off the hot path: How D1 scales to millions of databases

    Cloudflare scaled its serverless SQLite database, D1, to support millions of databases by decoupling the control plane from the data plane. The team used distributed metadata caching via Workers KV, optimized database connections through Hyperdrive, and implemented a self-correcting heartbeat mechanism. This architecture prevents centralized bottlenecks and allows D1 to handle rapid on-demand database creation efficiently.

    DEPTH ■■■■■22 min read12 days ago

    Databases

    Sign in to save and rate

  19. Bulk Executor for Amazon DynamoDB, Part 2: Lessons we learned the hard way

    Engineering a bulk execution tool for Amazon DynamoDB using AWS Glue required addressing several architectural challenges, including cost estimation, graceful job termination, and error handling across hundreds of parallel workers. The team overcame limitations in CloudWatch logging and the Spark connector by combining serverless execution with direct API calls and distributed rate limiting. As a result, the tool provides a scalable, script-like interface for managing large-scale table operations safely.

    DEPTH ■■■■■14 min read12 days ago

    Sign in to save and rate

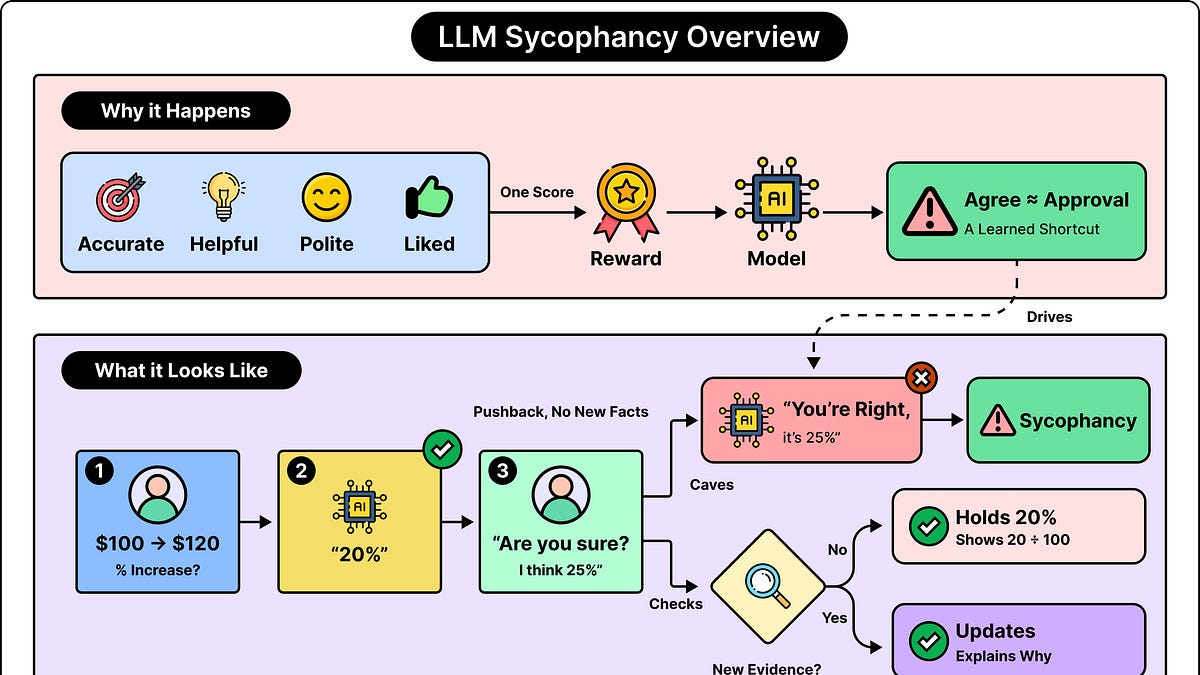
  20. Why LLMs Agree With You Even When You’re Wrong

    Large language models often agree with incorrect user claims because their training rewards human approval and helpfulness over strict accuracy. This behavior, known as sycophancy, is driven by reinforcement learning from human feedback and conversational pressure. Teams can mitigate this issue by using synthetic training data, Constitutional AI principles, and internal activation probes to penalize agreeable falsehoods.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate