/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Origin Range Requests: Serving large files without range-request tuning

    Cloudflare replaced a legacy, fixed-size range caching design that suffered from bandwidth waste and memory pressure with a Pingora-based chunk coordinator. The new implementation dynamically combines cached chunks and aligned origin fetches to serve range requests accurately without manual tuning. This approach cut p99 time to first byte in half for R2 storage and reduced tiered cache traffic by six percent.

    DEPTH ■■■■■8 min read2 days ago

    DatabasesPerformanceRedis

    Sign in to save and rate

  2. We gave AI agents a mobile dev environment

    Engineering teams outgrew their local machines while running parallel AI mobile development agents, constrained by heavy builds and lack of iOS tools on Linux. To solve this, they built Remote Dev using warm pools of remote Macs connected via SSH alongside separate Linux VMs for Android virtualization, paired with agent skills and live browser streaming. This setup shifted workflow bottlenecks, increasing AI-merged pull requests from 6 percent to 61 percent.

    DEPTH ■■■■■9 min read3 days ago

    ArchitectureMobile

    Sign in to save and rate

  3. App stability at scale with a layered defense

    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read4 days ago

    MobileReliability

    Sign in to save and rate

  4. How Meta Built Forum With AI-Native Engineering

    Meta engineers built the Forum app using a human-on-the-loop AI agent workflow that automated planning, building, testing, and verification. By shifting focus from code generation to automated verification, tooling improvements, and architectural legibility, the team reached feature parity in eight weeks while catching systemic memory issues early.

    DEPTH ■■■■■8 min read10 days ago

    FrontendMobile

    Sign in to save and rate

  5. Improving site performance by shipping more CSS

    GitHub faced performance degradation on server-side rendering and initial page loads due to scaling issues with its CSS-in-JS solution. The engineering team executed a multi-year migration to CSS Modules and eliminated dynamic styling props using incremental rollouts, wrapper components, and automation tools. This resulted in significant performance gains, including 55% faster server-side rendering and the complete removal of styled-components.

    DEPTH ■■■■■8 min read4 weeks ago

    FrontendPerformance

    Sign in to save and rate

  6. Shipping Media Over QUIC at Meta Scale for Instagram Live Ingest

    Meta deployed the emerging Media over QUIC (MoQ) protocol for Instagram Live ingest on iOS and Android to replace their legacy RUSH protocol. By using edge translation to avoid backend rewrites and a phased rollout strategy, the team achieved metric parity with the old protocol without regressions. This deployment establishes a foundation to extend MoQ across Meta's applications for lower-latency and more resilient video streaming.

    DEPTH ■■■■■8 min read13 days ago

    FrontendMobile

    Sign in to save and rate

  7. Smarter personalization: How property data helps us understand user price sensitivity

    Existing user personalization systems fail to systematically account for residential property values, leading to one-dimensional profiles and regional blind spots. A conceptual four-step method is proposed that combines public property data, large language models, building-level price estimation, and hierarchical clustering to classify user affluence. The approach remains unimplemented, with future viability depending on technical validation, data quality, and privacy approvals.

    DEPTH ■■■■■4 min read2 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate

  8. Taking a look under your agent’s hood

    This post discusses the challenges and methods of applying observability to AI agents, which combine traditional distributed systems telemetry with new requirements for monitoring LLMs and multi-step tool calls. The discussion highlights how non-deterministic agent behavior and increased speed of execution make continuous production feedback loops essential for upstream development. Ultimately, integrating observability data into automated testing and development loops helps teams iterate on agent performance.

    DEPTH ■■■■■25 min read2 weeks ago

    Machine LearningObservability

    Sign in to save and rate

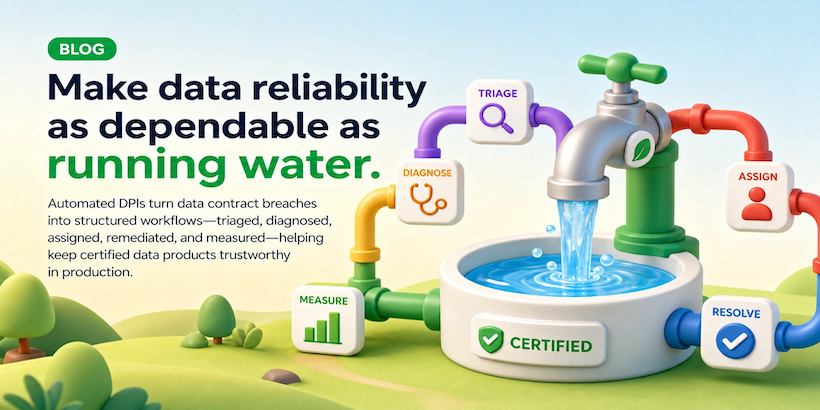
  9. Data Mesh at Grab (Part III): Operationalizing data reliability with automated DPIs

    Grab addressed runtime data reliability issues in its data mesh by implementing automated Data Production Issues (DPIs). The system uses an incident orchestrator to detect contract breaches, a Data Health API for cross-platform root cause analysis, and Hugo for automated remediation. This approach resolved 86.9 percent of incidents automatically and made mean time to resolve six times faster.

    DEPTH ■■■■■12 min read8 weeks ago

    DatabasesObservability

    Sign in to save and rate

  10. GrabMart data for faster disease outbreak detection

    The organization proposes a conceptual data pipeline to analyze aggregated GrabMart transaction data for symptom-related product demand, aiming to supplement clinical surveillance for disease outbreaks. The design relies on data aggregation, statistical baseline comparisons, and privacy safeguards like differential privacy without involving individual health inference. The system remains in an early planning phase requiring rigorous validation, privacy review, and public health oversight.

    DEPTH ■■■■■5 min read12 days ago

    Data EngineeringMachine Learning

    Sign in to save and rate