/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Shard design doesn't start from your tables

    Designing a sharded Postgres architecture requires grouping tables around shared query keys rather than starting from table structures alone. The post details how to configure shard groups, reference tables, SQL expressions in shard indexes, and global secondary indexes using Neki. This setup enables efficient single-shard queries and transactions while maintaining full Postgres semantics.

    DEPTH ■■■■■8 min read3 days ago
    PostgreSQL

    Sign in to save and rate

  2. The Pulse: Anthropic builds its own source control system

    Anthropic experienced a massive increase in code merges due to the heavy use of AI coding agents, which quickly overwhelmed standard Git scaling limits and CI checkouts. To solve this, a small engineering team built a custom centralized version control system called Scion backed by Google Spanner and Cloud Storage, along with a code review tool called Antique. This move successfully migrated the entire monorepo off Git and eliminated bottlenecks, though the architecture drew controversy over similarities to Meta's Mononoke.

    DEPTH ■■■■■12 min read4 days ago

    ArchitectureDistributed Systems

    Sign in to save and rate

  3. I don't trust ON DELETE CASCADE

    Postgres ON DELETE CASCADE can cause production outages, replication failures, and performance degradation during large deletions or schema migrations due to long-running transactions holding locks and generating massive WAL. The author recommends using soft deletes with batched background cleanup instead to keep transactions short and bounded. This approach avoids table locks and simplifies data recovery.

    DEPTH ■■■■■5 min read5 days ago

    PostgreSQL

    Sign in to save and rate

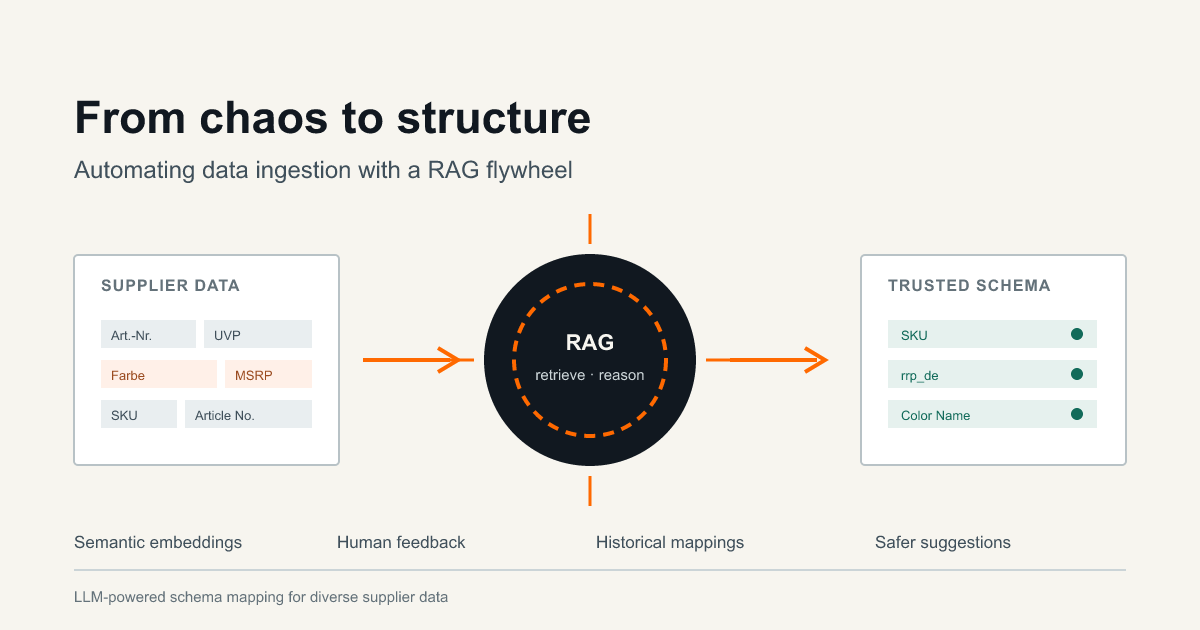
  4. Automating Data Ingestion with a RAG Flywheel

    Zalando replaced manual schema mapping for diverse supplier data with an LLM-powered Retrieval-Augmented Generation (RAG) flywheel. The system combines Amazon Titan embeddings stored in PostgreSQL via pgvector with tool-constrained generative models running at zero temperature. Every LLM suggestion passes through strict API validation checks before being reviewed by operations specialists, creating a continuous learning loop that improves future predictions.

    DEPTH ■■■■■14 min read2 weeks ago

    Machine LearningPostgreSQL

    Sign in to save and rate

  5. Thundering herd of circuit breakers

    An engineering team investigated why a client-side circuit breaker repeatedly failed to close on its own after an outage. By exporting OpenTelemetry traces into a custom visualization tool, they discovered that low probe traffic caused the autoscaler to scale down the service to minimum capacity, triggering a thundering herd of requests and immediate timeouts the moment the circuit breaker closed. Adjusting the system to account for capacity and probe representativeness prevents this oscillation.

    DEPTH ■■■■■10 min read2 weeks ago

    MicroservicesObservabilityReliability

    Sign in to save and rate

  6. What gets TOASTed in Postgres

    This post examines how PostgreSQL uses TOAST to manage oversized rows and variable-length columns through compression and off-row storage. It compares the pglz and LZ4 compression algorithms across different workloads, highlighting trade-offs in search windows, file sizes, and CPU overhead. The analysis demonstrates how these mechanisms impact storage efficiency and read performance for large text and JSON data.

    DEPTH ■■■■■12 min read2 weeks ago

    PostgreSQL

    Sign in to save and rate

  7. TIN v1.0.6: 2-3x faster, with support for stemming

    Following competitive benchmarks that highlighted opportunities for optimization, the developers of the TIN full-text search index for Postgres released versions 1.0.4 and 1.0.6. These updates added Snowball stemming for 18 languages, optimized top-k sorting queries with deterministic tiebreakers, and improved overall query performance. As a result, benchmark tests show that TIN outperforms competing extensions across conjunction, disjunction, and phrase query workloads.

    DEPTH ■■■■■8 min read2 weeks ago

    PostgreSQL

    Sign in to save and rate

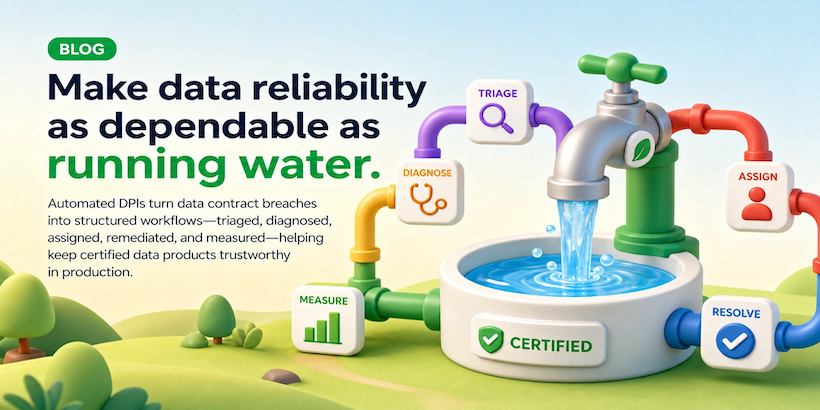
  8. Data Mesh at Grab (Part III): Operationalizing data reliability with automated DPIs

    Grab addressed runtime data reliability issues in its data mesh by implementing automated Data Production Issues (DPIs). The system uses an incident orchestrator to detect contract breaches, a Data Health API for cross-platform root cause analysis, and Hugo for automated remediation. This approach resolved 86.9 percent of incidents automatically and made mean time to resolve six times faster.

    DEPTH ■■■■■12 min read8 weeks ago

    DatabasesObservability

    Sign in to save and rate

  9. Taking a look under your agent’s hood

    This post discusses the challenges and methods of applying observability to AI agents, which combine traditional distributed systems telemetry with new requirements for monitoring LLMs and multi-step tool calls. The discussion highlights how non-deterministic agent behavior and increased speed of execution make continuous production feedback loops essential for upstream development. Ultimately, integrating observability data into automated testing and development loops helps teams iterate on agent performance.

    DEPTH ■■■■■25 min read2 weeks ago

    Machine LearningObservability

    Sign in to save and rate

  10. Handling hot shards

    Growing applications often encounter hot shards when certain tenants or data subsets outgrow initial sharding strategies based on workspace IDs. To mitigate this, teams can scale up resources, isolate large tenants into specific key ranges, or fundamentally change the shard key for problematic tables based on access patterns. Neki facilitates these adjustments by allowing declarative data topologies and online resharding without downtime.

    DEPTH ■■■■■7 min read4 weeks ago

    MySQLPostgreSQL

    Sign in to save and rate