/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Origin Range Requests: Serving large files without range-request tuning

    Cloudflare replaced a legacy, fixed-size range caching design that suffered from bandwidth waste and memory pressure with a Pingora-based chunk coordinator. The new implementation dynamically combines cached chunks and aligned origin fetches to serve range requests accurately without manual tuning. This approach cut p99 time to first byte in half for R2 storage and reduced tiered cache traffic by six percent.

    DEPTH ■■■■■8 min read3 days ago

    DatabasesPerformanceRedis

    Sign in to save and rate

  2. Shard design doesn't start from your tables

    Designing a sharded Postgres architecture requires grouping tables around shared query keys rather than starting from table structures alone. The post details how to configure shard groups, reference tables, SQL expressions in shard indexes, and global secondary indexes using Neki. This setup enables efficient single-shard queries and transactions while maintaining full Postgres semantics.

    DEPTH ■■■■■8 min read3 days ago
    PostgreSQL

    Sign in to save and rate

  3. Automate medical coding with Step Functions and Amazon Bedrock AgentCore

    Automating medical coding requires a hybrid approach that combines deterministic orchestration with bounded agentic reasoning to ensure safety, auditability, and human oversight. The team built a workflow using AWS Step Functions, AWS Lambda, and Amazon Bedrock AgentCore that evaluates terms cheapest-first via block-lists, exact matching, and finally an LLM agent for ambiguous cases. This design successfully autocodes confident cases while routing ambiguous ones to human reviewers with full audit trails and decision explanations.

    DEPTH ■■■■■15 min read5 days ago

    AWS

    Sign in to save and rate

  4. The Thin Orchestrator: How We Made Our AI Agents More Reliable by Giving the Router Less to Do

    Meta engineers reduced hallucinations and improved reliability in their data pipeline agents by replacing a single heavyweight LLM orchestrator with a thin deterministic router and fourteen specialized subagents. The thin orchestrator handles routing and reliability checks through a fixed protocol, while isolated subagents execute domain reasoning. This architecture reduced configuration preparation time from a day to under an hour.

    DEPTH ■■■■■7 min read7 days ago

    Machine Learning

    Sign in to save and rate

  5. Advancing Generative Recommendation Inference: our collaboration with NVIDIA on TensorRT LLM

    Spotify migrated its generative recommendation inference to NVIDIA TensorRT-LLM to address performance bottlenecks with vLLM and feature gaps in other engines. Through a collaboration with NVIDIA, the team added support for beam search, multi-item scoring, and soft token injection into TensorRT-LLM. This integration resulted in significant cost reductions of up to 54 percent for beam search and 7 percent for scoring workloads.

    DEPTH ■■■■■7 min read10 days ago

    Machine Learning

    Sign in to save and rate

  6. MCP standardized tools. Now we need the infrastructure around them.

    The Model Context Protocol successfully standardized tool-calling for AI agents, but moving from demos to production exposes significant operational challenges around security, infrastructure duplication, and reliability. Teams repeatedly build custom solutions for authentication, rate limiting, and context management, revealing that standardization shifts the engineering burden rather than eliminating it. Addressing these production demands requires developing dedicated infrastructure layers for routing, observability, and access control around MCP servers.

    DEPTH ■■■■■8 min read11 days ago

    Machine Learning

    Sign in to save and rate

  7. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read12 days ago

    Microservices

    Sign in to save and rate

  8. I don't trust ON DELETE CASCADE

    Postgres ON DELETE CASCADE can cause production outages, replication failures, and performance degradation during large deletions or schema migrations due to long-running transactions holding locks and generating massive WAL. The author recommends using soft deletes with batched background cleanup instead to keep transactions short and bounded. This approach avoids table locks and simplifies data recovery.

    DEPTH ■■■■■5 min read5 days ago

    PostgreSQL

    Sign in to save and rate

  9. Cutting our inference bill by 68% by being obsessive about optimization

    An engineering team investigated a steady rise in AI code review costs and found that cache misses and redundant model calls were driving up expenses. By restructuring system prompts to enable cross-repository prompt caching, eliminating wasted tool calls, and switching to more efficient models, the team cut inference costs by 68% while also significantly improving review latency.

    DEPTH ■■■■■15 min read7 days ago

    Machine Learning

    Sign in to save and rate

  10. Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster

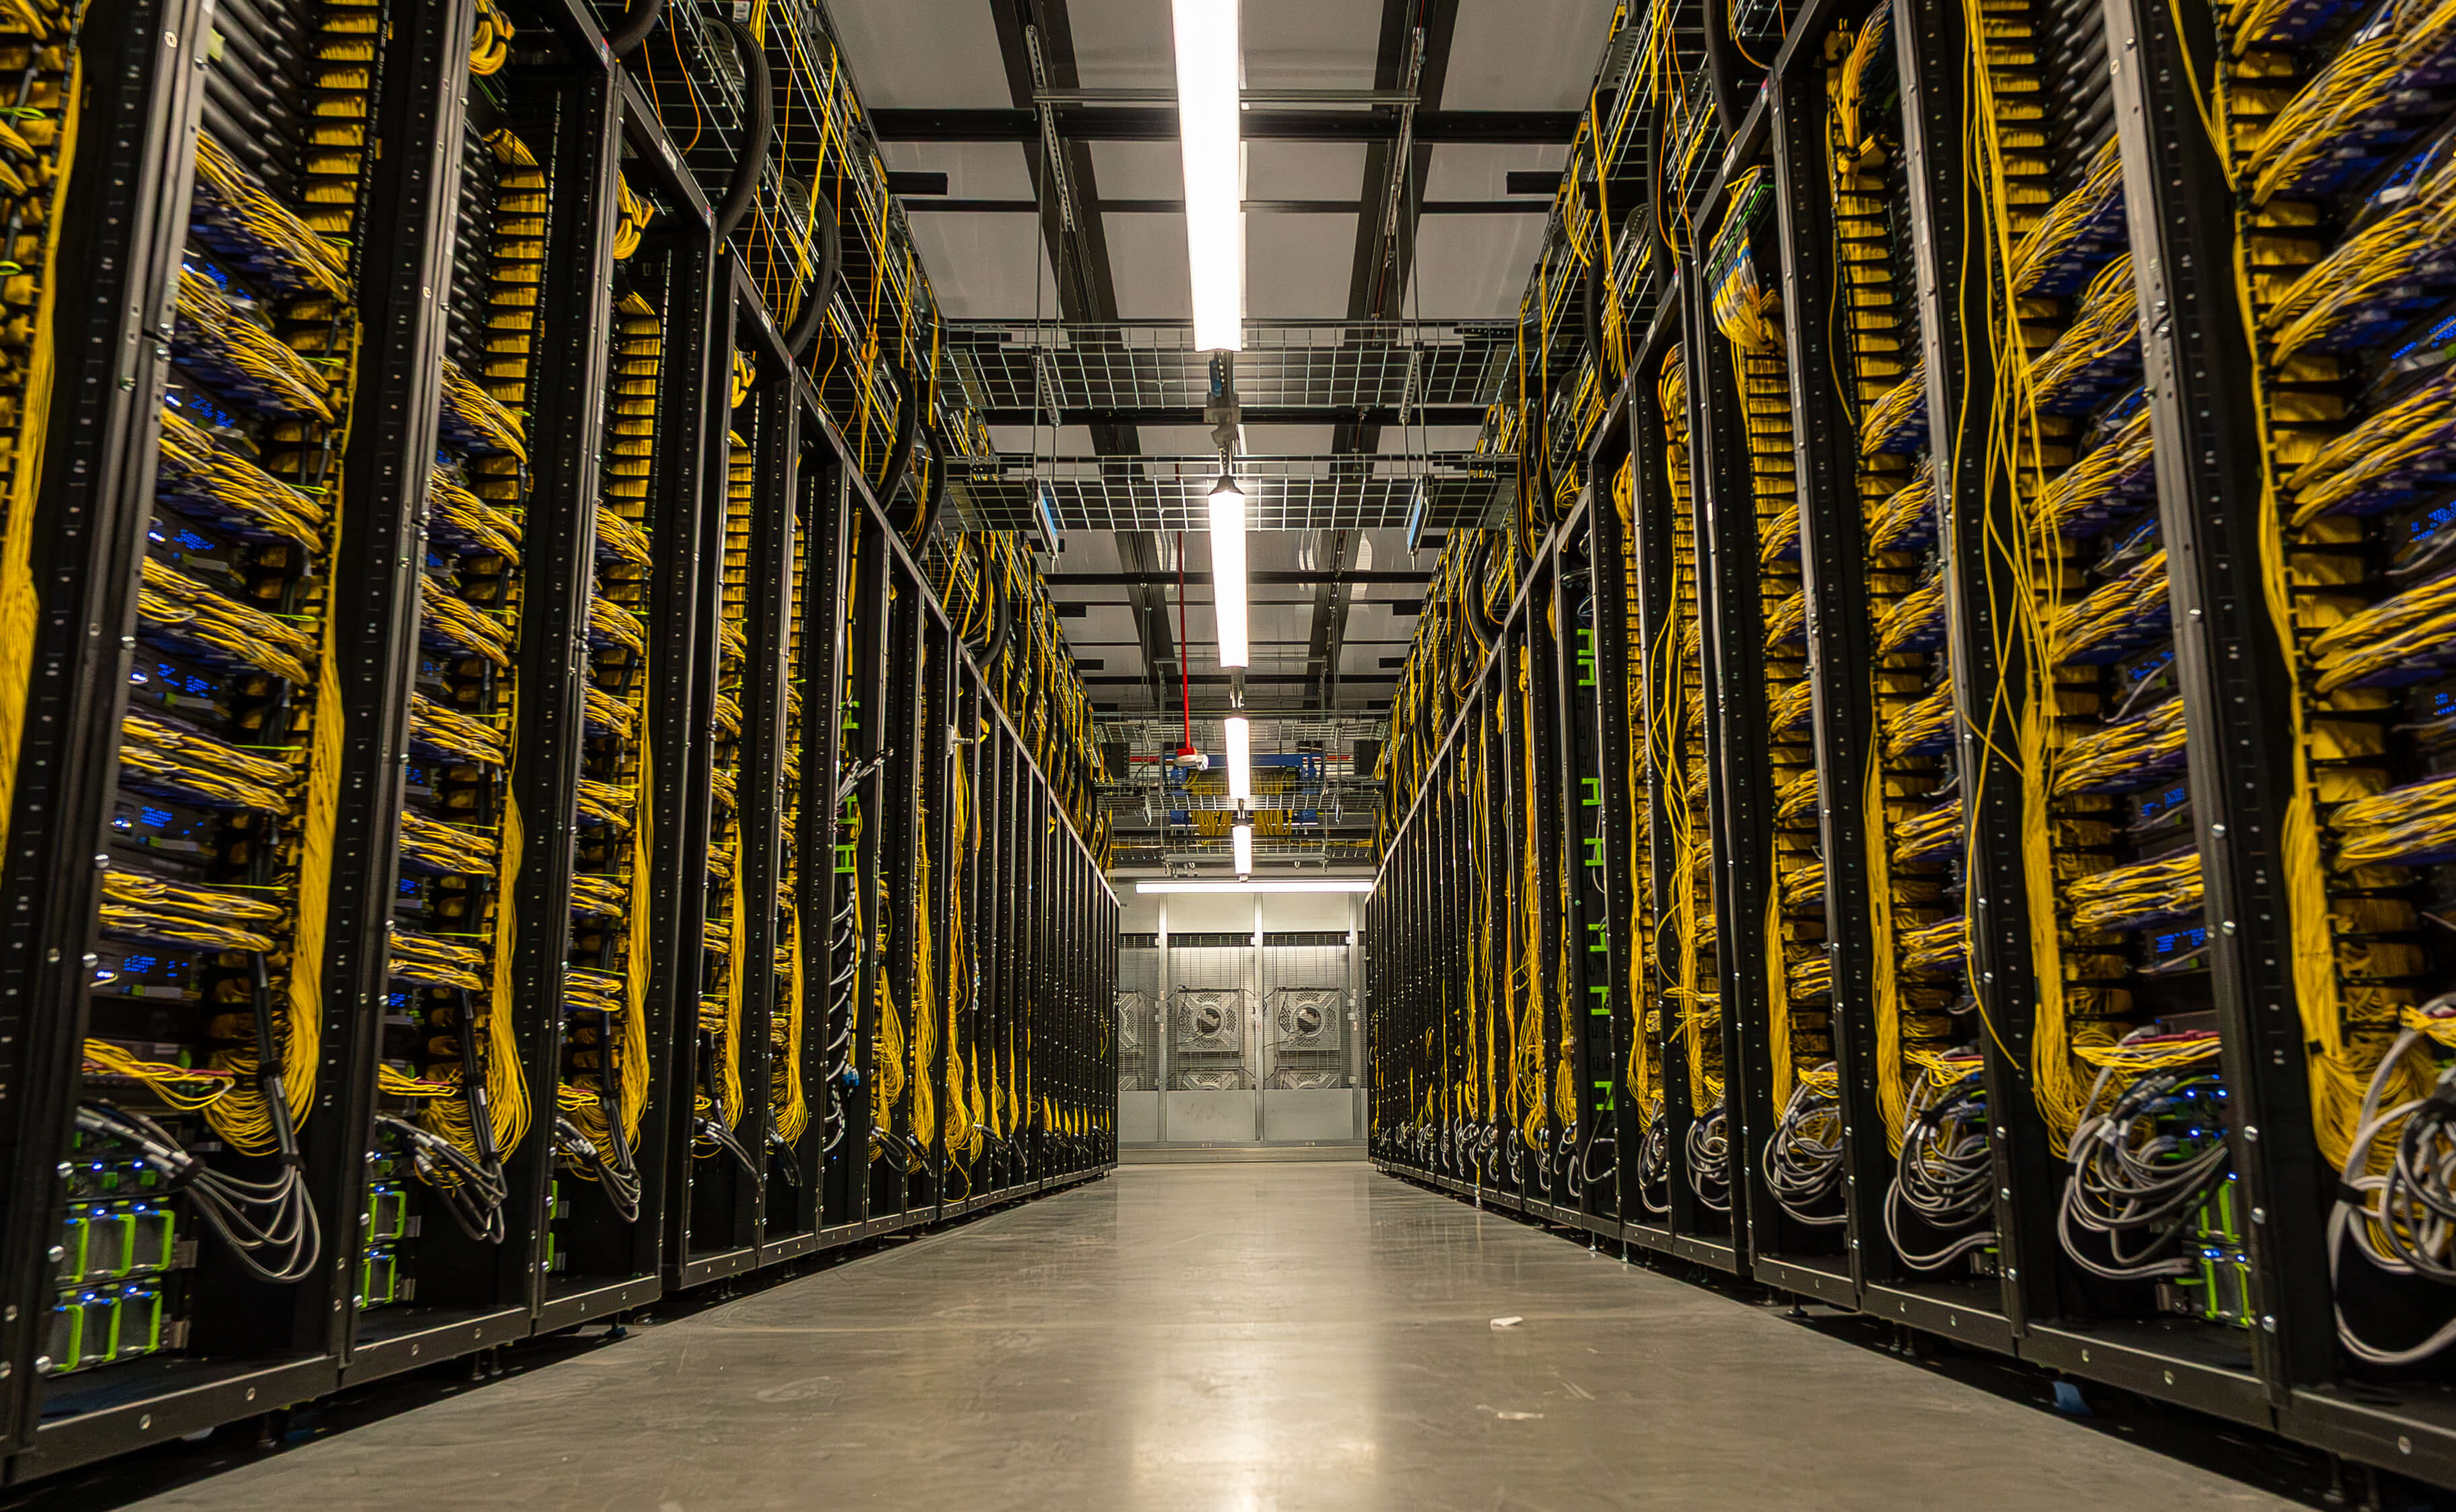
    Meta built Prometheus, a gigawatt-scale AI supercluster designed to scale up to one million GPUs using multi-generation NVIDIA hardware and specialized backend Ethernet networks. The team achieved high goodput and significantly reduced system interruptions by implementing an in-rack sparing strategy, parallelism-aware fault tolerance, and close co-engineering with vendors. These infrastructure advancements allowed the team to successfully train frontier foundational models like Muse Wonder.

    DEPTH ■■■■■17 min read7 days ago

    InfrastructureMachine Learning

    Sign in to save and rate

  11. Automating Data Ingestion with a RAG Flywheel

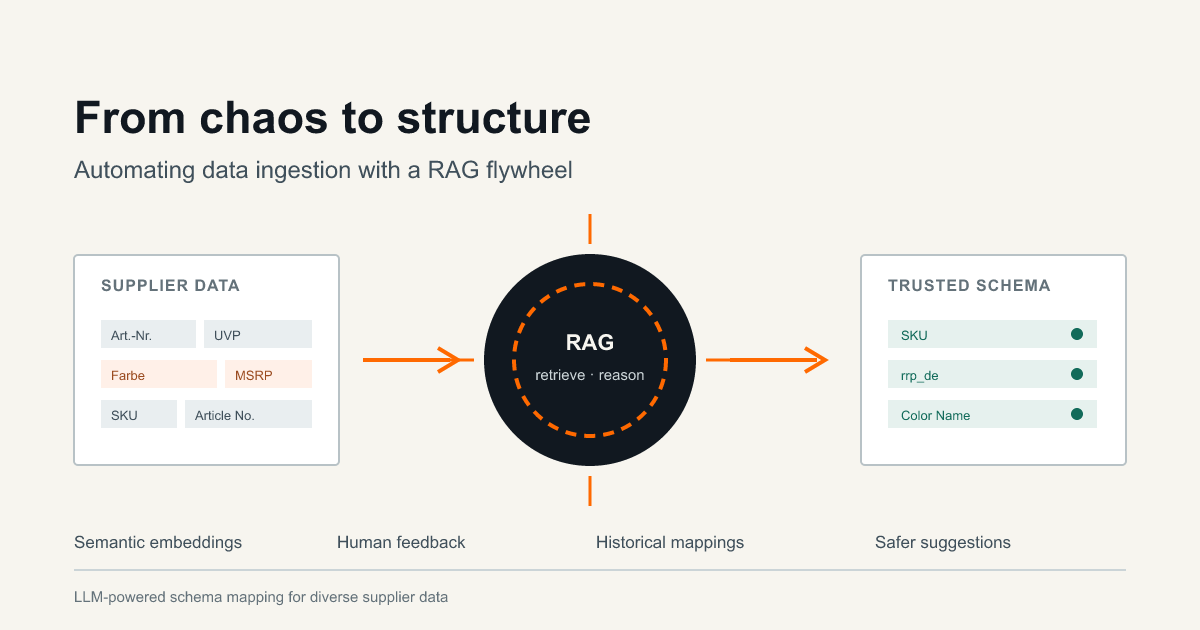
    Zalando replaced manual schema mapping for diverse supplier data with an LLM-powered Retrieval-Augmented Generation (RAG) flywheel. The system combines Amazon Titan embeddings stored in PostgreSQL via pgvector with tool-constrained generative models running at zero temperature. Every LLM suggestion passes through strict API validation checks before being reviewed by operations specialists, creating a continuous learning loop that improves future predictions.

    DEPTH ■■■■■14 min read2 weeks ago

    Machine LearningPostgreSQL

    Sign in to save and rate

  12. Powering AI-led research through simulation

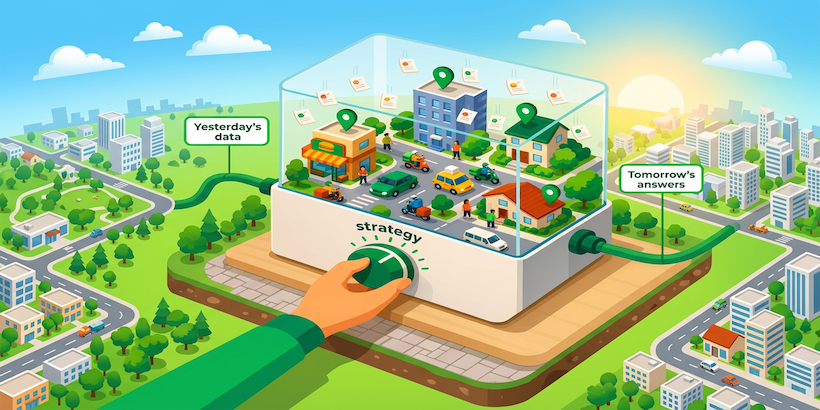
    The engineering team built a self-contained simulation platform called sim-rs to model marketplace dispatch dynamics and accelerate experimentation. By connecting automated software agents to this simulator with strict safety safeguards, the team successfully optimized strategy policies and simulator performance. This closed-loop lab environment allows agents to test ideas rapidly while ensuring that only valid, production-ready improvements are produced.

    DEPTH ■■■■■10 min read3 weeks ago

    Machine Learning

    Sign in to save and rate

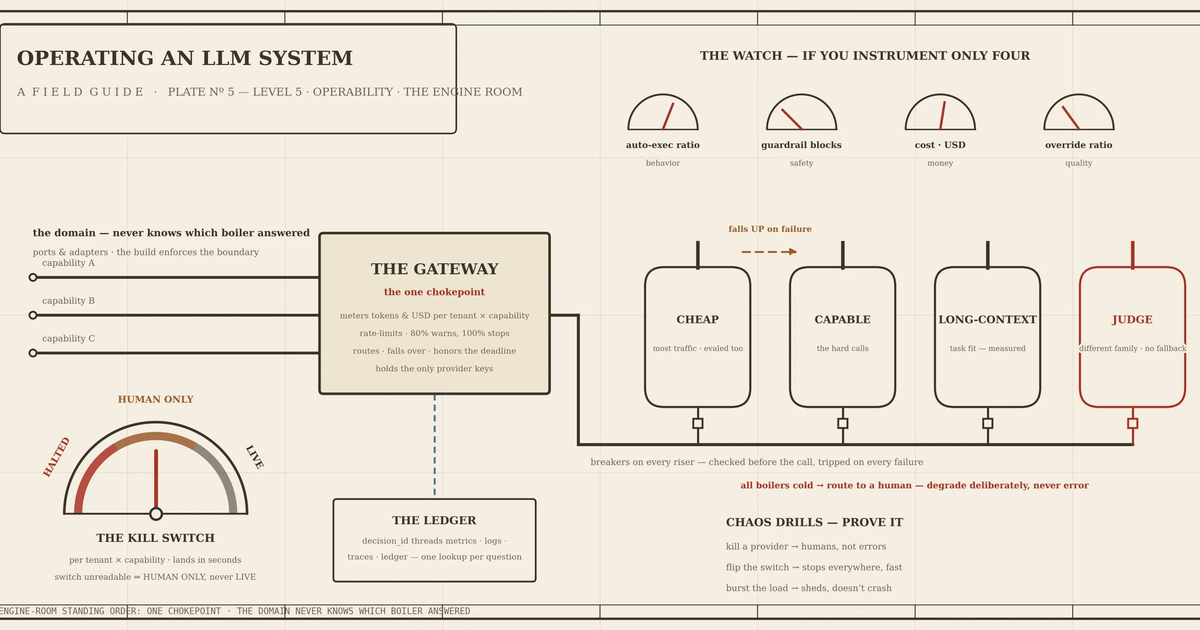
  13. Part 5: Operating an LLM system: observability, cost, routing, and the platform underneath

    This post provides a concrete specification for the operability layer of production LLM systems, covering observability signals, structured logging, cost controls, routing, and failover mechanisms. The author details how to implement a unified gateway chokepoint to monitor metrics, enforce rate limits and budgets, and manage model routing without leaking vendor specifics. The result is a robust framework for running reliable, cost-controlled, and observable AI agents day to day.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  14. Thundering herd of circuit breakers

    An engineering team investigated why a client-side circuit breaker repeatedly failed to close on its own after an outage. By exporting OpenTelemetry traces into a custom visualization tool, they discovered that low probe traffic caused the autoscaler to scale down the service to minimum capacity, triggering a thundering herd of requests and immediate timeouts the moment the circuit breaker closed. Adjusting the system to account for capacity and probe representativeness prevents this oscillation.

    DEPTH ■■■■■10 min read2 weeks ago

    MicroservicesObservabilityReliability

    Sign in to save and rate

  15. Under the hood, off the hot path: How D1 scales to millions of databases

    Cloudflare scaled its serverless SQLite database, D1, to support millions of databases by decoupling the control plane from the data plane. The team used distributed metadata caching via Workers KV, optimized database connections through Hyperdrive, and implemented a self-correcting heartbeat mechanism. This architecture prevents centralized bottlenecks and allows D1 to handle rapid on-demand database creation efficiently.

    DEPTH ■■■■■22 min read13 days ago

    Databases

    Sign in to save and rate

  16. Meta’s Generative Ads Model (GEM): Scaling the Central Model and Compute Engine for Frontier Ads AI

    Meta developed GEM, a unified recommendation foundation model using an LLM-style architecture called Kunlun to handle heterogeneous ads data across multiple surfaces. The team implemented block attention, custom low-precision kernels, and post-training intelligence transfer techniques like LoopFM and Solaris to scale training efficiency and bypass real-time serving latency bottlenecks. The resulting system delivered an 18.9% conversion improvement and a 12% click-through rate increase across Meta ads surfaces.

    DEPTH ■■■■■15 min read13 days ago

    Machine Learning

    Sign in to save and rate

  17. Evolving our calendar assistant Reclaim to be AI-native without starting over

    Dropbox engineers evolved their calendar assistant, Reclaim, to support natural-language AI requests by building a custom agent platform that integrates with existing scheduling logic. They utilized a shared action system and a Preview Mode backed by Redis to ensure AI suggestions are consistent and reviewable before affecting real calendars. This approach allows the product to adopt AI capabilities without fragmenting its core architecture or duplicating functionality.

    DEPTH ■■■■■7 min read3 weeks ago

    InfrastructureMachine Learning

    Sign in to save and rate

  18. What gets TOASTed in Postgres

    This post examines how PostgreSQL uses TOAST to manage oversized rows and variable-length columns through compression and off-row storage. It compares the pglz and LZ4 compression algorithms across different workloads, highlighting trade-offs in search windows, file sizes, and CPU overhead. The analysis demonstrates how these mechanisms impact storage efficiency and read performance for large text and JSON data.

    DEPTH ■■■■■12 min read2 weeks ago

    PostgreSQL

    Sign in to save and rate

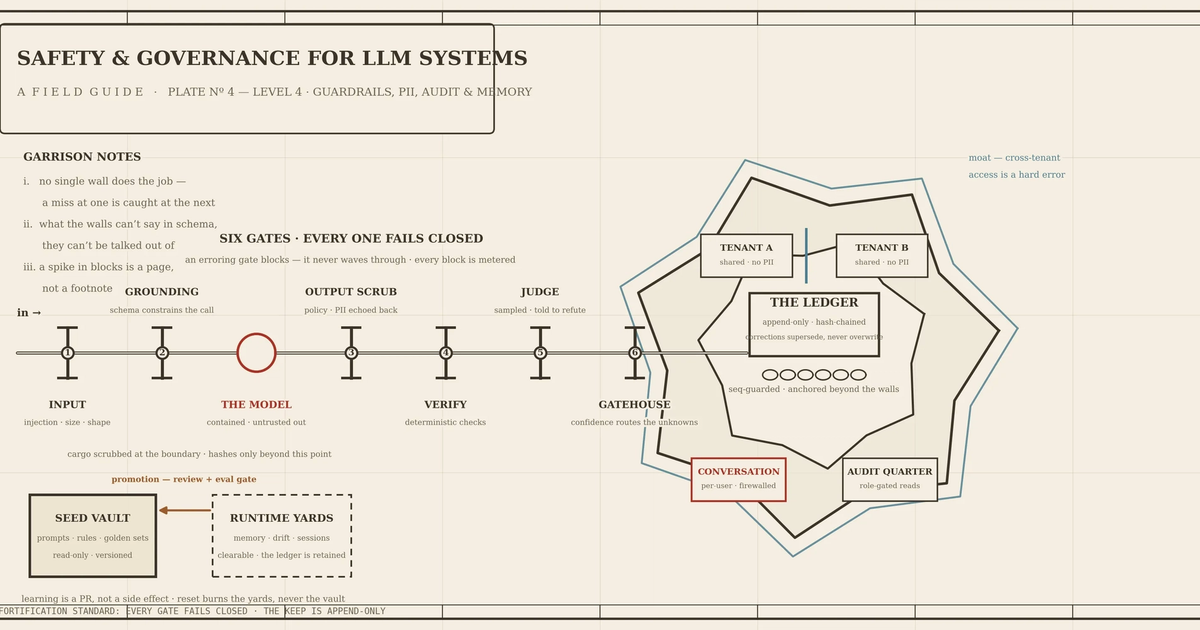
  19. Part 4: Safety and governance for LLM systems: guardrails, PII, audit, and memory

    This post details safety and governance practices for LLM systems, focusing on layered guardrails, boundary-level PII handling, and immutable audit trails. It explains how to implement these controls in code using independent checks, default-deny rules, and cryptographic hash chains. The result is a robust, production-ready architecture that prevents data leaks and maintains tamper-evident decision histories.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  20. OCP Summit 2026: Powering AI with Open Innovations in Scale-Up, Scale-Out, and Scale-Across Networks

    Meta shared its next-generation open networking infrastructure for AI at the OCP Summit 2026, including liquid-cooled 102.4T switch platforms, multiplane scale-out fabrics, and Ethernet-based scale-up solutions. The team also highlighted collaborative industry standards like ESUN and OSPA to unify hardware and transport layers. These open innovations aim to support massive gigawatt-scale AI clusters across diverse data center environments.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate