/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Shard design doesn't start from your tables

    Designing a sharded Postgres architecture requires grouping tables around shared query keys rather than starting from table structures alone. The post details how to configure shard groups, reference tables, SQL expressions in shard indexes, and global secondary indexes using Neki. This setup enables efficient single-shard queries and transactions while maintaining full Postgres semantics.

    DEPTH ■■■■■8 min read4 days ago
    PostgreSQL

    Sign in to save and rate

  2. The Pulse: Anthropic builds its own source control system

    Anthropic experienced a massive increase in code merges due to the heavy use of AI coding agents, which quickly overwhelmed standard Git scaling limits and CI checkouts. To solve this, a small engineering team built a custom centralized version control system called Scion backed by Google Spanner and Cloud Storage, along with a code review tool called Antique. This move successfully migrated the entire monorepo off Git and eliminated bottlenecks, though the architecture drew controversy over similarities to Meta's Mononoke.

    DEPTH ■■■■■12 min read5 days ago

    ArchitectureDistributed Systems

    Sign in to save and rate

  3. We gave AI agents a mobile dev environment

    Engineering teams outgrew their local machines while running parallel AI mobile development agents, constrained by heavy builds and lack of iOS tools on Linux. To solve this, they built Remote Dev using warm pools of remote Macs connected via SSH alongside separate Linux VMs for Android virtualization, paired with agent skills and live browser streaming. This setup shifted workflow bottlenecks, increasing AI-merged pull requests from 6 percent to 61 percent.

    DEPTH ■■■■■9 min read5 days ago

    ArchitectureMobile

    Sign in to save and rate

  4. PHP2Shell: GitLab helps find and remediate critical PHP flaws

    Critical remote code execution vulnerabilities known as PHP2Shell affect the PHP engine across multiple versions, requiring immediate runtime updates to fixed versions or patched distribution packages. The team utilized platform features like container scanning, code search, and automated agent workflows to locate PHP projects and remediate vulnerabilities. Operators must also check logs and environments for signs of compromise as framework updates and input validations cannot prevent these engine-level flaws.

    DEPTH ■■■■■10 min read5 days ago

    ArchitectureSecurity

    Sign in to save and rate

  5. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read5 days ago

    Infrastructure

    Sign in to save and rate

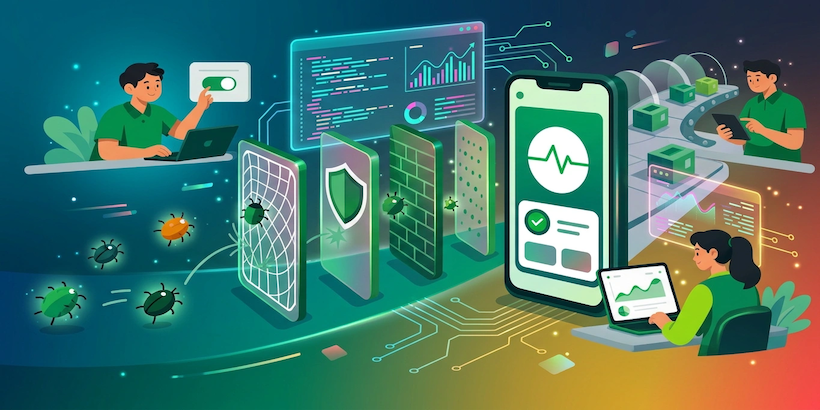
  6. App stability at scale with a layered defense

    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read6 days ago

    MobileReliability

    Sign in to save and rate

  7. Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster

    Meta built Prometheus, a gigawatt-scale AI supercluster designed to scale up to one million GPUs using multi-generation NVIDIA hardware and specialized backend Ethernet networks. The team achieved high goodput and significantly reduced system interruptions by implementing an in-rack sparing strategy, parallelism-aware fault tolerance, and close co-engineering with vendors. These infrastructure advancements allowed the team to successfully train frontier foundational models like Muse Wonder.

    DEPTH ■■■■■17 min read8 days ago

    InfrastructureMachine Learning

    Sign in to save and rate

  8. How Shopify turns open models into task experts

    Shopify uses a continual learning flywheel to post-train open models, such as NVIDIA Nemotron, to serve as dedicated subagents for specific tasks like GraphQL generation. By optimizing inference and utilizing automated self-healing to generate training data from production failures, the team successfully created task experts that outperform frontier models while reducing serving costs by 90-98% and improving response times.

    DEPTH ■■■■■5 min read6 days ago

    Architecture

    Sign in to save and rate

  9. I don't trust ON DELETE CASCADE

    Postgres ON DELETE CASCADE can cause production outages, replication failures, and performance degradation during large deletions or schema migrations due to long-running transactions holding locks and generating massive WAL. The author recommends using soft deletes with batched background cleanup instead to keep transactions short and bounded. This approach avoids table locks and simplifies data recovery.

    DEPTH ■■■■■5 min read6 days ago

    PostgreSQL

    Sign in to save and rate

  10. Rewinding the exponential: How we keep hardware usage down

    Cloudflare tackled exponential traffic growth against linear hardware growth by continuously evolving their data pipeline architecture over five years. Key optimizations included breaking up monolithic schemas, switching to zstd compression, decoupling pipeline transit from database replication, decentralizing sampling, and moving aggregations earlier in the pipeline. These strategies significantly reduced backbone bandwidth usage, network congestion, and storage requirements while preserving data quality.

    DEPTH ■■■■■12 min read13 days ago

    Infrastructure

    Sign in to save and rate

  11. Redesigning source control at Anthropic

    Anthropic experienced a massive surge in code generation due to AI coding tools, causing git to become a critical bottleneck for their monorepo. To scale, the team built Scion, a custom version control system optimized for online clients and server-side computation. This new architecture reduced infrastructure resource requirements by 200x and drastically improved checkout speeds for CI jobs.

    DEPTH ■■■■■17 min read2 weeks ago

    Architecture

    Sign in to save and rate

  12. Automating Data Ingestion with a RAG Flywheel

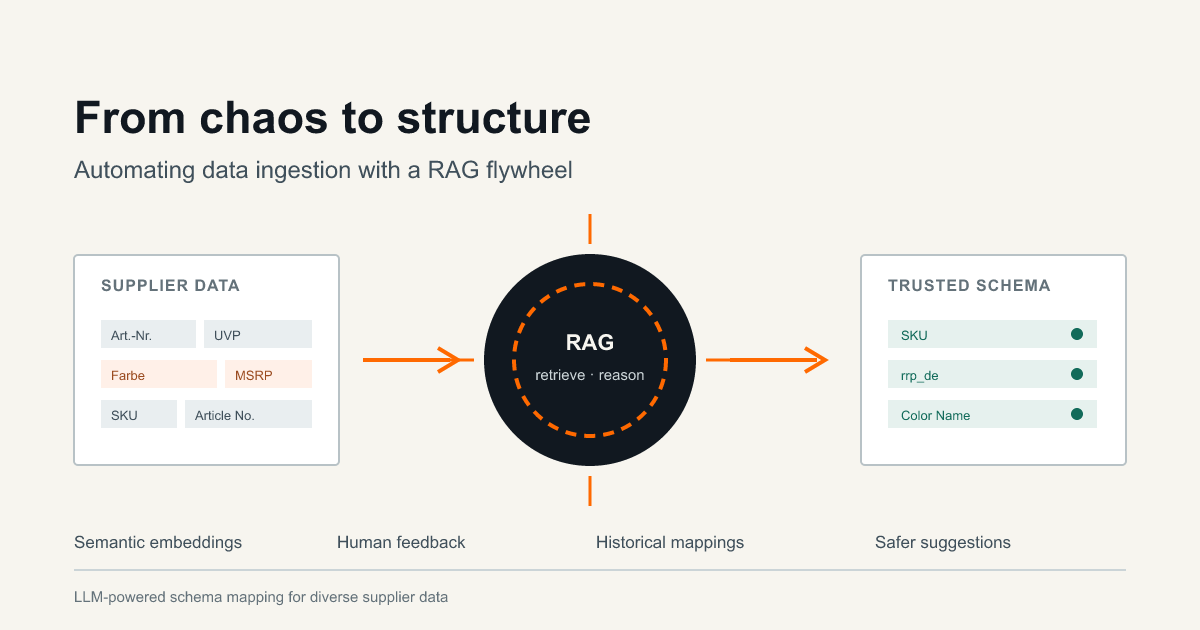
    Zalando replaced manual schema mapping for diverse supplier data with an LLM-powered Retrieval-Augmented Generation (RAG) flywheel. The system combines Amazon Titan embeddings stored in PostgreSQL via pgvector with tool-constrained generative models running at zero temperature. Every LLM suggestion passes through strict API validation checks before being reviewed by operations specialists, creating a continuous learning loop that improves future predictions.

    DEPTH ■■■■■14 min read2 weeks ago

    Machine LearningPostgreSQL

    Sign in to save and rate

  13. Cross-store product clustering across millions of stores

    Shopify needed to group identical product listings from millions of different merchants under a single global identifier. To solve this at scale without comparing every possible pair, the team implemented a multi-stage pipeline using vector retrieval, a tiered scoring system of ML models, and a bounded graph clustering approach. This architecture successfully standardizes product data across the entire platform while controlling computational costs.

    DEPTH ■■■■■13 min read7 days ago

    Architecture

    Sign in to save and rate

  14. Thundering herd of circuit breakers

    An engineering team investigated why a client-side circuit breaker repeatedly failed to close on its own after an outage. By exporting OpenTelemetry traces into a custom visualization tool, they discovered that low probe traffic caused the autoscaler to scale down the service to minimum capacity, triggering a thundering herd of requests and immediate timeouts the moment the circuit breaker closed. Adjusting the system to account for capacity and probe representativeness prevents this oscillation.

    DEPTH ■■■■■10 min read2 weeks ago

    MicroservicesObservabilityReliability

    Sign in to save and rate

  15. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

  16. Evolving our calendar assistant Reclaim to be AI-native without starting over

    Dropbox engineers evolved their calendar assistant, Reclaim, to support natural-language AI requests by building a custom agent platform that integrates with existing scheduling logic. They utilized a shared action system and a Preview Mode backed by Redis to ensure AI suggestions are consistent and reviewable before affecting real calendars. This approach allows the product to adopt AI capabilities without fragmenting its core architecture or duplicating functionality.

    DEPTH ■■■■■7 min read4 weeks ago

    InfrastructureMachine Learning

    Sign in to save and rate

  17. What gets TOASTed in Postgres

    This post examines how PostgreSQL uses TOAST to manage oversized rows and variable-length columns through compression and off-row storage. It compares the pglz and LZ4 compression algorithms across different workloads, highlighting trade-offs in search windows, file sizes, and CPU overhead. The analysis demonstrates how these mechanisms impact storage efficiency and read performance for large text and JSON data.

    DEPTH ■■■■■12 min read2 weeks ago

    PostgreSQL

    Sign in to save and rate

  18. 2026 World Cup: Breaking Records, Spiky Charts and Reliability at Scale

    Meta's infrastructure handled record-breaking traffic during the 2026 World Cup, including 30 million messages per second on WhatsApp, by relying on automated load balancing, capacity buffers, and targeted pre-builds. Traffic patterns revealed that surges occurred primarily during breaks rather than gameplay, requiring region-specific forecasting rather than cross-region load shifting. The systems maintained full reliability and allowed normal continuous deployment schedules to continue without manual intervention or system freezes.

    DEPTH ■■■■■5 min read11 days ago

    Infrastructure

    Sign in to save and rate

  19. The Regression Tests Nobody Writes: Capturing How Software Actually Behaves

    Standard regression tests usually only verify developer intent rather than the actual, unwritten behaviors that systems accumulate in production over time. By capturing real production traffic and network-level interactions, teams can build characterization test suites to automatically detect unintended behavioral shifts. This approach prevents accidental regressions during legacy refactoring, rewrites, and major framework upgrades.

    DEPTH ■■■■■6 min read4 days ago

    Testing

    Sign in to save and rate

  20. TIN v1.0.6: 2-3x faster, with support for stemming

    Following competitive benchmarks that highlighted opportunities for optimization, the developers of the TIN full-text search index for Postgres released versions 1.0.4 and 1.0.6. These updates added Snowball stemming for 18 languages, optimized top-k sorting queries with deterministic tiebreakers, and improved overall query performance. As a result, benchmark tests show that TIN outperforms competing extensions across conjunction, disjunction, and phrase query workloads.

    DEPTH ■■■■■8 min read2 weeks ago

    PostgreSQL

    Sign in to save and rate