21Stack Overflow · architecture
Part 2: Evals as a deployment gate — and how to know when they drift
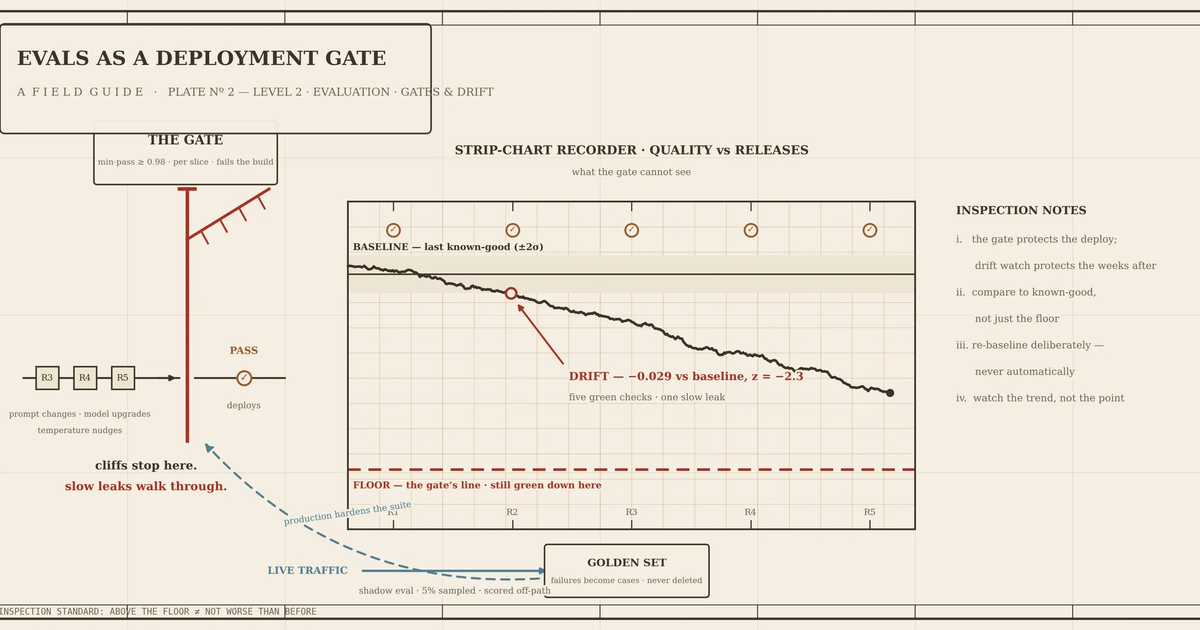
This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.
DEPTH ■■■■■8 min read2 weeks ago