/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Origin Range Requests: Serving large files without range-request tuning

    Cloudflare replaced a legacy, fixed-size range caching design that suffered from bandwidth waste and memory pressure with a Pingora-based chunk coordinator. The new implementation dynamically combines cached chunks and aligned origin fetches to serve range requests accurately without manual tuning. This approach cut p99 time to first byte in half for R2 storage and reduced tiered cache traffic by six percent.

    DEPTH ■■■■■8 min read4 days ago

    DatabasesPerformanceRedis

    Sign in to save and rate

  2. The Thin Orchestrator: How We Made Our AI Agents More Reliable by Giving the Router Less to Do

    Meta engineers reduced hallucinations and improved reliability in their data pipeline agents by replacing a single heavyweight LLM orchestrator with a thin deterministic router and fourteen specialized subagents. The thin orchestrator handles routing and reliability checks through a fixed protocol, while isolated subagents execute domain reasoning. This architecture reduced configuration preparation time from a day to under an hour.

    DEPTH ■■■■■7 min read8 days ago

    Machine Learning

    Sign in to save and rate

  3. Bringing post-quantum cryptography to geographically fenced key management

    Cloudflare introduced a post-quantum geographically restricted key manager in closed beta to enforce data sovereignty and protect customers against harvest-now-decrypt-later attacks. The team implemented a hybrid ML-KEM-768 and X25519 cryptographic design that separates globally distributed wrapped private keys from regionally restricted root keys. This ensures that decryption keys are only accessible within authorized geographical boundaries and fails closed if validation fails.

    DEPTH ■■■■■12 min read4 days ago

    Security

    Sign in to save and rate

  4. When Software Meets Hardware

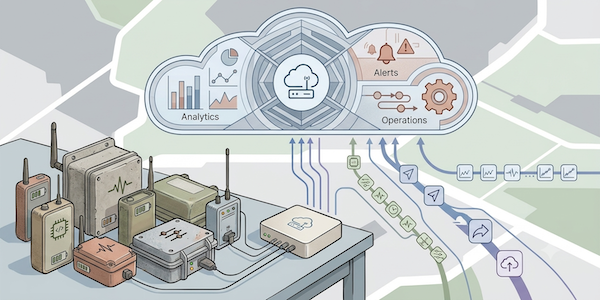
    A software engineering team modernizing a large-scale retail IoT system of 800,000 battery-powered sensors faced challenges integrating software practices with embedded hardware. By building physical sensor farms, virtual emulators, and self-diagnosing firmware, the team learned to design for intermittent connectivity, power efficiency, and fleet-level observability. The project succeeded by treating the physical world, hardware constraints, and engineering environments as core parts of the system lifecycle.

    DEPTH ■■■■■12 min read12 days ago

    Sign in to save and rate

  5. Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster

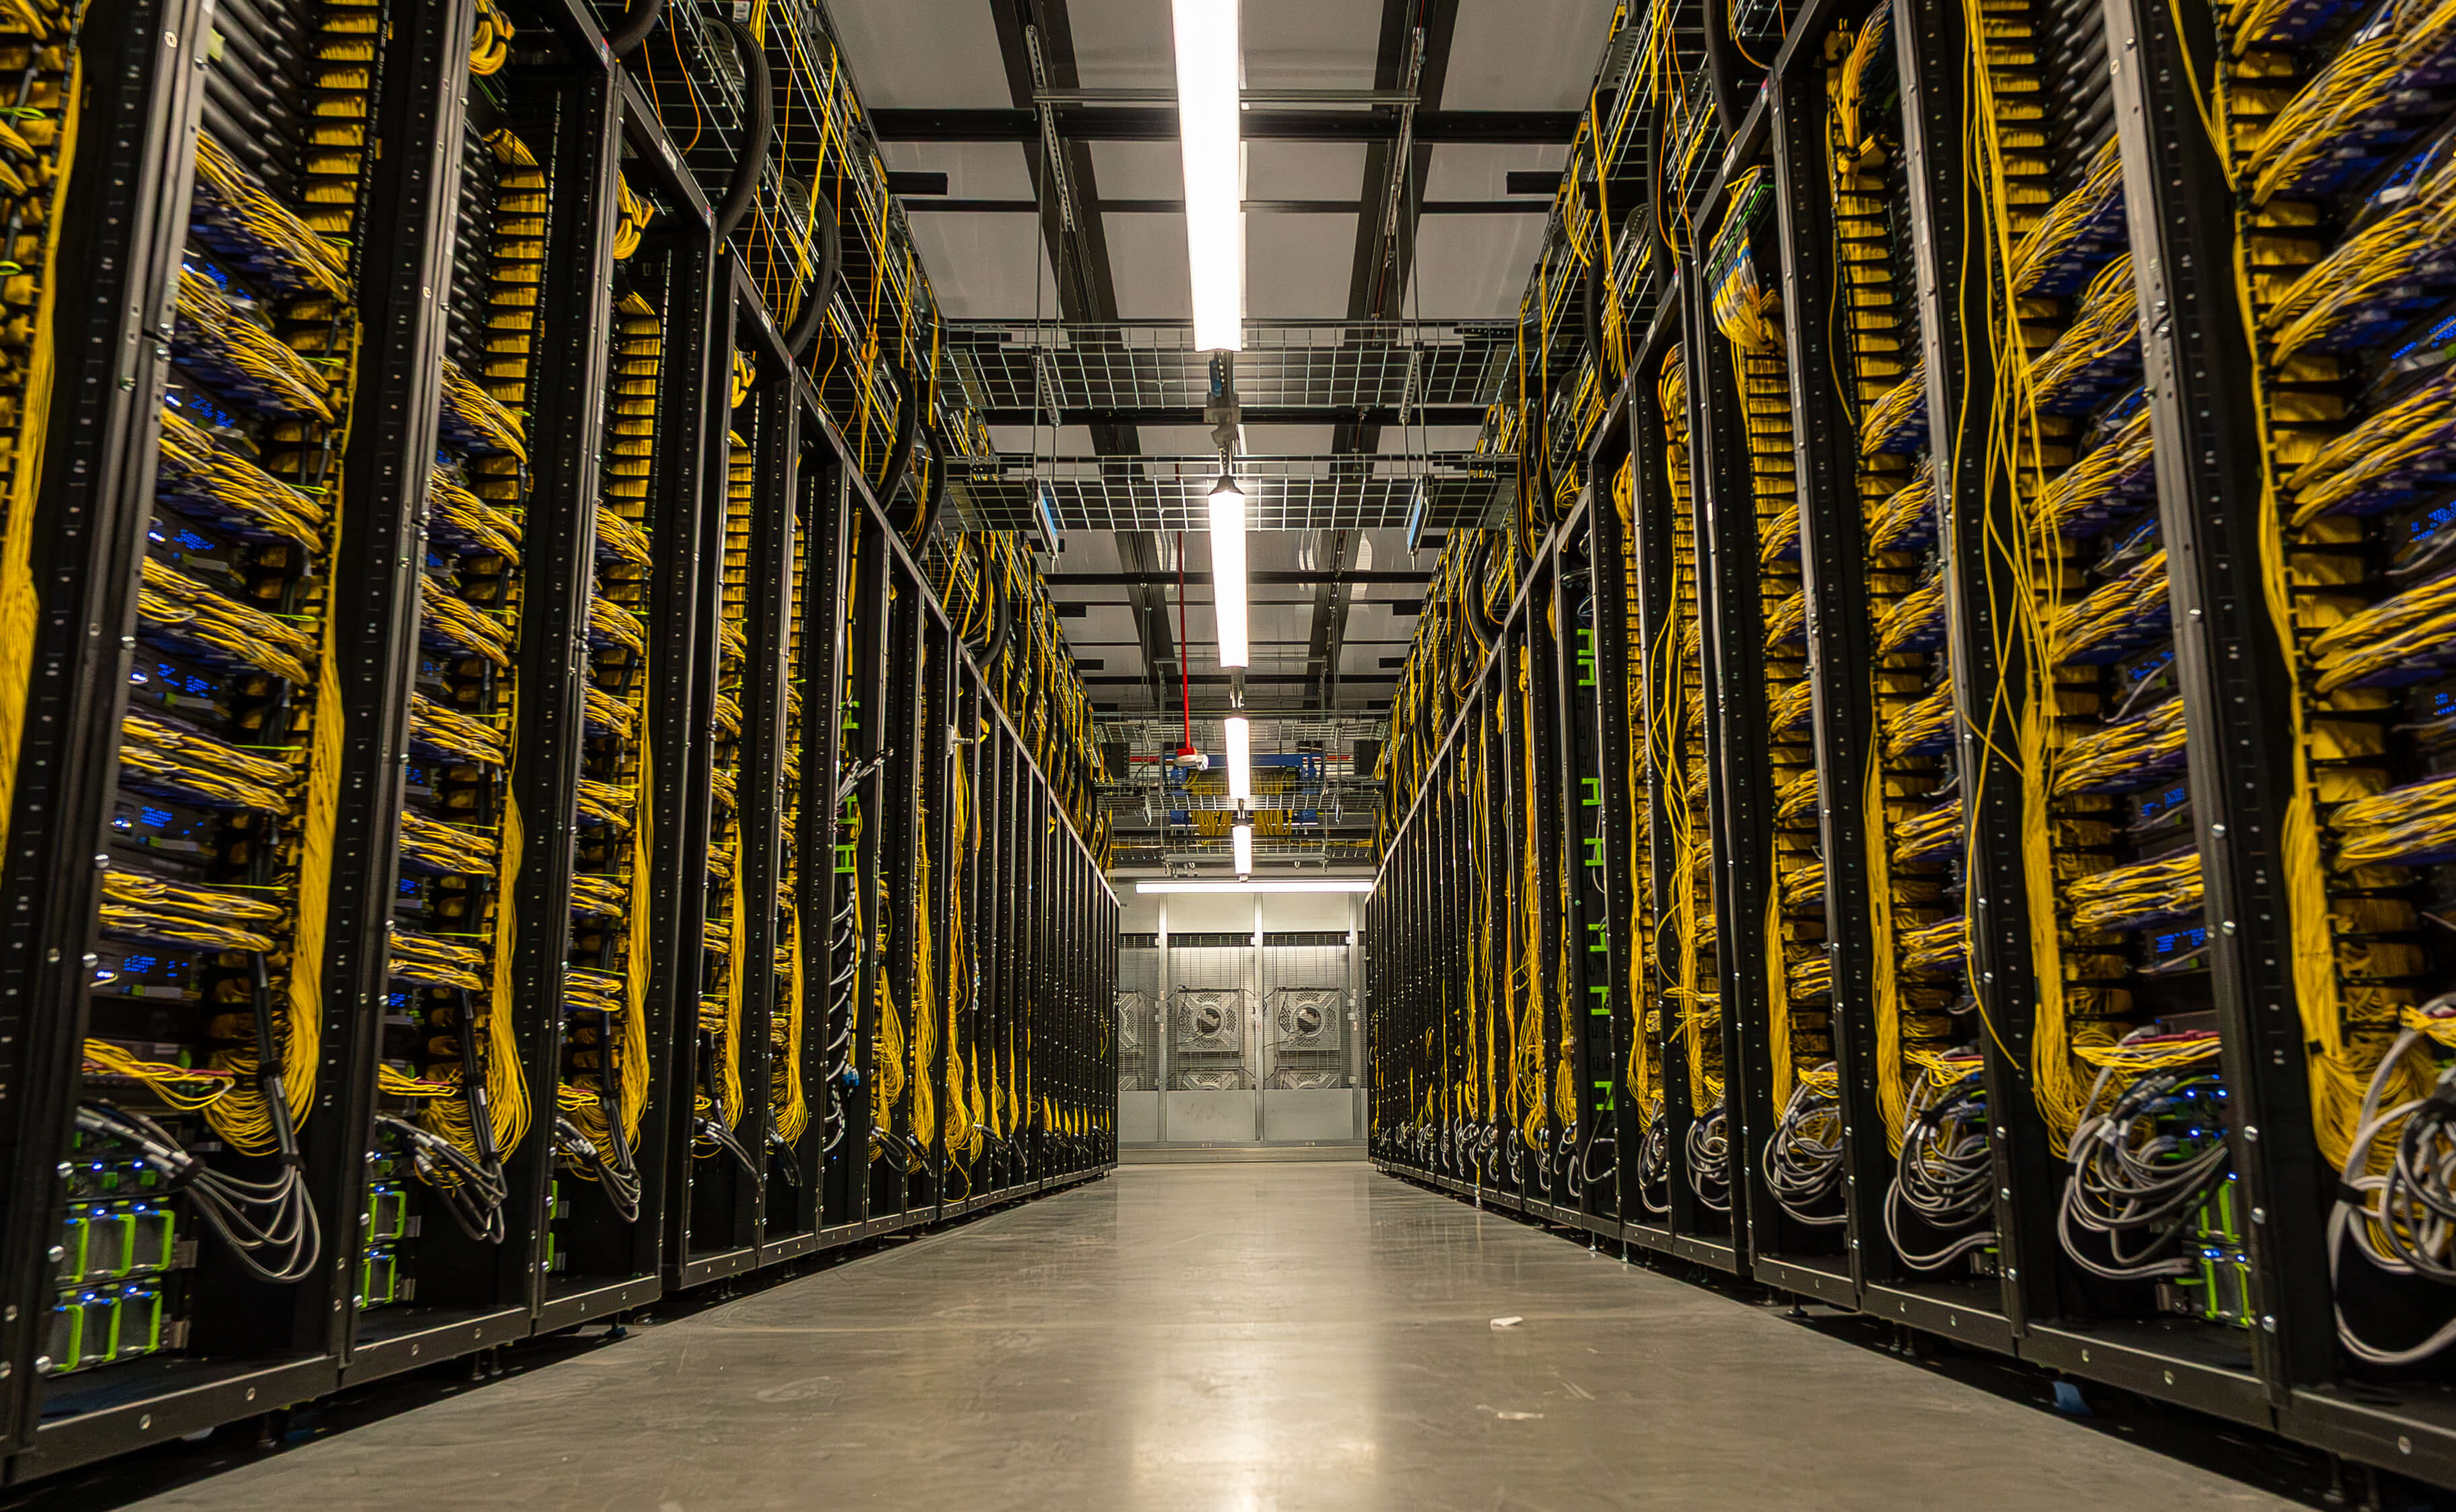
    Meta built Prometheus, a gigawatt-scale AI supercluster designed to scale up to one million GPUs using multi-generation NVIDIA hardware and specialized backend Ethernet networks. The team achieved high goodput and significantly reduced system interruptions by implementing an in-rack sparing strategy, parallelism-aware fault tolerance, and close co-engineering with vendors. These infrastructure advancements allowed the team to successfully train frontier foundational models like Muse Wonder.

    DEPTH ■■■■■17 min read8 days ago

    InfrastructureMachine Learning

    Sign in to save and rate

  6. Are Harnesses Worth the Cost?

    An experiment was conducted to evaluate whether behavioral harnesses improve coding agent reliability when building a complex backend-for-frontend service. While frontier models succeeded consistently with or without a harness, the harness significantly increased token usage, time, and cost without improving final output. However, for a cost-optimized model, the harness improved success rates from 30 percent to 100 percent.

    DEPTH ■■■■■17 min read2 weeks ago

    Sign in to save and rate

  7. Cutting our inference bill by 68% by being obsessive about optimization

    An engineering team investigated a steady rise in AI code review costs and found that cache misses and redundant model calls were driving up expenses. By restructuring system prompts to enable cross-repository prompt caching, eliminating wasted tool calls, and switching to more efficient models, the team cut inference costs by 68% while also significantly improving review latency.

    DEPTH ■■■■■15 min read8 days ago

    Machine Learning

    Sign in to save and rate

  8. How Meta Built Forum With AI-Native Engineering

    Meta engineers built the Forum app using a human-on-the-loop AI agent workflow that automated planning, building, testing, and verification. By shifting focus from code generation to automated verification, tooling improvements, and architectural legibility, the team reached feature parity in eight weeks while catching systemic memory issues early.

    DEPTH ■■■■■8 min read12 days ago

    FrontendMobile

    Sign in to save and rate

  9. Yandex outage: Data shows that instead of going dark, malicious bots went on the move

    Following physical strikes on Yandex data centers, overall HTTP traffic from the network dropped significantly, leading to speculation that malicious bot farms had been disabled. However, traffic analysis revealed that search crawling simply decreased while malicious automation quickly migrated to other hosting providers with identical fingerprints. Consequently, overall malicious bot traffic remained flat, demonstrating that network disruptions do not stop portable automated workloads.

    DEPTH ■■■■■8 min read12 days ago

    Incidents & Postmortems

    Sign in to save and rate

  10. Meta’s Generative Ads Model (GEM): Scaling the Central Model and Compute Engine for Frontier Ads AI

    Meta developed GEM, a unified recommendation foundation model using an LLM-style architecture called Kunlun to handle heterogeneous ads data across multiple surfaces. The team implemented block attention, custom low-precision kernels, and post-training intelligence transfer techniques like LoopFM and Solaris to scale training efficiency and bypass real-time serving latency bottlenecks. The resulting system delivered an 18.9% conversion improvement and a 12% click-through rate increase across Meta ads surfaces.

    DEPTH ■■■■■15 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  11. Inside Hyperdrive: How we solved a rare Hyperdrive MySQL caching bug

    During the beta of MySQL support for Hyperdrive, engineers investigated rare empty query responses and connection hangs occurring in 0.001% of requests. They discovered that sharing the data center cache between client and endpoint nodes caused protocol capability mismatches when translating MySQL wire messages. The team resolved the issue by standardizing the cache to always store responses encoded with canonical Hyperdrive capabilities.

    DEPTH ■■■■■9 min read13 days ago

    MySQL

    Sign in to save and rate

  12. OCP Summit 2026: Powering AI with Open Innovations in Scale-Up, Scale-Out, and Scale-Across Networks

    Meta shared its next-generation open networking infrastructure for AI at the OCP Summit 2026, including liquid-cooled 102.4T switch platforms, multiplane scale-out fabrics, and Ethernet-based scale-up solutions. The team also highlighted collaborative industry standards like ESUN and OSPA to unify hardware and transport layers. These open innovations aim to support massive gigawatt-scale AI clusters across diverse data center environments.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  13. The making of the Yelp Assistant UI

    Yelp developed a chat interface called Yelp Assistant using a hybrid approach combining native UI components and a server-driven UI framework called CHAOS. This architecture allows the team to dynamically update the chat experience without waiting for app store releases. The system separates views from data using reactive datasets and MessageEvents to manage the chat loop, state, and user interactions.

    DEPTH ■■■■■12 min read4 weeks ago

    Sign in to save and rate

  14. Under the hood, off the hot path: How D1 scales to millions of databases

    Cloudflare scaled its serverless SQLite database, D1, to support millions of databases by decoupling the control plane from the data plane. The team used distributed metadata caching via Workers KV, optimized database connections through Hyperdrive, and implemented a self-correcting heartbeat mechanism. This architecture prevents centralized bottlenecks and allows D1 to handle rapid on-demand database creation efficiently.

    DEPTH ■■■■■22 min read2 weeks ago

    Databases

    Sign in to save and rate

  15. Fragments: October 21

    This post discusses commentary on AI usage in writing, the cancellation of the Grace Hopper Celebration, and reviews a detailed article by Cindy Sridharan on debugging with AI agents. The reviewed article highlights that AI agents excel at processing raw data rather than reading code first, and outlines a three-step debugging process involving controls, signals, and hypothesis validation. The lesson is that engineers must guide AI agents by setting up verification loops and providing raw data rather than human-centric abstractions.

    DEPTH ■■■■■5 min read6 days ago

    Sign in to save and rate

  16. Rewinding the exponential: How we keep hardware usage down

    Cloudflare tackled exponential traffic growth against linear hardware growth by continuously evolving their data pipeline architecture over five years. Key optimizations included breaking up monolithic schemas, switching to zstd compression, decoupling pipeline transit from database replication, decentralizing sampling, and moving aggregations earlier in the pipeline. These strategies significantly reduced backbone bandwidth usage, network congestion, and storage requirements while preserving data quality.

    DEPTH ■■■■■12 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

  17. GenRecs Tokenization: Transforming Ads Recommendation at Meta with Stable Model Vocabulary

    Meta implemented GenRecs Tokenization to replace dedicated item IDs with a stable semantic vocabulary for ads recommendation. Using a three-stage encoding and quantization pipeline, the system enables language models to reason about ad content and user preferences simultaneously. This approach resulted in a +0.35% lift in conversions and improved cold-start performance for new entities.

    DEPTH ■■■■■6 min read8 days ago

    Machine Learning

    Sign in to save and rate

  18. Filter, reshape, and redact logs before export with Transformers

    Cloudflare integrated SQL-based log transformation directly into its Logpush export pipeline, allowing customers to filter, redact, and reshape logs before delivery. The team chose to embed the Apache DataFusion engine in-process using Rust and Go across an Arrow IPC boundary to ensure high throughput and avoid network latency. As a result, the system processes high-volume log streams efficiently while maintaining predictable resource usage and strict delivery reliability.

    DEPTH ■■■■■8 min read2 weeks ago

    Sign in to save and rate

  19. The Craft of Practitioner Voice

    The author explores a missing category of writing called Practitioner Voice, which is grounded in earned experience and visible personal judgment rather than academic rigor, corporate polish, or AI generation. They examine how AI can be used as an extended cognitive tool for practitioners without losing human accountability. Ultimately, the piece argues that maintaining personal judgment and consequence-bearing experience is essential for authentic professional writing.

    DEPTH ■■■■■39 min read2 weeks ago

    Sign in to save and rate

  20. 2026 World Cup: Breaking Records, Spiky Charts and Reliability at Scale

    Meta's infrastructure handled record-breaking traffic during the 2026 World Cup, including 30 million messages per second on WhatsApp, by relying on automated load balancing, capacity buffers, and targeted pre-builds. Traffic patterns revealed that surges occurred primarily during breaks rather than gameplay, requiring region-specific forecasting rather than cross-region load shifting. The systems maintained full reliability and allowed normal continuous deployment schedules to continue without manual intervention or system freezes.

    DEPTH ■■■■■5 min read12 days ago

    Infrastructure

    Sign in to save and rate