/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Origin Range Requests: Serving large files without range-request tuning

    Cloudflare replaced a legacy, fixed-size range caching design that suffered from bandwidth waste and memory pressure with a Pingora-based chunk coordinator. The new implementation dynamically combines cached chunks and aligned origin fetches to serve range requests accurately without manual tuning. This approach cut p99 time to first byte in half for R2 storage and reduced tiered cache traffic by six percent.

    DEPTH ■■■■■8 min read3 days ago

    DatabasesPerformanceRedis

    Sign in to save and rate

  2. We gave AI agents a mobile dev environment

    Engineering teams outgrew their local machines while running parallel AI mobile development agents, constrained by heavy builds and lack of iOS tools on Linux. To solve this, they built Remote Dev using warm pools of remote Macs connected via SSH alongside separate Linux VMs for Android virtualization, paired with agent skills and live browser streaming. This setup shifted workflow bottlenecks, increasing AI-merged pull requests from 6 percent to 61 percent.

    DEPTH ■■■■■9 min read5 days ago

    ArchitectureMobile

    Sign in to save and rate

  3. PHP2Shell: GitLab helps find and remediate critical PHP flaws

    Critical remote code execution vulnerabilities known as PHP2Shell affect the PHP engine across multiple versions, requiring immediate runtime updates to fixed versions or patched distribution packages. The team utilized platform features like container scanning, code search, and automated agent workflows to locate PHP projects and remediate vulnerabilities. Operators must also check logs and environments for signs of compromise as framework updates and input validations cannot prevent these engine-level flaws.

    DEPTH ■■■■■10 min read5 days ago

    ArchitectureSecurity

    Sign in to save and rate

  4. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read6 days ago

    Infrastructure

    Sign in to save and rate

  5. App stability at scale with a layered defense

    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read6 days ago

    MobileReliability

    Sign in to save and rate

  6. The Thin Orchestrator: How We Made Our AI Agents More Reliable by Giving the Router Less to Do

    Meta engineers reduced hallucinations and improved reliability in their data pipeline agents by replacing a single heavyweight LLM orchestrator with a thin deterministic router and fourteen specialized subagents. The thin orchestrator handles routing and reliability checks through a fixed protocol, while isolated subagents execute domain reasoning. This architecture reduced configuration preparation time from a day to under an hour.

    DEPTH ■■■■■7 min read8 days ago

    Machine Learning

    Sign in to save and rate

  7. Bringing post-quantum cryptography to geographically fenced key management

    Cloudflare introduced a post-quantum geographically restricted key manager in closed beta to enforce data sovereignty and protect customers against harvest-now-decrypt-later attacks. The team implemented a hybrid ML-KEM-768 and X25519 cryptographic design that separates globally distributed wrapped private keys from regionally restricted root keys. This ensures that decryption keys are only accessible within authorized geographical boundaries and fails closed if validation fails.

    DEPTH ■■■■■12 min read3 days ago

    Security

    Sign in to save and rate

  8. MCP standardized tools. Now we need the infrastructure around them.

    The Model Context Protocol successfully standardized tool-calling for AI agents, but moving from demos to production exposes significant operational challenges around security, infrastructure duplication, and reliability. Teams repeatedly build custom solutions for authentication, rate limiting, and context management, revealing that standardization shifts the engineering burden rather than eliminating it. Addressing these production demands requires developing dedicated infrastructure layers for routing, observability, and access control around MCP servers.

    DEPTH ■■■■■8 min read11 days ago

    Machine Learning

    Sign in to save and rate

  9. How Shopify turns open models into task experts

    Shopify uses a continual learning flywheel to post-train open models, such as NVIDIA Nemotron, to serve as dedicated subagents for specific tasks like GraphQL generation. By optimizing inference and utilizing automated self-healing to generate training data from production failures, the team successfully created task experts that outperform frontier models while reducing serving costs by 90-98% and improving response times.

    DEPTH ■■■■■5 min read6 days ago

    Architecture

    Sign in to save and rate

  10. Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster

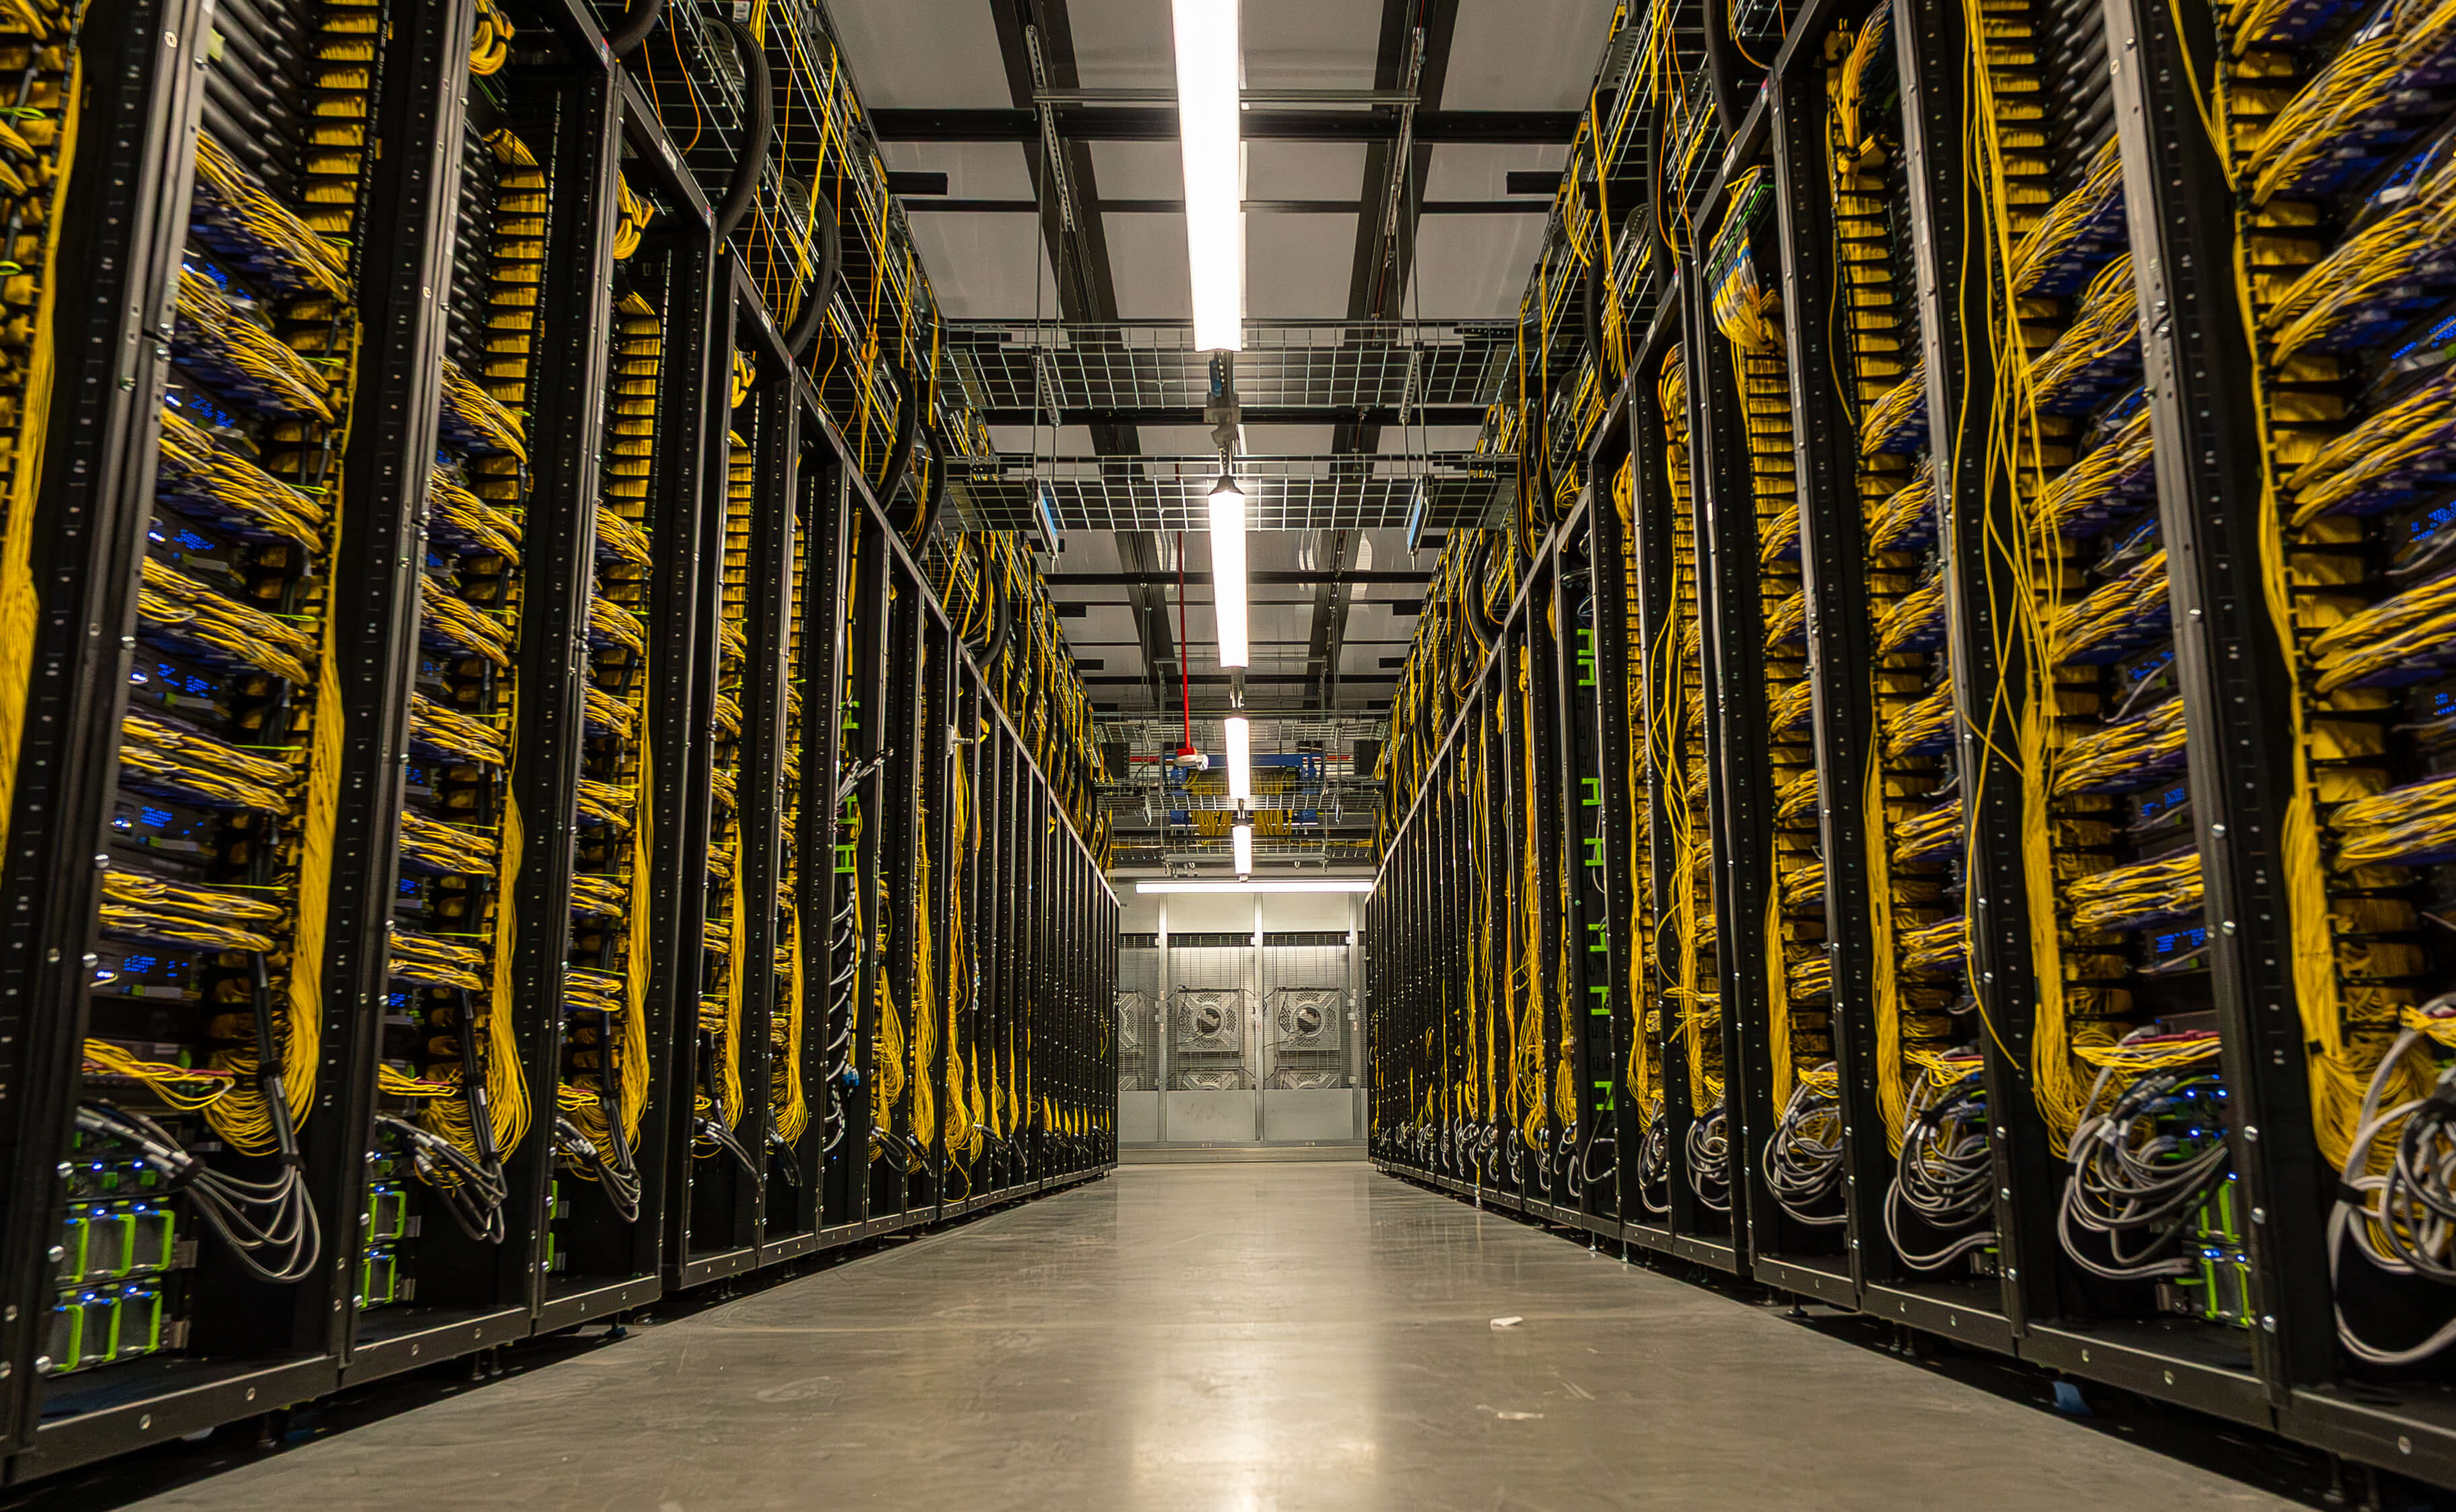
    Meta built Prometheus, a gigawatt-scale AI supercluster designed to scale up to one million GPUs using multi-generation NVIDIA hardware and specialized backend Ethernet networks. The team achieved high goodput and significantly reduced system interruptions by implementing an in-rack sparing strategy, parallelism-aware fault tolerance, and close co-engineering with vendors. These infrastructure advancements allowed the team to successfully train frontier foundational models like Muse Wonder.

    DEPTH ■■■■■17 min read8 days ago

    InfrastructureMachine Learning

    Sign in to save and rate

  11. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read12 days ago

    Microservices

    Sign in to save and rate

  12. Cross-store product clustering across millions of stores

    Shopify needed to group identical product listings from millions of different merchants under a single global identifier. To solve this at scale without comparing every possible pair, the team implemented a multi-stage pipeline using vector retrieval, a tiered scoring system of ML models, and a bounded graph clustering approach. This architecture successfully standardizes product data across the entire platform while controlling computational costs.

    DEPTH ■■■■■13 min read7 days ago

    Architecture

    Sign in to save and rate

  13. Cutting our inference bill by 68% by being obsessive about optimization

    An engineering team investigated a steady rise in AI code review costs and found that cache misses and redundant model calls were driving up expenses. By restructuring system prompts to enable cross-repository prompt caching, eliminating wasted tool calls, and switching to more efficient models, the team cut inference costs by 68% while also significantly improving review latency.

    DEPTH ■■■■■15 min read7 days ago

    Machine Learning

    Sign in to save and rate

  14. Make every AI credit count: See, cap, and reduce agent spend

    Uncontrolled AI agent spending can be mitigated by combining open-weight models, centralized context graphs to reduce retries, and usage analytics with credit caps. GitLab introduced these capabilities in its Duo Agent Platform to help platform teams trace, limit, and optimize AI credit consumption. The resulting architecture matches specific tasks to lower-cost models while maintaining task completion quality.

    DEPTH ■■■■■6 min read2 weeks ago

    Sign in to save and rate

  15. How Meta Built Forum With AI-Native Engineering

    Meta engineers built the Forum app using a human-on-the-loop AI agent workflow that automated planning, building, testing, and verification. By shifting focus from code generation to automated verification, tooling improvements, and architectural legibility, the team reached feature parity in eight weeks while catching systemic memory issues early.

    DEPTH ■■■■■8 min read11 days ago

    FrontendMobile

    Sign in to save and rate

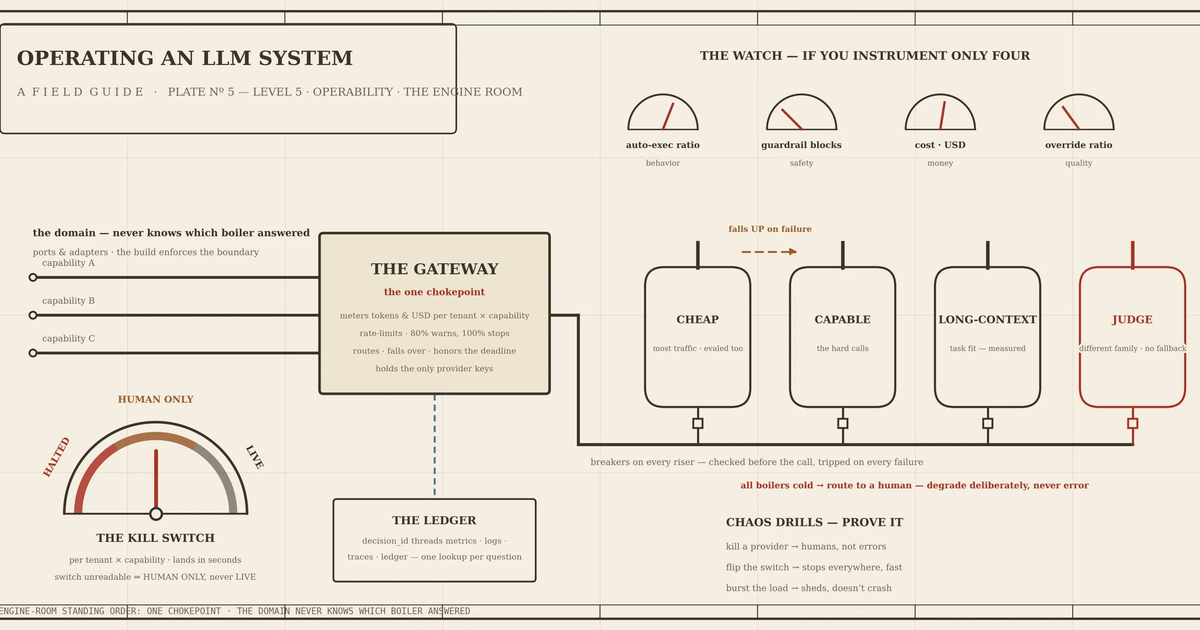
  16. Part 5: Operating an LLM system: observability, cost, routing, and the platform underneath

    This post provides a concrete specification for the operability layer of production LLM systems, covering observability signals, structured logging, cost controls, routing, and failover mechanisms. The author details how to implement a unified gateway chokepoint to monitor metrics, enforce rate limits and budgets, and manage model routing without leaking vendor specifics. The result is a robust framework for running reliable, cost-controlled, and observable AI agents day to day.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  17. Building Overexposed: understanding application exposure

    The team built an automated scanner called Overexposed to track internet-facing services and verify access controls across Kubernetes and Cloud Run. By querying live cloud inventories and probing endpoints like an outsider, the scanner classifies exposure while avoiding false assumptions from static config files. As a result, the engineering organization improved accuracy and significantly reduced inconclusive findings over time.

    DEPTH ■■■■■8 min read7 days ago

    Sign in to save and rate

  18. Evolving our calendar assistant Reclaim to be AI-native without starting over

    Dropbox engineers evolved their calendar assistant, Reclaim, to support natural-language AI requests by building a custom agent platform that integrates with existing scheduling logic. They utilized a shared action system and a Preview Mode backed by Redis to ensure AI suggestions are consistent and reviewable before affecting real calendars. This approach allows the product to adopt AI capabilities without fragmenting its core architecture or duplicating functionality.

    DEPTH ■■■■■7 min read4 weeks ago

    InfrastructureMachine Learning

    Sign in to save and rate

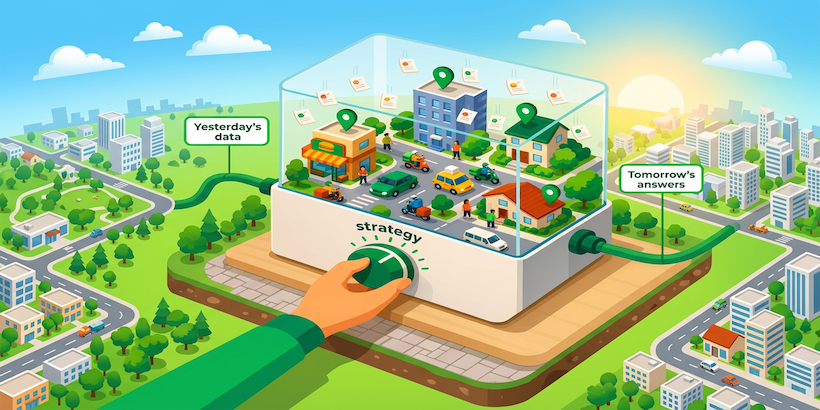
  19. Powering AI-led research through simulation

    The engineering team built a self-contained simulation platform called sim-rs to model marketplace dispatch dynamics and accelerate experimentation. By connecting automated software agents to this simulator with strict safety safeguards, the team successfully optimized strategy policies and simulator performance. This closed-loop lab environment allows agents to test ideas rapidly while ensuring that only valid, production-ready improvements are produced.

    DEPTH ■■■■■10 min read3 weeks ago

    Machine Learning

    Sign in to save and rate

  20. Yandex outage: Data shows that instead of going dark, malicious bots went on the move

    Following physical strikes on Yandex data centers, overall HTTP traffic from the network dropped significantly, leading to speculation that malicious bot farms had been disabled. However, traffic analysis revealed that search crawling simply decreased while malicious automation quickly migrated to other hosting providers with identical fingerprints. Consequently, overall malicious bot traffic remained flat, demonstrating that network disruptions do not stop portable automated workloads.

    DEPTH ■■■■■8 min read12 days ago

    Incidents & Postmortems

    Sign in to save and rate