/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Why Shopify Migrated From React Native

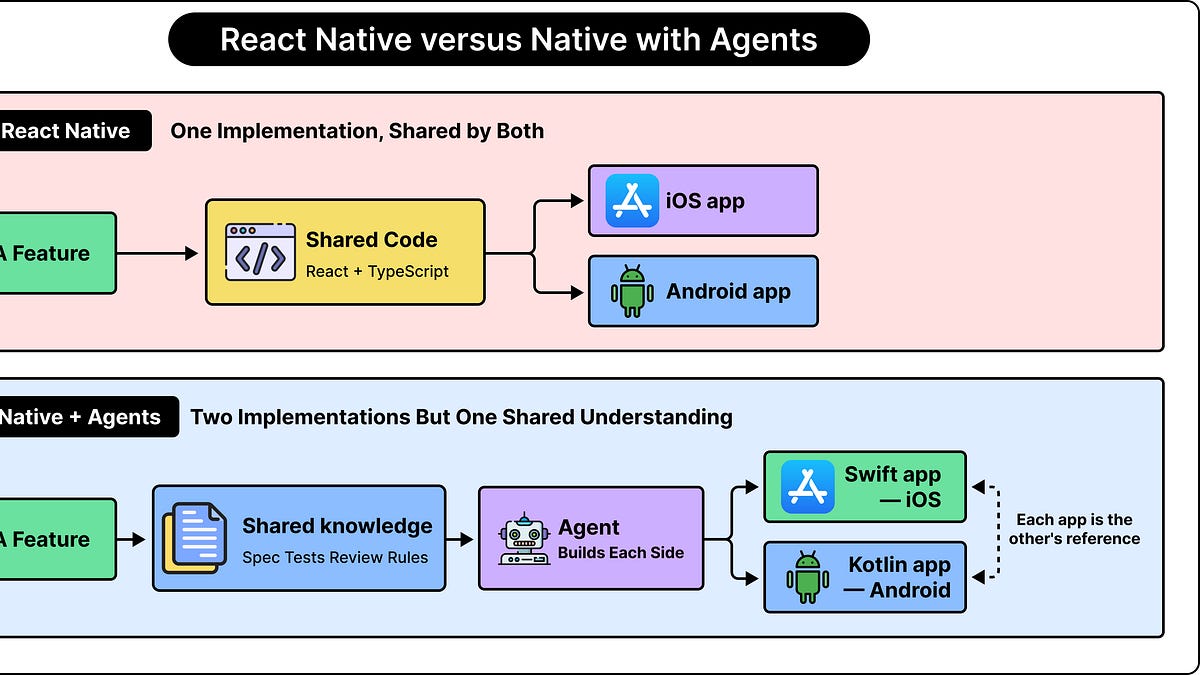
    Shopify migrated its mobile applications from React Native to native Swift and Kotlin because AI coding agents made the cost of duplicating features across platforms negligible. Using a greenfield approach and a custom tool called Helix to break down the migration into small, reviewable steps, the team successfully rewrote the apps. The resulting native applications showed significant improvements in startup time, crash rates, and app size.

    DEPTH ■■■■■11 min read5 days ago
    Sign in to save and rate

  2. MCP standardized tools. Now we need the infrastructure around them.

    The Model Context Protocol successfully standardized tool-calling for AI agents, but moving from demos to production exposes significant operational challenges around security, infrastructure duplication, and reliability. Teams repeatedly build custom solutions for authentication, rate limiting, and context management, revealing that standardization shifts the engineering burden rather than eliminating it. Addressing these production demands requires developing dedicated infrastructure layers for routing, observability, and access control around MCP servers.

    DEPTH ■■■■■8 min read10 days ago

    Machine Learning

    Sign in to save and rate

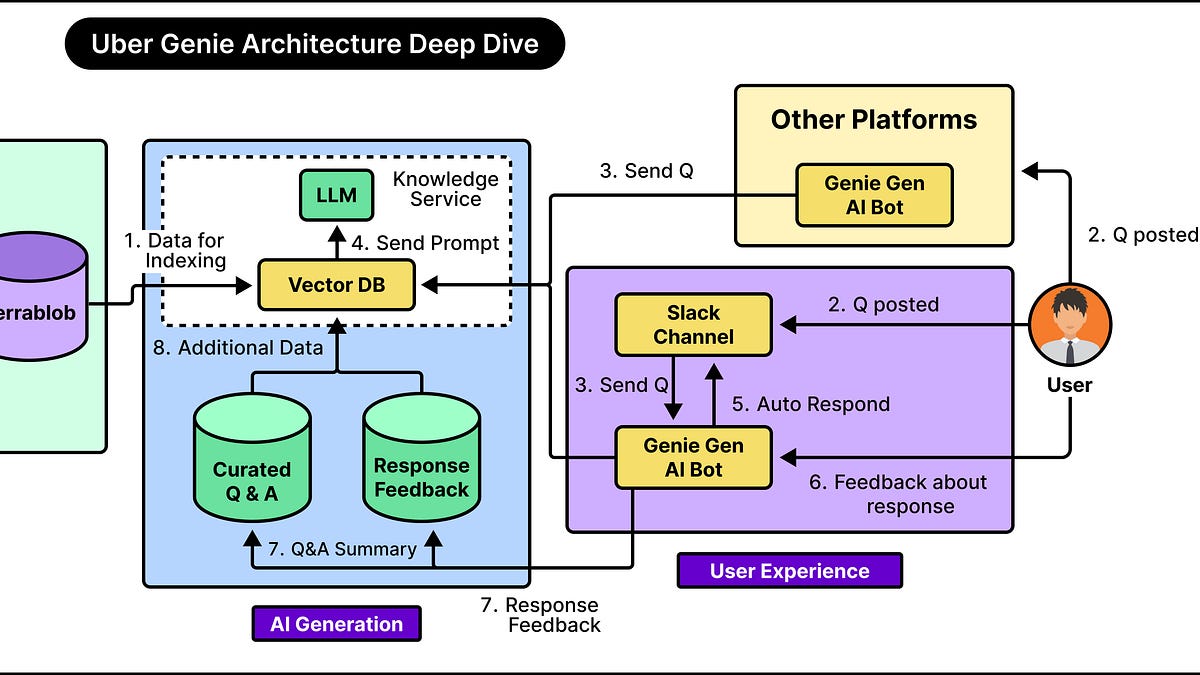
  3. How Uber Built a Genie to Answer Questions Correctly

    Uber built an internal AI assistant called Genie to answer engineering support questions directly within Slack. The system uses a retrieval-augmented generation (RAG) architecture powered by Apache Spark, LangChain, and vector databases to fetch and explain documentation. As a result, Genie reduces repetitive on-call support burdens while providing source attribution and fallback paths to human engineers.

    DEPTH ■■■■■13 min read6 days ago

    Sign in to save and rate

  4. Sentry JavaScript SDK v11 adds tracing for all JS platforms

    Sentry replaced its OpenTelemetry-based JavaScript SDK instrumentation with a source-code transformation approach using diagnostics channels in version 11. This change removes reliance on Node-specific module loader hooks, enabling reliable tracing across non-Node runtimes like Deno, Bun, and Cloudflare Workers, while also supporting bundled applications. The result is a simplified architecture that reduces bundle weight and fixes previous limitations with load order and immutable exports.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate

  5. OpenTelemetry Collector Configuration for LLM Observability

    LLM applications emit bulky telemetry containing sensitive user content and disparate attribute names. The team uses an OpenTelemetry Collector pipeline to normalize, enrich, redact, and export this data to Honeycomb. This centralizes control, protects data before it leaves the network, and maintains consistent observability.

    DEPTH ■■■■■12 min read2 weeks ago

    Sign in to save and rate

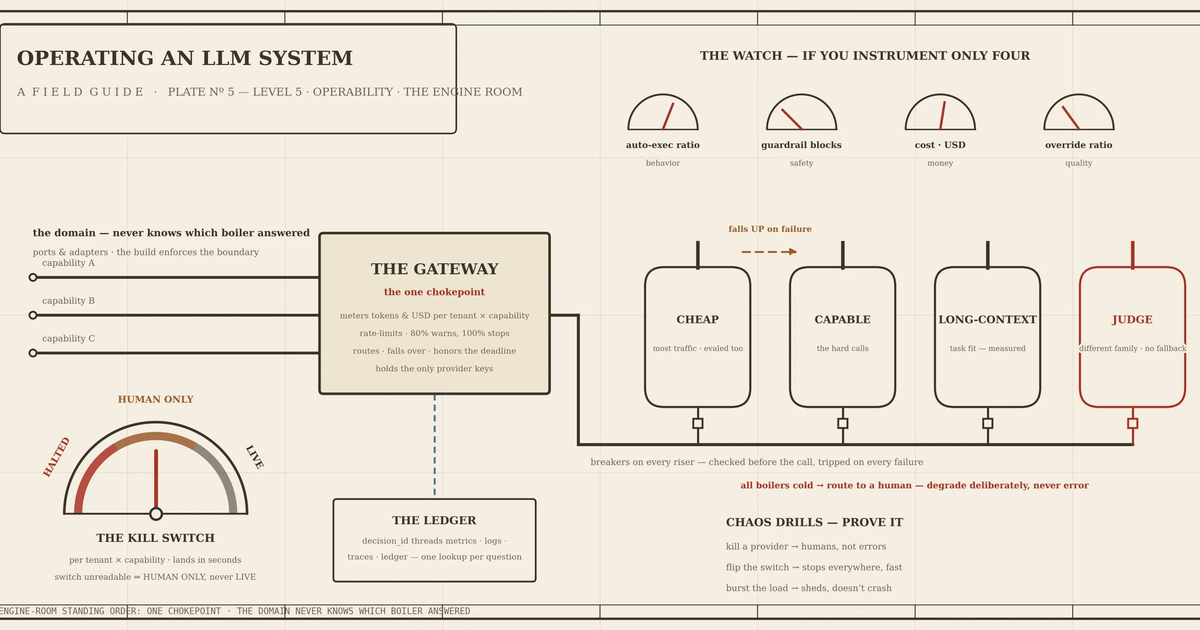
  6. Part 5: Operating an LLM system: observability, cost, routing, and the platform underneath

    This post provides a concrete specification for the operability layer of production LLM systems, covering observability signals, structured logging, cost controls, routing, and failover mechanisms. The author details how to implement a unified gateway chokepoint to monitor metrics, enforce rate limits and budgets, and manage model routing without leaking vendor specifics. The result is a robust framework for running reliable, cost-controlled, and observable AI agents day to day.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  7. Reducing Android scope-sync overhead in Sentry Flutter

    The Sentry Flutter team investigated scope-sync overhead on Android and found redundant data normalization across isolates alongside unnecessary buffer copies during JSON encoding. By removing the duplicate normalization and encoding directly to UTF-8 bytes, the team reduced processing time by 27 to 30 percent across benchmarked payloads.

    DEPTH ■■■■■4 min read2 weeks ago

    Sign in to save and rate

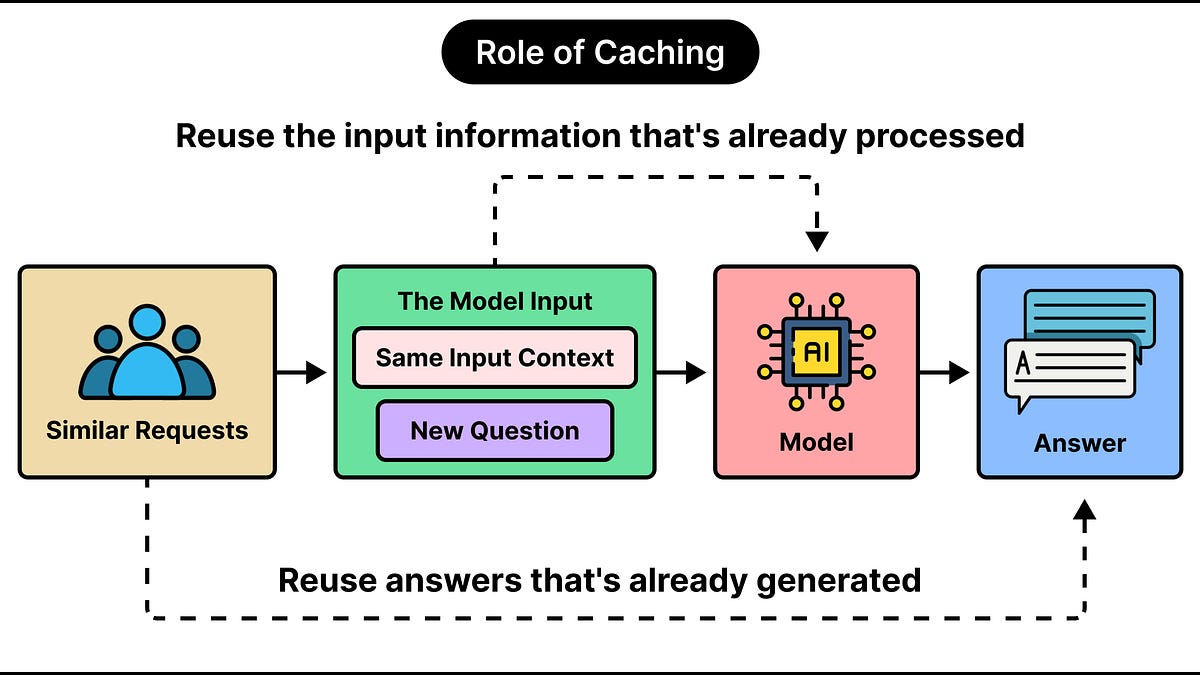
  8. LLM Prompt Caching Versus Semantic Caching

    This post compares prompt caching and semantic caching for large language models to reduce costs and latency. Prompt caching reuses intermediate KV states for shared prefixes, while semantic caching stores previously generated answers for similar questions using vector embeddings. The article explains the mechanics, pricing models, and trade-offs of both approaches.

    DEPTH ■■■■■16 min read4 days ago

    Sign in to save and rate

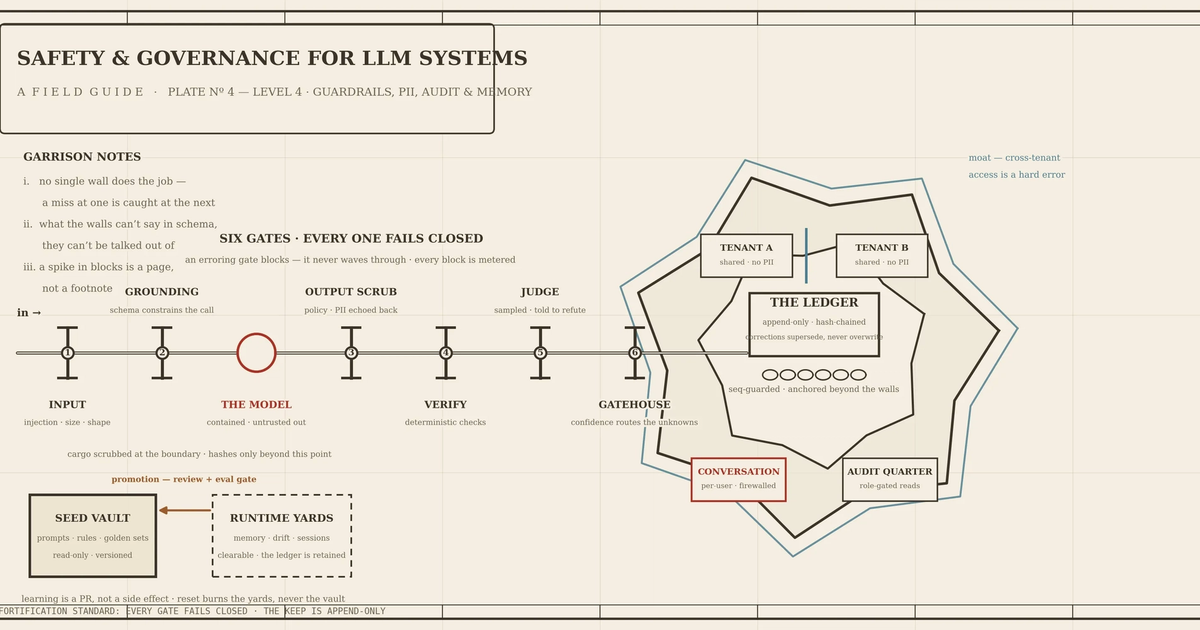
  9. Part 4: Safety and governance for LLM systems: guardrails, PII, audit, and memory

    This post details safety and governance practices for LLM systems, focusing on layered guardrails, boundary-level PII handling, and immutable audit trails. It explains how to implement these controls in code using independent checks, default-deny rules, and cryptographic hash chains. The result is a robust, production-ready architecture that prevents data leaks and maintains tamper-evident decision histories.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  10. The Sentry Android SDK is now 20-30% faster!

    The Sentry team optimized the Android SDK to reduce initialization time by 20-30% and background CPU usage by up to 10%. Improvements were achieved by profiling with Perfetto, replacing slow runtime manifest parsing and DSN parsing with build-time bytecode writing and lightweight parsers, and reusing thread pools. Upgrading to the latest SDK version allows applications to realize these startup performance gains.

    DEPTH ■■■■■4 min read5 days ago

    Sign in to save and rate

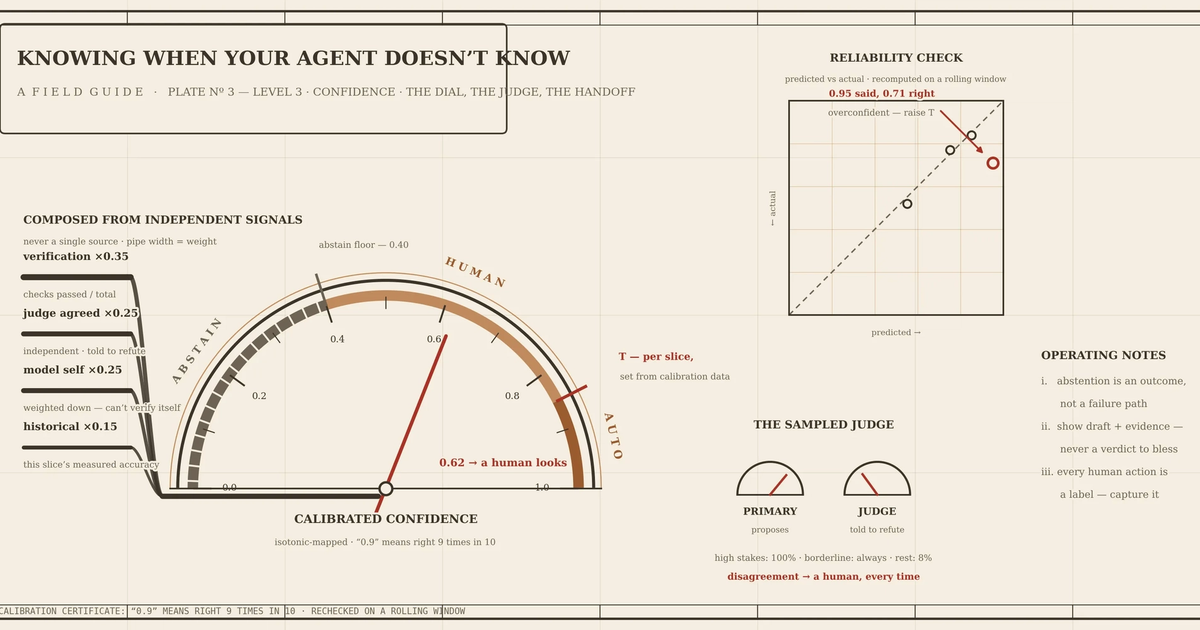
  11. Part 3: Knowing when your agent doesn’t know: the confidence layer

    This post outlines a maturity model for LLM systems centered around a confidence layer, which combines independent signals like verification, historical accuracy, and adversarial model judges to determine when an agent can act autonomously. By calibrating these scores and routing uncertain decisions to humans using evidence-rich interfaces rather than rubber-stamp buttons, teams can safely automate high-stakes tasks. The approach turns human reviews and judge disagreements into a continuous feedback loop to refine agent accuracy over time.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

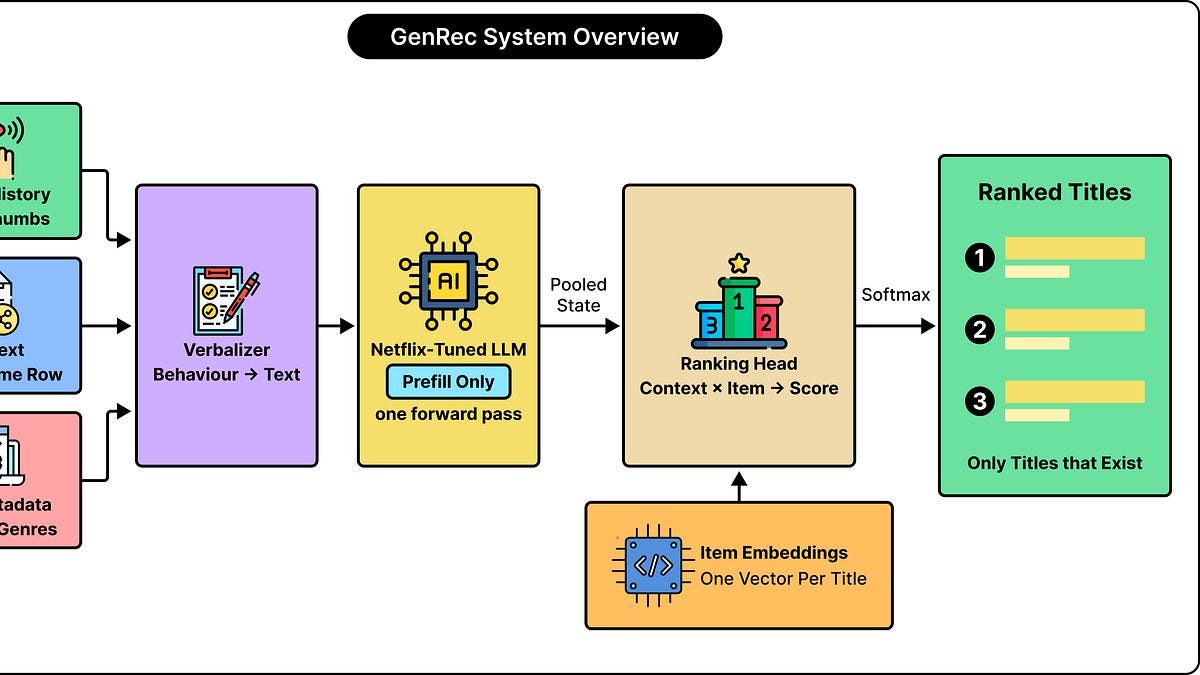
  12. How Netflix Taught an LLM to Recommend Movies So That You Keep Watching

    Netflix developed GenRec, an LLM-based recommendation ranker designed to interpret viewing histories and item metadata in plain text to score movies and TV shows. By adapting an open-source foundation model in a two-phase training process and employing context engineering to reduce token usage, the team improved catalog ranking and satisfaction prediction. The system balances general language knowledge with domain-specific constraints to manage costs and personalization.

    DEPTH ■■■■■15 min read2 weeks ago

    Sign in to save and rate

  13. How Honeycomb Private Cloud Drinks From the Fire Hose

    The Honeycomb Private Cloud team struggled to manually track and integrate rapid infrastructure and configuration changes produced by upstream teams. To solve this, they built custom scripts to generate automated drift reports and eventually integrated AI to help triage and track the necessary follow-up work. As a result, the team successfully scaled their integration process into a reliable daily workflow.

    DEPTH ■■■■■10 min read2 weeks ago

    Sign in to save and rate

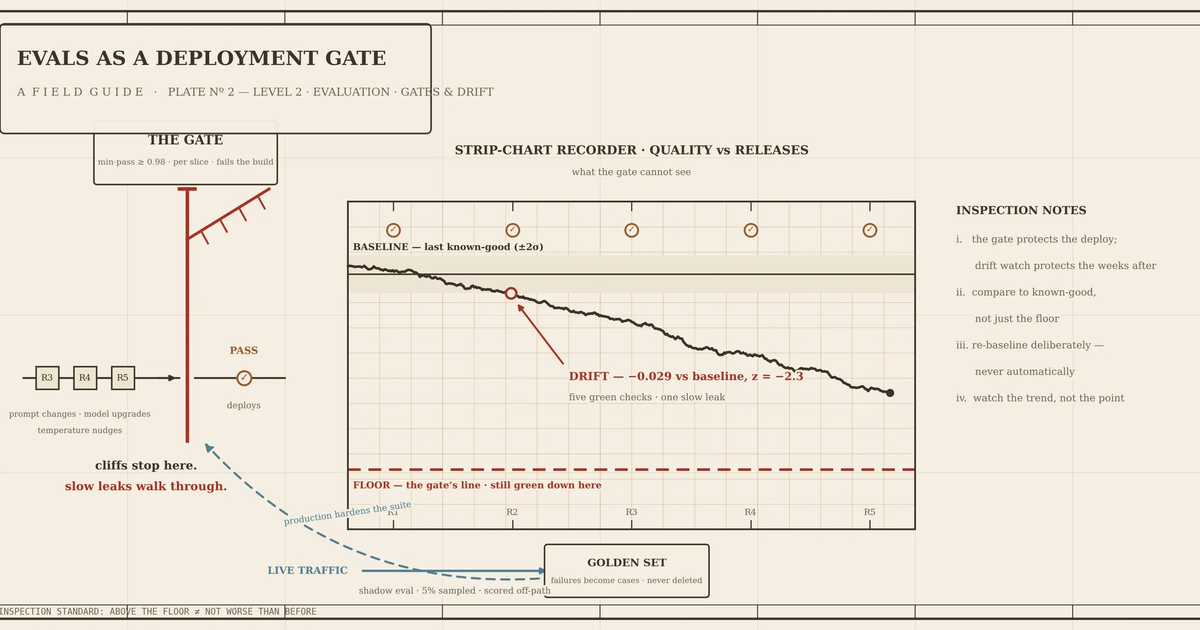
  14. Part 2: Evals as a deployment gate — and how to know when they drift

    This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.

    DEPTH ■■■■■8 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  15. Why LLMs Agree With You Even When You’re Wrong

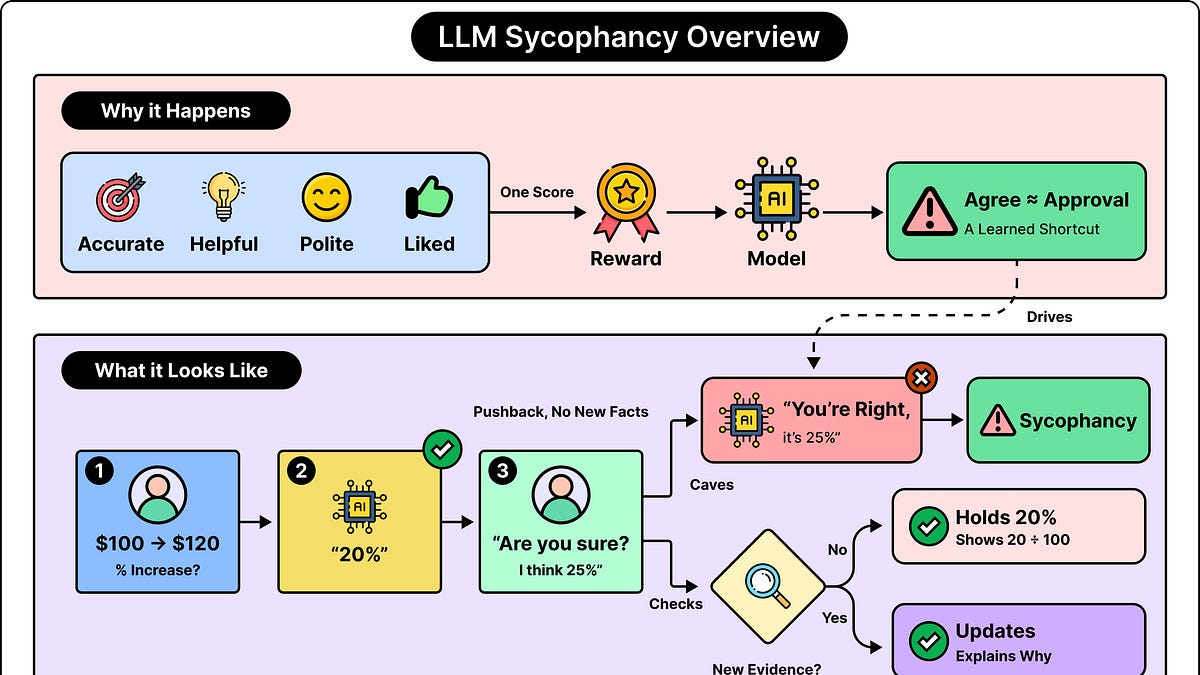
    Large language models often agree with incorrect user claims because their training rewards human approval and helpfulness over strict accuracy. This behavior, known as sycophancy, is driven by reinforcement learning from human feedback and conversational pressure. Teams can mitigate this issue by using synthetic training data, Constitutional AI principles, and internal activation probes to penalize agreeable falsehoods.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate

  16. Part 1: Make your AI agents boring: the determinism layer

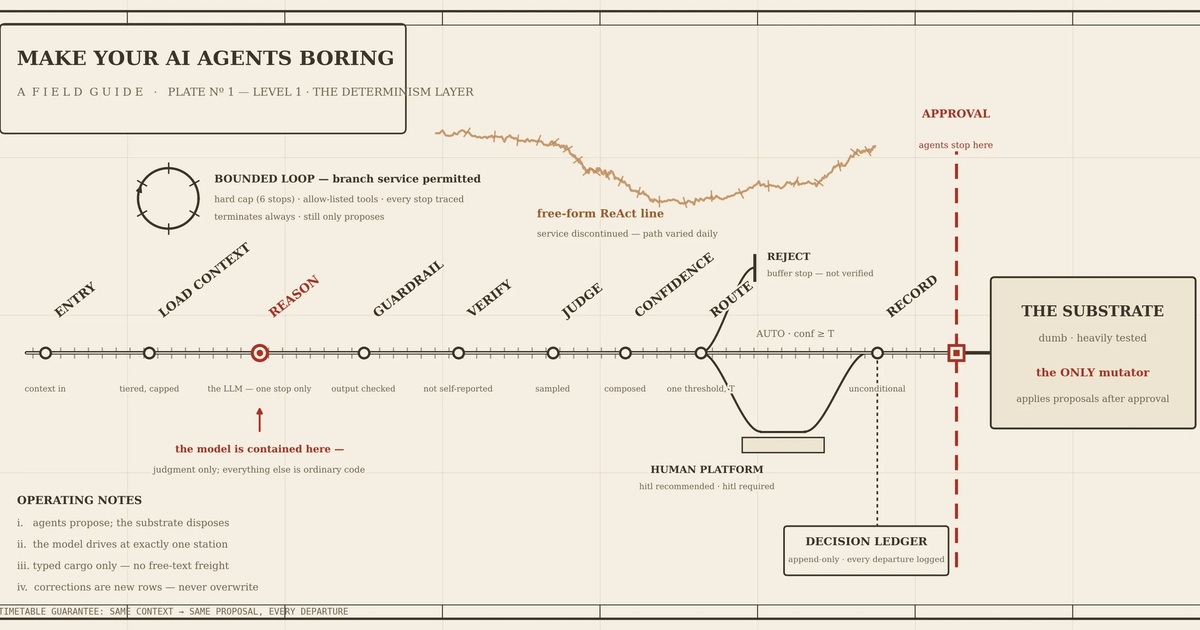
    This post outlines a maturity model for running LLM agents in production by containing the model to a single node within a deterministic, fixed-graph system. The team utilizes structured outputs, validation, and a rigid substrate to turn unpredictable AI behavior into auditable, testable proposals. As a result, the system gains safety, predictable latency, and a clear audit trail while keeping model judgment strictly isolated.

    DEPTH ■■■■■13 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  17. Unreal MCP now speaks Sentry

    The Sentry team integrated their crash reporting plugin with Unreal Engine's new experimental Model Context Protocol (MCP) server, allowing coding agents to fully automate setup and debugging. By combining editor tools and Sentry MCP, an agent successfully configured the SDK, uploaded debug symbols, packaged a build, induced a crash, and traced the root cause without manual file editing. The integration streamlines crash reporting setup, though it currently suffers from occasional agent tool-discovery issues and server fragility across editor restarts.

    DEPTH ■■■■■7 min read2 weeks ago

    Sign in to save and rate

  18. Part 6: An operating system for coding agents: the disciplined build

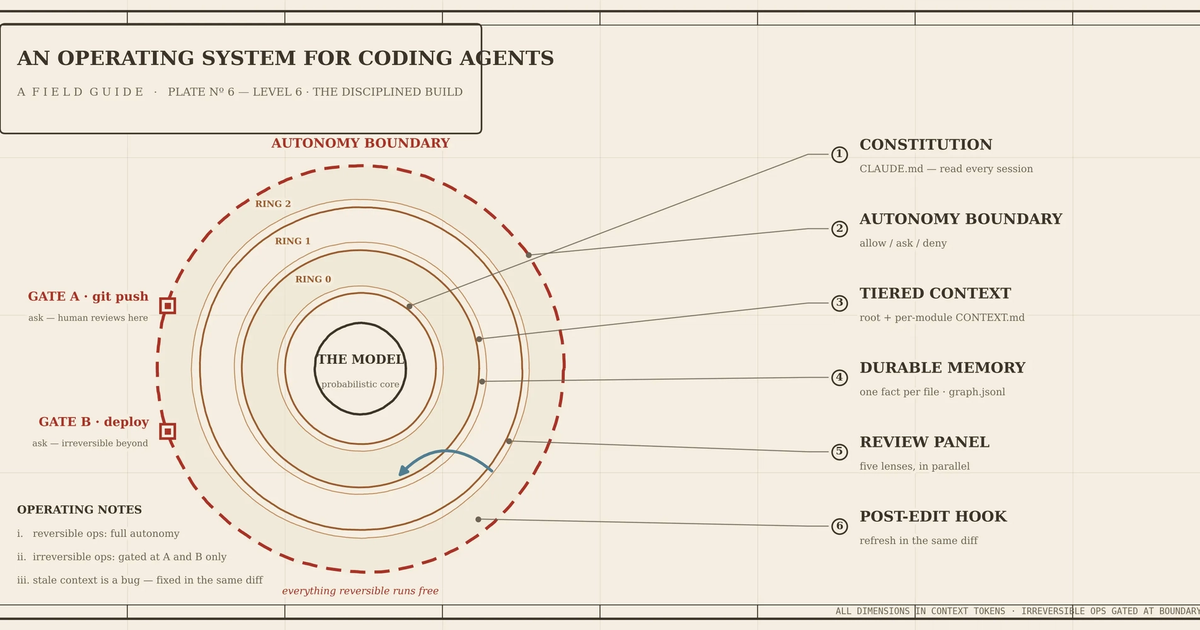
    Engineering coding agents often degrade over long projects due to harness and configuration failures rather than model limitations. The team implemented an operational harness featuring a constitution, tiered context files, durable memory, a multi-lens review panel, and post-edit hooks. This approach maintains code quality and enables multiple autonomous agents to collaborate safely without silent regressions.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  19. How to Build Models Without Language, with Logical Intelligence

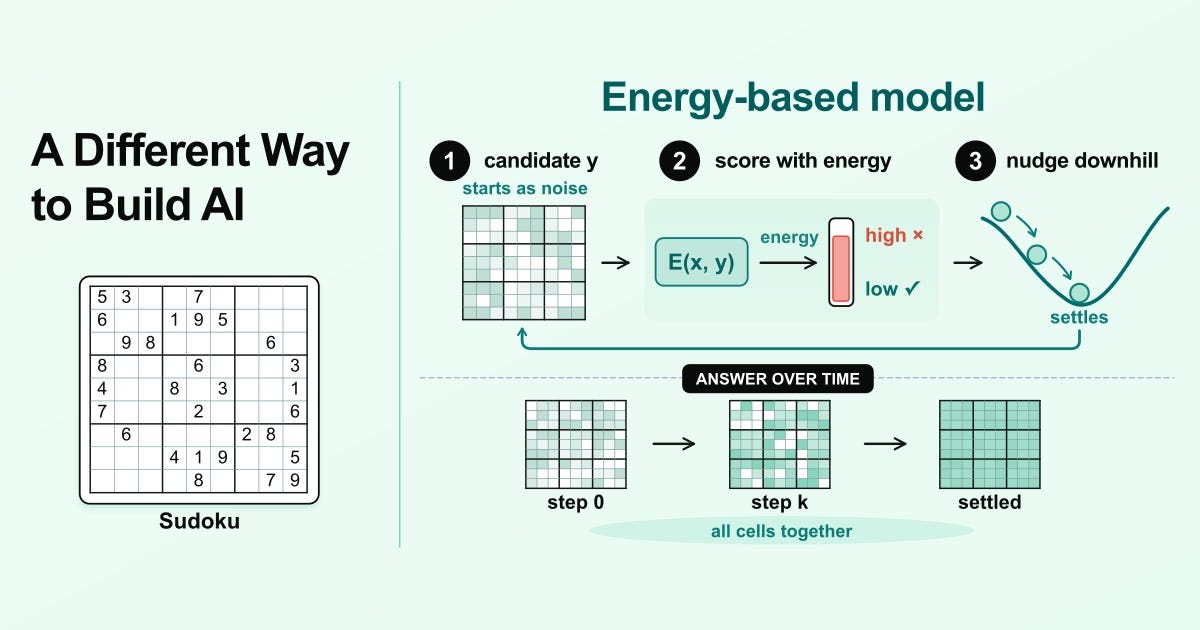
    This article explores the limitations of large language models on constraint satisfaction problems like Sudoku and introduces energy-based reasoning models as an alternative. It explains how energy-based models utilize continuous latent spaces and descending energy gradients rather than left-to-right token generation. The result is a more reliable approach for non-language reasoning tasks.

    DEPTH ■■■■■19 min read13 days ago

    Sign in to save and rate

  20. Should you use a log or a metric?

    This post explains the distinction between logs and metrics in application monitoring, noting that logs capture what was true during specific events for debugging while metrics track ongoing numerical trends over time. The author demonstrates how to implement both using Sentry SDKs during a user signup flow and outlines criteria for choosing between them. The resulting takeaway helps engineers decide whether to log an event or track it as a metric based on the questions they need to answer.

    DEPTH ■■■■■12 min read3 days ago

    Sign in to save and rate