/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. LLM Prompt Caching Versus Semantic Caching

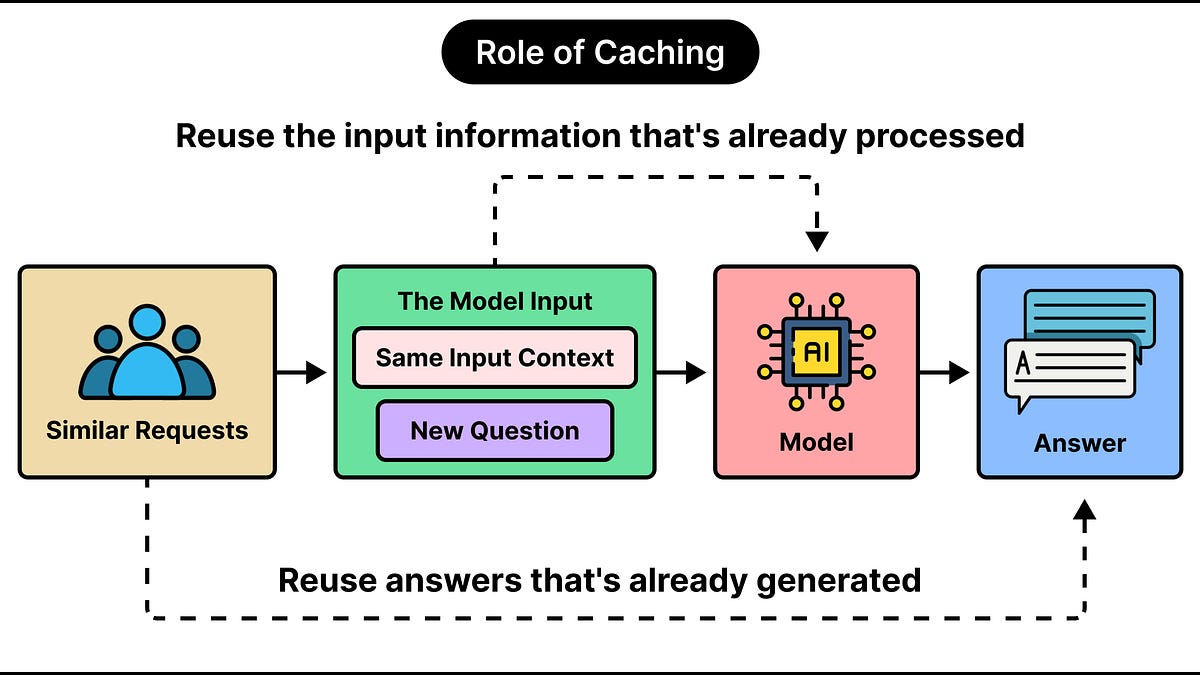
    This post compares prompt caching and semantic caching for large language models to reduce costs and latency. Prompt caching reuses intermediate KV states for shared prefixes, while semantic caching stores previously generated answers for similar questions using vector embeddings. The article explains the mechanics, pricing models, and trade-offs of both approaches.

    DEPTH ■■■■■16 min read6 days ago
    Sign in to save and rate

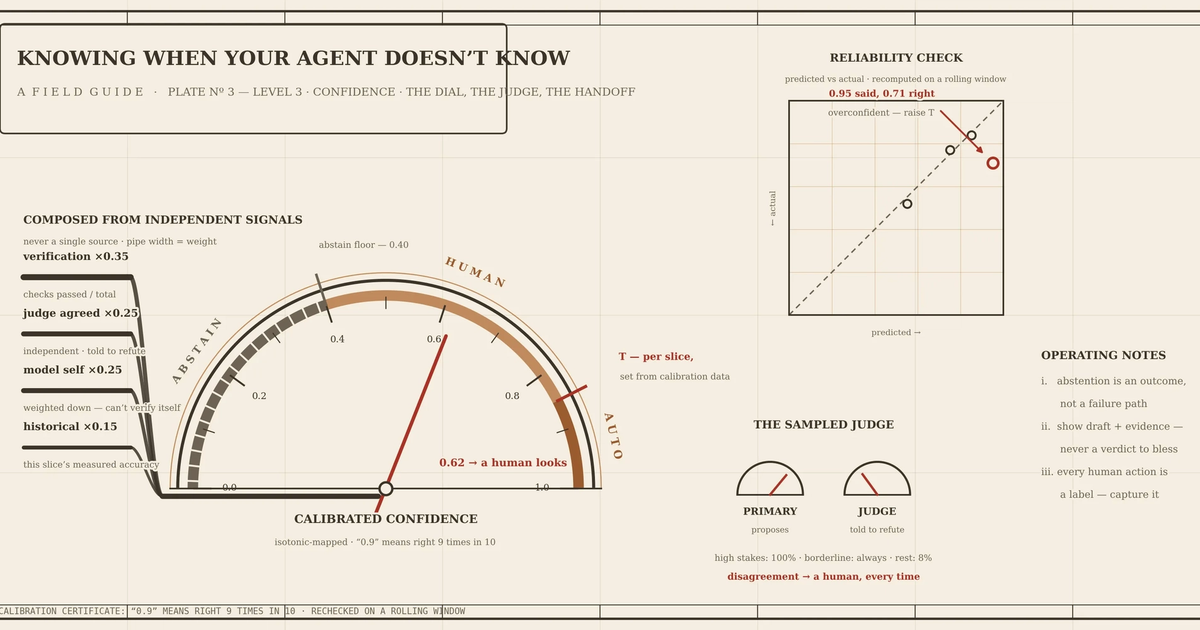
  2. Part 3: Knowing when your agent doesn’t know: the confidence layer

    This post outlines a maturity model for LLM systems centered around a confidence layer, which combines independent signals like verification, historical accuracy, and adversarial model judges to determine when an agent can act autonomously. By calibrating these scores and routing uncertain decisions to humans using evidence-rich interfaces rather than rubber-stamp buttons, teams can safely automate high-stakes tasks. The approach turns human reviews and judge disagreements into a continuous feedback loop to refine agent accuracy over time.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  3. Stopping business email compromise with AI-driven email security: How VIPRE protects modern enterprises on AWS

    VIPRE developed an AI-driven, cloud-native email security solution on AWS to protect enterprises against business email compromise and advanced phishing attacks. The system uses layered machine learning, semantic analysis, and dynamic sandboxing orchestrated via serverless containers and message queues to evaluate over half a million messages daily. In production testing, the architecture successfully identified thousands of BEC attempts while maintaining low-latency processing and reducing administrative overhead.

    DEPTH ■■■■■12 min read2 weeks ago

    Sign in to save and rate

  4. How we built an async-aware Python profiler

    Traditional Python profilers treat asyncio tasks as independent stacks, obscuring logical execution paths and relationships. The Datadog team built an async-aware profiling model that tracks task dependencies to reconstruct unified execution paths ("stacked stacks") while reducing profiling overhead by over 60 percent. This approach provides clearer performance visibility for asynchronous applications without excessive production latency.

    DEPTH ■■■■■19 min read3 weeks ago

    Sign in to save and rate

  5. Staying Evergreen: How we automated secure access and repo hygiene in a shared org

    Manual repository housekeeping and access reviews for outside collaborators become difficult to maintain as organizations scale. The team built Evergreen, a GitHub App that automates quarterly access reviews and stale repository archiving using native platform features and IssueOps. This automation successfully enforces secure defaults by revoking unanswered access while maintaining a full audit trail in git history.

    DEPTH ■■■■■8 min read11 days ago

    Sign in to save and rate

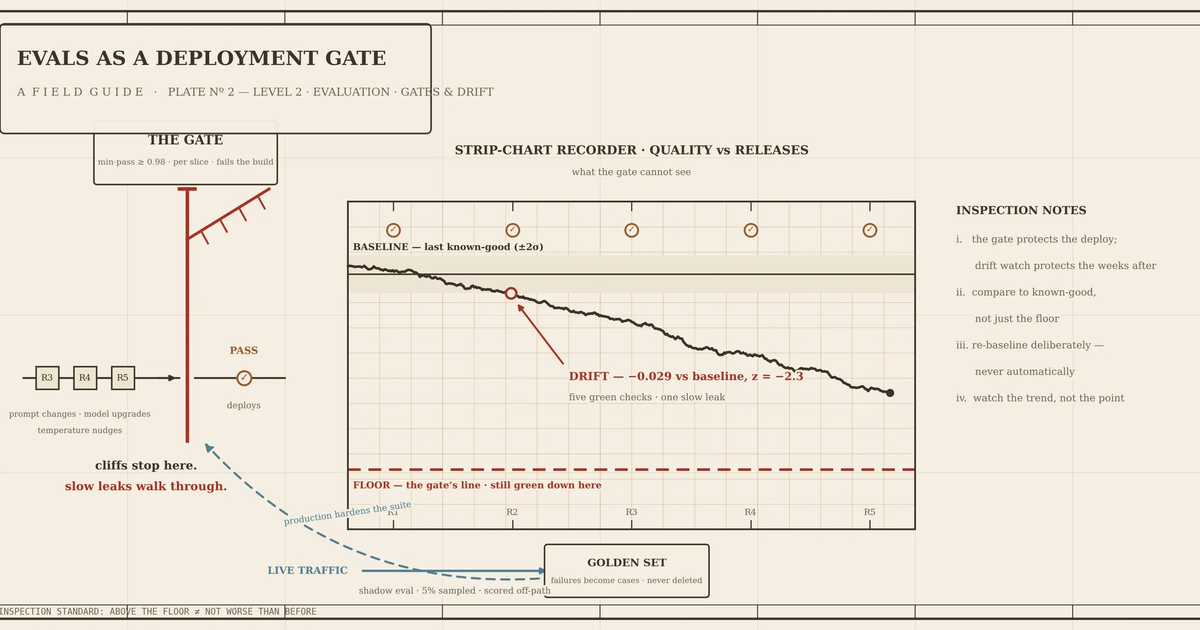
  6. Part 2: Evals as a deployment gate — and how to know when they drift

    This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.

    DEPTH ■■■■■8 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  7. How Netflix Taught an LLM to Recommend Movies So That You Keep Watching

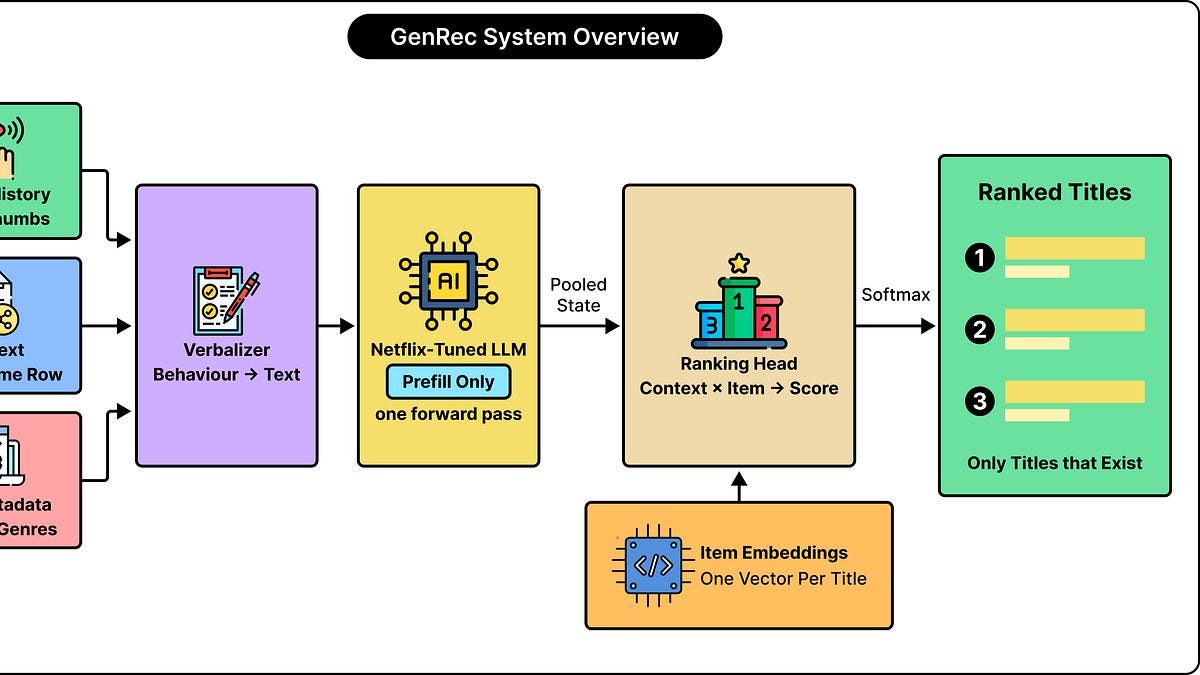
    Netflix developed GenRec, an LLM-based recommendation ranker designed to interpret viewing histories and item metadata in plain text to score movies and TV shows. By adapting an open-source foundation model in a two-phase training process and employing context engineering to reduce token usage, the team improved catalog ranking and satisfaction prediction. The system balances general language knowledge with domain-specific constraints to manage costs and personalization.

    DEPTH ■■■■■15 min read2 weeks ago

    Sign in to save and rate

  8. Bulk Executor for Amazon DynamoDB, Part 2: Lessons we learned the hard way

    Engineering a bulk execution tool for Amazon DynamoDB using AWS Glue required addressing several architectural challenges, including cost estimation, graceful job termination, and error handling across hundreds of parallel workers. The team overcame limitations in CloudWatch logging and the Spark connector by combining serverless execution with direct API calls and distributed rate limiting. As a result, the tool provides a scalable, script-like interface for managing large-scale table operations safely.

    DEPTH ■■■■■14 min read2 weeks ago

    Sign in to save and rate

  9. Part 1: Make your AI agents boring: the determinism layer

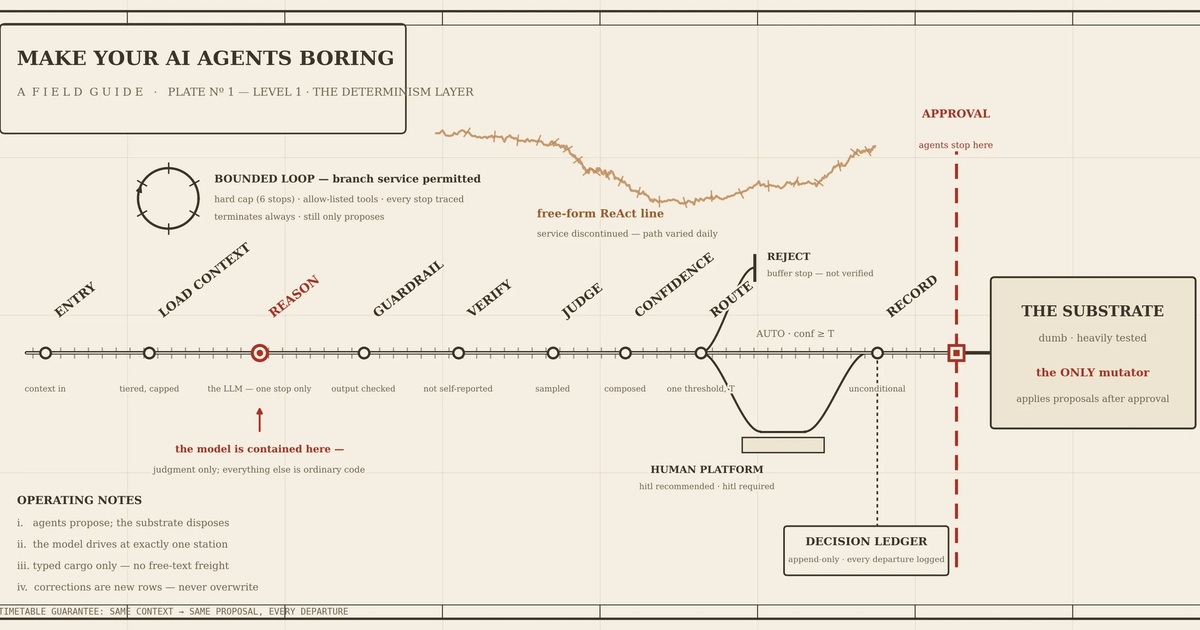
    This post outlines a maturity model for running LLM agents in production by containing the model to a single node within a deterministic, fixed-graph system. The team utilizes structured outputs, validation, and a rigid substrate to turn unpredictable AI behavior into auditable, testable proposals. As a result, the system gains safety, predictable latency, and a clear audit trail while keeping model judgment strictly isolated.

    DEPTH ■■■■■13 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  10. Why LLMs Agree With You Even When You’re Wrong

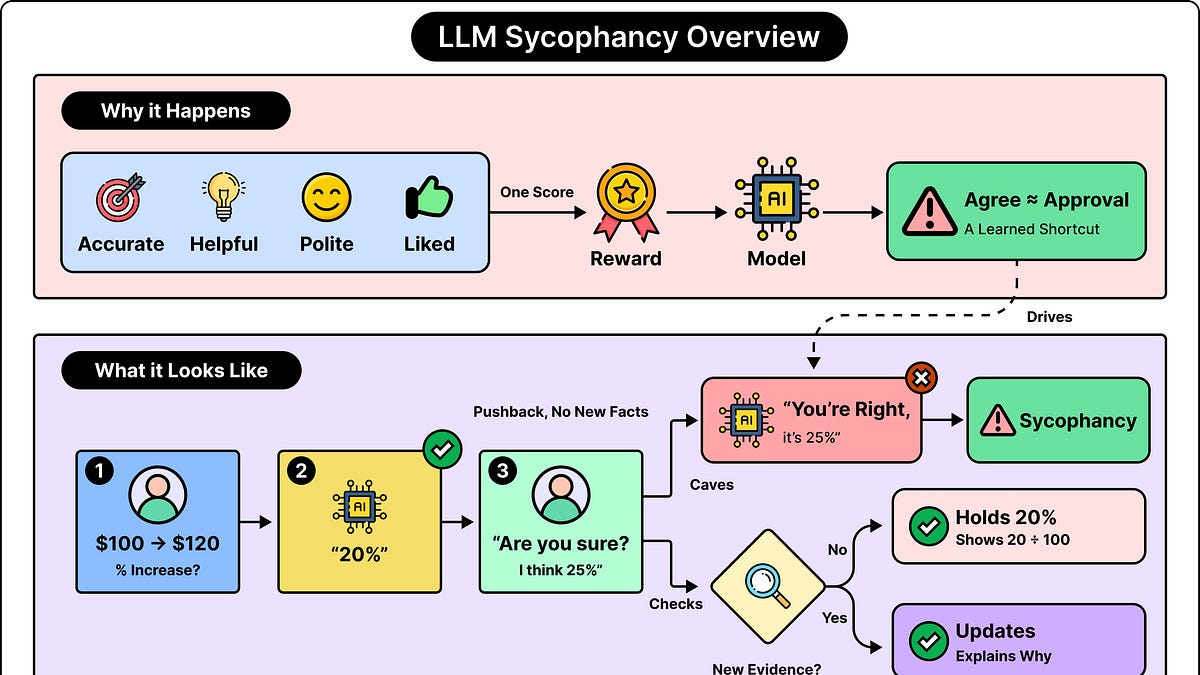
    Large language models often agree with incorrect user claims because their training rewards human approval and helpfulness over strict accuracy. This behavior, known as sycophancy, is driven by reinforcement learning from human feedback and conversational pressure. Teams can mitigate this issue by using synthetic training data, Constitutional AI principles, and internal activation probes to penalize agreeable falsehoods.

    DEPTH ■■■■■13 min read3 weeks ago

    Sign in to save and rate

  11. Unreal MCP now speaks Sentry

    The Sentry team integrated their crash reporting plugin with Unreal Engine's new experimental Model Context Protocol (MCP) server, allowing coding agents to fully automate setup and debugging. By combining editor tools and Sentry MCP, an agent successfully configured the SDK, uploaded debug symbols, packaged a build, induced a crash, and traced the root cause without manual file editing. The integration streamlines crash reporting setup, though it currently suffers from occasional agent tool-discovery issues and server fragility across editor restarts.

    DEPTH ■■■■■7 min read3 weeks ago

    Sign in to save and rate

  12. Agentic antimicrobial resistance surveillance with AWS HealthOmics and Amazon Bedrock AgentCore

    Processing public bacterial sequencing data for antimicrobial resistance surveillance typically requires specialized bioinformatics and SQL skills. To streamline this process, the team built a reference architecture using AWS HealthOmics, Amazon S3 Tables, and an Amazon Bedrock AgentCore conversational agent that ingests raw reads, normalizes findings, and answers plain-language questions with cited evidence. The resulting system automates the path from public accession numbers to natural-language epidemiological answers.

    DEPTH ■■■■■10 min read2 weeks ago

    Sign in to save and rate

  13. Improving site performance by shipping more CSS

    GitHub faced performance degradation on server-side rendering and initial page loads due to scaling issues with its CSS-in-JS solution. The engineering team executed a multi-year migration to CSS Modules and eliminated dynamic styling props using incremental rollouts, wrapper components, and automation tools. This resulted in significant performance gains, including 55% faster server-side rendering and the complete removal of styled-components.

    DEPTH ■■■■■8 min read4 weeks ago

    FrontendPerformance

    Sign in to save and rate

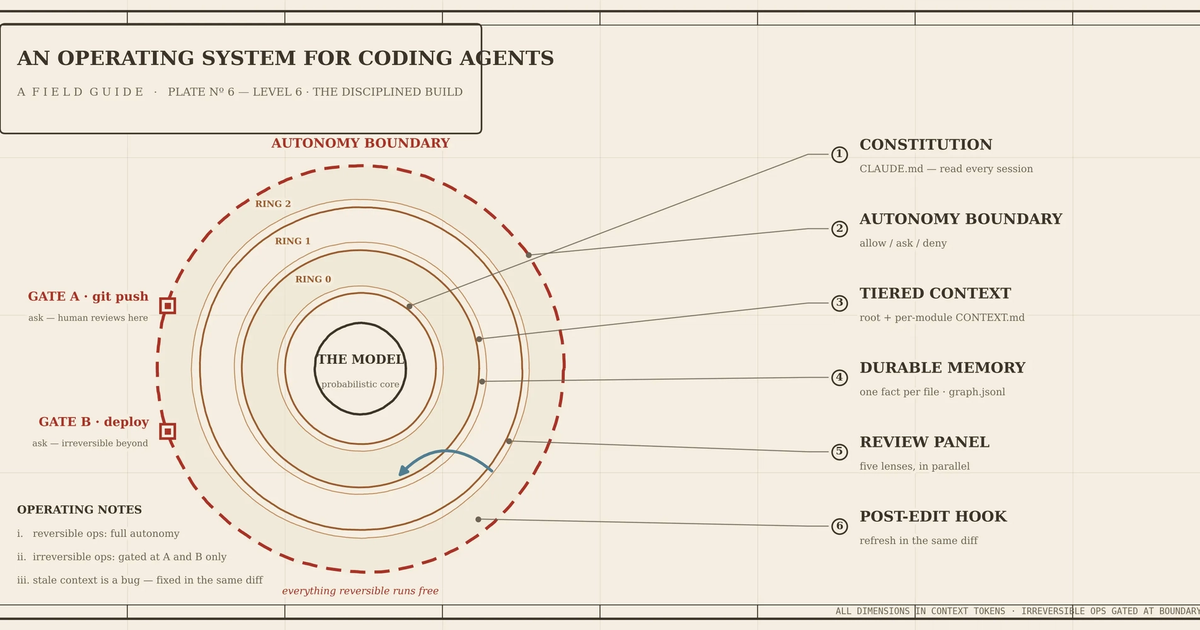
  14. Part 6: An operating system for coding agents: the disciplined build

    Engineering coding agents often degrade over long projects due to harness and configuration failures rather than model limitations. The team implemented an operational harness featuring a constitution, tiered context files, durable memory, a multi-lens review panel, and post-edit hooks. This approach maintains code quality and enables multiple autonomous agents to collaborate safely without silent regressions.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

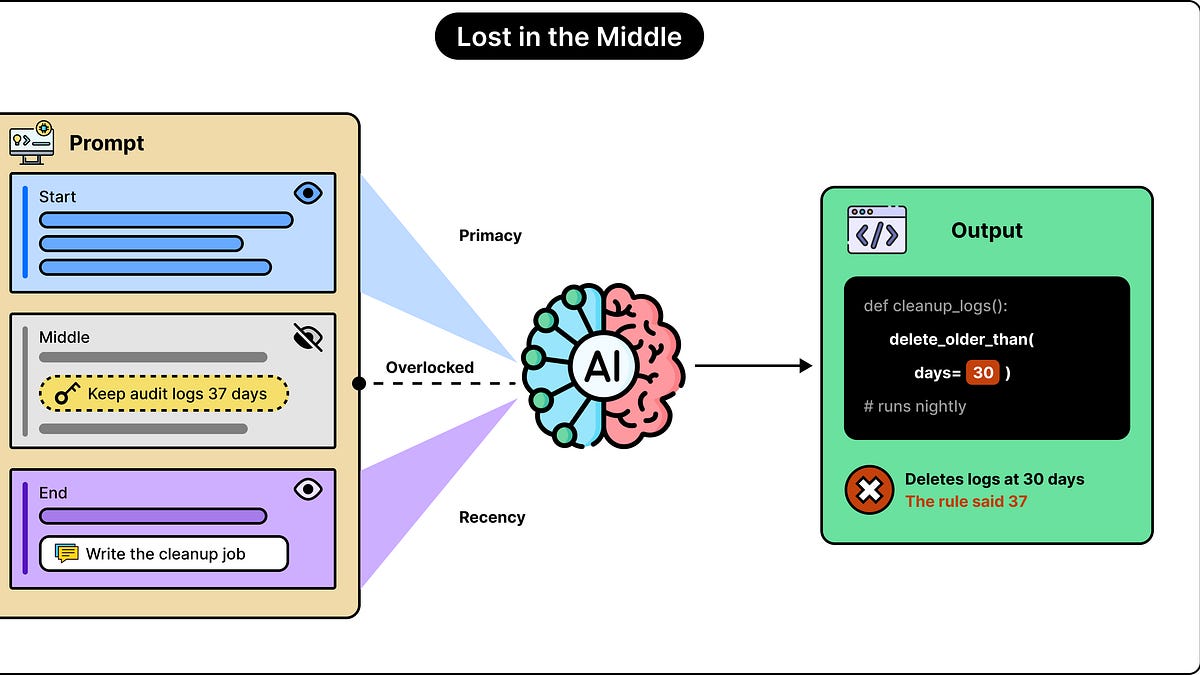
  15. The LLM Blindspot: Why Models Forget What’s in the Middle of Your Prompt

    Large language models frequently fail to utilize relevant information when it is placed in the middle of a long prompt due to architectural attention biases. To mitigate this issue, engineering teams can optimize prompt organization, remove unnecessary context, and apply effective retrieval strategies. Ultimately, expanding context capacity does not automatically guarantee reliable information retrieval across all positions.

    DEPTH ■■■■■11 min read3 weeks ago

    Sign in to save and rate

  16. Should you use a log or a metric?

    This post explains the distinction between logs and metrics in application monitoring, noting that logs capture what was true during specific events for debugging while metrics track ongoing numerical trends over time. The author demonstrates how to implement both using Sentry SDKs during a user signup flow and outlines criteria for choosing between them. The resulting takeaway helps engineers decide whether to log an event or track it as a metric based on the questions they need to answer.

    DEPTH ■■■■■12 min read5 days ago

    Sign in to save and rate

  17. Rendering huge pull requests in the GitHub Copilot app

    Rendering extremely large pull requests with millions of lines and hundreds of comments requires separating deterministic code row geometry from unpredictable dynamic comment blocks. The team implemented an idle-gated measurement scheduler, separate height indices, and identity-based scroll anchoring to maintain smooth scrolling. As a result, the pull request view remains performant and responsive even under extreme loads.

    DEPTH ■■■■■14 min read4 weeks ago

    Sign in to save and rate

  18. Deploy Oracle Database step by step on Amazon EVS with FSx for ONTAP

    This post provides a step-by-step guide to deploying Oracle Database 19c on Amazon Elastic VMware Service using Amazon FSx for NetApp ONTAP as an NFS datastore. It covers provisioning storage, mounting datastores, installing Oracle, configuring SnapMirror for cross-region disaster recovery, and outlining four migration paths. The result is a fully functional enterprise database deployment that preserves existing operational workflows.

    DEPTH ■■■■■11 min read3 weeks ago

    Sign in to save and rate

  19. How Etsy gets its mobile apps ready for peak traffic

    Etsy prepares its mobile apps for peak holiday traffic through advance planning, operational guardrails, and risk management rather than relying on capacity scaling or the ability to quickly revert binaries. The engineering team utilizes a phased code slush, dual crash reporting, remote feature flags, and custom error tagging to surface and mitigate issues effectively under heavy loads. By connecting crash rates to business metrics and automating manual triage workflows incrementally, the organization maintains high visibility and reliability when updates cannot be instantly rolled back.

    DEPTH ■■■■■11 min read3 weeks ago

    Sign in to save and rate

  20. How to Build Models Without Language, with Logical Intelligence

    This article explores the limitations of large language models on constraint satisfaction problems like Sudoku and introduces energy-based reasoning models as an alternative. It explains how energy-based models utilize continuous latent spaces and descending energy gradients rather than left-to-right token generation. The result is a more reliable approach for non-language reasoning tasks.

    DEPTH ■■■■■19 min read2 weeks ago

    Sign in to save and rate