/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read12 days ago
    Microservices

    Sign in to save and rate

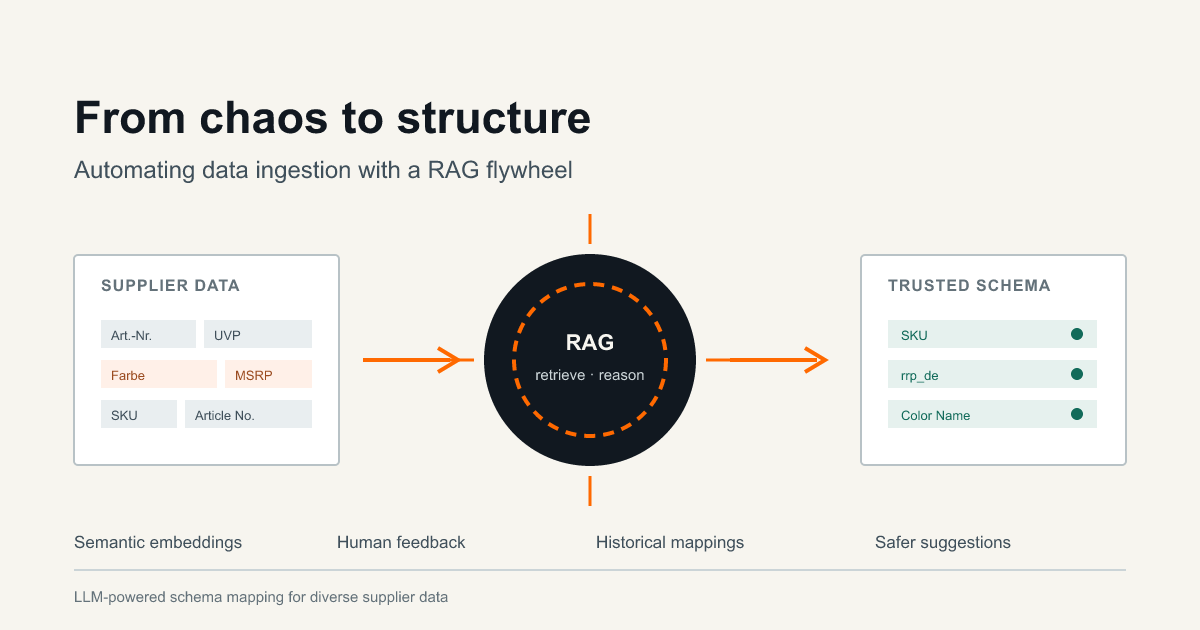
  2. Automating Data Ingestion with a RAG Flywheel

    Zalando replaced manual schema mapping for diverse supplier data with an LLM-powered Retrieval-Augmented Generation (RAG) flywheel. The system combines Amazon Titan embeddings stored in PostgreSQL via pgvector with tool-constrained generative models running at zero temperature. Every LLM suggestion passes through strict API validation checks before being reviewed by operations specialists, creating a continuous learning loop that improves future predictions.

    DEPTH ■■■■■14 min read2 weeks ago

    Machine LearningPostgreSQL

    Sign in to save and rate

  3. Thundering herd of circuit breakers

    An engineering team investigated why a client-side circuit breaker repeatedly failed to close on its own after an outage. By exporting OpenTelemetry traces into a custom visualization tool, they discovered that low probe traffic caused the autoscaler to scale down the service to minimum capacity, triggering a thundering herd of requests and immediate timeouts the moment the circuit breaker closed. Adjusting the system to account for capacity and probe representativeness prevents this oscillation.

    DEPTH ■■■■■10 min read2 weeks ago

    MicroservicesObservabilityReliability

    Sign in to save and rate