/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Origin Range Requests: Serving large files without range-request tuning

    Cloudflare replaced a legacy, fixed-size range caching design that suffered from bandwidth waste and memory pressure with a Pingora-based chunk coordinator. The new implementation dynamically combines cached chunks and aligned origin fetches to serve range requests accurately without manual tuning. This approach cut p99 time to first byte in half for R2 storage and reduced tiered cache traffic by six percent.

    DEPTH ■■■■■8 min read2 days ago

    DatabasesPerformanceRedis

    Sign in to save and rate

  2. Shard design doesn't start from your tables

    Designing a sharded Postgres architecture requires grouping tables around shared query keys rather than starting from table structures alone. The post details how to configure shard groups, reference tables, SQL expressions in shard indexes, and global secondary indexes using Neki. This setup enables efficient single-shard queries and transactions while maintaining full Postgres semantics.

    DEPTH ■■■■■8 min read2 days ago
    PostgreSQL

    Sign in to save and rate

  3. Bringing post-quantum cryptography to geographically fenced key management

    Cloudflare introduced a post-quantum geographically restricted key manager in closed beta to enforce data sovereignty and protect customers against harvest-now-decrypt-later attacks. The team implemented a hybrid ML-KEM-768 and X25519 cryptographic design that separates globally distributed wrapped private keys from regionally restricted root keys. This ensures that decryption keys are only accessible within authorized geographical boundaries and fails closed if validation fails.

    DEPTH ■■■■■12 min read2 days ago

    Security

    Sign in to save and rate

  4. MCP standardized tools. Now we need the infrastructure around them.

    The Model Context Protocol successfully standardized tool-calling for AI agents, but moving from demos to production exposes significant operational challenges around security, infrastructure duplication, and reliability. Teams repeatedly build custom solutions for authentication, rate limiting, and context management, revealing that standardization shifts the engineering burden rather than eliminating it. Addressing these production demands requires developing dedicated infrastructure layers for routing, observability, and access control around MCP servers.

    DEPTH ■■■■■8 min read10 days ago

    Machine Learning

    Sign in to save and rate

  5. I don't trust ON DELETE CASCADE

    Postgres ON DELETE CASCADE can cause production outages, replication failures, and performance degradation during large deletions or schema migrations due to long-running transactions holding locks and generating massive WAL. The author recommends using soft deletes with batched background cleanup instead to keep transactions short and bounded. This approach avoids table locks and simplifies data recovery.

    DEPTH ■■■■■5 min read4 days ago

    PostgreSQL

    Sign in to save and rate

  6. Better HTTP/1 connection reuse

    Failing to read an HTTP/1 response body completely prevents connection reuse, forcing clients to repeatedly pay the high cost of TCP and TLS handshakes. While developers previously had to implement complex manual body-draining logic, Go 1.27 introduces automatic asynchronous response draining in the net/http package. This improvement allows developers to simply close response bodies without worrying about connection pooling performance.

    DEPTH ■■■■■7 min read11 days ago

    Sign in to save and rate

  7. Cutting our inference bill by 68% by being obsessive about optimization

    An engineering team investigated a steady rise in AI code review costs and found that cache misses and redundant model calls were driving up expenses. By restructuring system prompts to enable cross-repository prompt caching, eliminating wasted tool calls, and switching to more efficient models, the team cut inference costs by 68% while also significantly improving review latency.

    DEPTH ■■■■■15 min read6 days ago

    Machine Learning

    Sign in to save and rate

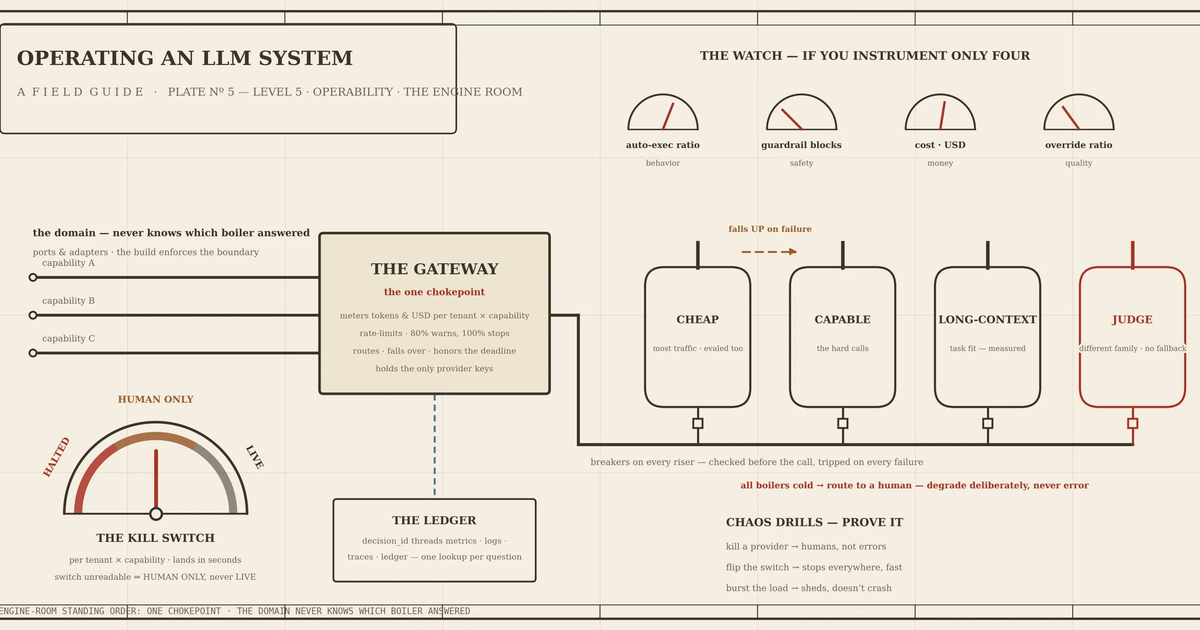
  8. Part 5: Operating an LLM system: observability, cost, routing, and the platform underneath

    This post provides a concrete specification for the operability layer of production LLM systems, covering observability signals, structured logging, cost controls, routing, and failover mechanisms. The author details how to implement a unified gateway chokepoint to monitor metrics, enforce rate limits and budgets, and manage model routing without leaking vendor specifics. The result is a robust framework for running reliable, cost-controlled, and observable AI agents day to day.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  9. What gets TOASTed in Postgres

    This post examines how PostgreSQL uses TOAST to manage oversized rows and variable-length columns through compression and off-row storage. It compares the pglz and LZ4 compression algorithms across different workloads, highlighting trade-offs in search windows, file sizes, and CPU overhead. The analysis demonstrates how these mechanisms impact storage efficiency and read performance for large text and JSON data.

    DEPTH ■■■■■12 min read13 days ago

    PostgreSQL

    Sign in to save and rate

  10. Arch-specific SIMD in Go

    Go 1.27 introduces the archsimd package to provide low-level architecture-specific SIMD intrinsics for amd64, arm64, and wasm without requiring assembly. The API uses sensible naming conventions, zero-cost type reinterpretation, and opaque masks to improve usability and maintainability while achieving high performance. The resulting design enables developers to write optimized vectorized code safely with proper runtime CPU feature checking and compiler optimizations.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

  11. Yandex outage: Data shows that instead of going dark, malicious bots went on the move

    Following physical strikes on Yandex data centers, overall HTTP traffic from the network dropped significantly, leading to speculation that malicious bot farms had been disabled. However, traffic analysis revealed that search crawling simply decreased while malicious automation quickly migrated to other hosting providers with identical fingerprints. Consequently, overall malicious bot traffic remained flat, demonstrating that network disruptions do not stop portable automated workloads.

    DEPTH ■■■■■8 min read11 days ago

    Incidents & Postmortems

    Sign in to save and rate

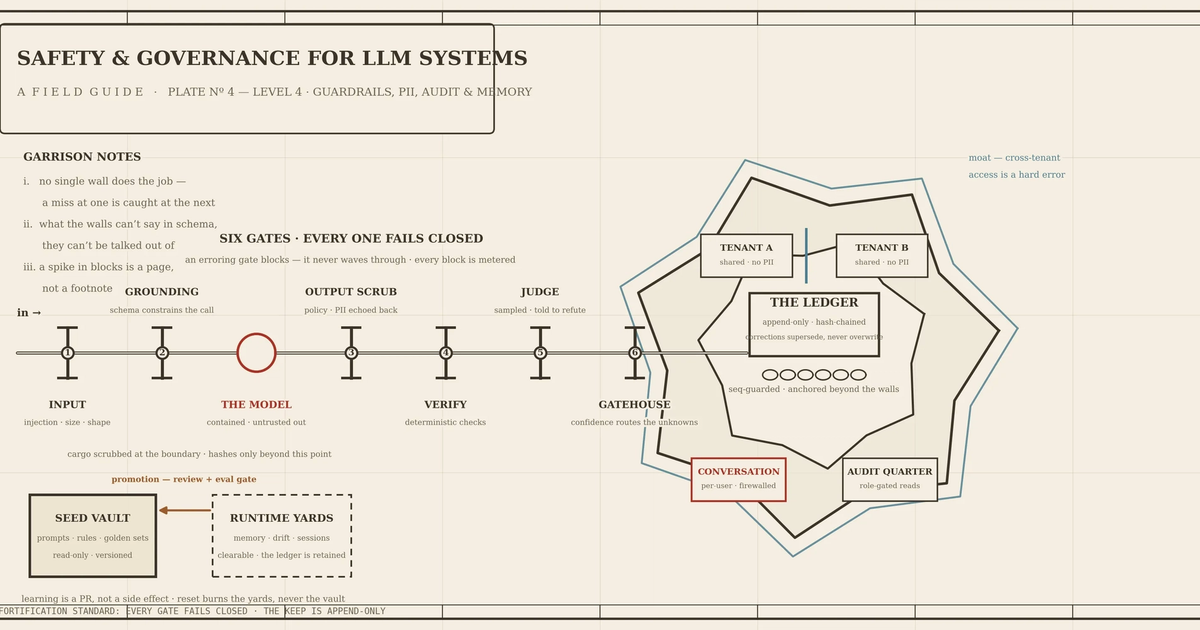
  12. Part 4: Safety and governance for LLM systems: guardrails, PII, audit, and memory

    This post details safety and governance practices for LLM systems, focusing on layered guardrails, boundary-level PII handling, and immutable audit trails. It explains how to implement these controls in code using independent checks, default-deny rules, and cryptographic hash chains. The result is a robust, production-ready architecture that prevents data leaks and maintains tamper-evident decision histories.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  13. TIN v1.0.6: 2-3x faster, with support for stemming

    Following competitive benchmarks that highlighted opportunities for optimization, the developers of the TIN full-text search index for Postgres released versions 1.0.4 and 1.0.6. These updates added Snowball stemming for 18 languages, optimized top-k sorting queries with deterministic tiebreakers, and improved overall query performance. As a result, benchmark tests show that TIN outperforms competing extensions across conjunction, disjunction, and phrase query workloads.

    DEPTH ■■■■■8 min read2 weeks ago

    PostgreSQL

    Sign in to save and rate

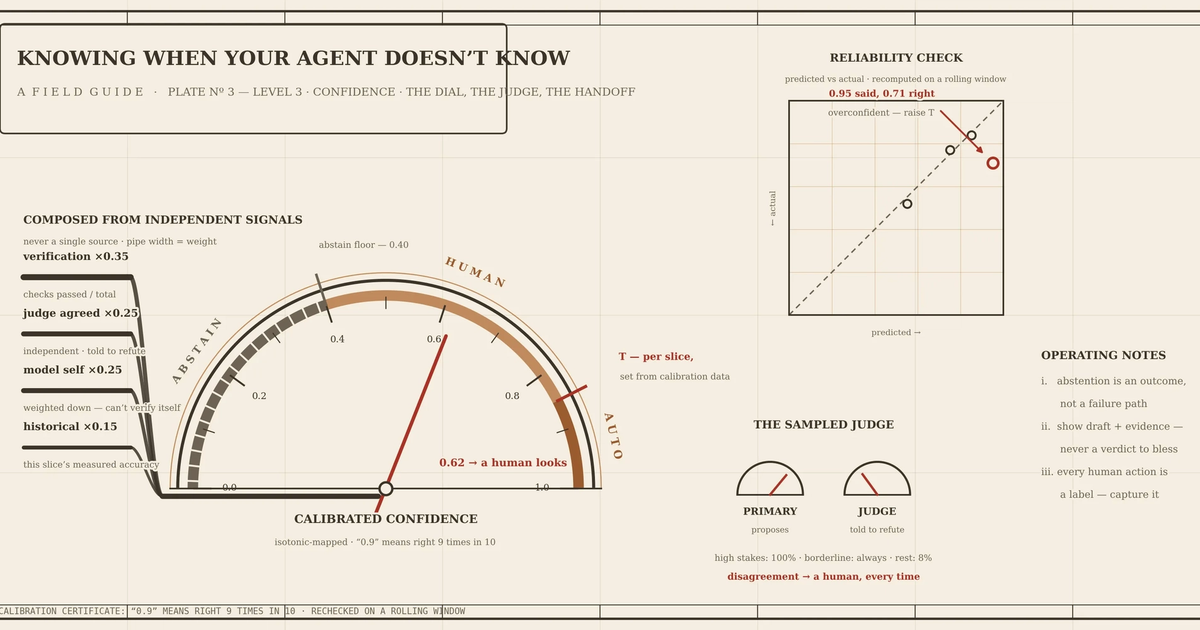
  14. Part 3: Knowing when your agent doesn’t know: the confidence layer

    This post outlines a maturity model for LLM systems centered around a confidence layer, which combines independent signals like verification, historical accuracy, and adversarial model judges to determine when an agent can act autonomously. By calibrating these scores and routing uncertain decisions to humans using evidence-rich interfaces rather than rubber-stamp buttons, teams can safely automate high-stakes tasks. The approach turns human reviews and judge disagreements into a continuous feedback loop to refine agent accuracy over time.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  15. Inside Hyperdrive: How we solved a rare Hyperdrive MySQL caching bug

    During the beta of MySQL support for Hyperdrive, engineers investigated rare empty query responses and connection hangs occurring in 0.001% of requests. They discovered that sharing the data center cache between client and endpoint nodes caused protocol capability mismatches when translating MySQL wire messages. The team resolved the issue by standardizing the cache to always store responses encoded with canonical Hyperdrive capabilities.

    DEPTH ■■■■■9 min read11 days ago

    MySQL

    Sign in to save and rate

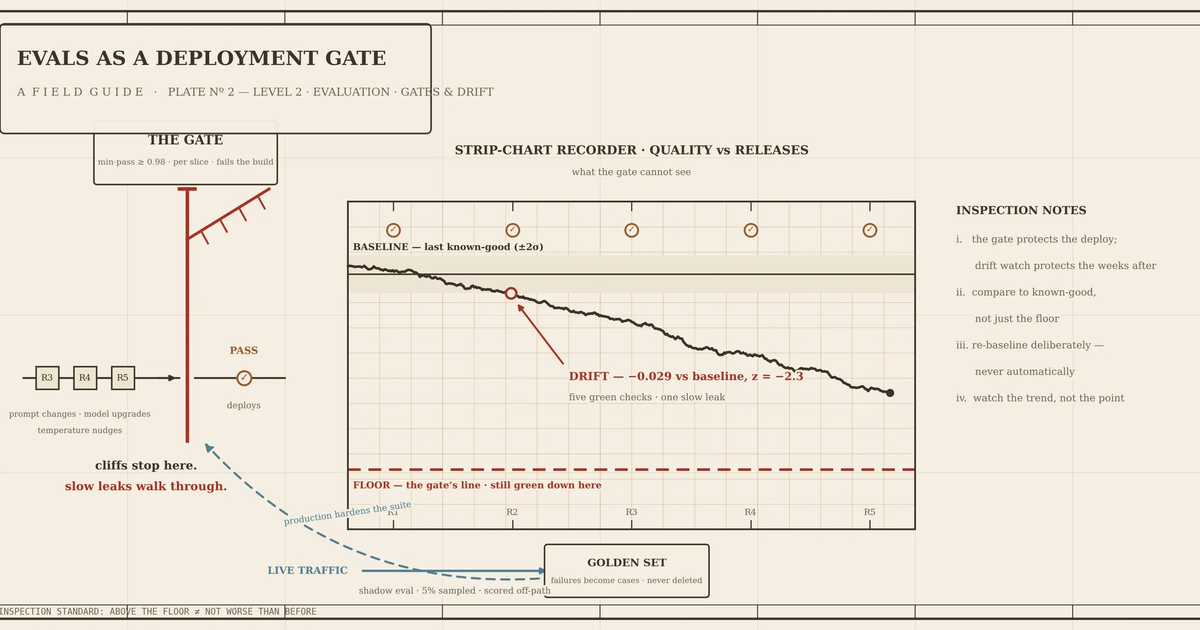
  16. Part 2: Evals as a deployment gate — and how to know when they drift

    This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.

    DEPTH ■■■■■8 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  17. Under the hood, off the hot path: How D1 scales to millions of databases

    Cloudflare scaled its serverless SQLite database, D1, to support millions of databases by decoupling the control plane from the data plane. The team used distributed metadata caching via Workers KV, optimized database connections through Hyperdrive, and implemented a self-correcting heartbeat mechanism. This architecture prevents centralized bottlenecks and allows D1 to handle rapid on-demand database creation efficiently.

    DEPTH ■■■■■22 min read12 days ago

    Databases

    Sign in to save and rate

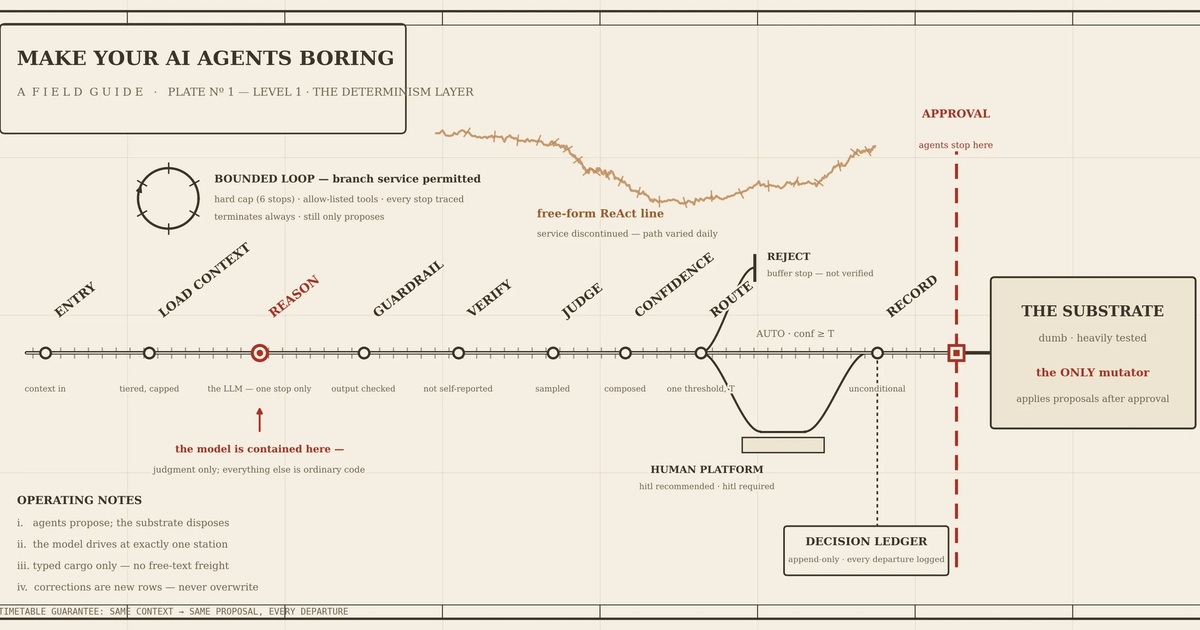
  18. Part 1: Make your AI agents boring: the determinism layer

    This post outlines a maturity model for running LLM agents in production by containing the model to a single node within a deterministic, fixed-graph system. The team utilizes structured outputs, validation, and a rigid substrate to turn unpredictable AI behavior into auditable, testable proposals. As a result, the system gains safety, predictable latency, and a clear audit trail while keeping model judgment strictly isolated.

    DEPTH ■■■■■13 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  19. Building a faster, lazier router for Postgres

    To reduce overhead when routing queries across PostgreSQL shards, the Neki router avoids unnecessary parsing and decodes responses lazily. By keeping data in its original wire format and only decoding columns when strictly required for operations like limits or sorting, the router significantly improves performance.

    DEPTH ■■■■■16 min read3 weeks ago

    Sign in to save and rate

  20. Rewinding the exponential: How we keep hardware usage down

    Cloudflare tackled exponential traffic growth against linear hardware growth by continuously evolving their data pipeline architecture over five years. Key optimizations included breaking up monolithic schemas, switching to zstd compression, decoupling pipeline transit from database replication, decentralizing sampling, and moving aggregations earlier in the pipeline. These strategies significantly reduced backbone bandwidth usage, network congestion, and storage requirements while preserving data quality.

    DEPTH ■■■■■12 min read12 days ago

    Infrastructure

    Sign in to save and rate