/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. App stability at scale with a layered defense

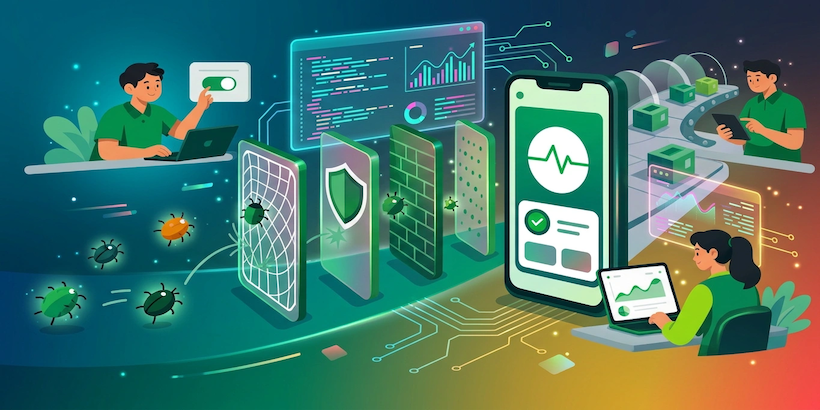
    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read6 days ago
    MobileReliability

    Sign in to save and rate

  2. Beyond container image signing: How we enforce software supply chain policies at Datadog

    Container image signing alone cannot detect upstream security compromises occurring before the image is signed. To address this, the engineering team built an internal system called Turnstile that generates cryptographically signed attestations across an artifact's life cycle and evaluates them against environment-specific policies at deployment time. This approach enables the organization to enforce strict security and compliance requirements at scale without disrupting developer workflows.

    DEPTH ■■■■■15 min read7 days ago

    Sign in to save and rate

  3. The Shift to cgroup v2 in Kubernetes: What You Need to Know

    Kubernetes has deprecated cgroup v1 in favor of cgroup v2, with complete removal scheduled for future releases. The transition requires migrating Linux nodes, updating container runtimes, and verifying kernel compatibility. Adopting cgroup v2 enables advanced features such as Memory QoS, improved OOM handling, and pressure stall information metrics.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

  4. Scaling Kubernetes Workloads with Node Swap

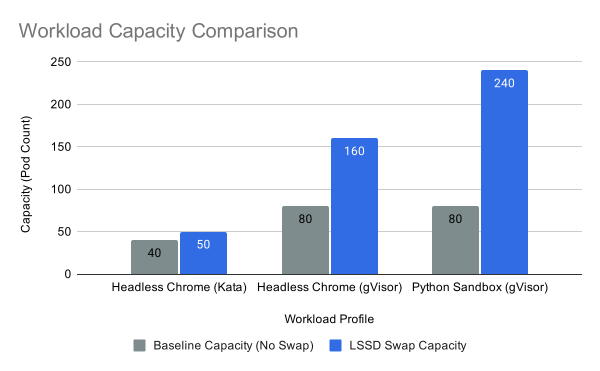
    Kubernetes memory limits often cap node density for bursty agentic AI workloads that sit idle with large memory footprints. To solve this, the engineering team benchmarked Kubernetes v1.34 node swap backed by fast NVMe Local SSDs across CI/CD builds, headless browsers, and Python sandboxes. The approach successfully increased pod density up to three times without significant latency costs.

    DEPTH ■■■■■6 min read3 weeks ago

    Sign in to save and rate

  5. Powering AI-led research through simulation

    The engineering team built a self-contained simulation platform called sim-rs to model marketplace dispatch dynamics and accelerate experimentation. By connecting automated software agents to this simulator with strict safety safeguards, the team successfully optimized strategy policies and simulator performance. This closed-loop lab environment allows agents to test ideas rapidly while ensuring that only valid, production-ready improvements are produced.

    DEPTH ■■■■■10 min read3 weeks ago

    Machine Learning

    Sign in to save and rate

  6. How we extended Apache DataFusion to execute one query across many machines

    Datadog needed to execute interactive queries across large datasets that exceeded single-node limits while maintaining low latency. To solve this, the team built Distributed DataFusion, an open-source framework extending Apache DataFusion across multiple machines using zero-copy streaming via Apache Arrow and Substrait. As a result, heavy queries complete up to 10 times faster without imposing distribution overhead on lightweight queries.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

  7. How we built an async-aware Python profiler

    Traditional Python profilers treat asyncio tasks as independent stacks, obscuring logical execution paths and relationships. The Datadog team built an async-aware profiling model that tracks task dependencies to reconstruct unified execution paths ("stacked stacks") while reducing profiling overhead by over 60 percent. This approach provides clearer performance visibility for asynchronous applications without excessive production latency.

    DEPTH ■■■■■19 min read3 weeks ago

    Sign in to save and rate

  8. It's time to make your own RSS reader

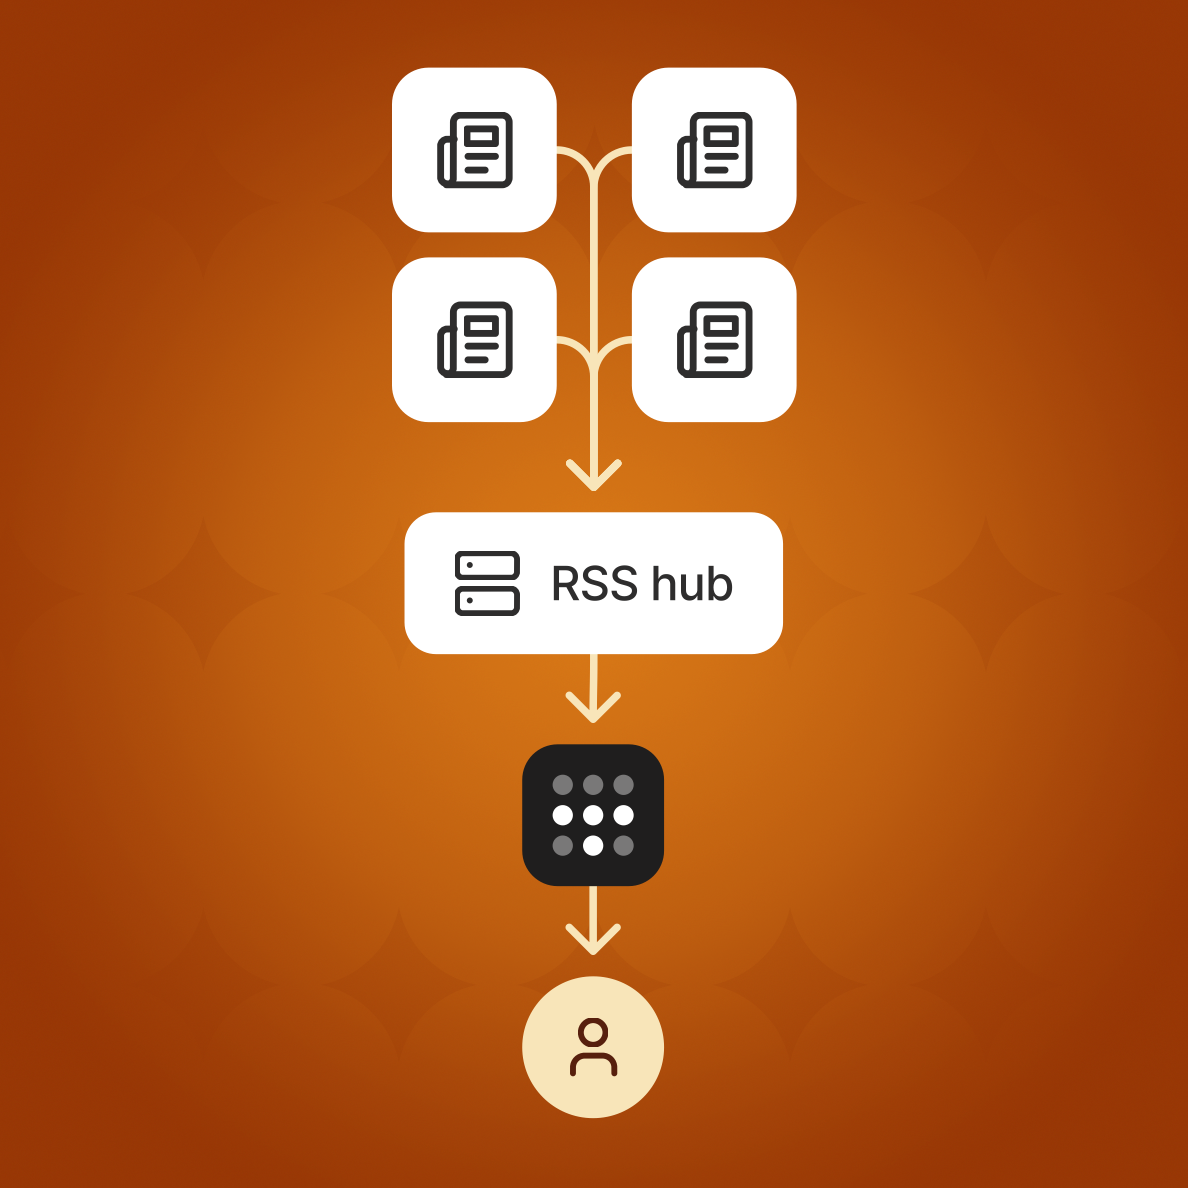
    This post walks through the process of self-hosting a personal RSS reader using FreshRSS and Docker, secured privately over a Tailscale network. The author details the configuration of environment variables, auth keys, and Docker compose deployment to avoid exposing the service to the open web. The result is a private, algorithm-free news reader accessible across multiple devices and integrable with external reading apps or AI agents.

    DEPTH ■■■■■10 min read11 days ago

    Sign in to save and rate

  9. Why Is My Kubernetes Job Still Pending? Tracing Kueue Admission with Headlamp

    Kubernetes jobs managed by Kueue can remain pending while waiting for admission checks and resource allocation. The team implemented a Kueue plugin for Headlamp to trace pending workloads through local queues, cluster queues, and resource flavors within a unified interface. This approach allows engineers to quickly determine whether a job is blocked by admission policies or standard pod scheduling.

    DEPTH ■■■■■9 min read13 days ago

    Sign in to save and rate

  10. Your agent, your network: How Meta’s Muse agent works with Tailscale

    Meta integrated Tailscale into its Muse personal AI agent, allowing the agent to join a user's tailnet as a separate node and interact with self-hosted services and SSH sessions. By treating Muse like any standard tailnet node, users can apply Tailscale's access controls, grants, and tags to enforce security and adhere to the principle of least privilege.

    DEPTH ■■■■■5 min read3 weeks ago

    Sign in to save and rate

  11. Smarter personalization: How property data helps us understand user price sensitivity

    Existing user personalization systems fail to systematically account for residential property values, leading to one-dimensional profiles and regional blind spots. A conceptual four-step method is proposed that combines public property data, large language models, building-level price estimation, and hierarchical clustering to classify user affluence. The approach remains unimplemented, with future viability depending on technical validation, data quality, and privacy approvals.

    DEPTH ■■■■■4 min read3 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate

  12. Making Rust observability reliable at scale with OpenTelemetry

    Datadog engineers faced inconsistent tracing, broken spans, and context loss across Rust services due to fragmented tooling and unopinionated OpenTelemetry configurations. To fix this, they contributed upstream to OpenTelemetry to improve interoperability and built an opinionated Rust tracing library called dd-trace-rs. This reduced backend ingestion volume by 20x while increasing the rate of indexed spans per service by 3x.

    DEPTH ■■■■■10 min read8 weeks ago

    Sign in to save and rate

  13. Automated merchant review summary system with integrated feedback

    To help users navigate large volumes of unstructured merchant reviews, the engineering team built an automated review summary system using representative sampling, large language models, and automated quality control checks. The pipeline generates overall and topic-based summaries while incorporating maintenance triggers based on new review counts and consumer feedback. This approach reduces the text consumers need to scan while ensuring claims remain grounded in source data.

    DEPTH ■■■■■5 min read4 weeks ago

    Machine Learning

    Sign in to save and rate

  14. GrabMart data for faster disease outbreak detection

    The organization proposes a conceptual data pipeline to analyze aggregated GrabMart transaction data for symptom-related product demand, aiming to supplement clinical surveillance for disease outbreaks. The design relies on data aggregation, statistical baseline comparisons, and privacy safeguards like differential privacy without involving individual health inference. The system remains in an early planning phase requiring rigorous validation, privacy review, and public health oversight.

    DEPTH ■■■■■5 min read2 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate