/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

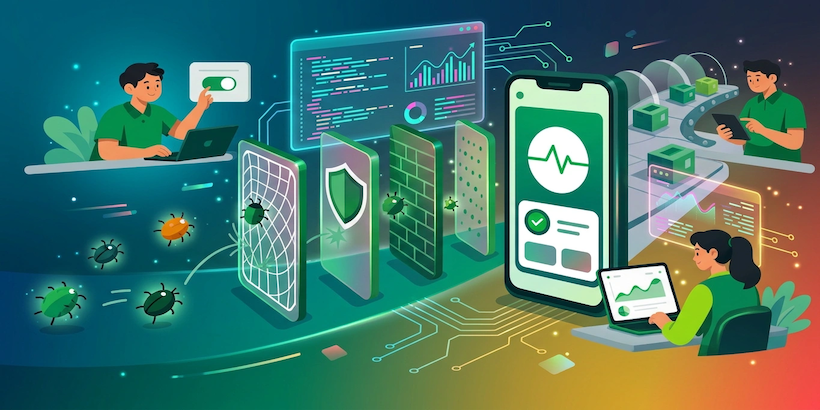
  1. App stability at scale with a layered defense

    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read4 days ago
    MobileReliability

    Sign in to save and rate

  2. Beyond container image signing: How we enforce software supply chain policies at Datadog

    Container image signing alone cannot detect upstream security compromises occurring before the image is signed. To address this, the engineering team built an internal system called Turnstile that generates cryptographically signed attestations across an artifact's life cycle and evaluates them against environment-specific policies at deployment time. This approach enables the organization to enforce strict security and compliance requirements at scale without disrupting developer workflows.

    DEPTH ■■■■■15 min read5 days ago

    Sign in to save and rate

  3. MCP standardized tools. Now we need the infrastructure around them.

    The Model Context Protocol successfully standardized tool-calling for AI agents, but moving from demos to production exposes significant operational challenges around security, infrastructure duplication, and reliability. Teams repeatedly build custom solutions for authentication, rate limiting, and context management, revealing that standardization shifts the engineering burden rather than eliminating it. Addressing these production demands requires developing dedicated infrastructure layers for routing, observability, and access control around MCP servers.

    DEPTH ■■■■■8 min read10 days ago

    Machine Learning

    Sign in to save and rate

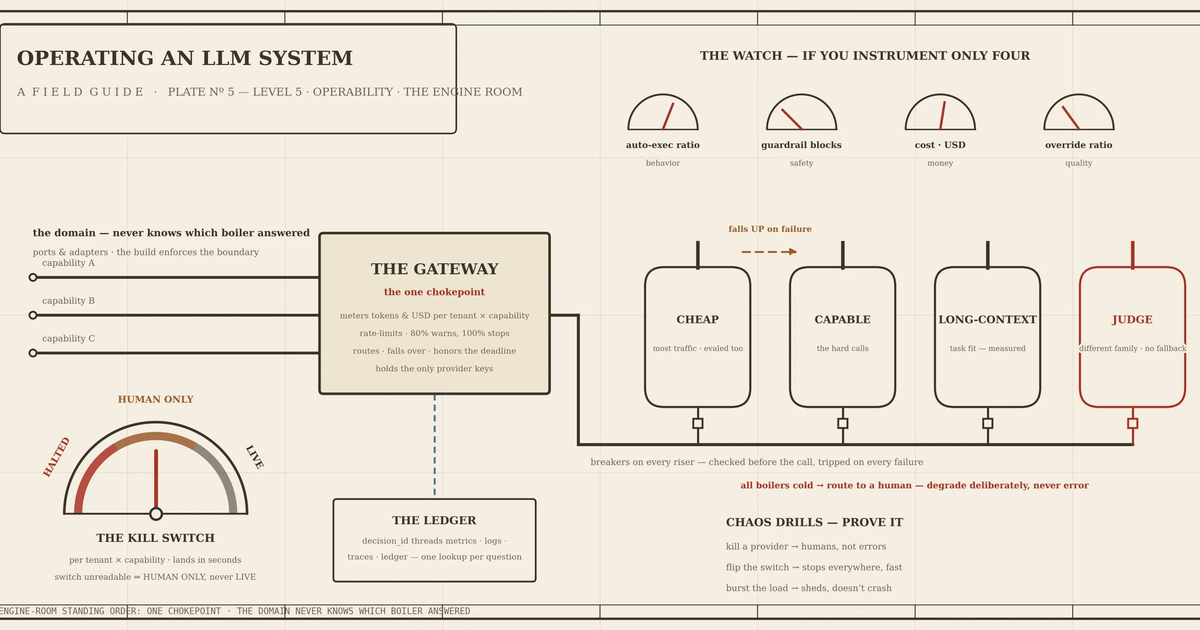
  4. Part 5: Operating an LLM system: observability, cost, routing, and the platform underneath

    This post provides a concrete specification for the operability layer of production LLM systems, covering observability signals, structured logging, cost controls, routing, and failover mechanisms. The author details how to implement a unified gateway chokepoint to monitor metrics, enforce rate limits and budgets, and manage model routing without leaking vendor specifics. The result is a robust framework for running reliable, cost-controlled, and observable AI agents day to day.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  5. Powering AI-led research through simulation

    The engineering team built a self-contained simulation platform called sim-rs to model marketplace dispatch dynamics and accelerate experimentation. By connecting automated software agents to this simulator with strict safety safeguards, the team successfully optimized strategy policies and simulator performance. This closed-loop lab environment allows agents to test ideas rapidly while ensuring that only valid, production-ready improvements are produced.

    DEPTH ■■■■■10 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

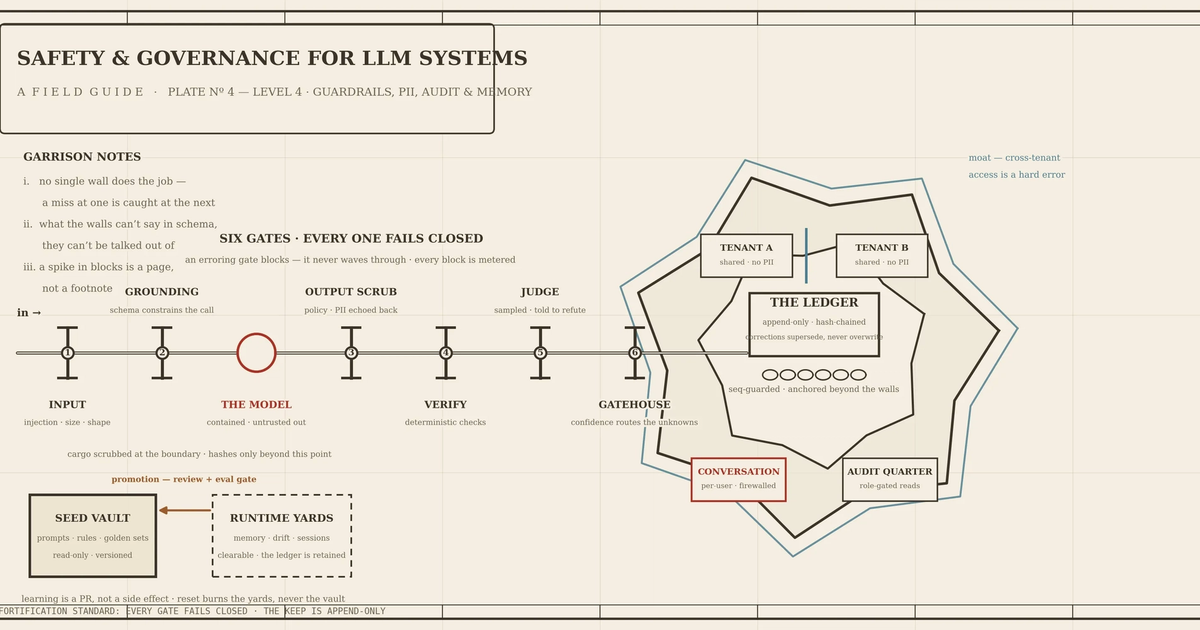
  6. Part 4: Safety and governance for LLM systems: guardrails, PII, audit, and memory

    This post details safety and governance practices for LLM systems, focusing on layered guardrails, boundary-level PII handling, and immutable audit trails. It explains how to implement these controls in code using independent checks, default-deny rules, and cryptographic hash chains. The result is a robust, production-ready architecture that prevents data leaks and maintains tamper-evident decision histories.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  7. How we extended Apache DataFusion to execute one query across many machines

    Datadog needed to execute interactive queries across large datasets that exceeded single-node limits while maintaining low latency. To solve this, the team built Distributed DataFusion, an open-source framework extending Apache DataFusion across multiple machines using zero-copy streaming via Apache Arrow and Substrait. As a result, heavy queries complete up to 10 times faster without imposing distribution overhead on lightweight queries.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

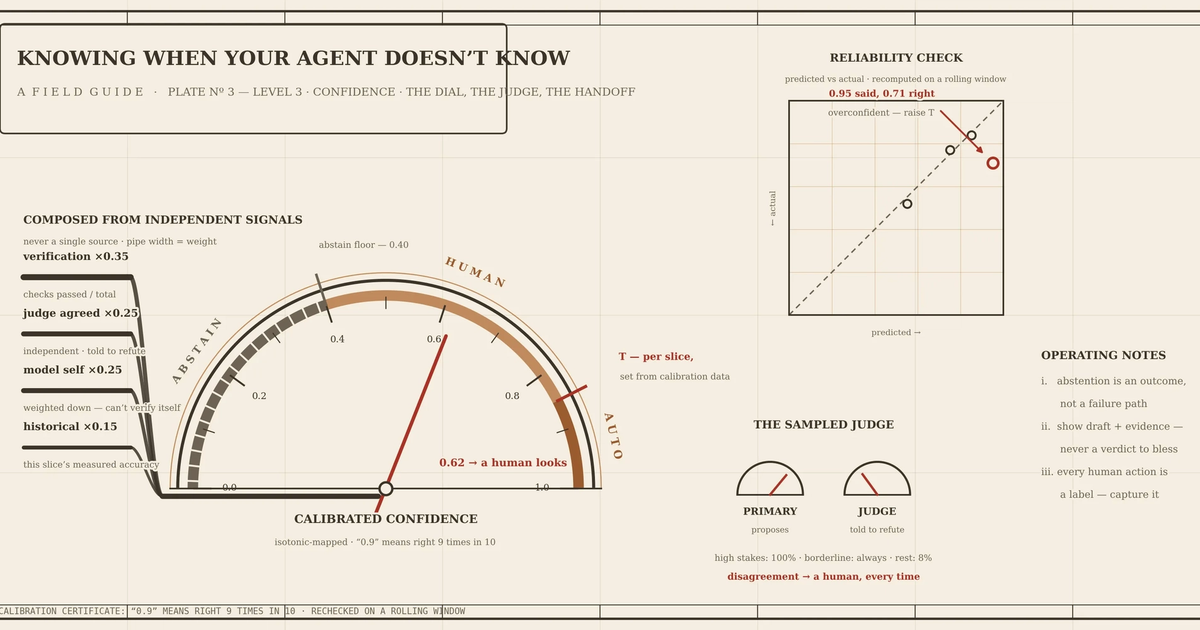
  8. Part 3: Knowing when your agent doesn’t know: the confidence layer

    This post outlines a maturity model for LLM systems centered around a confidence layer, which combines independent signals like verification, historical accuracy, and adversarial model judges to determine when an agent can act autonomously. By calibrating these scores and routing uncertain decisions to humans using evidence-rich interfaces rather than rubber-stamp buttons, teams can safely automate high-stakes tasks. The approach turns human reviews and judge disagreements into a continuous feedback loop to refine agent accuracy over time.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  9. How we built an async-aware Python profiler

    Traditional Python profilers treat asyncio tasks as independent stacks, obscuring logical execution paths and relationships. The Datadog team built an async-aware profiling model that tracks task dependencies to reconstruct unified execution paths ("stacked stacks") while reducing profiling overhead by over 60 percent. This approach provides clearer performance visibility for asynchronous applications without excessive production latency.

    DEPTH ■■■■■19 min read3 weeks ago

    Sign in to save and rate

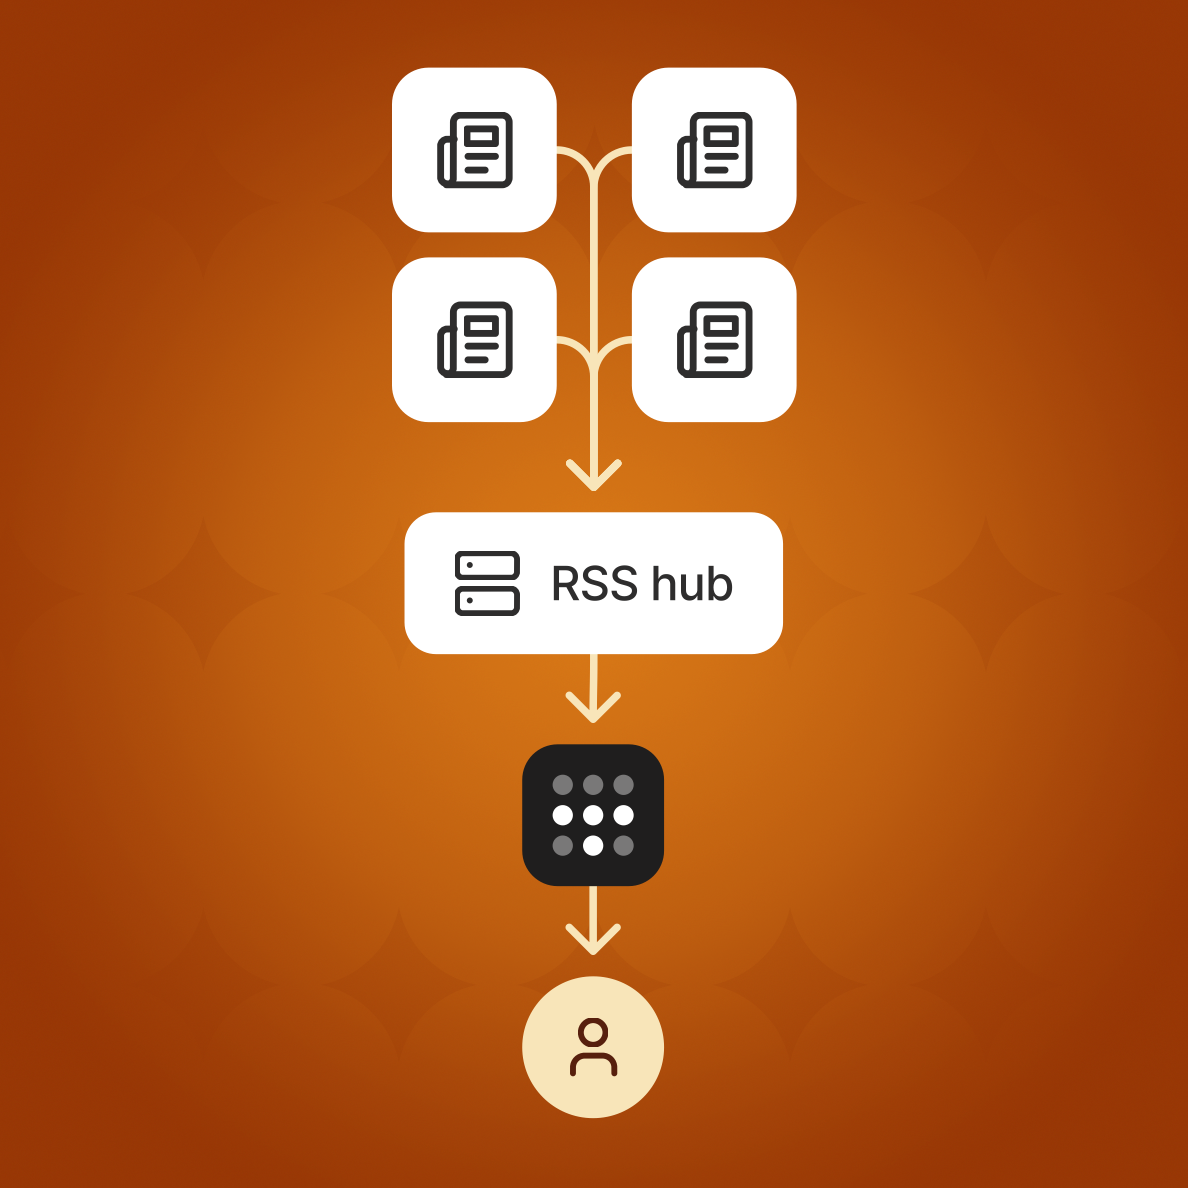
  10. It's time to make your own RSS reader

    This post walks through the process of self-hosting a personal RSS reader using FreshRSS and Docker, secured privately over a Tailscale network. The author details the configuration of environment variables, auth keys, and Docker compose deployment to avoid exposing the service to the open web. The result is a private, algorithm-free news reader accessible across multiple devices and integrable with external reading apps or AI agents.

    DEPTH ■■■■■10 min read9 days ago

    Sign in to save and rate

  11. Part 2: Evals as a deployment gate — and how to know when they drift

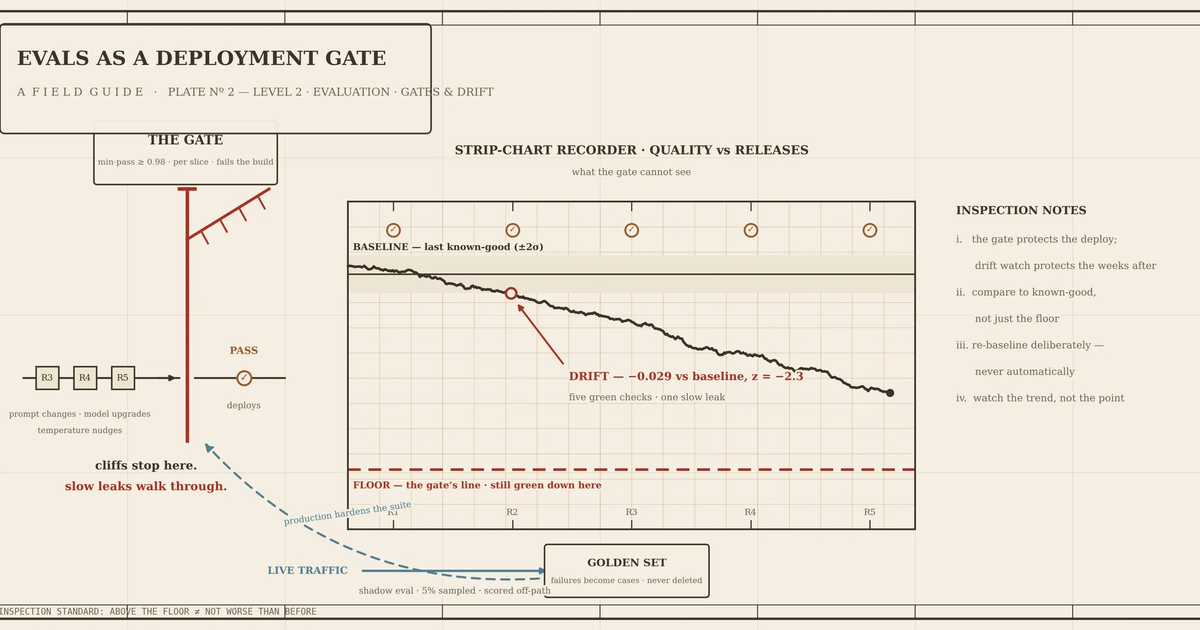
    This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.

    DEPTH ■■■■■8 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  12. Part 1: Make your AI agents boring: the determinism layer

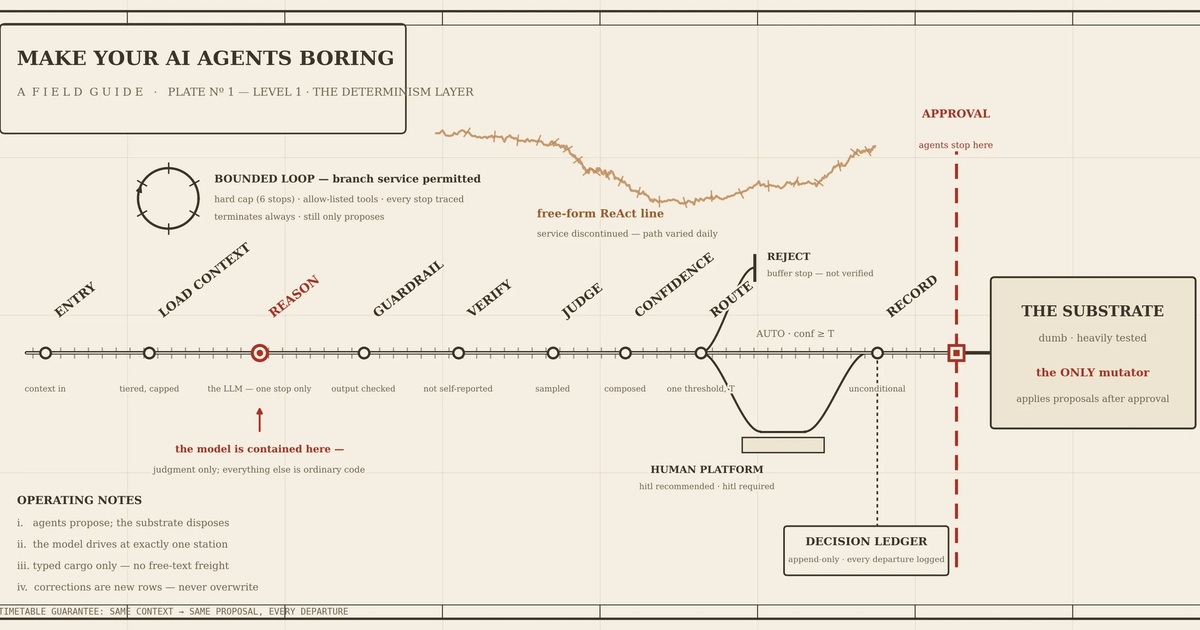
    This post outlines a maturity model for running LLM agents in production by containing the model to a single node within a deterministic, fixed-graph system. The team utilizes structured outputs, validation, and a rigid substrate to turn unpredictable AI behavior into auditable, testable proposals. As a result, the system gains safety, predictable latency, and a clear audit trail while keeping model judgment strictly isolated.

    DEPTH ■■■■■13 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  13. Part 6: An operating system for coding agents: the disciplined build

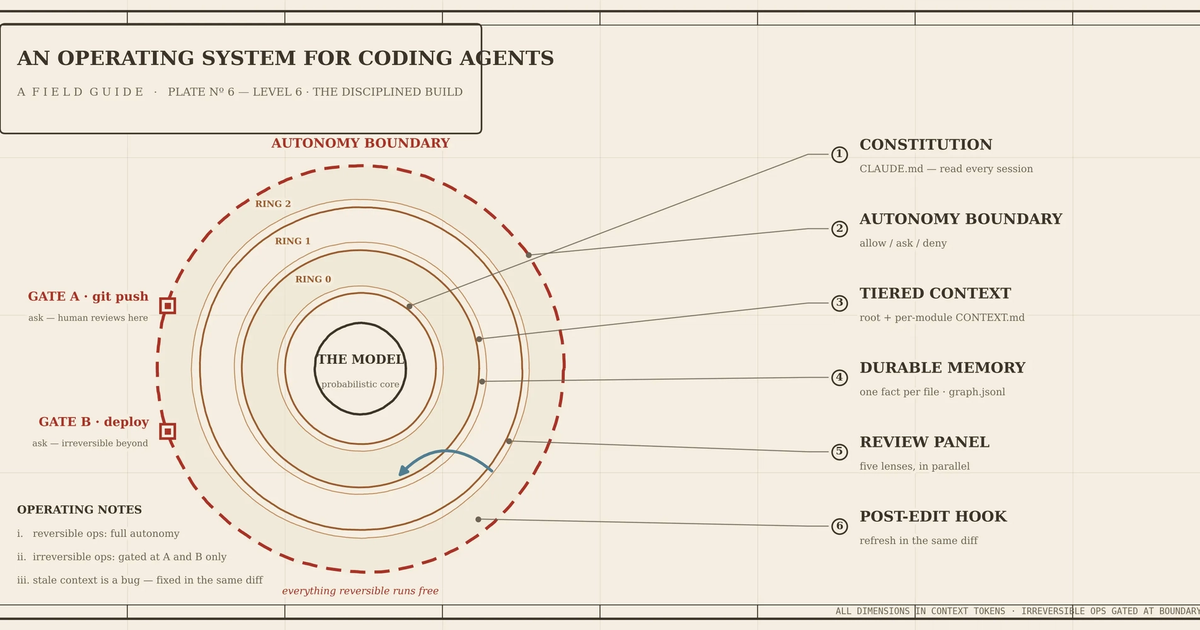
    Engineering coding agents often degrade over long projects due to harness and configuration failures rather than model limitations. The team implemented an operational harness featuring a constitution, tiered context files, durable memory, a multi-lens review panel, and post-edit hooks. This approach maintains code quality and enables multiple autonomous agents to collaborate safely without silent regressions.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  14. Your agent, your network: How Meta’s Muse agent works with Tailscale

    Meta integrated Tailscale into its Muse personal AI agent, allowing the agent to join a user's tailnet as a separate node and interact with self-hosted services and SSH sessions. By treating Muse like any standard tailnet node, users can apply Tailscale's access controls, grants, and tags to enforce security and adhere to the principle of least privilege.

    DEPTH ■■■■■5 min read3 weeks ago

    Sign in to save and rate

  15. Smarter personalization: How property data helps us understand user price sensitivity

    Existing user personalization systems fail to systematically account for residential property values, leading to one-dimensional profiles and regional blind spots. A conceptual four-step method is proposed that combines public property data, large language models, building-level price estimation, and hierarchical clustering to classify user affluence. The approach remains unimplemented, with future viability depending on technical validation, data quality, and privacy approvals.

    DEPTH ■■■■■4 min read2 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate

  16. Why model versioning is not enough for production AI

    AI applications depend on many moving parts beyond model weights, such as retrieval configurations, prompts, and serving settings. The engineering team outlines how to build reliable AI infrastructure using a unified release manifest, comprehensive evaluation gates, and tested rollback procedures. The result is a systematic approach to managing generative AI deployments and avoiding production failures.

    DEPTH ■■■■■8 min read3 weeks ago

    Machine Learning

    Sign in to save and rate

  17. Making Rust observability reliable at scale with OpenTelemetry

    Datadog engineers faced inconsistent tracing, broken spans, and context loss across Rust services due to fragmented tooling and unopinionated OpenTelemetry configurations. To fix this, they contributed upstream to OpenTelemetry to improve interoperability and built an opinionated Rust tracing library called dd-trace-rs. This reduced backend ingestion volume by 20x while increasing the rate of indexed spans per service by 3x.

    DEPTH ■■■■■10 min read7 weeks ago

    Sign in to save and rate

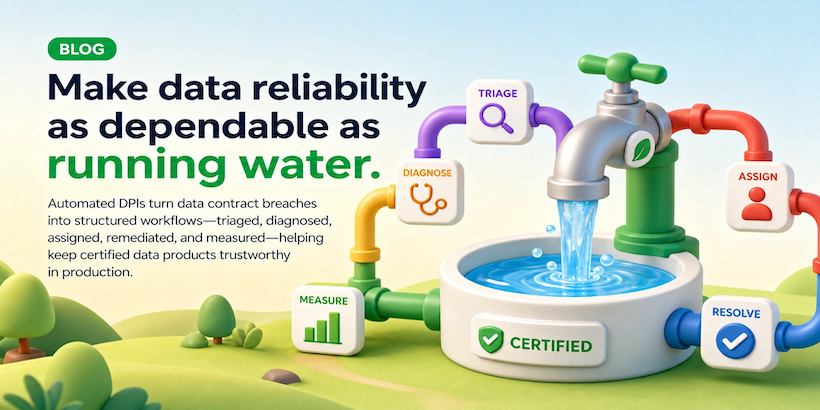
  18. Data Mesh at Grab (Part III): Operationalizing data reliability with automated DPIs

    Grab addressed runtime data reliability issues in its data mesh by implementing automated Data Production Issues (DPIs). The system uses an incident orchestrator to detect contract breaches, a Data Health API for cross-platform root cause analysis, and Hugo for automated remediation. This approach resolved 86.9 percent of incidents automatically and made mean time to resolve six times faster.

    DEPTH ■■■■■12 min read8 weeks ago

    DatabasesObservability

    Sign in to save and rate

  19. Is Your “Human-in-the-Loop” Actually Slowing You Down? Here’s What We Learned

    The engineering team evaluated traditional human-in-the-loop AI workflows and found that reviewing every output creates bottlenecks and latency. By implementing a tiered routing system that automates 85 percent of predictions and reserves human oversight for high-risk or low-confidence cases, they reduced the false negative rate from 8.3 percent to 2.1 percent. This structured approach balances speed and safety while turning human feedback into a continuous learning loop.

    DEPTH ■■■■■11 min read3 weeks ago

    Machine Learning

    Sign in to save and rate

  20. Automated merchant review summary system with integrated feedback

    To help users navigate large volumes of unstructured merchant reviews, the engineering team built an automated review summary system using representative sampling, large language models, and automated quality control checks. The pipeline generates overall and topic-based summaries while incorporating maintenance triggers based on new review counts and consumer feedback. This approach reduces the text consumers need to scan while ensuring claims remain grounded in source data.

    DEPTH ■■■■■5 min read4 weeks ago

    Machine Learning

    Sign in to save and rate