/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Improving site performance by shipping more CSS

    GitHub faced performance degradation on server-side rendering and initial page loads due to scaling issues with its CSS-in-JS solution. The engineering team executed a multi-year migration to CSS Modules and eliminated dynamic styling props using incremental rollouts, wrapper components, and automation tools. This resulted in significant performance gains, including 55% faster server-side rendering and the complete removal of styled-components.

    DEPTH ■■■■■8 min read4 weeks ago

    FrontendPerformance

    Sign in to save and rate

  2. Smarter personalization: How property data helps us understand user price sensitivity

    Existing user personalization systems fail to systematically account for residential property values, leading to one-dimensional profiles and regional blind spots. A conceptual four-step method is proposed that combines public property data, large language models, building-level price estimation, and hierarchical clustering to classify user affluence. The approach remains unimplemented, with future viability depending on technical validation, data quality, and privacy approvals.

    DEPTH ■■■■■4 min read2 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate

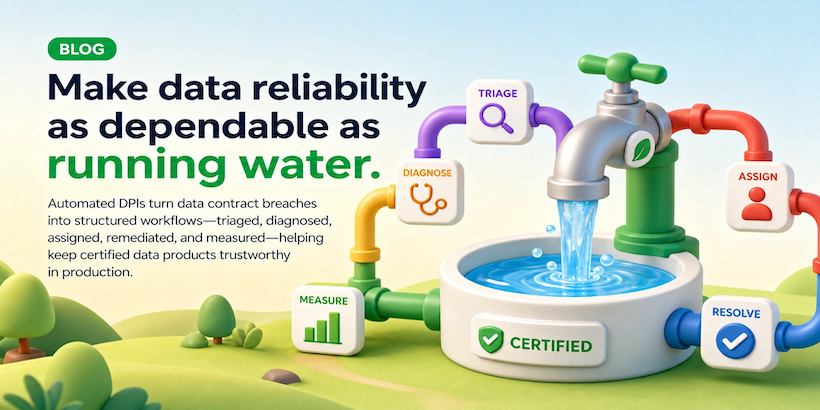
  3. Data Mesh at Grab (Part III): Operationalizing data reliability with automated DPIs

    Grab addressed runtime data reliability issues in its data mesh by implementing automated Data Production Issues (DPIs). The system uses an incident orchestrator to detect contract breaches, a Data Health API for cross-platform root cause analysis, and Hugo for automated remediation. This approach resolved 86.9 percent of incidents automatically and made mean time to resolve six times faster.

    DEPTH ■■■■■12 min read8 weeks ago

    DatabasesObservability

    Sign in to save and rate

  4. GrabMart data for faster disease outbreak detection

    The organization proposes a conceptual data pipeline to analyze aggregated GrabMart transaction data for symptom-related product demand, aiming to supplement clinical surveillance for disease outbreaks. The design relies on data aggregation, statistical baseline comparisons, and privacy safeguards like differential privacy without involving individual health inference. The system remains in an early planning phase requiring rigorous validation, privacy review, and public health oversight.

    DEPTH ■■■■■5 min read12 days ago

    Data EngineeringMachine Learning

    Sign in to save and rate