/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

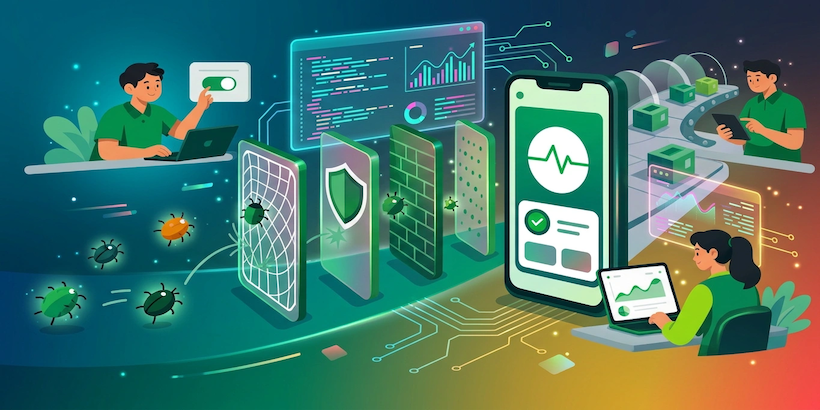
  1. App stability at scale with a layered defense

    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read4 days ago
    MobileReliability

    Sign in to save and rate

  2. Sentry JavaScript SDK v11 adds tracing for all JS platforms

    Sentry replaced its OpenTelemetry-based JavaScript SDK instrumentation with a source-code transformation approach using diagnostics channels in version 11. This change removes reliance on Node-specific module loader hooks, enabling reliable tracing across non-Node runtimes like Deno, Bun, and Cloudflare Workers, while also supporting bundled applications. The result is a simplified architecture that reduces bundle weight and fixes previous limitations with load order and immutable exports.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate

  3. Reducing Android scope-sync overhead in Sentry Flutter

    The Sentry Flutter team investigated scope-sync overhead on Android and found redundant data normalization across isolates alongside unnecessary buffer copies during JSON encoding. By removing the duplicate normalization and encoding directly to UTF-8 bytes, the team reduced processing time by 27 to 30 percent across benchmarked payloads.

    DEPTH ■■■■■4 min read2 weeks ago

    Sign in to save and rate

  4. Powering AI-led research through simulation

    The engineering team built a self-contained simulation platform called sim-rs to model marketplace dispatch dynamics and accelerate experimentation. By connecting automated software agents to this simulator with strict safety safeguards, the team successfully optimized strategy policies and simulator performance. This closed-loop lab environment allows agents to test ideas rapidly while ensuring that only valid, production-ready improvements are produced.

    DEPTH ■■■■■10 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  5. The Sentry Android SDK is now 20-30% faster!

    The Sentry team optimized the Android SDK to reduce initialization time by 20-30% and background CPU usage by up to 10%. Improvements were achieved by profiling with Perfetto, replacing slow runtime manifest parsing and DSN parsing with build-time bytecode writing and lightweight parsers, and reusing thread pools. Upgrading to the latest SDK version allows applications to realize these startup performance gains.

    DEPTH ■■■■■4 min read5 days ago

    Sign in to save and rate

  6. Unreal MCP now speaks Sentry

    The Sentry team integrated their crash reporting plugin with Unreal Engine's new experimental Model Context Protocol (MCP) server, allowing coding agents to fully automate setup and debugging. By combining editor tools and Sentry MCP, an agent successfully configured the SDK, uploaded debug symbols, packaged a build, induced a crash, and traced the root cause without manual file editing. The integration streamlines crash reporting setup, though it currently suffers from occasional agent tool-discovery issues and server fragility across editor restarts.

    DEPTH ■■■■■7 min read2 weeks ago

    Sign in to save and rate

  7. Should you use a log or a metric?

    This post explains the distinction between logs and metrics in application monitoring, noting that logs capture what was true during specific events for debugging while metrics track ongoing numerical trends over time. The author demonstrates how to implement both using Sentry SDKs during a user signup flow and outlines criteria for choosing between them. The resulting takeaway helps engineers decide whether to log an event or track it as a metric based on the questions they need to answer.

    DEPTH ■■■■■12 min read3 days ago

    Sign in to save and rate

  8. Smarter personalization: How property data helps us understand user price sensitivity

    Existing user personalization systems fail to systematically account for residential property values, leading to one-dimensional profiles and regional blind spots. A conceptual four-step method is proposed that combines public property data, large language models, building-level price estimation, and hierarchical clustering to classify user affluence. The approach remains unimplemented, with future viability depending on technical validation, data quality, and privacy approvals.

    DEPTH ■■■■■4 min read2 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate

  9. How Etsy gets its mobile apps ready for peak traffic

    Etsy prepares its mobile apps for peak holiday traffic through advance planning, operational guardrails, and risk management rather than relying on capacity scaling or the ability to quickly revert binaries. The engineering team utilizes a phased code slush, dual crash reporting, remote feature flags, and custom error tagging to surface and mitigate issues effectively under heavy loads. By connecting crash rates to business metrics and automating manual triage workflows incrementally, the organization maintains high visibility and reliability when updates cannot be instantly rolled back.

    DEPTH ■■■■■11 min read3 weeks ago

    Sign in to save and rate

  10. Data Mesh at Grab (Part III): Operationalizing data reliability with automated DPIs

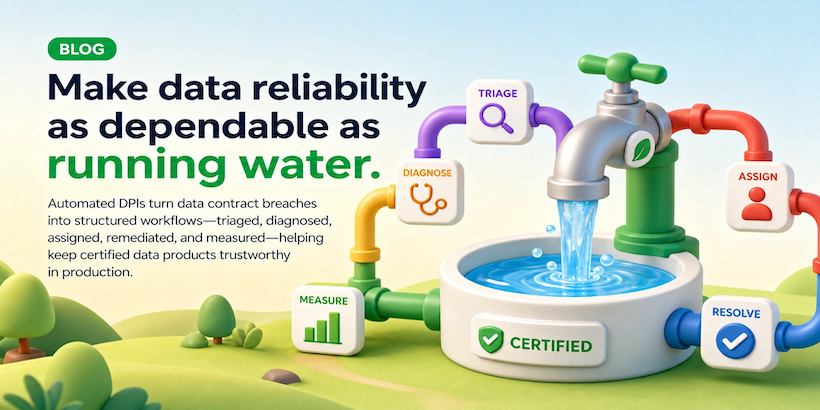
    Grab addressed runtime data reliability issues in its data mesh by implementing automated Data Production Issues (DPIs). The system uses an incident orchestrator to detect contract breaches, a Data Health API for cross-platform root cause analysis, and Hugo for automated remediation. This approach resolved 86.9 percent of incidents automatically and made mean time to resolve six times faster.

    DEPTH ■■■■■12 min read8 weeks ago

    DatabasesObservability

    Sign in to save and rate

  11. Automated merchant review summary system with integrated feedback

    To help users navigate large volumes of unstructured merchant reviews, the engineering team built an automated review summary system using representative sampling, large language models, and automated quality control checks. The pipeline generates overall and topic-based summaries while incorporating maintenance triggers based on new review counts and consumer feedback. This approach reduces the text consumers need to scan while ensuring claims remain grounded in source data.

    DEPTH ■■■■■5 min read4 weeks ago

    Machine Learning

    Sign in to save and rate

  12. Application Metrics caught my broken size estimator

    An engineer integrated application metrics into a client-side video conversion tool to monitor file size estimation accuracy without using invasive telemetry. By tracking key performance indicators and analyzing the metric distributions, they discovered that an AI-generated estimation formula was flawed and producing results off by up to 83 percent. Replacing the broken logic with a correct bitrate-based formula brought the size estimation accuracy to within five percent of real-world results.

    DEPTH ■■■■■15 min read7 weeks ago

    Sign in to save and rate

  13. Seer, the Sentry MCP and CLI, or your own coding agent: where each one fits

    Engineers often struggle to choose between native debugging agents, Model Context Protocols, and command-line tools when integrating error tracking into their workflows. Sentry demonstrates how its debugging assistant Seer, the Sentry MCP, the Sentry CLI, and various coding agent integrations complement each other rather than compete. The resulting setup allows teams to diagnose complex application errors and automatically generate pull requests through whichever surface they prefer.

    DEPTH ■■■■■11 min read3 weeks ago

    Sign in to save and rate

  14. Measuring the back/forward cache with Application Metrics

    Engineering teams often lack visibility into back/forward cache performance because successful cache hits leave no telemetry traces and browser heuristics frequently change. To solve this blind spot, the team introduced an opt-in application metrics integration in their JavaScript SDK that models browser bfcache signals into hits, specific miss reasons, and reload durations. As a result, developers can track, query, and fix silent navigation regressions using customizable dashboards.

    DEPTH ■■■■■6 min read4 weeks ago

    Sign in to save and rate

  15. Building Sentry's Laravel AI Integration

    The Sentry team built a Laravel AI integration to support Agent Tracing during an internal hackweek. Because Laravel AI lacked events for individual LLM invocations, the integration correlates outgoing HTTP requests with active invocations using provider URL prefixes. The resulting zero-config feature is available in sentry-laravel 4.27 and automatically traces agents, LLM requests, and tool calls.

    DEPTH ■■■■■4 min read4 weeks ago

    Sign in to save and rate

  16. Debugging our AI search assistant with agent tracing

    The Sentry team developed a Search Query Assistant to convert natural language prompts into search syntax, which initially failed on custom numerical attributes due to incorrect field formatting in the system prompt. By utilizing their own AI Conversation view and agent tracing, they identified the root cause in the tool call results and system prompt generation. This observability workflow enabled them to reproduce, fix, and verify the issue both locally and in production.

    DEPTH ■■■■■4 min read6 weeks ago

    Sign in to save and rate