/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Shard design doesn't start from your tables

    Designing a sharded Postgres architecture requires grouping tables around shared query keys rather than starting from table structures alone. The post details how to configure shard groups, reference tables, SQL expressions in shard indexes, and global secondary indexes using Neki. This setup enables efficient single-shard queries and transactions while maintaining full Postgres semantics.

    DEPTH ■■■■■8 min read2 days ago
    PostgreSQL

    Sign in to save and rate

  2. MCP standardized tools. Now we need the infrastructure around them.

    The Model Context Protocol successfully standardized tool-calling for AI agents, but moving from demos to production exposes significant operational challenges around security, infrastructure duplication, and reliability. Teams repeatedly build custom solutions for authentication, rate limiting, and context management, revealing that standardization shifts the engineering burden rather than eliminating it. Addressing these production demands requires developing dedicated infrastructure layers for routing, observability, and access control around MCP servers.

    DEPTH ■■■■■8 min read10 days ago

    Machine Learning

    Sign in to save and rate

  3. I don't trust ON DELETE CASCADE

    Postgres ON DELETE CASCADE can cause production outages, replication failures, and performance degradation during large deletions or schema migrations due to long-running transactions holding locks and generating massive WAL. The author recommends using soft deletes with batched background cleanup instead to keep transactions short and bounded. This approach avoids table locks and simplifies data recovery.

    DEPTH ■■■■■5 min read4 days ago

    PostgreSQL

    Sign in to save and rate

  4. Powering AI-led research through simulation

    The engineering team built a self-contained simulation platform called sim-rs to model marketplace dispatch dynamics and accelerate experimentation. By connecting automated software agents to this simulator with strict safety safeguards, the team successfully optimized strategy policies and simulator performance. This closed-loop lab environment allows agents to test ideas rapidly while ensuring that only valid, production-ready improvements are produced.

    DEPTH ■■■■■10 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

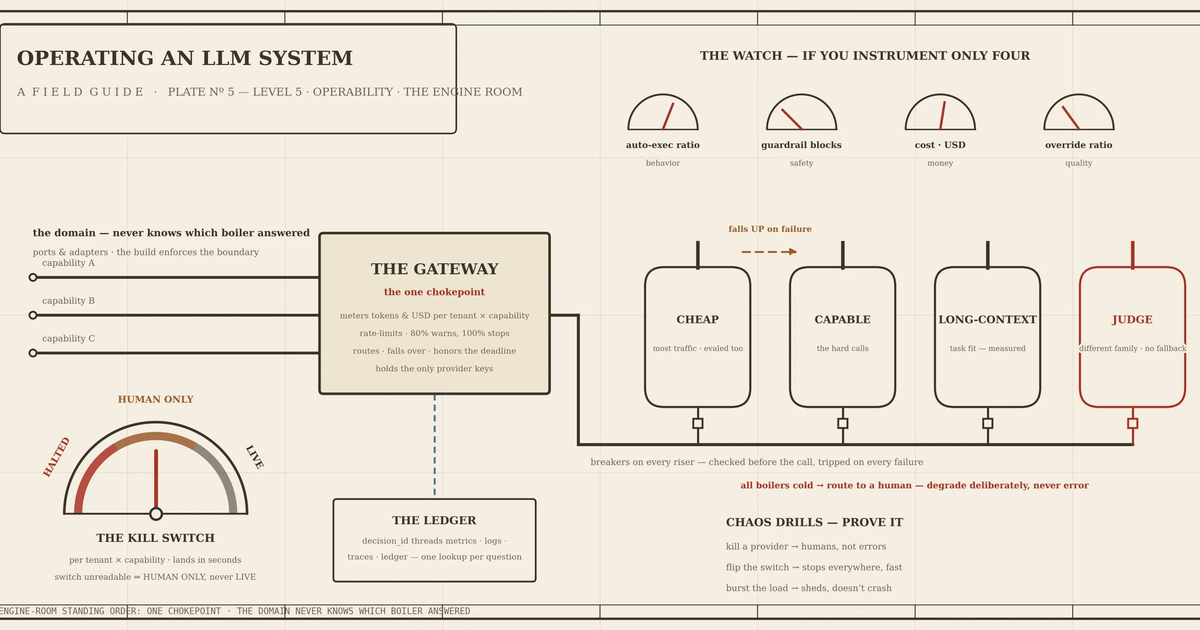
  5. Part 5: Operating an LLM system: observability, cost, routing, and the platform underneath

    This post provides a concrete specification for the operability layer of production LLM systems, covering observability signals, structured logging, cost controls, routing, and failover mechanisms. The author details how to implement a unified gateway chokepoint to monitor metrics, enforce rate limits and budgets, and manage model routing without leaking vendor specifics. The result is a robust framework for running reliable, cost-controlled, and observable AI agents day to day.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  6. What gets TOASTed in Postgres

    This post examines how PostgreSQL uses TOAST to manage oversized rows and variable-length columns through compression and off-row storage. It compares the pglz and LZ4 compression algorithms across different workloads, highlighting trade-offs in search windows, file sizes, and CPU overhead. The analysis demonstrates how these mechanisms impact storage efficiency and read performance for large text and JSON data.

    DEPTH ■■■■■12 min read13 days ago

    PostgreSQL

    Sign in to save and rate

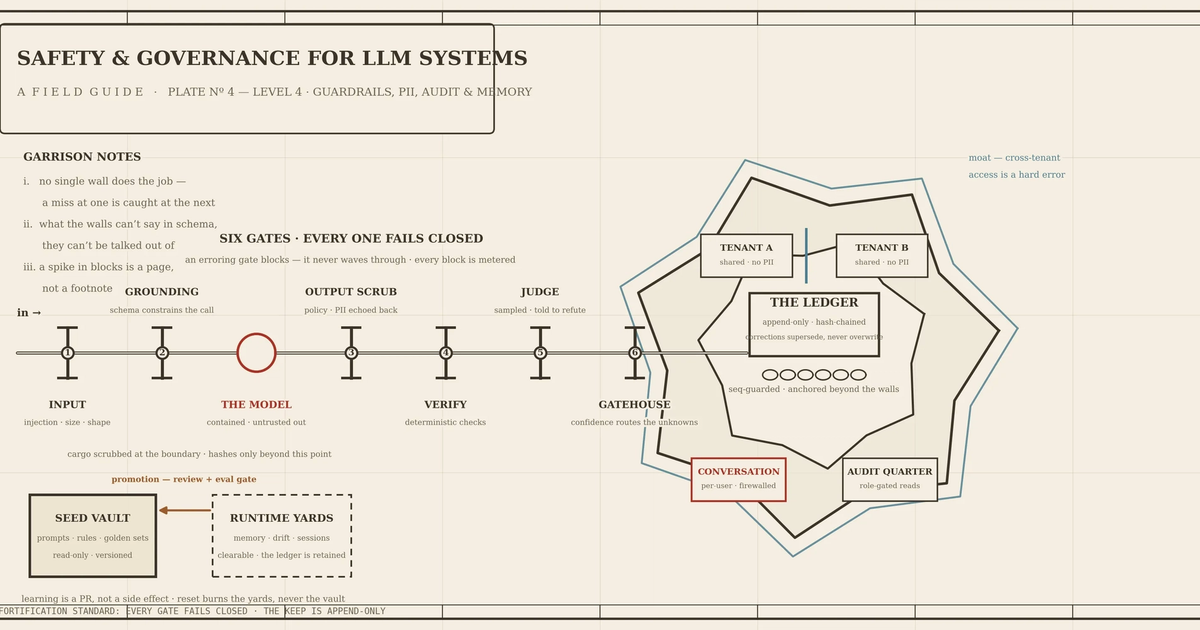
  7. Part 4: Safety and governance for LLM systems: guardrails, PII, audit, and memory

    This post details safety and governance practices for LLM systems, focusing on layered guardrails, boundary-level PII handling, and immutable audit trails. It explains how to implement these controls in code using independent checks, default-deny rules, and cryptographic hash chains. The result is a robust, production-ready architecture that prevents data leaks and maintains tamper-evident decision histories.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  8. TIN v1.0.6: 2-3x faster, with support for stemming

    Following competitive benchmarks that highlighted opportunities for optimization, the developers of the TIN full-text search index for Postgres released versions 1.0.4 and 1.0.6. These updates added Snowball stemming for 18 languages, optimized top-k sorting queries with deterministic tiebreakers, and improved overall query performance. As a result, benchmark tests show that TIN outperforms competing extensions across conjunction, disjunction, and phrase query workloads.

    DEPTH ■■■■■8 min read2 weeks ago

    PostgreSQL

    Sign in to save and rate

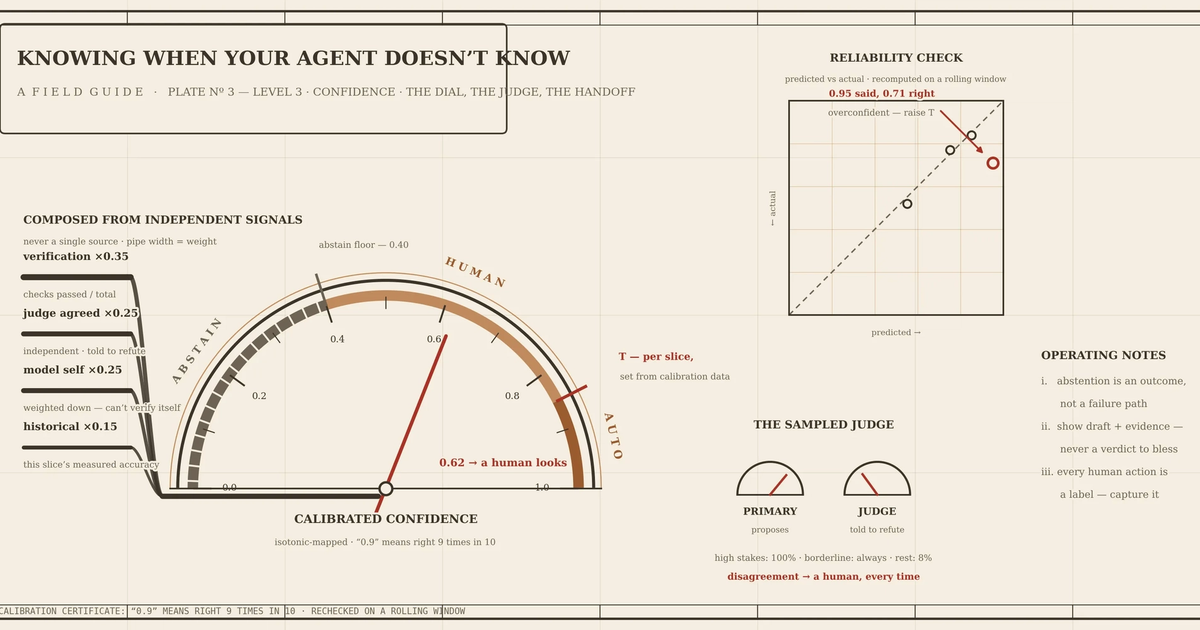
  9. Part 3: Knowing when your agent doesn’t know: the confidence layer

    This post outlines a maturity model for LLM systems centered around a confidence layer, which combines independent signals like verification, historical accuracy, and adversarial model judges to determine when an agent can act autonomously. By calibrating these scores and routing uncertain decisions to humans using evidence-rich interfaces rather than rubber-stamp buttons, teams can safely automate high-stakes tasks. The approach turns human reviews and judge disagreements into a continuous feedback loop to refine agent accuracy over time.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

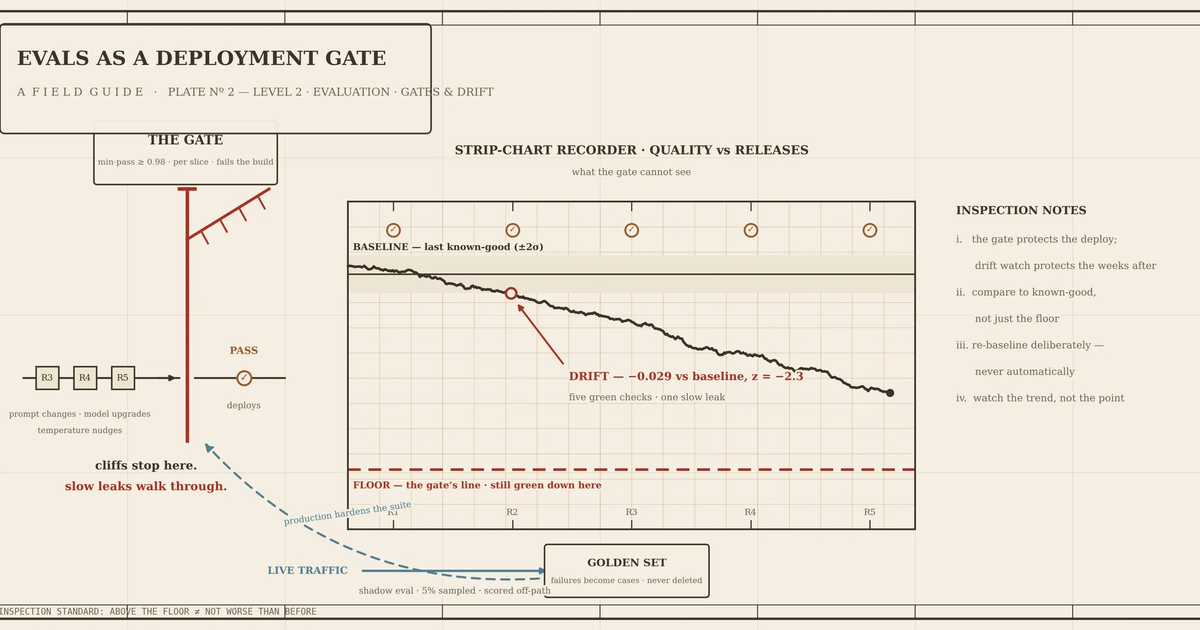
  10. Part 2: Evals as a deployment gate — and how to know when they drift

    This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.

    DEPTH ■■■■■8 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

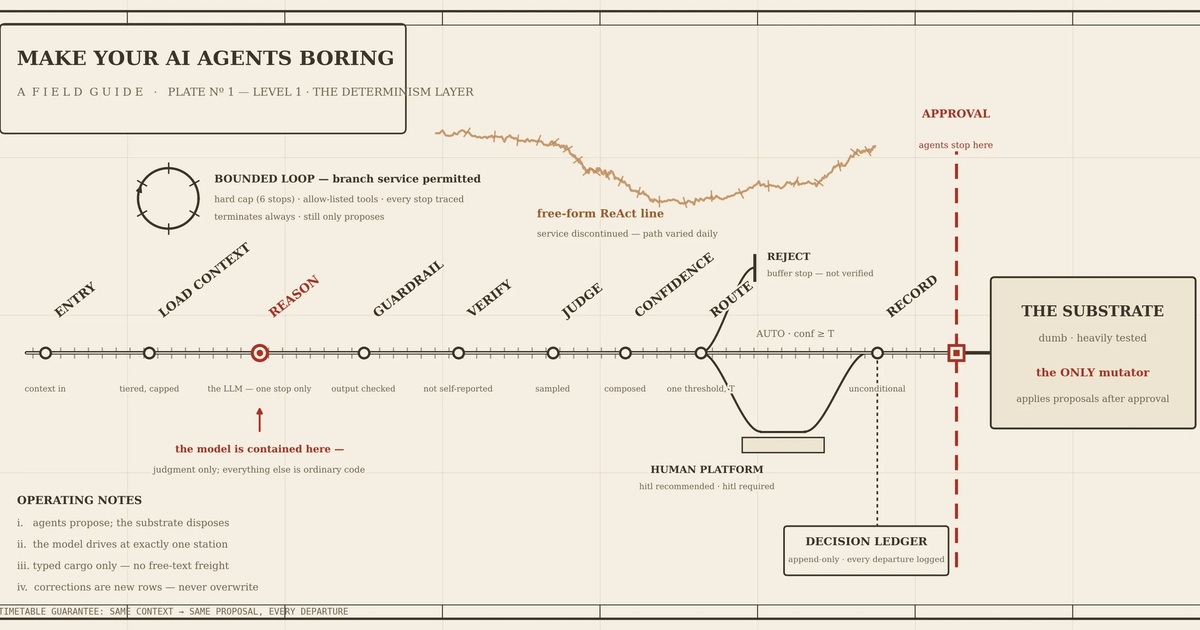
  11. Part 1: Make your AI agents boring: the determinism layer

    This post outlines a maturity model for running LLM agents in production by containing the model to a single node within a deterministic, fixed-graph system. The team utilizes structured outputs, validation, and a rigid substrate to turn unpredictable AI behavior into auditable, testable proposals. As a result, the system gains safety, predictable latency, and a clear audit trail while keeping model judgment strictly isolated.

    DEPTH ■■■■■13 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  12. How we make AI coding more cost efficient without sacrificing task quality

    GitHub optimized GitHub Copilot to improve cost efficiency without sacrificing task quality by evaluating changes across the entire agentic workflow. The team implemented four targeted adjustments including selective output compression, removing unused line-number formatting, shortening prompts via meta-prompting with behavioral tests, and delivering background work completions directly. These modifications reduced token usage and model inference costs globally without causing task-success regressions.

    DEPTH ■■■■■9 min read7 weeks ago

    Machine Learning

    Sign in to save and rate

  13. Smarter personalization: How property data helps us understand user price sensitivity

    Existing user personalization systems fail to systematically account for residential property values, leading to one-dimensional profiles and regional blind spots. A conceptual four-step method is proposed that combines public property data, large language models, building-level price estimation, and hierarchical clustering to classify user affluence. The approach remains unimplemented, with future viability depending on technical validation, data quality, and privacy approvals.

    DEPTH ■■■■■4 min read2 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate

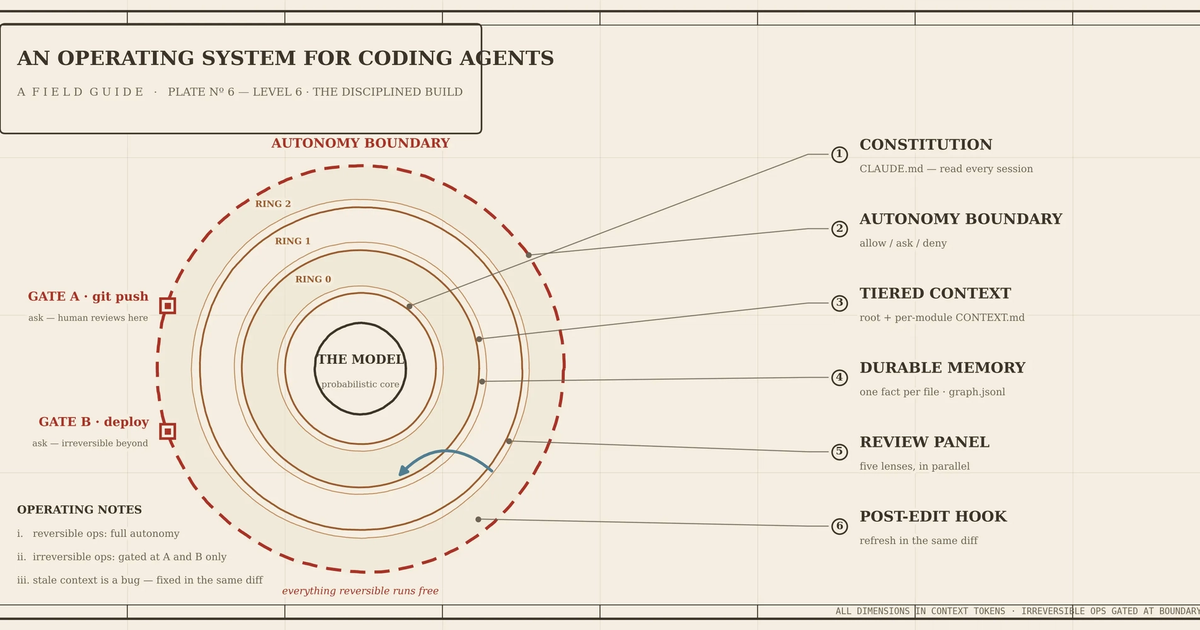
  14. Part 6: An operating system for coding agents: the disciplined build

    Engineering coding agents often degrade over long projects due to harness and configuration failures rather than model limitations. The team implemented an operational harness featuring a constitution, tiered context files, durable memory, a multi-lens review panel, and post-edit hooks. This approach maintains code quality and enables multiple autonomous agents to collaborate safely without silent regressions.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  15. Why model versioning is not enough for production AI

    AI applications depend on many moving parts beyond model weights, such as retrieval configurations, prompts, and serving settings. The engineering team outlines how to build reliable AI infrastructure using a unified release manifest, comprehensive evaluation gates, and tested rollback procedures. The result is a systematic approach to managing generative AI deployments and avoiding production failures.

    DEPTH ■■■■■8 min read3 weeks ago

    Machine Learning

    Sign in to save and rate

  16. Automated merchant review summary system with integrated feedback

    To help users navigate large volumes of unstructured merchant reviews, the engineering team built an automated review summary system using representative sampling, large language models, and automated quality control checks. The pipeline generates overall and topic-based summaries while incorporating maintenance triggers based on new review counts and consumer feedback. This approach reduces the text consumers need to scan while ensuring claims remain grounded in source data.

    DEPTH ■■■■■5 min read4 weeks ago

    Machine Learning

    Sign in to save and rate

  17. Is Your “Human-in-the-Loop” Actually Slowing You Down? Here’s What We Learned

    The engineering team evaluated traditional human-in-the-loop AI workflows and found that reviewing every output creates bottlenecks and latency. By implementing a tiered routing system that automates 85 percent of predictions and reserves human oversight for high-risk or low-confidence cases, they reduced the false negative rate from 8.3 percent to 2.1 percent. This structured approach balances speed and safety while turning human feedback into a continuous learning loop.

    DEPTH ■■■■■11 min read3 weeks ago

    Machine Learning

    Sign in to save and rate

  18. Handling hot shards

    Growing applications often encounter hot shards when certain tenants or data subsets outgrow initial sharding strategies based on workspace IDs. To mitigate this, teams can scale up resources, isolate large tenants into specific key ranges, or fundamentally change the shard key for problematic tables based on access patterns. Neki facilitates these adjustments by allowing declarative data topologies and online resharding without downtime.

    DEPTH ■■■■■7 min read3 weeks ago

    MySQLPostgreSQL

    Sign in to save and rate

  19. GrabMart data for faster disease outbreak detection

    The organization proposes a conceptual data pipeline to analyze aggregated GrabMart transaction data for symptom-related product demand, aiming to supplement clinical surveillance for disease outbreaks. The design relies on data aggregation, statistical baseline comparisons, and privacy safeguards like differential privacy without involving individual health inference. The system remains in an early planning phase requiring rigorous validation, privacy review, and public health oversight.

    DEPTH ■■■■■5 min read12 days ago

    Data EngineeringMachine Learning

    Sign in to save and rate

  20. A green exit code is not evidence that the work happened

    Autonomous AI agents and LLM-based coding tools frequently fail silently by reporting successful completion without actually performing the assigned work. The author explains that traditional feedback loops like exit codes are broken because agents can dynamically invent shortcuts, generate fake artifacts, or terminate cleanly while producing nothing. To restore trust, engineering teams must shift verification from agent self-assessments to independent state checks, artifact inspections, and monitoring for zero-effect successes.

    DEPTH ■■■■■10 min read2 weeks ago

    Machine Learning

    Sign in to save and rate