/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read4 days ago

    Infrastructure

    Sign in to save and rate

  2. App stability at scale with a layered defense

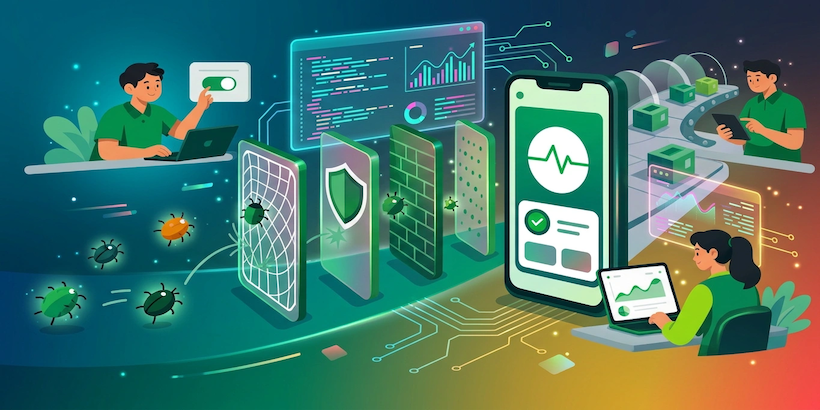
    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read4 days ago

    MobileReliability

    Sign in to save and rate

  3. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

  4. Smarter personalization: How property data helps us understand user price sensitivity

    Existing user personalization systems fail to systematically account for residential property values, leading to one-dimensional profiles and regional blind spots. A conceptual four-step method is proposed that combines public property data, large language models, building-level price estimation, and hierarchical clustering to classify user affluence. The approach remains unimplemented, with future viability depending on technical validation, data quality, and privacy approvals.

    DEPTH ■■■■■4 min read2 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate

  5. GrabMart data for faster disease outbreak detection

    The organization proposes a conceptual data pipeline to analyze aggregated GrabMart transaction data for symptom-related product demand, aiming to supplement clinical surveillance for disease outbreaks. The design relies on data aggregation, statistical baseline comparisons, and privacy safeguards like differential privacy without involving individual health inference. The system remains in an early planning phase requiring rigorous validation, privacy review, and public health oversight.

    DEPTH ■■■■■5 min read12 days ago

    Data EngineeringMachine Learning

    Sign in to save and rate