/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read4 days ago

    Infrastructure

    Sign in to save and rate

  2. App stability at scale with a layered defense

    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read4 days ago

    MobileReliability

    Sign in to save and rate

  3. When Software Meets Hardware

    A software engineering team modernizing a large-scale retail IoT system of 800,000 battery-powered sensors faced challenges integrating software practices with embedded hardware. By building physical sensor farms, virtual emulators, and self-diagnosing firmware, the team learned to design for intermittent connectivity, power efficiency, and fleet-level observability. The project succeeded by treating the physical world, hardware constraints, and engineering environments as core parts of the system lifecycle.

    DEPTH ■■■■■12 min read10 days ago

    Sign in to save and rate

  4. Sentry JavaScript SDK v11 adds tracing for all JS platforms

    Sentry replaced its OpenTelemetry-based JavaScript SDK instrumentation with a source-code transformation approach using diagnostics channels in version 11. This change removes reliance on Node-specific module loader hooks, enabling reliable tracing across non-Node runtimes like Deno, Bun, and Cloudflare Workers, while also supporting bundled applications. The result is a simplified architecture that reduces bundle weight and fixes previous limitations with load order and immutable exports.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate

  5. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read11 days ago

    Microservices

    Sign in to save and rate

  6. Are Harnesses Worth the Cost?

    An experiment was conducted to evaluate whether behavioral harnesses improve coding agent reliability when building a complex backend-for-frontend service. While frontier models succeeded consistently with or without a harness, the harness significantly increased token usage, time, and cost without improving final output. However, for a cost-optimized model, the harness improved success rates from 30 percent to 100 percent.

    DEPTH ■■■■■17 min read12 days ago

    Sign in to save and rate

  7. Reducing Android scope-sync overhead in Sentry Flutter

    The Sentry Flutter team investigated scope-sync overhead on Android and found redundant data normalization across isolates alongside unnecessary buffer copies during JSON encoding. By removing the duplicate normalization and encoding directly to UTF-8 bytes, the team reduced processing time by 27 to 30 percent across benchmarked payloads.

    DEPTH ■■■■■4 min read2 weeks ago

    Sign in to save and rate

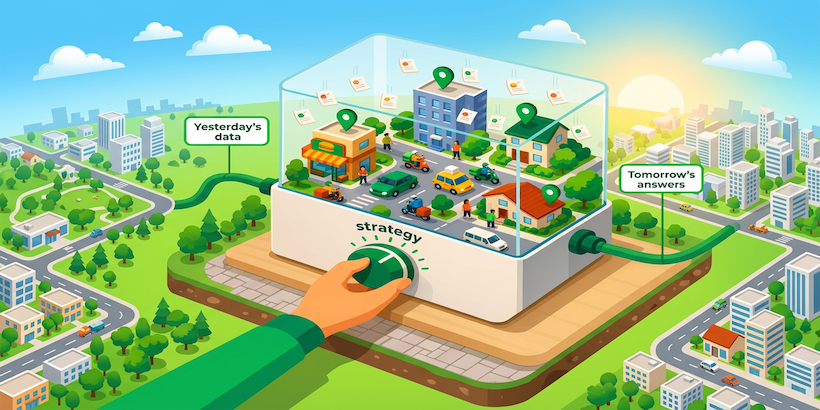
  8. Powering AI-led research through simulation

    The engineering team built a self-contained simulation platform called sim-rs to model marketplace dispatch dynamics and accelerate experimentation. By connecting automated software agents to this simulator with strict safety safeguards, the team successfully optimized strategy policies and simulator performance. This closed-loop lab environment allows agents to test ideas rapidly while ensuring that only valid, production-ready improvements are produced.

    DEPTH ■■■■■10 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  9. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

  10. The Sentry Android SDK is now 20-30% faster!

    The Sentry team optimized the Android SDK to reduce initialization time by 20-30% and background CPU usage by up to 10%. Improvements were achieved by profiling with Perfetto, replacing slow runtime manifest parsing and DSN parsing with build-time bytecode writing and lightweight parsers, and reusing thread pools. Upgrading to the latest SDK version allows applications to realize these startup performance gains.

    DEPTH ■■■■■4 min read5 days ago

    Sign in to save and rate

  11. Staying Evergreen: How we automated secure access and repo hygiene in a shared org

    Manual repository housekeeping and access reviews for outside collaborators become difficult to maintain as organizations scale. The team built Evergreen, a GitHub App that automates quarterly access reviews and stale repository archiving using native platform features and IssueOps. This automation successfully enforces secure defaults by revoking unanswered access while maintaining a full audit trail in git history.

    DEPTH ■■■■■8 min read10 days ago

    Sign in to save and rate

  12. Fragments: October 21

    This post discusses commentary on AI usage in writing, the cancellation of the Grace Hopper Celebration, and reviews a detailed article by Cindy Sridharan on debugging with AI agents. The reviewed article highlights that AI agents excel at processing raw data rather than reading code first, and outlines a three-step debugging process involving controls, signals, and hypothesis validation. The lesson is that engineers must guide AI agents by setting up verification loops and providing raw data rather than human-centric abstractions.

    DEPTH ■■■■■5 min read4 days ago

    Sign in to save and rate

  13. Unreal MCP now speaks Sentry

    The Sentry team integrated their crash reporting plugin with Unreal Engine's new experimental Model Context Protocol (MCP) server, allowing coding agents to fully automate setup and debugging. By combining editor tools and Sentry MCP, an agent successfully configured the SDK, uploaded debug symbols, packaged a build, induced a crash, and traced the root cause without manual file editing. The integration streamlines crash reporting setup, though it currently suffers from occasional agent tool-discovery issues and server fragility across editor restarts.

    DEPTH ■■■■■7 min read2 weeks ago

    Sign in to save and rate

  14. Improving site performance by shipping more CSS

    GitHub faced performance degradation on server-side rendering and initial page loads due to scaling issues with its CSS-in-JS solution. The engineering team executed a multi-year migration to CSS Modules and eliminated dynamic styling props using incremental rollouts, wrapper components, and automation tools. This resulted in significant performance gains, including 55% faster server-side rendering and the complete removal of styled-components.

    DEPTH ■■■■■8 min read4 weeks ago

    FrontendPerformance

    Sign in to save and rate

  15. Should you use a log or a metric?

    This post explains the distinction between logs and metrics in application monitoring, noting that logs capture what was true during specific events for debugging while metrics track ongoing numerical trends over time. The author demonstrates how to implement both using Sentry SDKs during a user signup flow and outlines criteria for choosing between them. The resulting takeaway helps engineers decide whether to log an event or track it as a metric based on the questions they need to answer.

    DEPTH ■■■■■12 min read3 days ago

    Sign in to save and rate

  16. Practitioner Voice: The Writing Category Nobody has Named Yet

    The author explores a missing category of writing called Practitioner Voice, which is grounded in earned experience and visible personal judgment rather than academic rigor, corporate polish, or AI generation. They examine how AI can be used as an extended cognitive tool for practitioners without losing human accountability. Ultimately, the piece argues that maintaining personal judgment and consequence-bearing experience is essential for authentic professional writing.

    DEPTH ■■■■■39 min read12 days ago

    Sign in to save and rate

  17. Smarter personalization: How property data helps us understand user price sensitivity

    Existing user personalization systems fail to systematically account for residential property values, leading to one-dimensional profiles and regional blind spots. A conceptual four-step method is proposed that combines public property data, large language models, building-level price estimation, and hierarchical clustering to classify user affluence. The approach remains unimplemented, with future viability depending on technical validation, data quality, and privacy approvals.

    DEPTH ■■■■■4 min read2 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate

  18. Rendering huge pull requests in the GitHub Copilot app

    Rendering extremely large pull requests with millions of lines and hundreds of comments requires separating deterministic code row geometry from unpredictable dynamic comment blocks. The team implemented an idle-gated measurement scheduler, separate height indices, and identity-based scroll anchoring to maintain smooth scrolling. As a result, the pull request view remains performant and responsive even under extreme loads.

    DEPTH ■■■■■14 min read4 weeks ago

    Sign in to save and rate

  19. How Etsy gets its mobile apps ready for peak traffic

    Etsy prepares its mobile apps for peak holiday traffic through advance planning, operational guardrails, and risk management rather than relying on capacity scaling or the ability to quickly revert binaries. The engineering team utilizes a phased code slush, dual crash reporting, remote feature flags, and custom error tagging to surface and mitigate issues effectively under heavy loads. By connecting crash rates to business metrics and automating manual triage workflows incrementally, the organization maintains high visibility and reliability when updates cannot be instantly rolled back.

    DEPTH ■■■■■11 min read3 weeks ago

    Sign in to save and rate

  20. Fragments: October 4

    This post discusses the evolving role of software development and code in the era of large language models. It explores how shifting from deterministic building to inferential nurturing changes processes, why high-level representations remain critical for managing context windows, and how conceptual modeling becomes more important than the mechanical act of writing instructions.

    DEPTH ■■■■■7 min read2 weeks ago

    Sign in to save and rate