/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Shard design doesn't start from your tables

    Designing a sharded Postgres architecture requires grouping tables around shared query keys rather than starting from table structures alone. The post details how to configure shard groups, reference tables, SQL expressions in shard indexes, and global secondary indexes using Neki. This setup enables efficient single-shard queries and transactions while maintaining full Postgres semantics.

    DEPTH ■■■■■8 min read2 days ago
    PostgreSQL

    Sign in to save and rate

  2. Automate medical coding with Step Functions and Amazon Bedrock AgentCore

    Automating medical coding requires a hybrid approach that combines deterministic orchestration with bounded agentic reasoning to ensure safety, auditability, and human oversight. The team built a workflow using AWS Step Functions, AWS Lambda, and Amazon Bedrock AgentCore that evaluates terms cheapest-first via block-lists, exact matching, and finally an LLM agent for ambiguous cases. This design successfully autocodes confident cases while routing ambiguous ones to human reviewers with full audit trails and decision explanations.

    DEPTH ■■■■■15 min read4 days ago

    AWS

    Sign in to save and rate

  3. App stability at scale with a layered defense

    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read4 days ago

    MobileReliability

    Sign in to save and rate

  4. MCP standardized tools. Now we need the infrastructure around them.

    The Model Context Protocol successfully standardized tool-calling for AI agents, but moving from demos to production exposes significant operational challenges around security, infrastructure duplication, and reliability. Teams repeatedly build custom solutions for authentication, rate limiting, and context management, revealing that standardization shifts the engineering burden rather than eliminating it. Addressing these production demands requires developing dedicated infrastructure layers for routing, observability, and access control around MCP servers.

    DEPTH ■■■■■8 min read10 days ago

    Machine Learning

    Sign in to save and rate

  5. I don't trust ON DELETE CASCADE

    Postgres ON DELETE CASCADE can cause production outages, replication failures, and performance degradation during large deletions or schema migrations due to long-running transactions holding locks and generating massive WAL. The author recommends using soft deletes with batched background cleanup instead to keep transactions short and bounded. This approach avoids table locks and simplifies data recovery.

    DEPTH ■■■■■5 min read4 days ago

    PostgreSQL

    Sign in to save and rate

  6. Multi-region disaster recovery for Amazon API Gateway WebSocket APIs

    Real-time applications using WebSocket connections face disruptions during regional AWS outages because connections are tied to specific regions. The team implemented an active-passive multi-region disaster recovery architecture using Route 53 DNS failover, DynamoDB Global Tables, an automated canary health probe, and client-side exponential backoff with jitter. This design automatically detects failures, redirects traffic, and restores client state without manual intervention.

    DEPTH ■■■■■10 min read11 days ago

    Sign in to save and rate

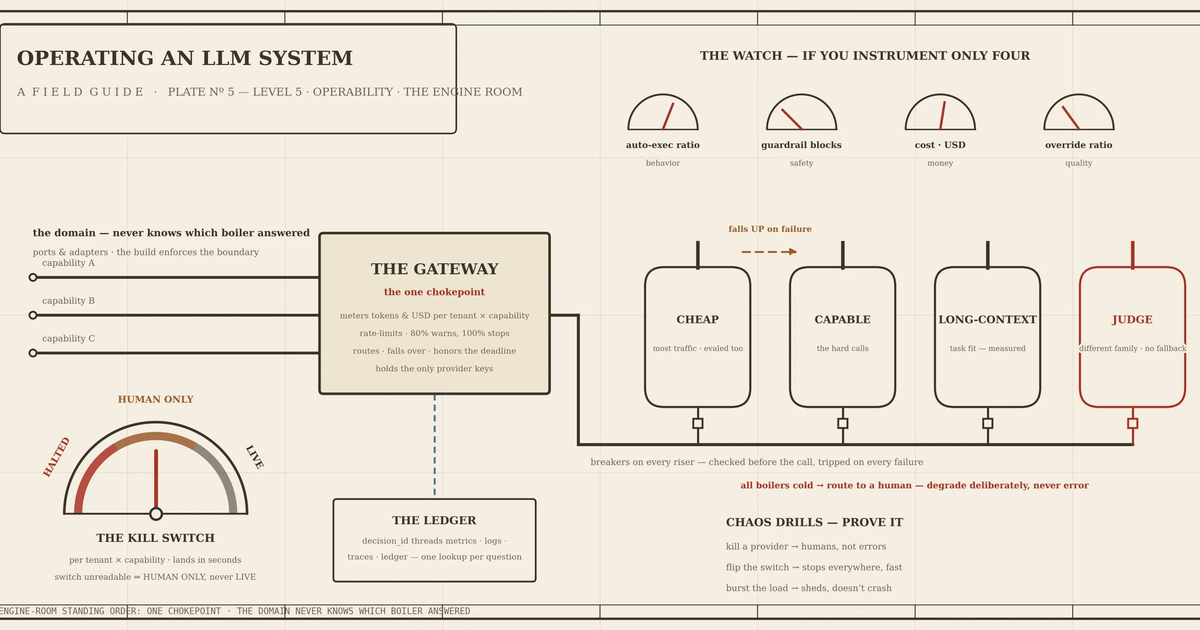
  7. Part 5: Operating an LLM system: observability, cost, routing, and the platform underneath

    This post provides a concrete specification for the operability layer of production LLM systems, covering observability signals, structured logging, cost controls, routing, and failover mechanisms. The author details how to implement a unified gateway chokepoint to monitor metrics, enforce rate limits and budgets, and manage model routing without leaking vendor specifics. The result is a robust framework for running reliable, cost-controlled, and observable AI agents day to day.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  8. How UTS established a modern curriculum data services foundation on AWS

    University of Technology Sydney rearchitected its curriculum data integration using serverless AWS services to decouple systems of record from downstream consumers. By implementing domain-driven design with an event-driven architecture and purpose-built persistence layers, the team achieved zero production incidents, low latency, and reduced operational overhead while managed by a single engineer.

    DEPTH ■■■■■9 min read11 days ago

    Sign in to save and rate

  9. What gets TOASTed in Postgres

    This post examines how PostgreSQL uses TOAST to manage oversized rows and variable-length columns through compression and off-row storage. It compares the pglz and LZ4 compression algorithms across different workloads, highlighting trade-offs in search windows, file sizes, and CPU overhead. The analysis demonstrates how these mechanisms impact storage efficiency and read performance for large text and JSON data.

    DEPTH ■■■■■12 min read13 days ago

    PostgreSQL

    Sign in to save and rate

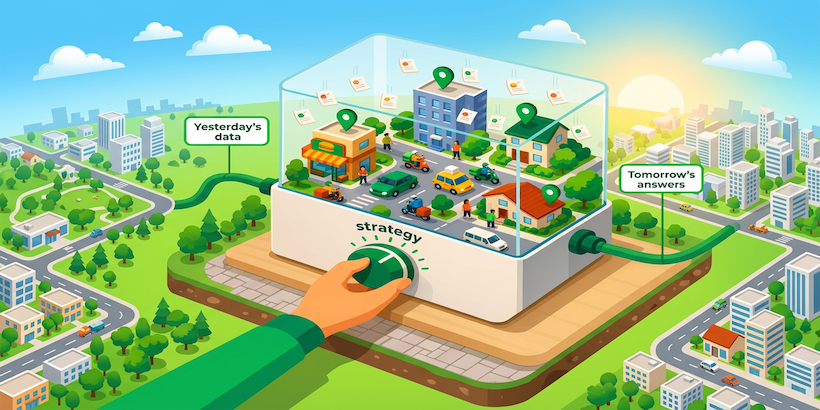
  10. Powering AI-led research through simulation

    The engineering team built a self-contained simulation platform called sim-rs to model marketplace dispatch dynamics and accelerate experimentation. By connecting automated software agents to this simulator with strict safety safeguards, the team successfully optimized strategy policies and simulator performance. This closed-loop lab environment allows agents to test ideas rapidly while ensuring that only valid, production-ready improvements are produced.

    DEPTH ■■■■■10 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  11. Part 4: Safety and governance for LLM systems: guardrails, PII, audit, and memory

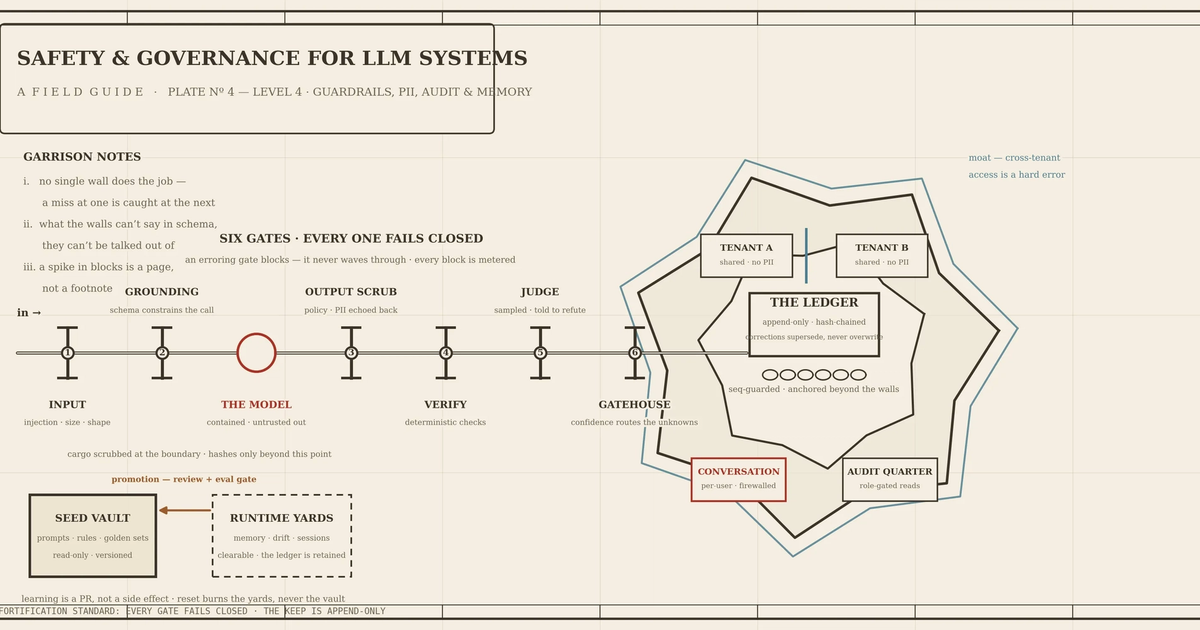
    This post details safety and governance practices for LLM systems, focusing on layered guardrails, boundary-level PII handling, and immutable audit trails. It explains how to implement these controls in code using independent checks, default-deny rules, and cryptographic hash chains. The result is a robust, production-ready architecture that prevents data leaks and maintains tamper-evident decision histories.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  12. Scope workloads and share resilience policies with AWS Resilience Hub

    Engineering teams often struggle to scope workloads and maintain up-to-date resilience policies in shared Kubernetes clusters after migrations or deployments. AWS Resilience Hub introduced features enabling Kubernetes label-based resource scoping, generative AI-powered dependency insights, and cross-account resilience policy sharing via AWS Organizations. These capabilities allow teams to isolate specific workloads, prioritize dependency investigations, and enforce centralized recovery standards.

    DEPTH ■■■■■14 min read12 days ago

    Sign in to save and rate

  13. TIN v1.0.6: 2-3x faster, with support for stemming

    Following competitive benchmarks that highlighted opportunities for optimization, the developers of the TIN full-text search index for Postgres released versions 1.0.4 and 1.0.6. These updates added Snowball stemming for 18 languages, optimized top-k sorting queries with deterministic tiebreakers, and improved overall query performance. As a result, benchmark tests show that TIN outperforms competing extensions across conjunction, disjunction, and phrase query workloads.

    DEPTH ■■■■■8 min read2 weeks ago

    PostgreSQL

    Sign in to save and rate

  14. Part 3: Knowing when your agent doesn’t know: the confidence layer

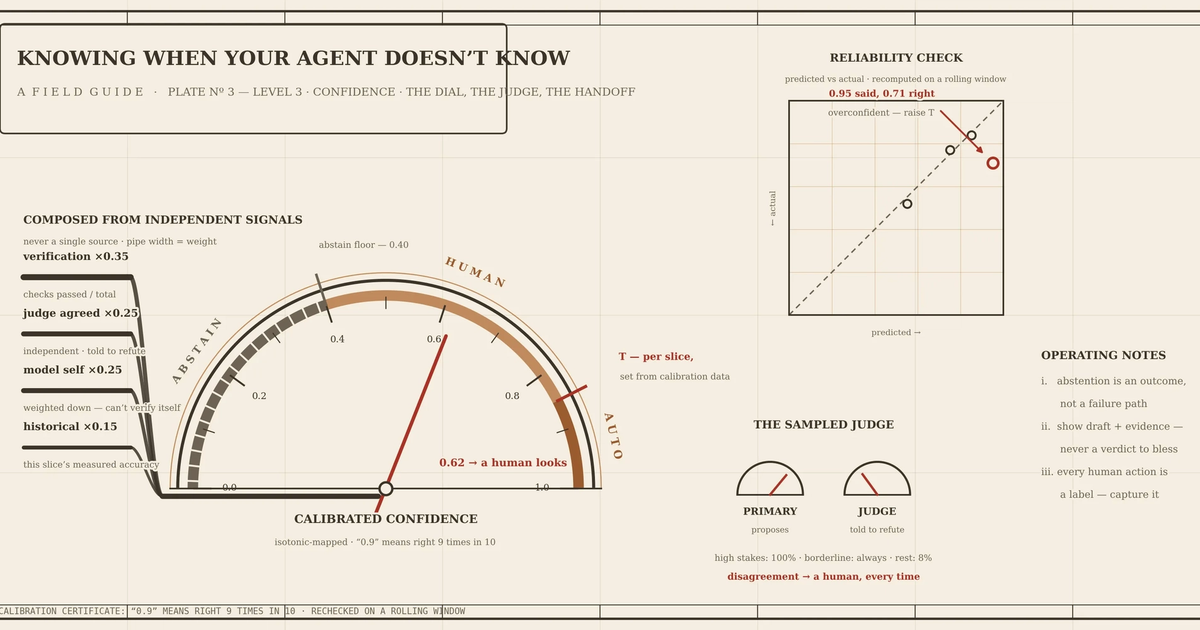
    This post outlines a maturity model for LLM systems centered around a confidence layer, which combines independent signals like verification, historical accuracy, and adversarial model judges to determine when an agent can act autonomously. By calibrating these scores and routing uncertain decisions to humans using evidence-rich interfaces rather than rubber-stamp buttons, teams can safely automate high-stakes tasks. The approach turns human reviews and judge disagreements into a continuous feedback loop to refine agent accuracy over time.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  15. Stopping business email compromise with AI-driven email security: How VIPRE protects modern enterprises on AWS

    VIPRE developed an AI-driven, cloud-native email security solution on AWS to protect enterprises against business email compromise and advanced phishing attacks. The system uses layered machine learning, semantic analysis, and dynamic sandboxing orchestrated via serverless containers and message queues to evaluate over half a million messages daily. In production testing, the architecture successfully identified thousands of BEC attempts while maintaining low-latency processing and reducing administrative overhead.

    DEPTH ■■■■■12 min read12 days ago

    Sign in to save and rate

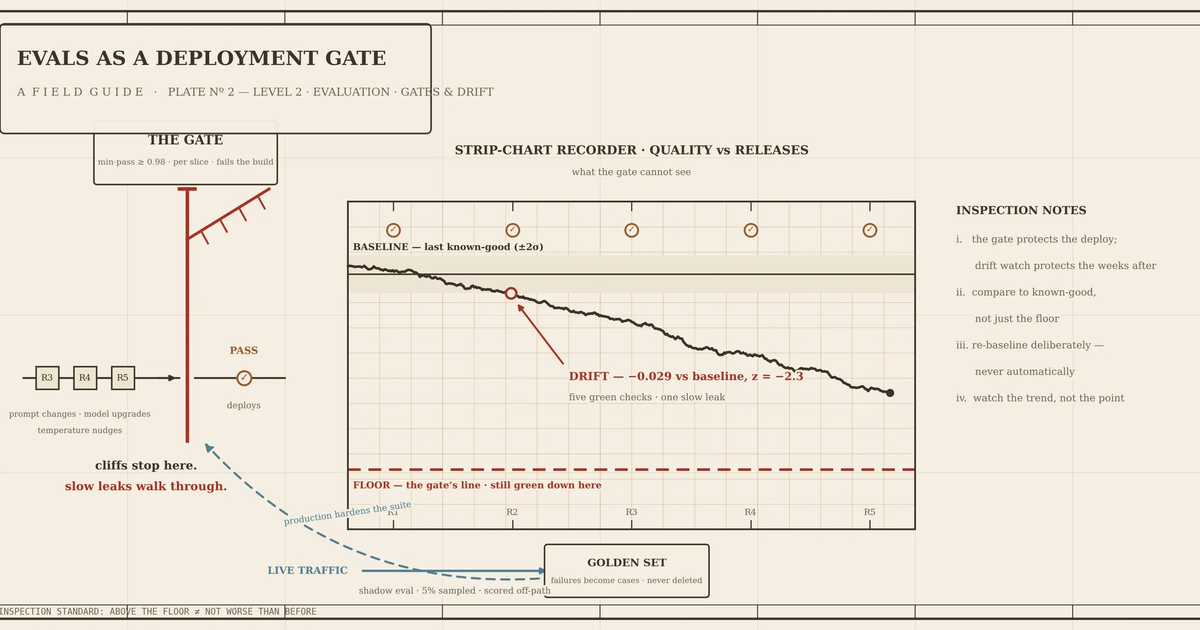
  16. Part 2: Evals as a deployment gate — and how to know when they drift

    This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.

    DEPTH ■■■■■8 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  17. Bulk Executor for Amazon DynamoDB, Part 2: Lessons we learned the hard way

    Engineering a bulk execution tool for Amazon DynamoDB using AWS Glue required addressing several architectural challenges, including cost estimation, graceful job termination, and error handling across hundreds of parallel workers. The team overcame limitations in CloudWatch logging and the Spark connector by combining serverless execution with direct API calls and distributed rate limiting. As a result, the tool provides a scalable, script-like interface for managing large-scale table operations safely.

    DEPTH ■■■■■14 min read12 days ago

    Sign in to save and rate

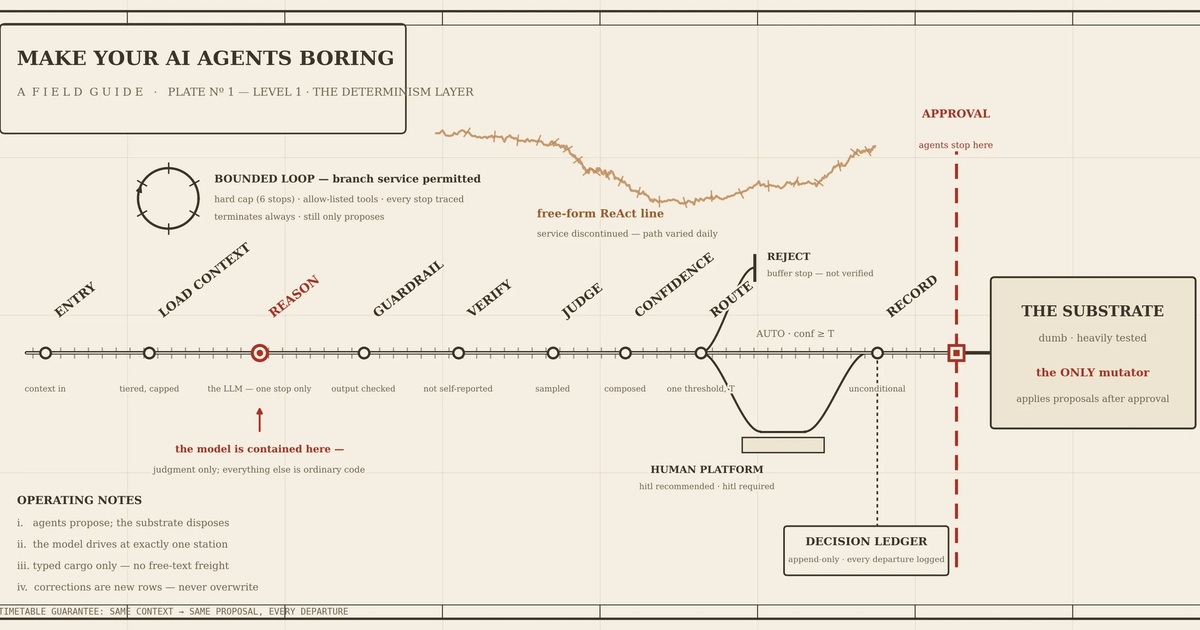
  18. Part 1: Make your AI agents boring: the determinism layer

    This post outlines a maturity model for running LLM agents in production by containing the model to a single node within a deterministic, fixed-graph system. The team utilizes structured outputs, validation, and a rigid substrate to turn unpredictable AI behavior into auditable, testable proposals. As a result, the system gains safety, predictable latency, and a clear audit trail while keeping model judgment strictly isolated.

    DEPTH ■■■■■13 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  19. Building a faster, lazier router for Postgres

    To reduce overhead when routing queries across PostgreSQL shards, the Neki router avoids unnecessary parsing and decodes responses lazily. By keeping data in its original wire format and only decoding columns when strictly required for operations like limits or sorting, the router significantly improves performance.

    DEPTH ■■■■■16 min read3 weeks ago

    Sign in to save and rate

  20. Agentic antimicrobial resistance surveillance with AWS HealthOmics and Amazon Bedrock AgentCore

    Processing public bacterial sequencing data for antimicrobial resistance surveillance typically requires specialized bioinformatics and SQL skills. To streamline this process, the team built a reference architecture using AWS HealthOmics, Amazon S3 Tables, and an Amazon Bedrock AgentCore conversational agent that ingests raw reads, normalizes findings, and answers plain-language questions with cited evidence. The resulting system automates the path from public accession numbers to natural-language epidemiological answers.

    DEPTH ■■■■■10 min read13 days ago

    Sign in to save and rate