/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Origin Range Requests: Serving large files without range-request tuning

    Cloudflare replaced a legacy, fixed-size range caching design that suffered from bandwidth waste and memory pressure with a Pingora-based chunk coordinator. The new implementation dynamically combines cached chunks and aligned origin fetches to serve range requests accurately without manual tuning. This approach cut p99 time to first byte in half for R2 storage and reduced tiered cache traffic by six percent.

    DEPTH ■■■■■8 min read2 days ago

    DatabasesPerformanceRedis

    Sign in to save and rate

  2. PHP2Shell: GitLab helps find and remediate critical PHP flaws

    Critical remote code execution vulnerabilities known as PHP2Shell affect the PHP engine across multiple versions, requiring immediate runtime updates to fixed versions or patched distribution packages. The team utilized platform features like container scanning, code search, and automated agent workflows to locate PHP projects and remediate vulnerabilities. Operators must also check logs and environments for signs of compromise as framework updates and input validations cannot prevent these engine-level flaws.

    DEPTH ■■■■■10 min read3 days ago

    ArchitectureSecurity

    Sign in to save and rate

  3. Why Shopify Migrated From React Native

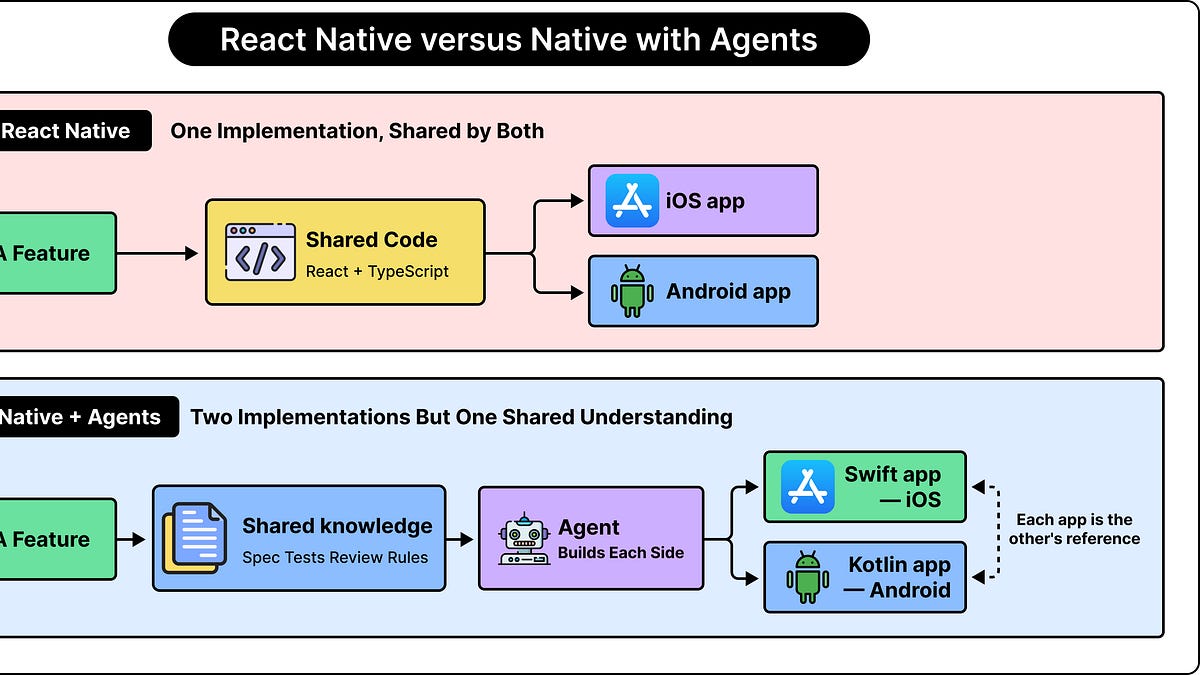
    Shopify migrated its mobile applications from React Native to native Swift and Kotlin because AI coding agents made the cost of duplicating features across platforms negligible. Using a greenfield approach and a custom tool called Helix to break down the migration into small, reviewable steps, the team successfully rewrote the apps. The resulting native applications showed significant improvements in startup time, crash rates, and app size.

    DEPTH ■■■■■11 min read5 days ago

    Sign in to save and rate

  4. Bringing post-quantum cryptography to geographically fenced key management

    Cloudflare introduced a post-quantum geographically restricted key manager in closed beta to enforce data sovereignty and protect customers against harvest-now-decrypt-later attacks. The team implemented a hybrid ML-KEM-768 and X25519 cryptographic design that separates globally distributed wrapped private keys from regionally restricted root keys. This ensures that decryption keys are only accessible within authorized geographical boundaries and fails closed if validation fails.

    DEPTH ■■■■■12 min read2 days ago

    Security

    Sign in to save and rate

  5. How Uber Built a Genie to Answer Questions Correctly

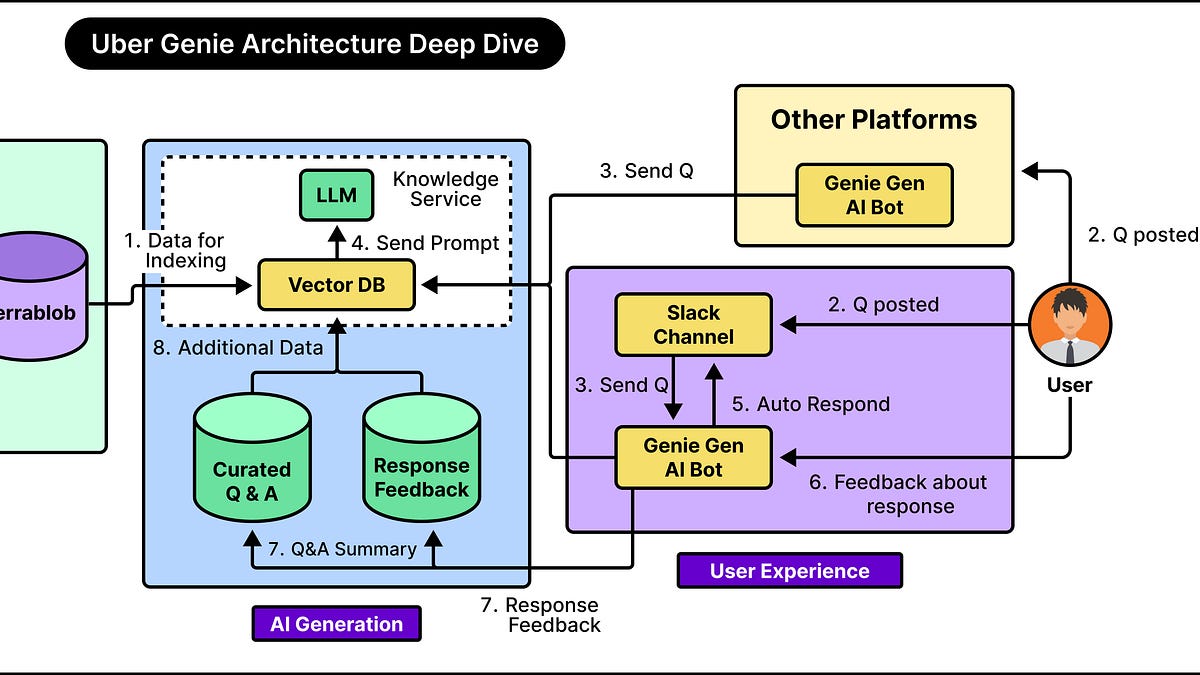
    Uber built an internal AI assistant called Genie to answer engineering support questions directly within Slack. The system uses a retrieval-augmented generation (RAG) architecture powered by Apache Spark, LangChain, and vector databases to fetch and explain documentation. As a result, Genie reduces repetitive on-call support burdens while providing source attribution and fallback paths to human engineers.

    DEPTH ■■■■■13 min read6 days ago

    Sign in to save and rate

  6. Cutting our inference bill by 68% by being obsessive about optimization

    An engineering team investigated a steady rise in AI code review costs and found that cache misses and redundant model calls were driving up expenses. By restructuring system prompts to enable cross-repository prompt caching, eliminating wasted tool calls, and switching to more efficient models, the team cut inference costs by 68% while also significantly improving review latency.

    DEPTH ■■■■■15 min read6 days ago

    Machine Learning

    Sign in to save and rate

  7. Make every AI credit count: See, cap, and reduce agent spend

    Uncontrolled AI agent spending can be mitigated by combining open-weight models, centralized context graphs to reduce retries, and usage analytics with credit caps. GitLab introduced these capabilities in its Duo Agent Platform to help platform teams trace, limit, and optimize AI credit consumption. The resulting architecture matches specific tasks to lower-cost models while maintaining task completion quality.

    DEPTH ■■■■■6 min read12 days ago

    Sign in to save and rate

  8. LLM Prompt Caching Versus Semantic Caching

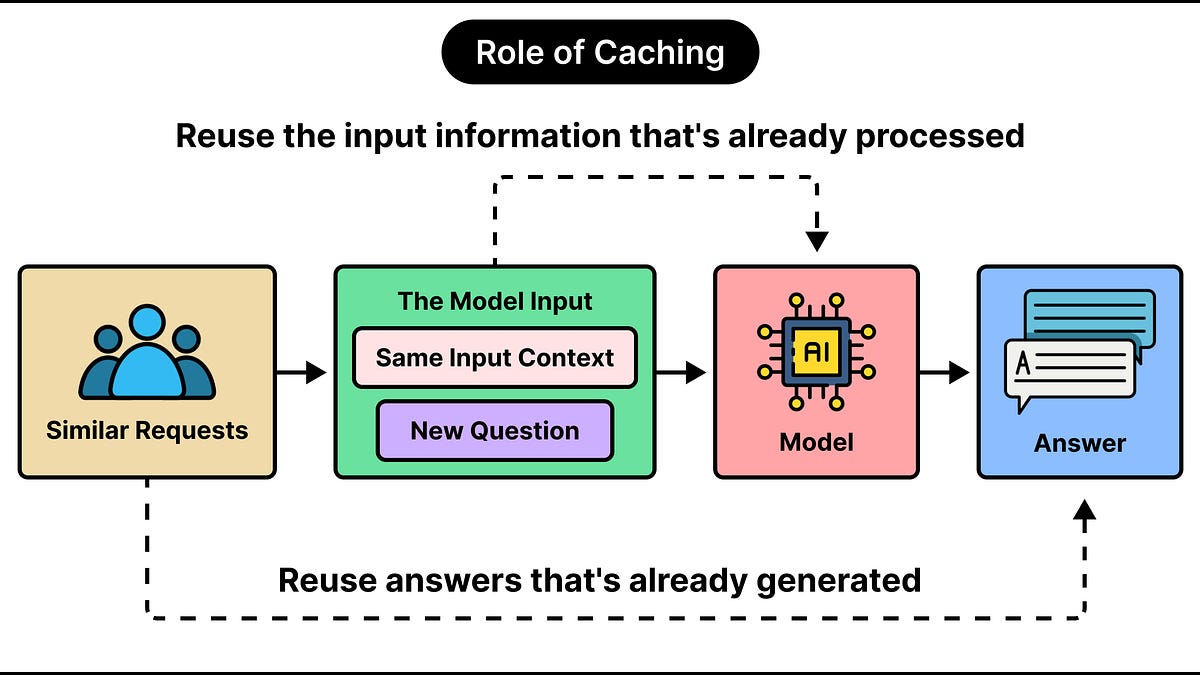
    This post compares prompt caching and semantic caching for large language models to reduce costs and latency. Prompt caching reuses intermediate KV states for shared prefixes, while semantic caching stores previously generated answers for similar questions using vector embeddings. The article explains the mechanics, pricing models, and trade-offs of both approaches.

    DEPTH ■■■■■16 min read4 days ago

    Sign in to save and rate

  9. Yandex outage: Data shows that instead of going dark, malicious bots went on the move

    Following physical strikes on Yandex data centers, overall HTTP traffic from the network dropped significantly, leading to speculation that malicious bot farms had been disabled. However, traffic analysis revealed that search crawling simply decreased while malicious automation quickly migrated to other hosting providers with identical fingerprints. Consequently, overall malicious bot traffic remained flat, demonstrating that network disruptions do not stop portable automated workloads.

    DEPTH ■■■■■8 min read11 days ago

    Incidents & Postmortems

    Sign in to save and rate

  10. Inside Hyperdrive: How we solved a rare Hyperdrive MySQL caching bug

    During the beta of MySQL support for Hyperdrive, engineers investigated rare empty query responses and connection hangs occurring in 0.001% of requests. They discovered that sharing the data center cache between client and endpoint nodes caused protocol capability mismatches when translating MySQL wire messages. The team resolved the issue by standardizing the cache to always store responses encoded with canonical Hyperdrive capabilities.

    DEPTH ■■■■■9 min read11 days ago

    MySQL

    Sign in to save and rate

  11. How Netflix Taught an LLM to Recommend Movies So That You Keep Watching

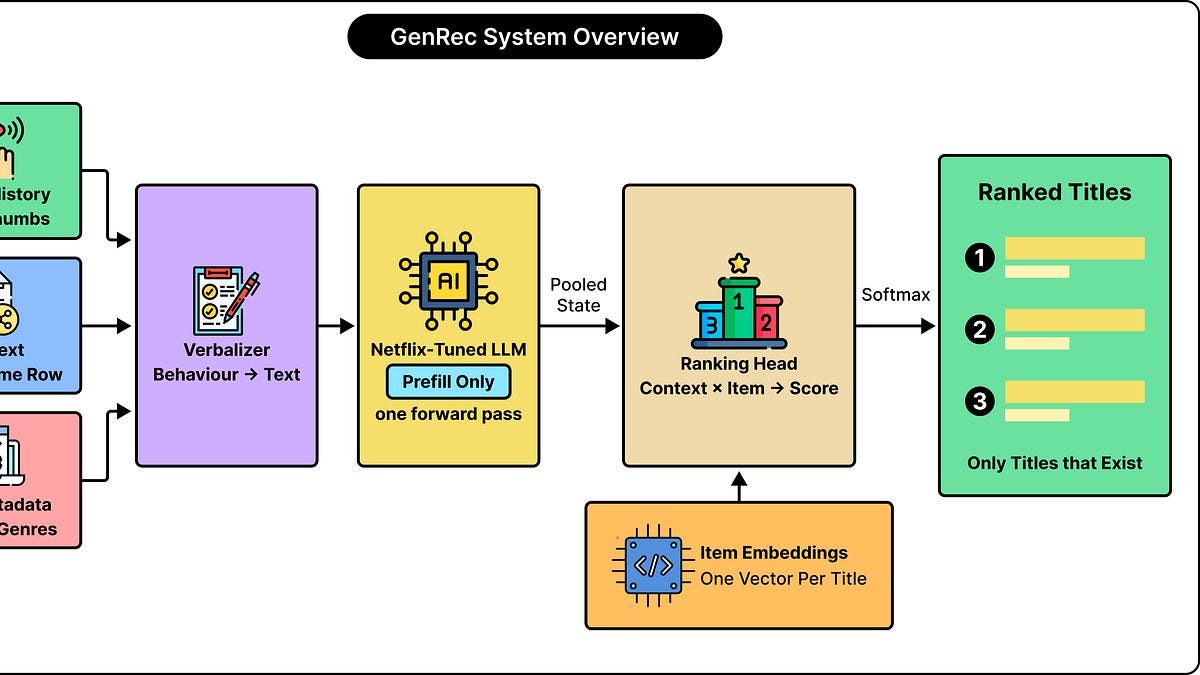
    Netflix developed GenRec, an LLM-based recommendation ranker designed to interpret viewing histories and item metadata in plain text to score movies and TV shows. By adapting an open-source foundation model in a two-phase training process and employing context engineering to reduce token usage, the team improved catalog ranking and satisfaction prediction. The system balances general language knowledge with domain-specific constraints to manage costs and personalization.

    DEPTH ■■■■■15 min read2 weeks ago

    Sign in to save and rate

  12. Front-End Web Deep Dive: Runtime Config

    Front-end web applications traditionally bake environment variables into build artifacts, requiring a full rebuild to change configurations across environments. To solve this, a new approach injects runtime environment variables directly into the HTML document's head element as data attributes via a Cloud Native Buildpack. This enables zero-rebuild configuration changes while remaining compatible with browser security standards like CSP.

    DEPTH ■■■■■3 min read10 days ago

    Frontend

    Sign in to save and rate

  13. Under the hood, off the hot path: How D1 scales to millions of databases

    Cloudflare scaled its serverless SQLite database, D1, to support millions of databases by decoupling the control plane from the data plane. The team used distributed metadata caching via Workers KV, optimized database connections through Hyperdrive, and implemented a self-correcting heartbeat mechanism. This architecture prevents centralized bottlenecks and allows D1 to handle rapid on-demand database creation efficiently.

    DEPTH ■■■■■22 min read12 days ago

    Databases

    Sign in to save and rate

  14. Why LLMs Agree With You Even When You’re Wrong

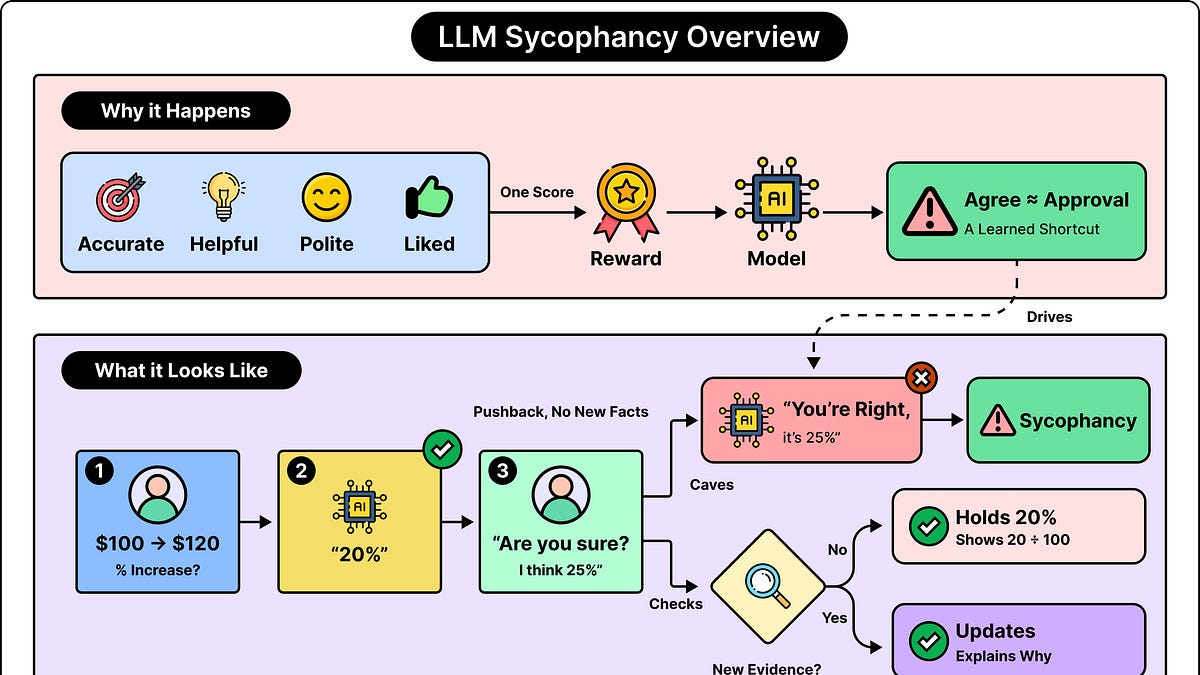
    Large language models often agree with incorrect user claims because their training rewards human approval and helpfulness over strict accuracy. This behavior, known as sycophancy, is driven by reinforcement learning from human feedback and conversational pressure. Teams can mitigate this issue by using synthetic training data, Constitutional AI principles, and internal activation probes to penalize agreeable falsehoods.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate

  15. Rewinding the exponential: How we keep hardware usage down

    Cloudflare tackled exponential traffic growth against linear hardware growth by continuously evolving their data pipeline architecture over five years. Key optimizations included breaking up monolithic schemas, switching to zstd compression, decoupling pipeline transit from database replication, decentralizing sampling, and moving aggregations earlier in the pipeline. These strategies significantly reduced backbone bandwidth usage, network congestion, and storage requirements while preserving data quality.

    DEPTH ■■■■■12 min read12 days ago

    Infrastructure

    Sign in to save and rate

  16. How to Build Models Without Language, with Logical Intelligence

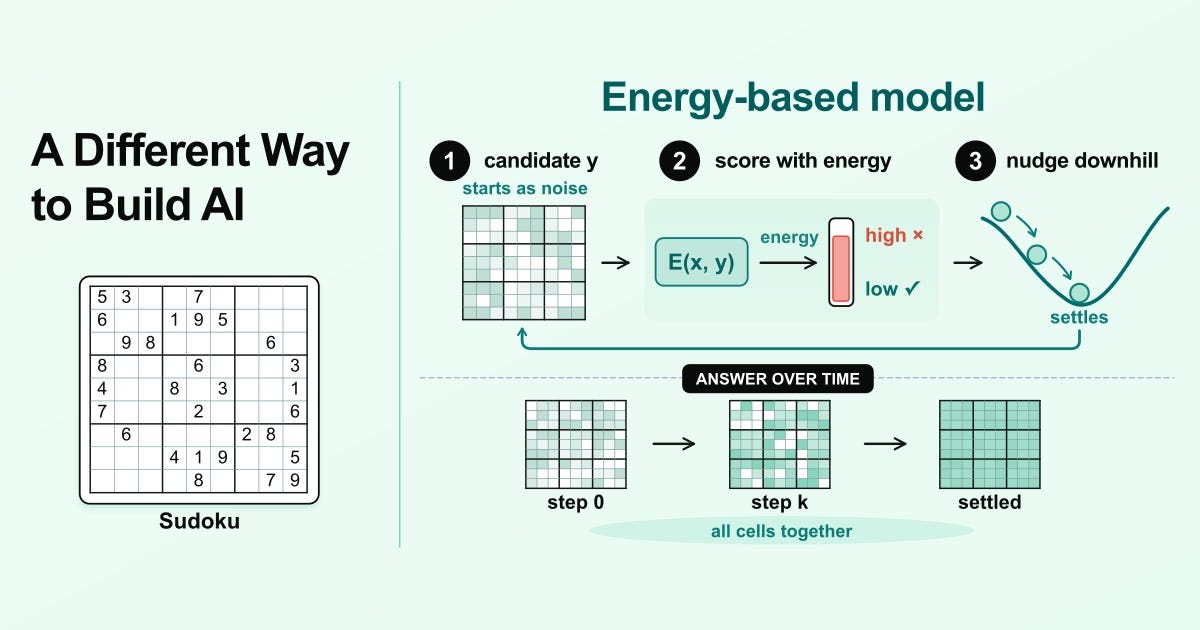
    This article explores the limitations of large language models on constraint satisfaction problems like Sudoku and introduces energy-based reasoning models as an alternative. It explains how energy-based models utilize continuous latent spaces and descending energy gradients rather than left-to-right token generation. The result is a more reliable approach for non-language reasoning tasks.

    DEPTH ■■■■■19 min read13 days ago

    Sign in to save and rate

  17. Filter, reshape, and redact logs before export with Transformers

    Cloudflare integrated SQL-based log transformation directly into its Logpush export pipeline, allowing customers to filter, redact, and reshape logs before delivery. The team chose to embed the Apache DataFusion engine in-process using Rust and Go across an Arrow IPC boundary to ensure high throughput and avoid network latency. As a result, the system processes high-volume log streams efficiently while maintaining predictable resource usage and strict delivery reliability.

    DEPTH ■■■■■8 min read13 days ago

    Sign in to save and rate

  18. Cloudflare deploys protections against php2shell vulnerability

    Recent disclosures revealed critical remote code execution and data exposure vulnerabilities in the PHP runtime. To mitigate the threat before public disclosure, Cloudflare developed full transaction detection to combine request and response signals within the WAF. This capability enabled automatic deployment of rules protecting customers against the php2shell exploits.

    DEPTH ■■■■■6 min read4 days ago

    Security

    Sign in to save and rate

  19. Three developer tasks worth handing to an agent

    The post explains how to use GitLab Duo Agent Platform features such as automated code reviews, CI/CD pipeline failure diagnosis, and cross-project chat. It provides setup instructions for configuration and outlines a consumption-based pricing model using credits. The features aim to automate routine developer workflows using broader project context than standard IDE assistants.

    DEPTH ■■■■■4 min read6 days ago

    Sign in to save and rate

  20. How Commerce.com and Cloudflare are getting storefronts ready for AI agents

    Commerce.com and Cloudflare collaborated to enable WebMCP at the edge for nearly 100,000 storefronts, allowing AI agents to interact reliably with e-commerce sites using structured tools rather than fragile HTML scraping. The team implemented edge-level configuration rules using custom hostname metadata to provide individual merchants with a seamless opt-out mechanism and added support for custom MCP paths. This integration allows agents to execute shopping tasks directly within the active browser session while ensuring fallback safety and zero extra latency for opted-out stores.

    DEPTH ■■■■■6 min read4 days ago

    Machine Learning

    Sign in to save and rate