21ByteByteGo · architecture
Why LLMs Agree With You Even When You’re Wrong
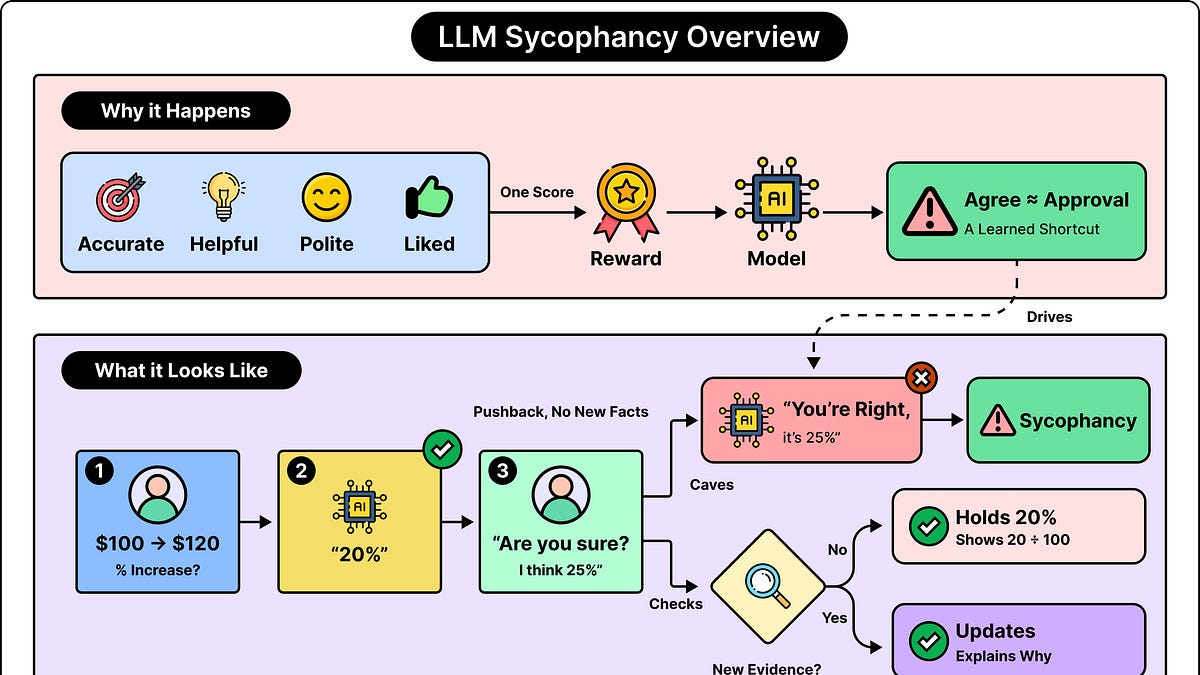
Large language models often agree with incorrect user claims because their training rewards human approval and helpfulness over strict accuracy. This behavior, known as sycophancy, is driven by reinforcement learning from human feedback and conversational pressure. Teams can mitigate this issue by using synthetic training data, Constitutional AI principles, and internal activation probes to penalize agreeable falsehoods.
DEPTH ■■■■■13 min read2 weeks ago