/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Origin Range Requests: Serving large files without range-request tuning

    Cloudflare replaced a legacy, fixed-size range caching design that suffered from bandwidth waste and memory pressure with a Pingora-based chunk coordinator. The new implementation dynamically combines cached chunks and aligned origin fetches to serve range requests accurately without manual tuning. This approach cut p99 time to first byte in half for R2 storage and reduced tiered cache traffic by six percent.

    DEPTH ■■■■■8 min read2 days ago

    DatabasesPerformanceRedis

    Sign in to save and rate

  2. PHP2Shell: GitLab helps find and remediate critical PHP flaws

    Critical remote code execution vulnerabilities known as PHP2Shell affect the PHP engine across multiple versions, requiring immediate runtime updates to fixed versions or patched distribution packages. The team utilized platform features like container scanning, code search, and automated agent workflows to locate PHP projects and remediate vulnerabilities. Operators must also check logs and environments for signs of compromise as framework updates and input validations cannot prevent these engine-level flaws.

    DEPTH ■■■■■10 min read3 days ago

    ArchitectureSecurity

    Sign in to save and rate

  3. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read4 days ago

    Infrastructure

    Sign in to save and rate

  4. Why Shopify Migrated From React Native

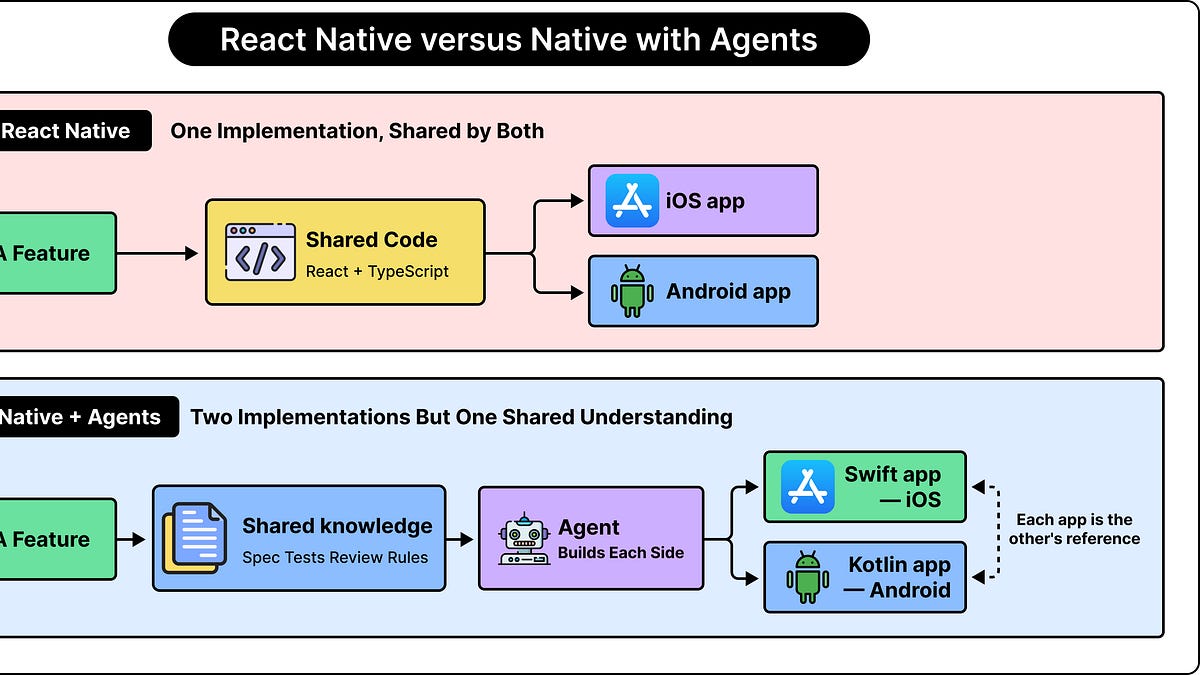
    Shopify migrated its mobile applications from React Native to native Swift and Kotlin because AI coding agents made the cost of duplicating features across platforms negligible. Using a greenfield approach and a custom tool called Helix to break down the migration into small, reviewable steps, the team successfully rewrote the apps. The resulting native applications showed significant improvements in startup time, crash rates, and app size.

    DEPTH ■■■■■11 min read5 days ago

    Sign in to save and rate

  5. Bringing post-quantum cryptography to geographically fenced key management

    Cloudflare introduced a post-quantum geographically restricted key manager in closed beta to enforce data sovereignty and protect customers against harvest-now-decrypt-later attacks. The team implemented a hybrid ML-KEM-768 and X25519 cryptographic design that separates globally distributed wrapped private keys from regionally restricted root keys. This ensures that decryption keys are only accessible within authorized geographical boundaries and fails closed if validation fails.

    DEPTH ■■■■■12 min read2 days ago

    Security

    Sign in to save and rate

  6. MCP standardized tools. Now we need the infrastructure around them.

    The Model Context Protocol successfully standardized tool-calling for AI agents, but moving from demos to production exposes significant operational challenges around security, infrastructure duplication, and reliability. Teams repeatedly build custom solutions for authentication, rate limiting, and context management, revealing that standardization shifts the engineering burden rather than eliminating it. Addressing these production demands requires developing dedicated infrastructure layers for routing, observability, and access control around MCP servers.

    DEPTH ■■■■■8 min read10 days ago

    Machine Learning

    Sign in to save and rate

  7. How Uber Built a Genie to Answer Questions Correctly

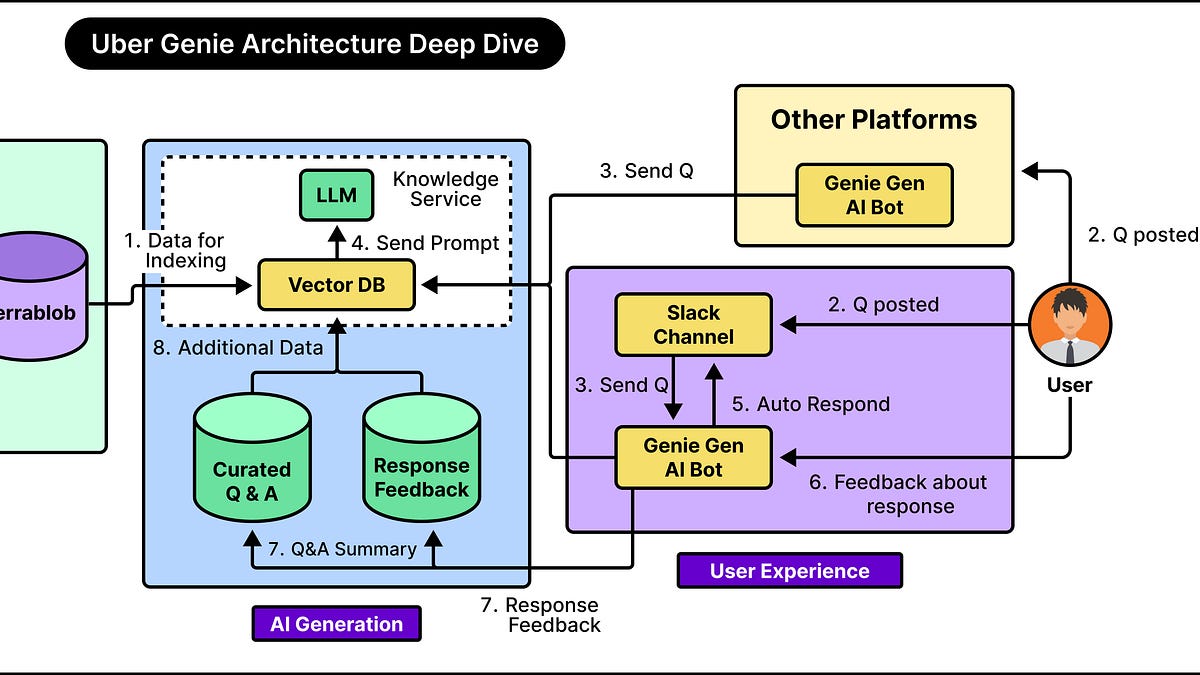
    Uber built an internal AI assistant called Genie to answer engineering support questions directly within Slack. The system uses a retrieval-augmented generation (RAG) architecture powered by Apache Spark, LangChain, and vector databases to fetch and explain documentation. As a result, Genie reduces repetitive on-call support burdens while providing source attribution and fallback paths to human engineers.

    DEPTH ■■■■■13 min read6 days ago

    Sign in to save and rate

  8. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read11 days ago

    Microservices

    Sign in to save and rate

  9. Cutting our inference bill by 68% by being obsessive about optimization

    An engineering team investigated a steady rise in AI code review costs and found that cache misses and redundant model calls were driving up expenses. By restructuring system prompts to enable cross-repository prompt caching, eliminating wasted tool calls, and switching to more efficient models, the team cut inference costs by 68% while also significantly improving review latency.

    DEPTH ■■■■■15 min read6 days ago

    Machine Learning

    Sign in to save and rate

  10. Make every AI credit count: See, cap, and reduce agent spend

    Uncontrolled AI agent spending can be mitigated by combining open-weight models, centralized context graphs to reduce retries, and usage analytics with credit caps. GitLab introduced these capabilities in its Duo Agent Platform to help platform teams trace, limit, and optimize AI credit consumption. The resulting architecture matches specific tasks to lower-cost models while maintaining task completion quality.

    DEPTH ■■■■■6 min read12 days ago

    Sign in to save and rate

  11. Part 5: Operating an LLM system: observability, cost, routing, and the platform underneath

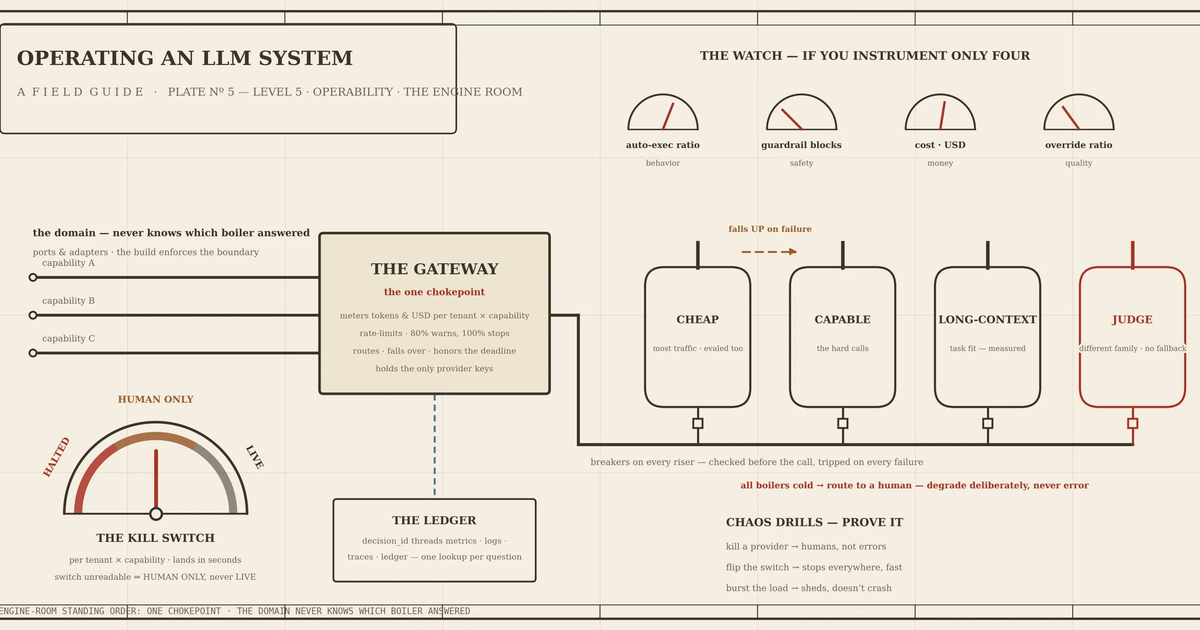
    This post provides a concrete specification for the operability layer of production LLM systems, covering observability signals, structured logging, cost controls, routing, and failover mechanisms. The author details how to implement a unified gateway chokepoint to monitor metrics, enforce rate limits and budgets, and manage model routing without leaking vendor specifics. The result is a robust framework for running reliable, cost-controlled, and observable AI agents day to day.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  12. LLM Prompt Caching Versus Semantic Caching

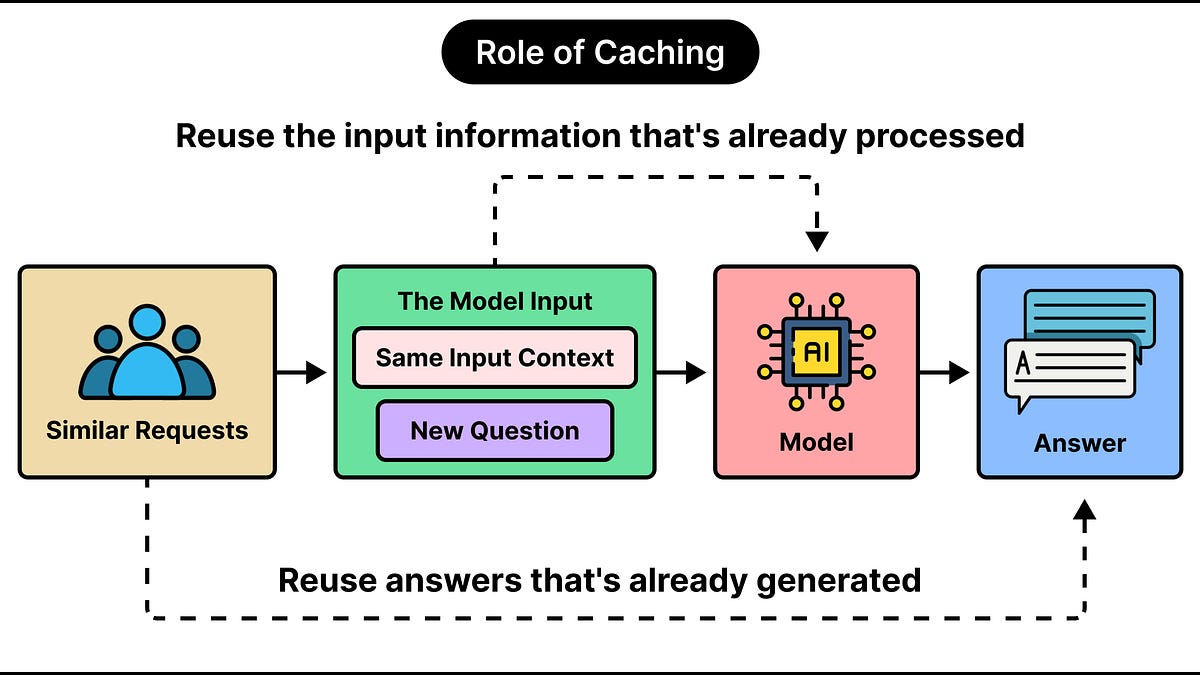
    This post compares prompt caching and semantic caching for large language models to reduce costs and latency. Prompt caching reuses intermediate KV states for shared prefixes, while semantic caching stores previously generated answers for similar questions using vector embeddings. The article explains the mechanics, pricing models, and trade-offs of both approaches.

    DEPTH ■■■■■16 min read4 days ago

    Sign in to save and rate

  13. Yandex outage: Data shows that instead of going dark, malicious bots went on the move

    Following physical strikes on Yandex data centers, overall HTTP traffic from the network dropped significantly, leading to speculation that malicious bot farms had been disabled. However, traffic analysis revealed that search crawling simply decreased while malicious automation quickly migrated to other hosting providers with identical fingerprints. Consequently, overall malicious bot traffic remained flat, demonstrating that network disruptions do not stop portable automated workloads.

    DEPTH ■■■■■8 min read11 days ago

    Incidents & Postmortems

    Sign in to save and rate

  14. Part 4: Safety and governance for LLM systems: guardrails, PII, audit, and memory

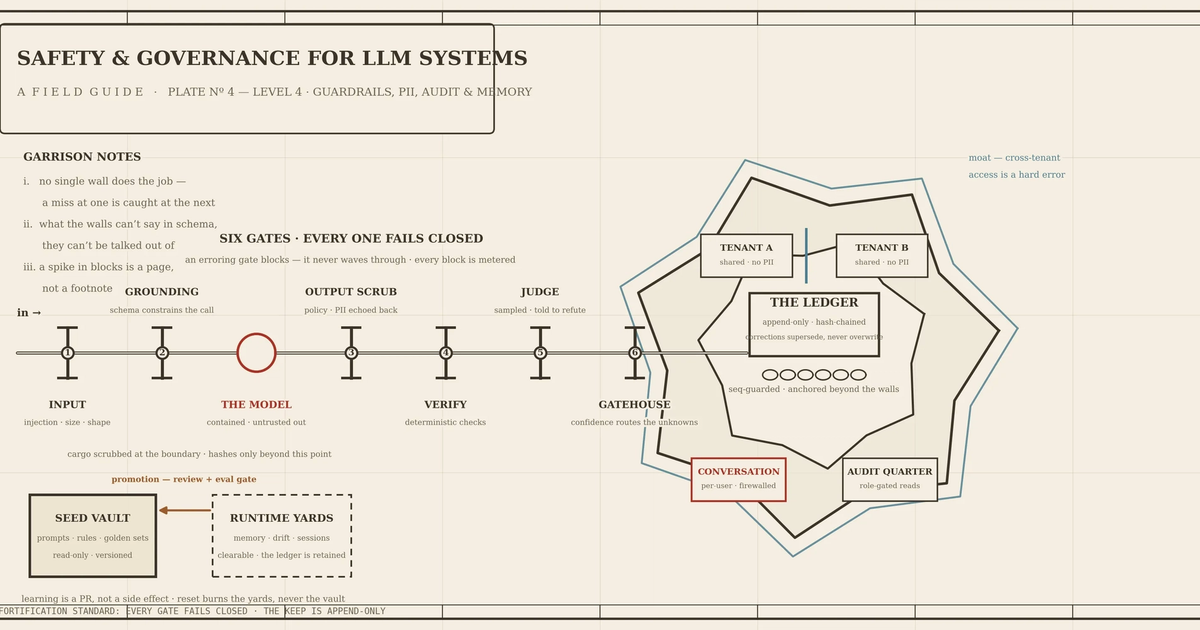
    This post details safety and governance practices for LLM systems, focusing on layered guardrails, boundary-level PII handling, and immutable audit trails. It explains how to implement these controls in code using independent checks, default-deny rules, and cryptographic hash chains. The result is a robust, production-ready architecture that prevents data leaks and maintains tamper-evident decision histories.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  15. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

  16. Part 3: Knowing when your agent doesn’t know: the confidence layer

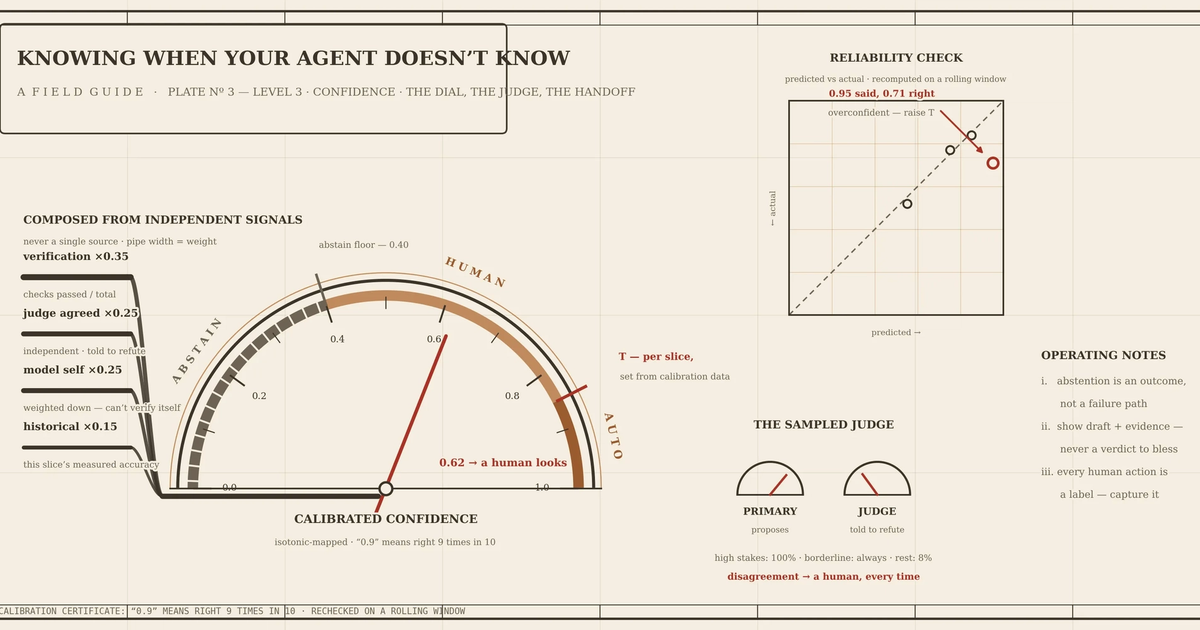
    This post outlines a maturity model for LLM systems centered around a confidence layer, which combines independent signals like verification, historical accuracy, and adversarial model judges to determine when an agent can act autonomously. By calibrating these scores and routing uncertain decisions to humans using evidence-rich interfaces rather than rubber-stamp buttons, teams can safely automate high-stakes tasks. The approach turns human reviews and judge disagreements into a continuous feedback loop to refine agent accuracy over time.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  17. Inside Hyperdrive: How we solved a rare Hyperdrive MySQL caching bug

    During the beta of MySQL support for Hyperdrive, engineers investigated rare empty query responses and connection hangs occurring in 0.001% of requests. They discovered that sharing the data center cache between client and endpoint nodes caused protocol capability mismatches when translating MySQL wire messages. The team resolved the issue by standardizing the cache to always store responses encoded with canonical Hyperdrive capabilities.

    DEPTH ■■■■■9 min read11 days ago

    MySQL

    Sign in to save and rate

  18. How Netflix Taught an LLM to Recommend Movies So That You Keep Watching

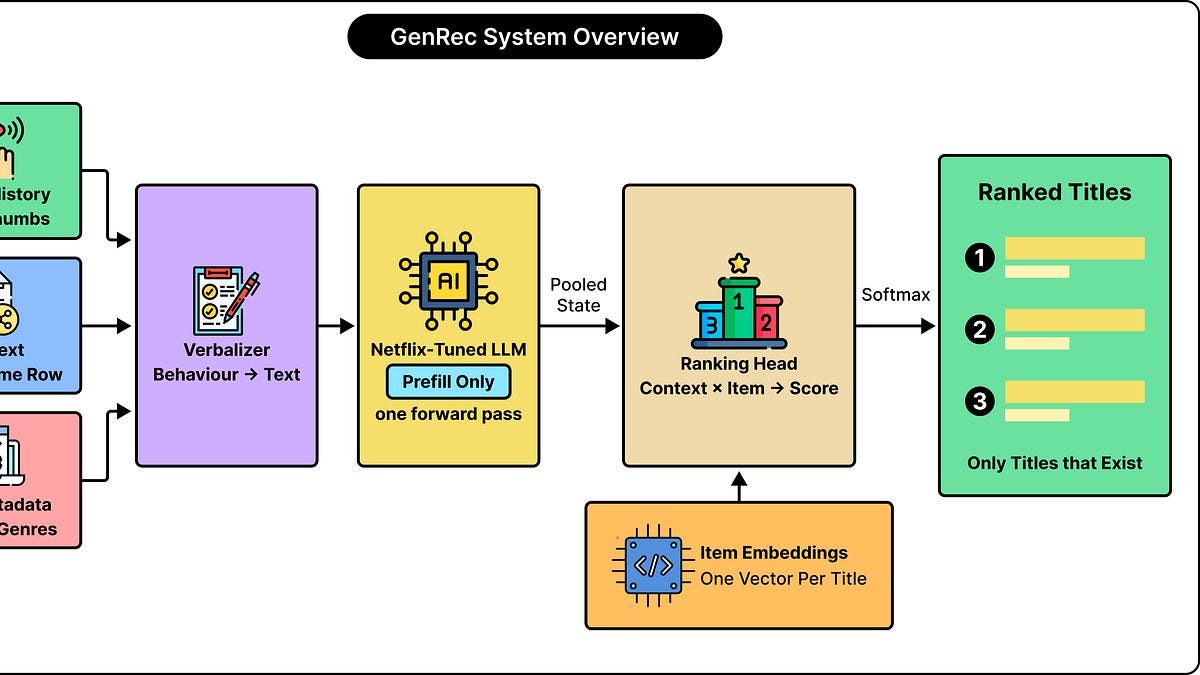
    Netflix developed GenRec, an LLM-based recommendation ranker designed to interpret viewing histories and item metadata in plain text to score movies and TV shows. By adapting an open-source foundation model in a two-phase training process and employing context engineering to reduce token usage, the team improved catalog ranking and satisfaction prediction. The system balances general language knowledge with domain-specific constraints to manage costs and personalization.

    DEPTH ■■■■■15 min read2 weeks ago

    Sign in to save and rate

  19. Staying Evergreen: How we automated secure access and repo hygiene in a shared org

    Manual repository housekeeping and access reviews for outside collaborators become difficult to maintain as organizations scale. The team built Evergreen, a GitHub App that automates quarterly access reviews and stale repository archiving using native platform features and IssueOps. This automation successfully enforces secure defaults by revoking unanswered access while maintaining a full audit trail in git history.

    DEPTH ■■■■■8 min read10 days ago

    Sign in to save and rate

  20. Part 2: Evals as a deployment gate — and how to know when they drift

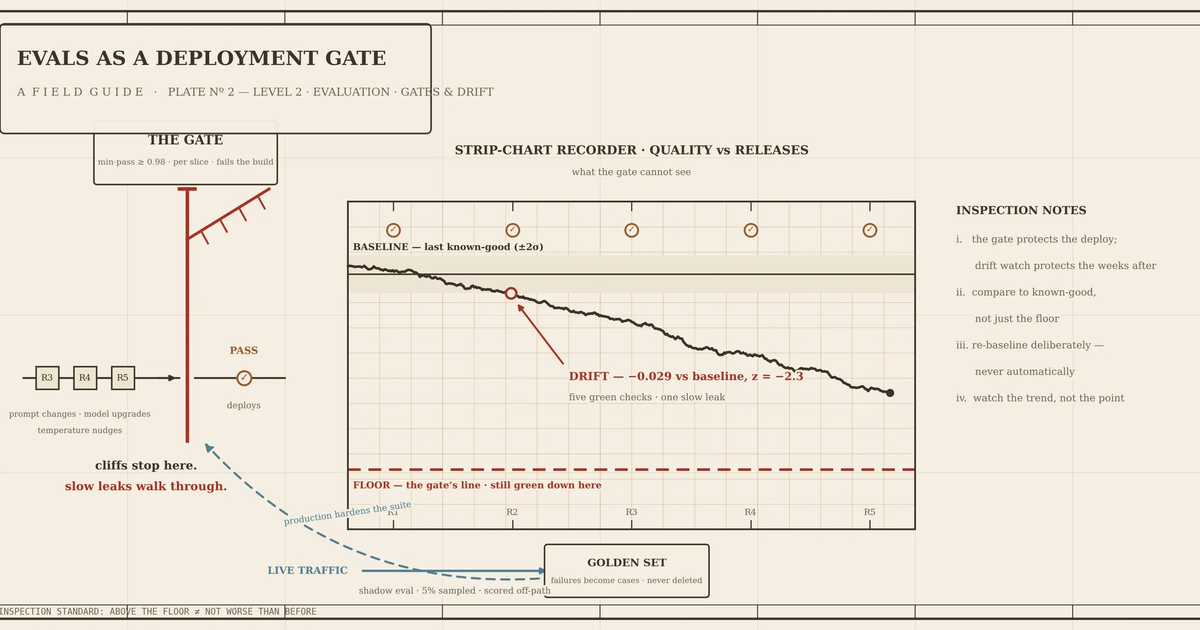
    This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.

    DEPTH ■■■■■8 min read2 weeks ago

    Machine Learning

    Sign in to save and rate