/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read6 days ago
    Infrastructure

    Sign in to save and rate

  2. The Thin Orchestrator: How We Made Our AI Agents More Reliable by Giving the Router Less to Do

    Meta engineers reduced hallucinations and improved reliability in their data pipeline agents by replacing a single heavyweight LLM orchestrator with a thin deterministic router and fourteen specialized subagents. The thin orchestrator handles routing and reliability checks through a fixed protocol, while isolated subagents execute domain reasoning. This architecture reduced configuration preparation time from a day to under an hour.

    DEPTH ■■■■■7 min read8 days ago

    Machine Learning

    Sign in to save and rate

  3. Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster

    Meta built Prometheus, a gigawatt-scale AI supercluster designed to scale up to one million GPUs using multi-generation NVIDIA hardware and specialized backend Ethernet networks. The team achieved high goodput and significantly reduced system interruptions by implementing an in-rack sparing strategy, parallelism-aware fault tolerance, and close co-engineering with vendors. These infrastructure advancements allowed the team to successfully train frontier foundational models like Muse Wonder.

    DEPTH ■■■■■17 min read8 days ago

    InfrastructureMachine Learning

    Sign in to save and rate

  4. Sentry JavaScript SDK v11 adds tracing for all JS platforms

    Sentry replaced its OpenTelemetry-based JavaScript SDK instrumentation with a source-code transformation approach using diagnostics channels in version 11. This change removes reliance on Node-specific module loader hooks, enabling reliable tracing across non-Node runtimes like Deno, Bun, and Cloudflare Workers, while also supporting bundled applications. The result is a simplified architecture that reduces bundle weight and fixes previous limitations with load order and immutable exports.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate

  5. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read12 days ago

    Microservices

    Sign in to save and rate

  6. The Shift to cgroup v2 in Kubernetes: What You Need to Know

    Kubernetes has deprecated cgroup v1 in favor of cgroup v2, with complete removal scheduled for future releases. The transition requires migrating Linux nodes, updating container runtimes, and verifying kernel compatibility. Adopting cgroup v2 enables advanced features such as Memory QoS, improved OOM handling, and pressure stall information metrics.

    DEPTH ■■■■■12 min read2 weeks ago

    Sign in to save and rate

  7. How Meta Built Forum With AI-Native Engineering

    Meta engineers built the Forum app using a human-on-the-loop AI agent workflow that automated planning, building, testing, and verification. By shifting focus from code generation to automated verification, tooling improvements, and architectural legibility, the team reached feature parity in eight weeks while catching systemic memory issues early.

    DEPTH ■■■■■8 min read11 days ago

    FrontendMobile

    Sign in to save and rate

  8. Reducing Android scope-sync overhead in Sentry Flutter

    The Sentry Flutter team investigated scope-sync overhead on Android and found redundant data normalization across isolates alongside unnecessary buffer copies during JSON encoding. By removing the duplicate normalization and encoding directly to UTF-8 bytes, the team reduced processing time by 27 to 30 percent across benchmarked payloads.

    DEPTH ■■■■■4 min read2 weeks ago

    Sign in to save and rate

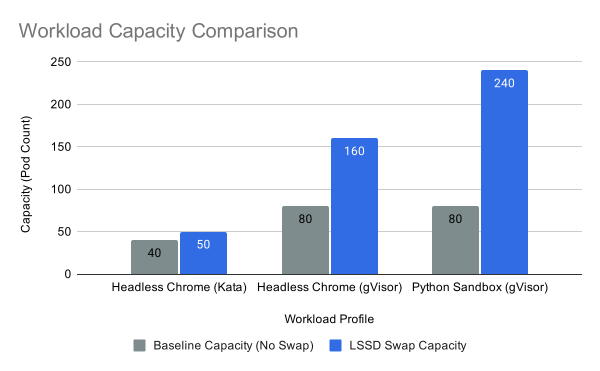
  9. Scaling Kubernetes Workloads with Node Swap

    Kubernetes memory limits often cap node density for bursty agentic AI workloads that sit idle with large memory footprints. To solve this, the engineering team benchmarked Kubernetes v1.34 node swap backed by fast NVMe Local SSDs across CI/CD builds, headless browsers, and Python sandboxes. The approach successfully increased pod density up to three times without significant latency costs.

    DEPTH ■■■■■6 min read3 weeks ago

    Sign in to save and rate

  10. Meta’s Generative Ads Model (GEM): Scaling the Central Model and Compute Engine for Frontier Ads AI

    Meta developed GEM, a unified recommendation foundation model using an LLM-style architecture called Kunlun to handle heterogeneous ads data across multiple surfaces. The team implemented block attention, custom low-precision kernels, and post-training intelligence transfer techniques like LoopFM and Solaris to scale training efficiency and bypass real-time serving latency bottlenecks. The resulting system delivered an 18.9% conversion improvement and a 12% click-through rate increase across Meta ads surfaces.

    DEPTH ■■■■■15 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  11. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

  12. The Sentry Android SDK is now 20-30% faster!

    The Sentry team optimized the Android SDK to reduce initialization time by 20-30% and background CPU usage by up to 10%. Improvements were achieved by profiling with Perfetto, replacing slow runtime manifest parsing and DSN parsing with build-time bytecode writing and lightweight parsers, and reusing thread pools. Upgrading to the latest SDK version allows applications to realize these startup performance gains.

    DEPTH ■■■■■4 min read7 days ago

    Sign in to save and rate

  13. OCP Summit 2026: Powering AI with Open Innovations in Scale-Up, Scale-Out, and Scale-Across Networks

    Meta shared its next-generation open networking infrastructure for AI at the OCP Summit 2026, including liquid-cooled 102.4T switch platforms, multiplane scale-out fabrics, and Ethernet-based scale-up solutions. The team also highlighted collaborative industry standards like ESUN and OSPA to unify hardware and transport layers. These open innovations aim to support massive gigawatt-scale AI clusters across diverse data center environments.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

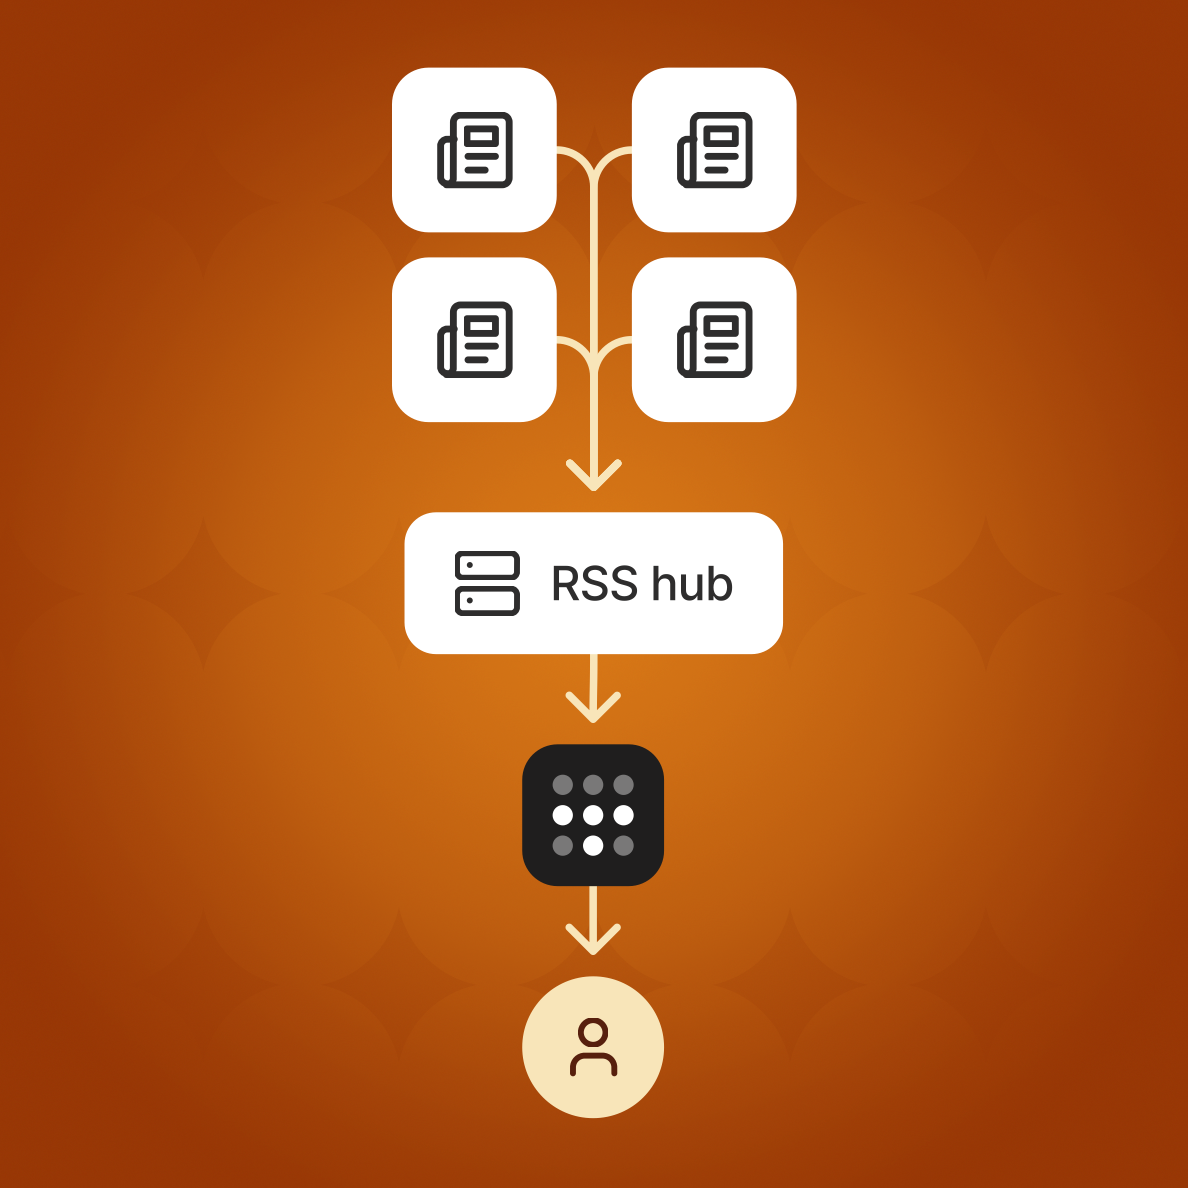
  14. It's time to make your own RSS reader

    This post walks through the process of self-hosting a personal RSS reader using FreshRSS and Docker, secured privately over a Tailscale network. The author details the configuration of environment variables, auth keys, and Docker compose deployment to avoid exposing the service to the open web. The result is a private, algorithm-free news reader accessible across multiple devices and integrable with external reading apps or AI agents.

    DEPTH ■■■■■10 min read11 days ago

    Sign in to save and rate

  15. Staying Evergreen: How we automated secure access and repo hygiene in a shared org

    Manual repository housekeeping and access reviews for outside collaborators become difficult to maintain as organizations scale. The team built Evergreen, a GitHub App that automates quarterly access reviews and stale repository archiving using native platform features and IssueOps. This automation successfully enforces secure defaults by revoking unanswered access while maintaining a full audit trail in git history.

    DEPTH ■■■■■8 min read11 days ago

    Sign in to save and rate

  16. Unreal MCP now speaks Sentry

    The Sentry team integrated their crash reporting plugin with Unreal Engine's new experimental Model Context Protocol (MCP) server, allowing coding agents to fully automate setup and debugging. By combining editor tools and Sentry MCP, an agent successfully configured the SDK, uploaded debug symbols, packaged a build, induced a crash, and traced the root cause without manual file editing. The integration streamlines crash reporting setup, though it currently suffers from occasional agent tool-discovery issues and server fragility across editor restarts.

    DEPTH ■■■■■7 min read3 weeks ago

    Sign in to save and rate

  17. GenRecs Tokenization: Transforming Ads Recommendation at Meta with Stable Model Vocabulary

    Meta implemented GenRecs Tokenization to replace dedicated item IDs with a stable semantic vocabulary for ads recommendation. Using a three-stage encoding and quantization pipeline, the system enables language models to reason about ad content and user preferences simultaneously. This approach resulted in a +0.35% lift in conversions and improved cold-start performance for new entities.

    DEPTH ■■■■■6 min read8 days ago

    Machine Learning

    Sign in to save and rate

  18. Why Is My Kubernetes Job Still Pending? Tracing Kueue Admission with Headlamp

    Kubernetes jobs managed by Kueue can remain pending while waiting for admission checks and resource allocation. The team implemented a Kueue plugin for Headlamp to trace pending workloads through local queues, cluster queues, and resource flavors within a unified interface. This approach allows engineers to quickly determine whether a job is blocked by admission policies or standard pod scheduling.

    DEPTH ■■■■■9 min read12 days ago

    Sign in to save and rate

  19. Improving site performance by shipping more CSS

    GitHub faced performance degradation on server-side rendering and initial page loads due to scaling issues with its CSS-in-JS solution. The engineering team executed a multi-year migration to CSS Modules and eliminated dynamic styling props using incremental rollouts, wrapper components, and automation tools. This resulted in significant performance gains, including 55% faster server-side rendering and the complete removal of styled-components.

    DEPTH ■■■■■8 min read4 weeks ago

    FrontendPerformance

    Sign in to save and rate

  20. Should you use a log or a metric?

    This post explains the distinction between logs and metrics in application monitoring, noting that logs capture what was true during specific events for debugging while metrics track ongoing numerical trends over time. The author demonstrates how to implement both using Sentry SDKs during a user signup flow and outlines criteria for choosing between them. The resulting takeaway helps engineers decide whether to log an event or track it as a metric based on the questions they need to answer.

    DEPTH ■■■■■12 min read5 days ago

    Sign in to save and rate