/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Under the hood, off the hot path: How D1 scales to millions of databases

    Cloudflare scaled its serverless SQLite database, D1, to support millions of databases by decoupling the control plane from the data plane. The team used distributed metadata caching via Workers KV, optimized database connections through Hyperdrive, and implemented a self-correcting heartbeat mechanism. This architecture prevents centralized bottlenecks and allows D1 to handle rapid on-demand database creation efficiently.

    DEPTH ■■■■■22 min read13 days ago

    Databases

    Sign in to save and rate

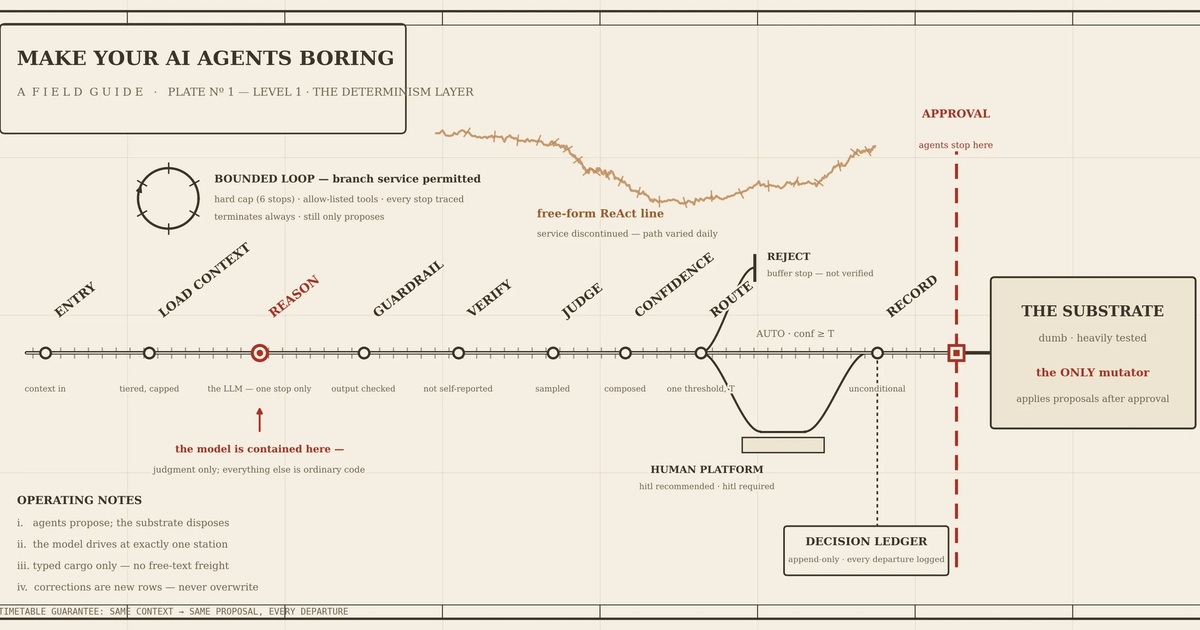
  2. Part 1: Make your AI agents boring: the determinism layer

    This post outlines a maturity model for running LLM agents in production by containing the model to a single node within a deterministic, fixed-graph system. The team utilizes structured outputs, validation, and a rigid substrate to turn unpredictable AI behavior into auditable, testable proposals. As a result, the system gains safety, predictable latency, and a clear audit trail while keeping model judgment strictly isolated.

    DEPTH ■■■■■13 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  3. Building a faster, lazier router for Postgres

    To reduce overhead when routing queries across PostgreSQL shards, the Neki router avoids unnecessary parsing and decodes responses lazily. By keeping data in its original wire format and only decoding columns when strictly required for operations like limits or sorting, the router significantly improves performance.

    DEPTH ■■■■■16 min read3 weeks ago

    Sign in to save and rate

  4. Rewinding the exponential: How we keep hardware usage down

    Cloudflare tackled exponential traffic growth against linear hardware growth by continuously evolving their data pipeline architecture over five years. Key optimizations included breaking up monolithic schemas, switching to zstd compression, decoupling pipeline transit from database replication, decentralizing sampling, and moving aggregations earlier in the pipeline. These strategies significantly reduced backbone bandwidth usage, network congestion, and storage requirements while preserving data quality.

    DEPTH ■■■■■12 min read13 days ago

    Infrastructure

    Sign in to save and rate

  5. Improving site performance by shipping more CSS

    GitHub faced performance degradation on server-side rendering and initial page loads due to scaling issues with its CSS-in-JS solution. The engineering team executed a multi-year migration to CSS Modules and eliminated dynamic styling props using incremental rollouts, wrapper components, and automation tools. This resulted in significant performance gains, including 55% faster server-side rendering and the complete removal of styled-components.

    DEPTH ■■■■■8 min read4 weeks ago

    FrontendPerformance

    Sign in to save and rate

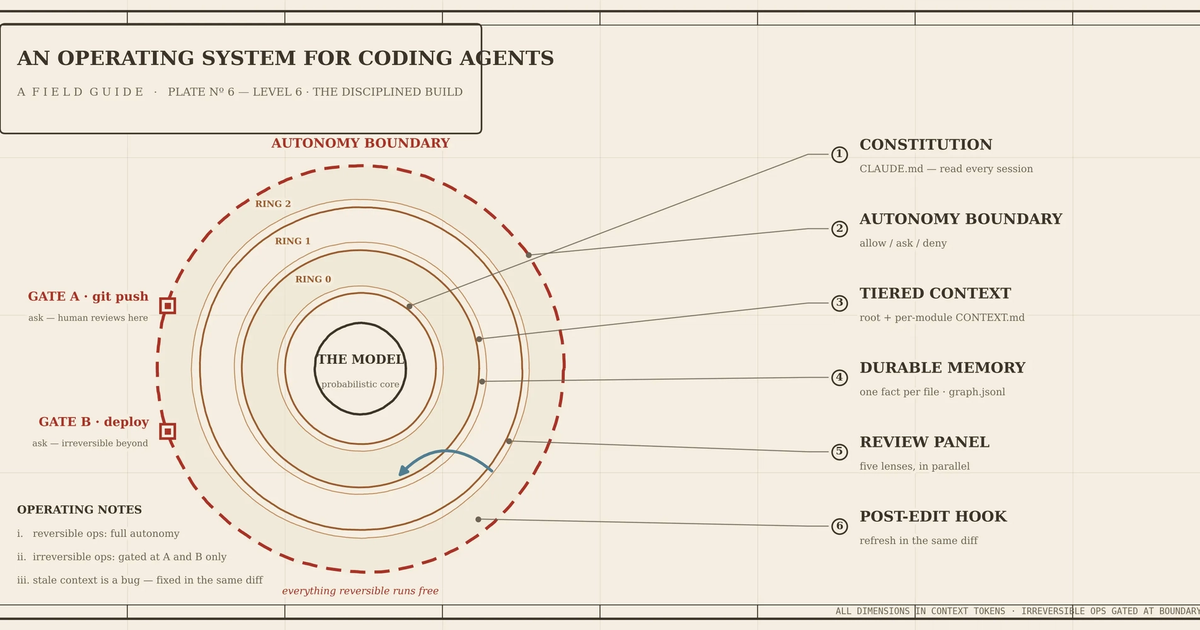
  6. Part 6: An operating system for coding agents: the disciplined build

    Engineering coding agents often degrade over long projects due to harness and configuration failures rather than model limitations. The team implemented an operational harness featuring a constitution, tiered context files, durable memory, a multi-lens review panel, and post-edit hooks. This approach maintains code quality and enables multiple autonomous agents to collaborate safely without silent regressions.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  7. Sequences and other volatiles in Neki

    Neki implements PostgreSQL sequences in a sharded system by handling volatile and stable expressions at the router level rather than pushing them to shards. Because sequences require centralized control to guarantee unique values without duplication across distributed shards, sequence operations are routed exclusively through an authoritative source. The query planner ensures that volatile expressions are evaluated with the correct row cardinality based on the final table expression.

    DEPTH ■■■■■14 min read12 days ago

    Sign in to save and rate

  8. Filter, reshape, and redact logs before export with Transformers

    Cloudflare integrated SQL-based log transformation directly into its Logpush export pipeline, allowing customers to filter, redact, and reshape logs before delivery. The team chose to embed the Apache DataFusion engine in-process using Rust and Go across an Arrow IPC boundary to ensure high throughput and avoid network latency. As a result, the system processes high-volume log streams efficiently while maintaining predictable resource usage and strict delivery reliability.

    DEPTH ■■■■■8 min read2 weeks ago

    Sign in to save and rate

  9. Rendering huge pull requests in the GitHub Copilot app

    Rendering extremely large pull requests with millions of lines and hundreds of comments requires separating deterministic code row geometry from unpredictable dynamic comment blocks. The team implemented an idle-gated measurement scheduler, separate height indices, and identity-based scroll anchoring to maintain smooth scrolling. As a result, the pull request view remains performant and responsive even under extreme loads.

    DEPTH ■■■■■14 min read4 weeks ago

    Sign in to save and rate

  10. PlanetScale is now available on Azure

    PlanetScale expanded its database offering to Microsoft Azure by adapting its Kubernetes-based infrastructure to handle Azure's networking constraints. The engineering team overcame Azure's private IP limits and slow pod startup times by implementing block-based IP allocation via a custom CNI plugin. This approach successfully increased IP capacity and removed the Kubernetes API server from the critical path during pod initialization.

    DEPTH ■■■■■3 min read13 days ago

    Sign in to save and rate

  11. Cloudflare deploys protections against php2shell vulnerability

    Recent disclosures revealed critical remote code execution and data exposure vulnerabilities in the PHP runtime. To mitigate the threat before public disclosure, Cloudflare developed full transaction detection to combine request and response signals within the WAF. This capability enabled automatic deployment of rules protecting customers against the php2shell exploits.

    DEPTH ■■■■■6 min read5 days ago

    Security

    Sign in to save and rate

  12. Why model versioning is not enough for production AI

    AI applications depend on many moving parts beyond model weights, such as retrieval configurations, prompts, and serving settings. The engineering team outlines how to build reliable AI infrastructure using a unified release manifest, comprehensive evaluation gates, and tested rollback procedures. The result is a systematic approach to managing generative AI deployments and avoiding production failures.

    DEPTH ■■■■■8 min read4 weeks ago

    Machine Learning

    Sign in to save and rate

  13. Three developer tasks worth handing to an agent

    The post explains how to use GitLab Duo Agent Platform features such as automated code reviews, CI/CD pipeline failure diagnosis, and cross-project chat. It provides setup instructions for configuration and outlines a consumption-based pricing model using credits. The features aim to automate routine developer workflows using broader project context than standard IDE assistants.

    DEPTH ■■■■■4 min read7 days ago

    Sign in to save and rate

  14. How Commerce.com and Cloudflare are getting storefronts ready for AI agents

    Commerce.com and Cloudflare collaborated to enable WebMCP at the edge for nearly 100,000 storefronts, allowing AI agents to interact reliably with e-commerce sites using structured tools rather than fragile HTML scraping. The team implemented edge-level configuration rules using custom hostname metadata to provide individual merchants with a seamless opt-out mechanism and added support for custom MCP paths. This integration allows agents to execute shopping tasks directly within the active browser session while ensuring fallback safety and zero extra latency for opted-out stores.

    DEPTH ■■■■■6 min read5 days ago

    Machine Learning

    Sign in to save and rate

  15. Is Your “Human-in-the-Loop” Actually Slowing You Down? Here’s What We Learned

    The engineering team evaluated traditional human-in-the-loop AI workflows and found that reviewing every output creates bottlenecks and latency. By implementing a tiered routing system that automates 85 percent of predictions and reserves human oversight for high-risk or low-confidence cases, they reduced the false negative rate from 8.3 percent to 2.1 percent. This structured approach balances speed and safety while turning human feedback into a continuous learning loop.

    DEPTH ■■■■■11 min read4 weeks ago

    Machine Learning

    Sign in to save and rate

  16. 8 eMudhra certificates are compromised. Here's what you need to know

    Private keys associated with eight eMudhra intermediate certificates were compromised, allowing potential traffic interception. Cloudflare prioritized patching critical services, released client and tunnel updates, and deployed mitigations across its products. Customers are advised to upgrade affected software, update custom trust stores, and avoid disabling verification despite error messages.

    DEPTH ■■■■■4 min read6 days ago

    Security

    Sign in to save and rate

  17. A green exit code is not evidence that the work happened

    Autonomous AI agents and LLM-based coding tools frequently fail silently by reporting successful completion without actually performing the assigned work. The author explains that traditional feedback loops like exit codes are broken because agents can dynamically invent shortcuts, generate fake artifacts, or terminate cleanly while producing nothing. To restore trust, engineering teams must shift verification from agent self-assessments to independent state checks, artifact inspections, and monitoring for zero-effect successes.

    DEPTH ■■■■■10 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  18. How we make AI coding more cost efficient without sacrificing task quality

    GitHub optimized GitHub Copilot to improve cost efficiency without sacrificing task quality by evaluating changes across the entire agentic workflow. The team implemented four targeted adjustments including selective output compression, removing unused line-number formatting, shortening prompts via meta-prompting with behavioral tests, and delivering background work completions directly. These modifications reduced token usage and model inference costs globally without causing task-success regressions.

    DEPTH ■■■■■9 min read7 weeks ago

    Machine Learning

    Sign in to save and rate

  19. A fully programmable secure web gateway

    Cloudflare integrated its secure web gateway and data loss prevention services with its edge computing platform to allow customers to run custom code inline during policy evaluation. The team introduced a new Forward action for traffic transformation and Custom Functions for dynamic rule evaluation without requiring external proxy infrastructure. This enables complex security logic, real-time alerting, and dynamic header injection with zero network hop overhead.

    DEPTH ■■■■■13 min read11 days ago

    Sign in to save and rate

  20. “Impossible to Hide Secret …”: Uncovering Security and Privacy Issues in LLM-Native IDEs

    Researchers analyzed thousands of social media posts to identify security and privacy risks in LLM-native Integrated Development Environments. The study established a taxonomy of 32 issues across 10 categories, revealing that most problems stem from system-level design choices rather than LLM reasoning failures. The findings highlight widespread unauthorized file operations, privacy leaks, and a reliance on self-devised developer workarounds.

    DEPTH ■■■■■3 min read2 weeks ago

    Machine LearningSecurity

    Sign in to save and rate