21ByteByteGo · architecture
LLM Prompt Caching Versus Semantic Caching
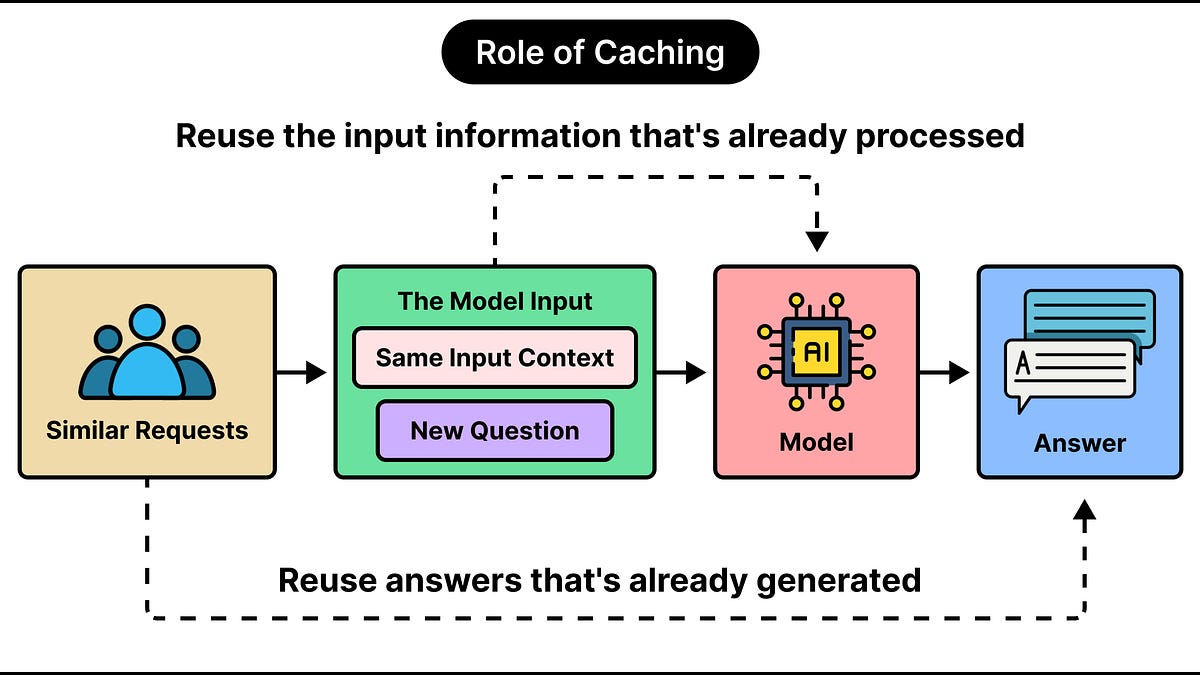
This post compares prompt caching and semantic caching for large language models to reduce costs and latency. Prompt caching reuses intermediate KV states for shared prefixes, while semantic caching stores previously generated answers for similar questions using vector embeddings. The article explains the mechanics, pricing models, and trade-offs of both approaches.
DEPTH ■■■■■16 min read5 days ago