/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Running multi-day AZ evacuation drills with ARC Zonal Shift

    This post explains how to run multi-day Availability Zone evacuation drills using ARC Zonal Shift to prove application resilience under sustained stress. The team details step-by-step procedures across ECS, EKS, and PostgreSQL databases to uncover hidden failure modes like unoptimized scaling and stale connections. The result is a practical framework for moving from theoretical multi-AZ architectures to proven operational resilience.

    DEPTH ■■■■■19 min read3 weeks ago
    Sign in to save and rate

  2. “Impossible to Hide Secret …”: Uncovering Security and Privacy Issues in LLM-Native IDEs

    Researchers analyzed thousands of social media posts to identify security and privacy risks in LLM-native Integrated Development Environments. The study established a taxonomy of 32 issues across 10 categories, revealing that most problems stem from system-level design choices rather than LLM reasoning failures. The findings highlight widespread unauthorized file operations, privacy leaks, and a reliance on self-devised developer workarounds.

    DEPTH ■■■■■3 min read2 weeks ago

    Machine LearningSecurity

    Sign in to save and rate

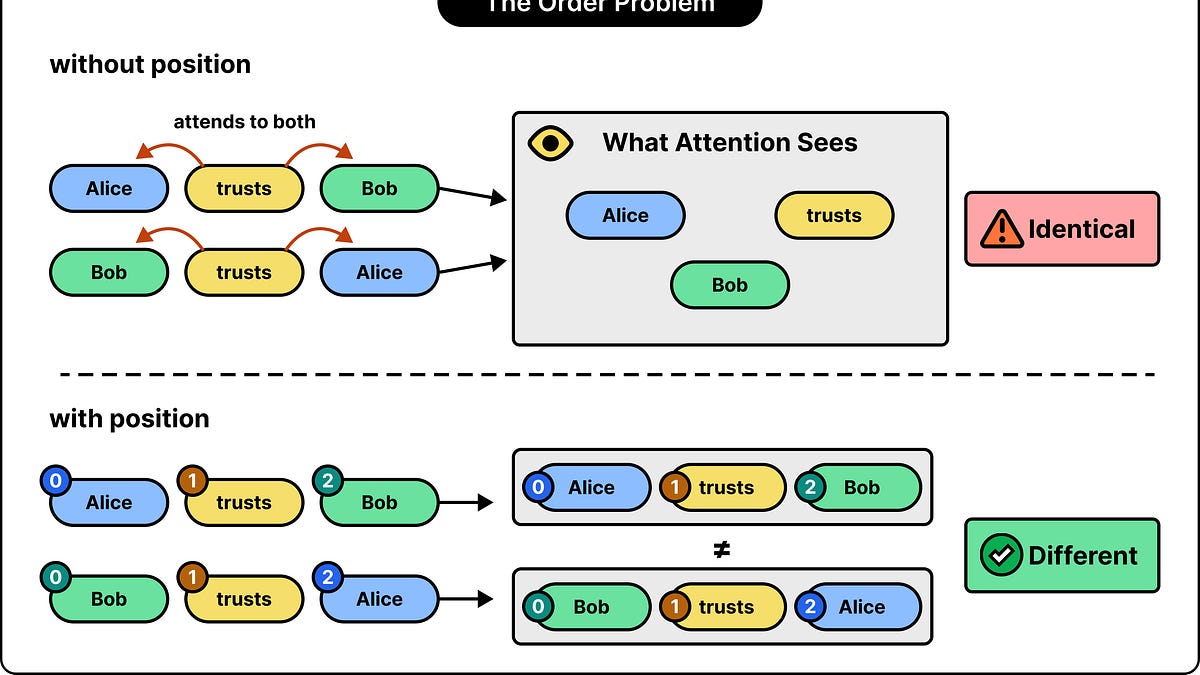
  3. How the Math Used in 19th-Century Heat Physics Helps LLMs Understand Sentences

    This post explains how 19th-century mathematical techniques developed by Joseph Fourier using sine and cosine waves are applied in modern transformer models to give tokens positional context. The author demonstrates how word order dictates semantic meaning and how multi-speed rotational patterns provide bounded, scalable positional encodings. Ultimately, this mathematical structure helps attention mechanisms account for relative token distances during training.

    DEPTH ■■■■■13 min read13 days ago

    Sign in to save and rate

  4. How MHK built a HIPAA-eligible agentic AI solution on Amazon Bedrock

    Healthcare technology company MHK faced fragmented AI infrastructure and lengthy development cycles while trying to process unstructured medical documents under strict HIPAA standards. To solve this, they built a multi-tenant, event-driven agentic workflow framework called the SmartProminence AI Orchestrator on AWS using Amazon Bedrock, ECS, and SQS. The new system reduced manual review effort by 90% and shortened AI feature deployment times from months to weeks.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

  5. The Regression Tests Nobody Writes: Capturing How Software Actually Behaves

    Standard regression tests usually only verify developer intent rather than the actual, unwritten behaviors that systems accumulate in production over time. By capturing real production traffic and network-level interactions, teams can build characterization test suites to automatically detect unintended behavioral shifts. This approach prevents accidental regressions during legacy refactoring, rewrites, and major framework upgrades.

    DEPTH ■■■■■6 min read3 days ago

    Testing

    Sign in to save and rate

  6. Build adaptive AI interfaces with the AG-UI protocol, agent swarms, and Nova Act on AWS

    AI applications produce variable outputs that cannot be effectively handled by static user interfaces, leading to development friction and poor user experiences. The team implemented an adaptive interface pattern using the AG-UI protocol, the Strands Agents SDK Swarm pattern, and Amazon Nova Act on AWS to dynamically render components and automate legacy integrations. This architecture streams agent findings over Server-Sent Events, enabling real-time multi-agent consensus and reducing interface development overhead.

    DEPTH ■■■■■22 min read3 weeks ago

    Sign in to save and rate

  7. Survey Says: You'll swap the model, but everything you build around it is staying put

    Stacklok surveyed technical leaders to understand enterprise AI adoption and vendor lock-in concerns. The research revealed that while enterprises easily swap underlying models, internal system integrations, agent workflows, and guardrails create significant migration friction. Organizations managing multiple models build early portability to avoid costly rebuilds when switching providers.

    DEPTH ■■■■■4 min read5 days ago

    Machine Learning

    Sign in to save and rate

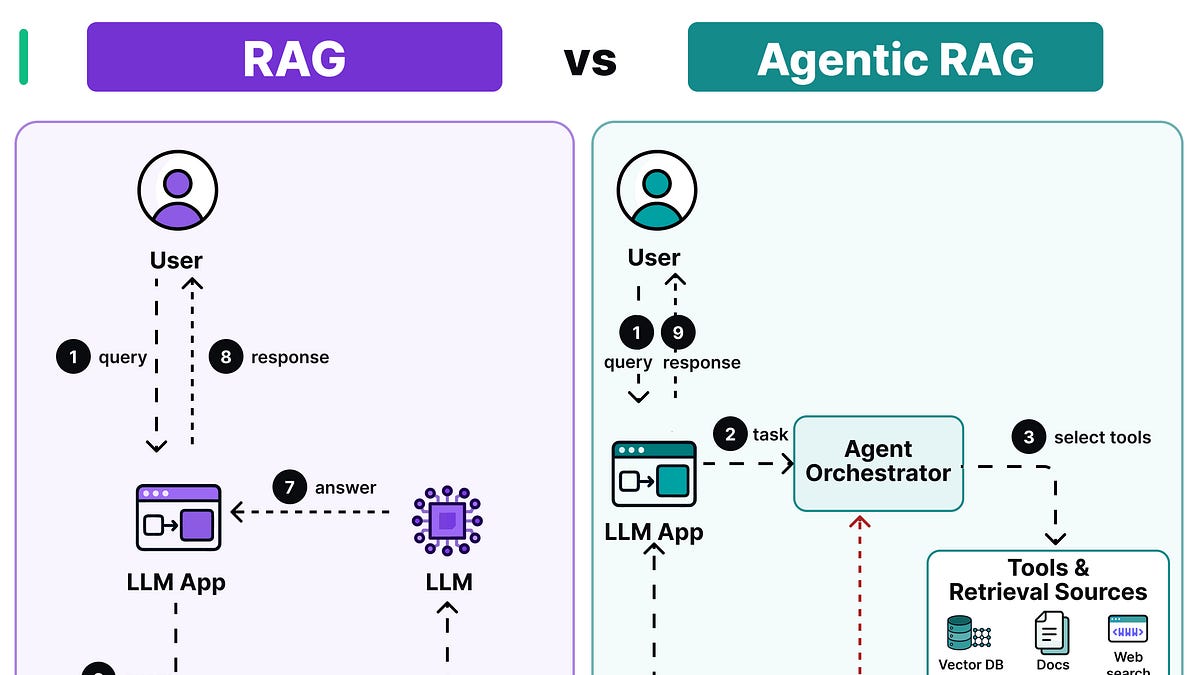
  8. EP230: RAG vs Agentic RAG

    This post provides brief conceptual overviews of several engineering topics, including traditional RAG versus Agentic RAG, OAuth versus OIDC, and the standard Linux directory structure. Traditional RAG relies on a single retrieval step, whereas Agentic RAG allows iterative searches and tool selection until sufficient evidence is gathered. The text outlines how OAuth handles authorization and OIDC adds user authentication, alongside a breakdown of core Linux directories like boot, dev, bin, and etc.

    DEPTH ■■■■■3 min read2 days ago

    Sign in to save and rate

  9. Don't forget about the UI for AI

    OpenAI developed ChatGPT Space, a real-time collaborative workspace designed to allow software engineering teams and individual AI agents to work together on shared artifacts. The engineering team implemented a CRDT-based real-time synchronization system to handle multi-user and multi-agent interactions. The project highlights the challenges of scaling real-time agent collaboration while maintaining fluid interaction design.

    DEPTH ■■■■■26 min read6 days ago

    Machine Learning

    Sign in to save and rate

  10. Production-grade LLMs and agents: a field guide

    Deploying LLMs and agents to production requires surrounding probabilistic models with deterministic machinery like evaluations, guardrails, and audit trails rather than relying on the model alone. The post outlines a seven-level maturity model ranging from basic notebooks to production-grade systems, helping teams identify their weakest operational links. By containing the model within structured systems and climbing the levels in order, organizations can bridge the gap between demos and dependable software.

    DEPTH ■■■■■4 min read7 days ago

    Machine Learning

    Sign in to save and rate

  11. How Dynata scaled AI across the development lifecycle with AI-DLC and Kiro IDE

    Dynata adopted the AI-Driven Development Lifecycle methodology using Kiro IDE and Amazon Q Developer to compress multi-sprint feature delivery into a single sprint. The team progressed from code generation to integrating knowledge ecosystems and conducting structured three-day feature workshops. As a result, requirements ambiguities surfaced early during planning and the team achieved faster, more aligned feature delivery.

    DEPTH ■■■■■15 min read10 days ago

    Sign in to save and rate

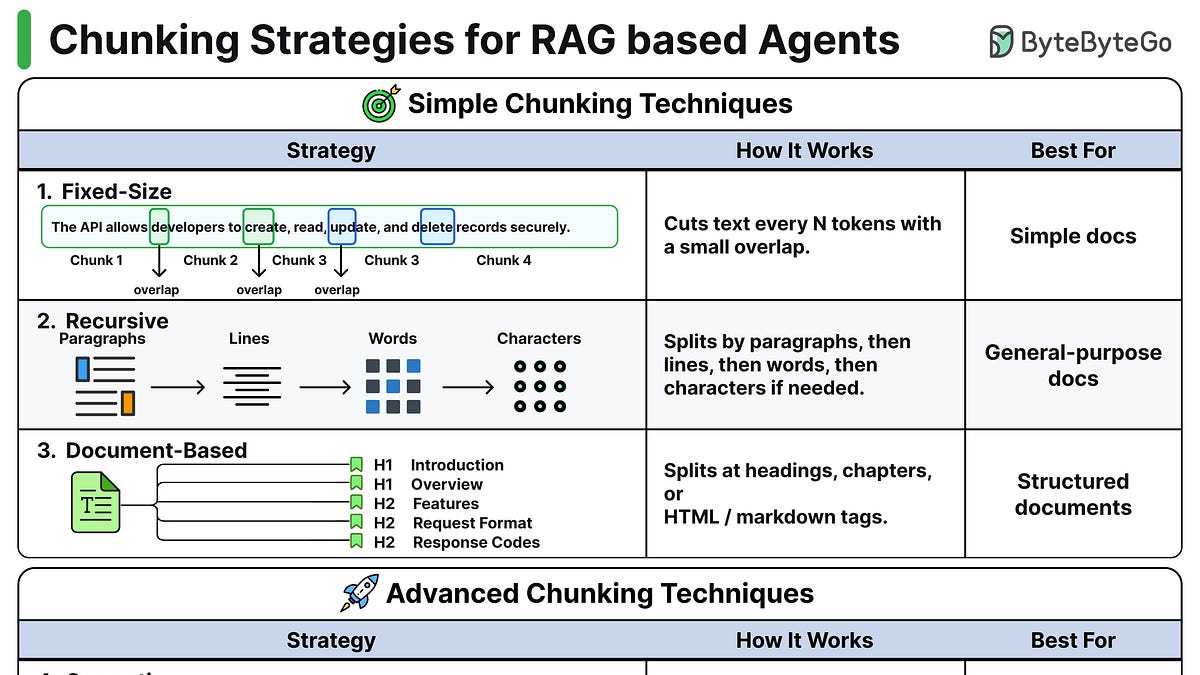
  12. EP229: 8 Chunking strategies for RAG-based agents

    The post provides brief, high-level overviews of various software engineering concepts including eight chunking strategies for RAG, the architecture of Google Translate, agent skills workflows, and the structural differences between PostgreSQL and MySQL. It touches upon how these different components and techniques function theoretically without deep benchmark comparisons. The content serves as a summary refresher on multiple system design topics.

    DEPTH ■■■■■3 min read9 days ago

    Sign in to save and rate

  13. AI says you’re right, formal methods say you’re wrong

    Engineers often struggle with the intimidating reputation and adoption of formal verification tools like TLA+ and its derivatives, despite their value in catching elusive edge cases and race conditions. Using specification languages to model systems allows teams to test fixes and optimizations mathematically before deploying them to production. This approach helps prevent complex bugs that take weeks to manifest in real-world traffic.

    DEPTH ■■■■■28 min read10 days ago

    Machine Learning

    Sign in to save and rate

  14. Why your platform team shouldn't build an AI context layer (even though they probably could)

    Engineering teams often underestimate the long-term maintenance required to build and run an internal AI context layer, mistaking a simple vector database for a fully governed knowledge pipeline. Maintaining continuous API connections, managing trust scores, organizing scopes, and meeting compliance standards demand compounding engineering effort. Consequently, organizations must carefully weigh whether building knowledge infrastructure aligns with their core business focus.

    DEPTH ■■■■■6 min read10 days ago

    Machine Learning

    Sign in to save and rate

  15. Your next job doesn’t have a title yet: Emerging role skills Q&A with Cory Hymel of Andela

    Researchers analyzed thousands of job postings to understand how artificial intelligence is changing technical skill requirements. The findings indicate that instead of creating a workforce of pure generalists, the market is developing distinct new specialized skill bundles and hybrid roles. Consequently, organizations are facing talent debt as the half-life of technical skills rapidly shrinks.

    DEPTH ■■■■■15 min read11 days ago

    Testing

    Sign in to save and rate

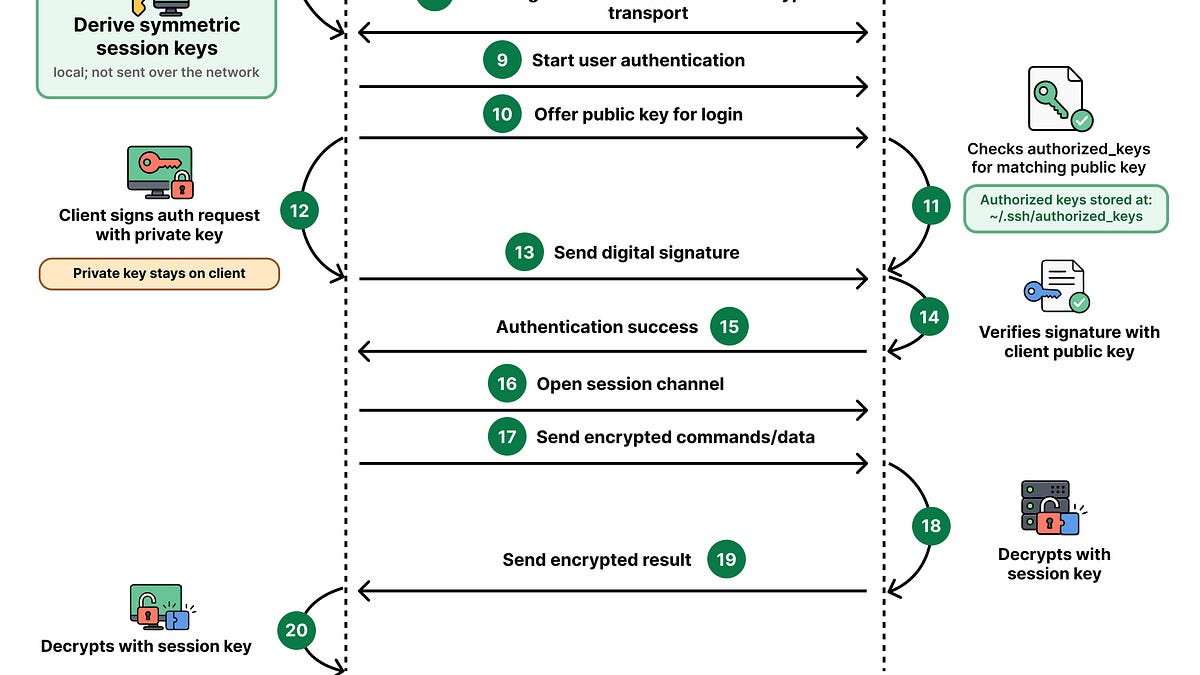
  16. EP228: How SSH Works

    This engineering newsletter covers the fundamentals of how SSH establishes secure remote connections through TCP, key exchange, and authentication. It also outlines key techniques for efficient LLM serving, the core anatomy of AI agents, and a structured approach to building evaluation systems.

    DEPTH ■■■■■6 min read3 weeks ago

    Sign in to save and rate

  17. Why Your Sandbox Never Quite Matches Production (And Why That's Fine)

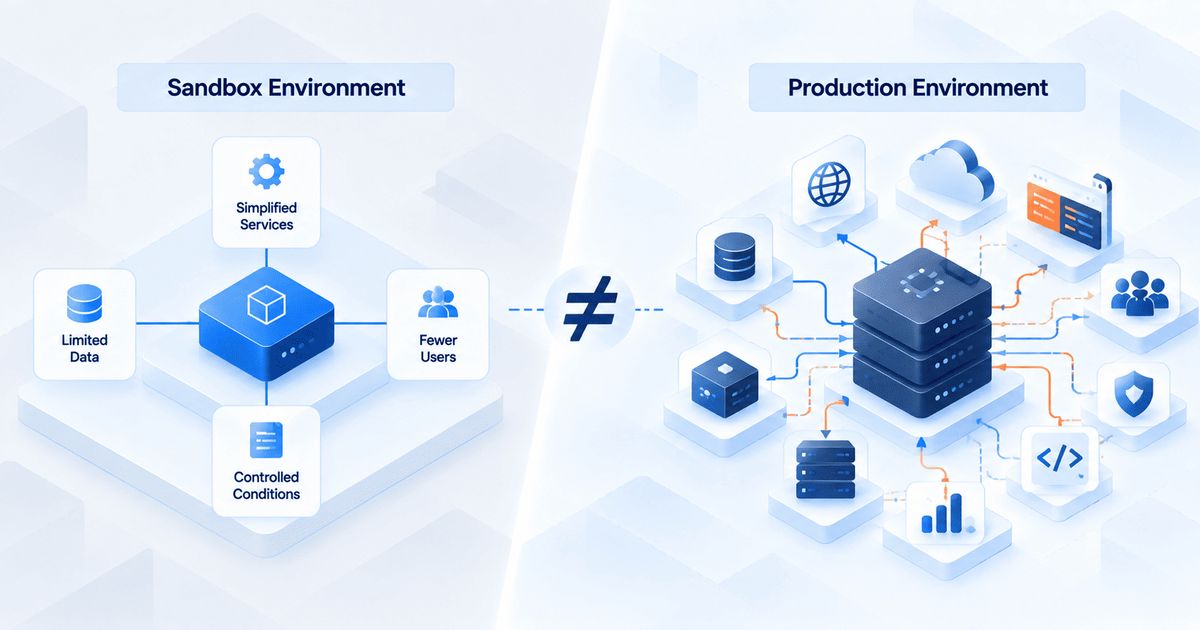
    This post examines why sandbox environments inevitably drift from production and argues that pursuing total infrastructure parity is a waste of effort. Instead of chasing impossible replication, teams should focus on maintaining accurate behavioral contracts and updating mock simulations when upstream services deploy. The result is a targeted approach that prevents integration failures caused by stale assumptions rather than expensive, low-value environmental matching.

    DEPTH ■■■■■6 min read12 days ago

    Sign in to save and rate

  18. A Treatise on Model Oriented Programming Languages

    An author reflects on a custom model-oriented programming language and IDE they built thirteen years ago, outlining principles and forms of model-oriented development. The article defines model structures and data using a restaurant scenario to compare informal, inline, coupled, and decoupled modeling approaches. Ultimately, the author aims to inspire further research and development into model-oriented programming languages.

    DEPTH ■■■■■33 min read2 weeks ago

    Sign in to save and rate

  19. Implementing a Modular Master-Agent Telemetry & Diagnostic Framework in Python: Prime-Sentinel Command (PSC)

    The post introduces the Prime-Sentinel Command architecture, a master-agent pattern designed to separate centralized governance from autonomous edge execution in distributed telemetry systems. It provides an object-oriented Python implementation where Sentinels handle localized diagnostics and a Prime controller manages orchestration and telemetry intake. This separation avoids bottlenecks and improves fault isolation in health-checking pipelines.

    DEPTH ■■■■■3 min read2 weeks ago

    Sign in to save and rate

  20. Constraints that make developers faster

    Julien Verlaguet, CEO of Skip Labs, discusses the design of programming languages and tooling to prevent developer mistakes. The conversation explores balancing code constraints with developer tolerance, the nuances of type systems across different use cases, and how AI agents change the requirements for constraint-based tooling. The key takeaway emphasizes that language choice and constraints must match the specific use case and context rather than a universal standard.

    DEPTH ■■■■■23 min read3 weeks ago

    Machine Learning

    Sign in to save and rate