/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Shard design doesn't start from your tables

    Designing a sharded Postgres architecture requires grouping tables around shared query keys rather than starting from table structures alone. The post details how to configure shard groups, reference tables, SQL expressions in shard indexes, and global secondary indexes using Neki. This setup enables efficient single-shard queries and transactions while maintaining full Postgres semantics.

    DEPTH ■■■■■8 min read4 days ago
    PostgreSQL

    Sign in to save and rate

  2. PHP2Shell: GitLab helps find and remediate critical PHP flaws

    Critical remote code execution vulnerabilities known as PHP2Shell affect the PHP engine across multiple versions, requiring immediate runtime updates to fixed versions or patched distribution packages. The team utilized platform features like container scanning, code search, and automated agent workflows to locate PHP projects and remediate vulnerabilities. Operators must also check logs and environments for signs of compromise as framework updates and input validations cannot prevent these engine-level flaws.

    DEPTH ■■■■■10 min read5 days ago

    ArchitectureSecurity

    Sign in to save and rate

  3. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read6 days ago

    Infrastructure

    Sign in to save and rate

  4. When Software Meets Hardware

    A software engineering team modernizing a large-scale retail IoT system of 800,000 battery-powered sensors faced challenges integrating software practices with embedded hardware. By building physical sensor farms, virtual emulators, and self-diagnosing firmware, the team learned to design for intermittent connectivity, power efficiency, and fleet-level observability. The project succeeded by treating the physical world, hardware constraints, and engineering environments as core parts of the system lifecycle.

    DEPTH ■■■■■12 min read12 days ago

    Sign in to save and rate

  5. I don't trust ON DELETE CASCADE

    Postgres ON DELETE CASCADE can cause production outages, replication failures, and performance degradation during large deletions or schema migrations due to long-running transactions holding locks and generating massive WAL. The author recommends using soft deletes with batched background cleanup instead to keep transactions short and bounded. This approach avoids table locks and simplifies data recovery.

    DEPTH ■■■■■5 min read6 days ago

    PostgreSQL

    Sign in to save and rate

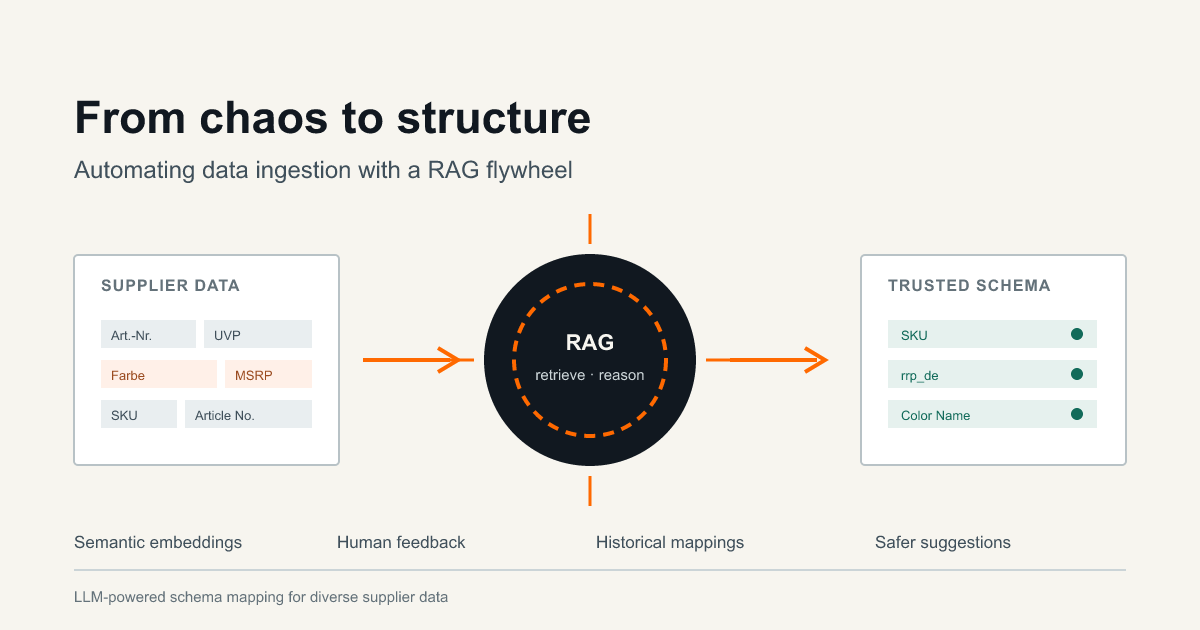
  6. Automating Data Ingestion with a RAG Flywheel

    Zalando replaced manual schema mapping for diverse supplier data with an LLM-powered Retrieval-Augmented Generation (RAG) flywheel. The system combines Amazon Titan embeddings stored in PostgreSQL via pgvector with tool-constrained generative models running at zero temperature. Every LLM suggestion passes through strict API validation checks before being reviewed by operations specialists, creating a continuous learning loop that improves future predictions.

    DEPTH ■■■■■14 min read2 weeks ago

    Machine LearningPostgreSQL

    Sign in to save and rate

  7. Sentry JavaScript SDK v11 adds tracing for all JS platforms

    Sentry replaced its OpenTelemetry-based JavaScript SDK instrumentation with a source-code transformation approach using diagnostics channels in version 11. This change removes reliance on Node-specific module loader hooks, enabling reliable tracing across non-Node runtimes like Deno, Bun, and Cloudflare Workers, while also supporting bundled applications. The result is a simplified architecture that reduces bundle weight and fixes previous limitations with load order and immutable exports.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate

  8. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read12 days ago

    Microservices

    Sign in to save and rate

  9. Are Harnesses Worth the Cost?

    An experiment was conducted to evaluate whether behavioral harnesses improve coding agent reliability when building a complex backend-for-frontend service. While frontier models succeeded consistently with or without a harness, the harness significantly increased token usage, time, and cost without improving final output. However, for a cost-optimized model, the harness improved success rates from 30 percent to 100 percent.

    DEPTH ■■■■■17 min read2 weeks ago

    Sign in to save and rate

  10. Make every AI credit count: See, cap, and reduce agent spend

    Uncontrolled AI agent spending can be mitigated by combining open-weight models, centralized context graphs to reduce retries, and usage analytics with credit caps. GitLab introduced these capabilities in its Duo Agent Platform to help platform teams trace, limit, and optimize AI credit consumption. The resulting architecture matches specific tasks to lower-cost models while maintaining task completion quality.

    DEPTH ■■■■■6 min read2 weeks ago

    Sign in to save and rate

  11. Reducing Android scope-sync overhead in Sentry Flutter

    The Sentry Flutter team investigated scope-sync overhead on Android and found redundant data normalization across isolates alongside unnecessary buffer copies during JSON encoding. By removing the duplicate normalization and encoding directly to UTF-8 bytes, the team reduced processing time by 27 to 30 percent across benchmarked payloads.

    DEPTH ■■■■■4 min read2 weeks ago

    Sign in to save and rate

  12. Thundering herd of circuit breakers

    An engineering team investigated why a client-side circuit breaker repeatedly failed to close on its own after an outage. By exporting OpenTelemetry traces into a custom visualization tool, they discovered that low probe traffic caused the autoscaler to scale down the service to minimum capacity, triggering a thundering herd of requests and immediate timeouts the moment the circuit breaker closed. Adjusting the system to account for capacity and probe representativeness prevents this oscillation.

    DEPTH ■■■■■10 min read2 weeks ago

    MicroservicesObservabilityReliability

    Sign in to save and rate

  13. What gets TOASTed in Postgres

    This post examines how PostgreSQL uses TOAST to manage oversized rows and variable-length columns through compression and off-row storage. It compares the pglz and LZ4 compression algorithms across different workloads, highlighting trade-offs in search windows, file sizes, and CPU overhead. The analysis demonstrates how these mechanisms impact storage efficiency and read performance for large text and JSON data.

    DEPTH ■■■■■12 min read2 weeks ago

    PostgreSQL

    Sign in to save and rate

  14. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

  15. The Sentry Android SDK is now 20-30% faster!

    The Sentry team optimized the Android SDK to reduce initialization time by 20-30% and background CPU usage by up to 10%. Improvements were achieved by profiling with Perfetto, replacing slow runtime manifest parsing and DSN parsing with build-time bytecode writing and lightweight parsers, and reusing thread pools. Upgrading to the latest SDK version allows applications to realize these startup performance gains.

    DEPTH ■■■■■4 min read7 days ago

    Sign in to save and rate

  16. TIN v1.0.6: 2-3x faster, with support for stemming

    Following competitive benchmarks that highlighted opportunities for optimization, the developers of the TIN full-text search index for Postgres released versions 1.0.4 and 1.0.6. These updates added Snowball stemming for 18 languages, optimized top-k sorting queries with deterministic tiebreakers, and improved overall query performance. As a result, benchmark tests show that TIN outperforms competing extensions across conjunction, disjunction, and phrase query workloads.

    DEPTH ■■■■■8 min read2 weeks ago

    PostgreSQL

    Sign in to save and rate

  17. Staying Evergreen: How we automated secure access and repo hygiene in a shared org

    Manual repository housekeeping and access reviews for outside collaborators become difficult to maintain as organizations scale. The team built Evergreen, a GitHub App that automates quarterly access reviews and stale repository archiving using native platform features and IssueOps. This automation successfully enforces secure defaults by revoking unanswered access while maintaining a full audit trail in git history.

    DEPTH ■■■■■8 min read11 days ago

    Sign in to save and rate

  18. Fragments: October 21

    This post discusses commentary on AI usage in writing, the cancellation of the Grace Hopper Celebration, and reviews a detailed article by Cindy Sridharan on debugging with AI agents. The reviewed article highlights that AI agents excel at processing raw data rather than reading code first, and outlines a three-step debugging process involving controls, signals, and hypothesis validation. The lesson is that engineers must guide AI agents by setting up verification loops and providing raw data rather than human-centric abstractions.

    DEPTH ■■■■■5 min read6 days ago

    Sign in to save and rate

  19. Building a faster, lazier router for Postgres

    To reduce overhead when routing queries across PostgreSQL shards, the Neki router avoids unnecessary parsing and decodes responses lazily. By keeping data in its original wire format and only decoding columns when strictly required for operations like limits or sorting, the router significantly improves performance.

    DEPTH ■■■■■16 min read3 weeks ago

    Sign in to save and rate

  20. Unreal MCP now speaks Sentry

    The Sentry team integrated their crash reporting plugin with Unreal Engine's new experimental Model Context Protocol (MCP) server, allowing coding agents to fully automate setup and debugging. By combining editor tools and Sentry MCP, an agent successfully configured the SDK, uploaded debug symbols, packaged a build, induced a crash, and traced the root cause without manual file editing. The integration streamlines crash reporting setup, though it currently suffers from occasional agent tool-discovery issues and server fragility across editor restarts.

    DEPTH ■■■■■7 min read3 weeks ago

    Sign in to save and rate