/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read4 days ago

    Infrastructure

    Sign in to save and rate

  2. Why Shopify Migrated From React Native

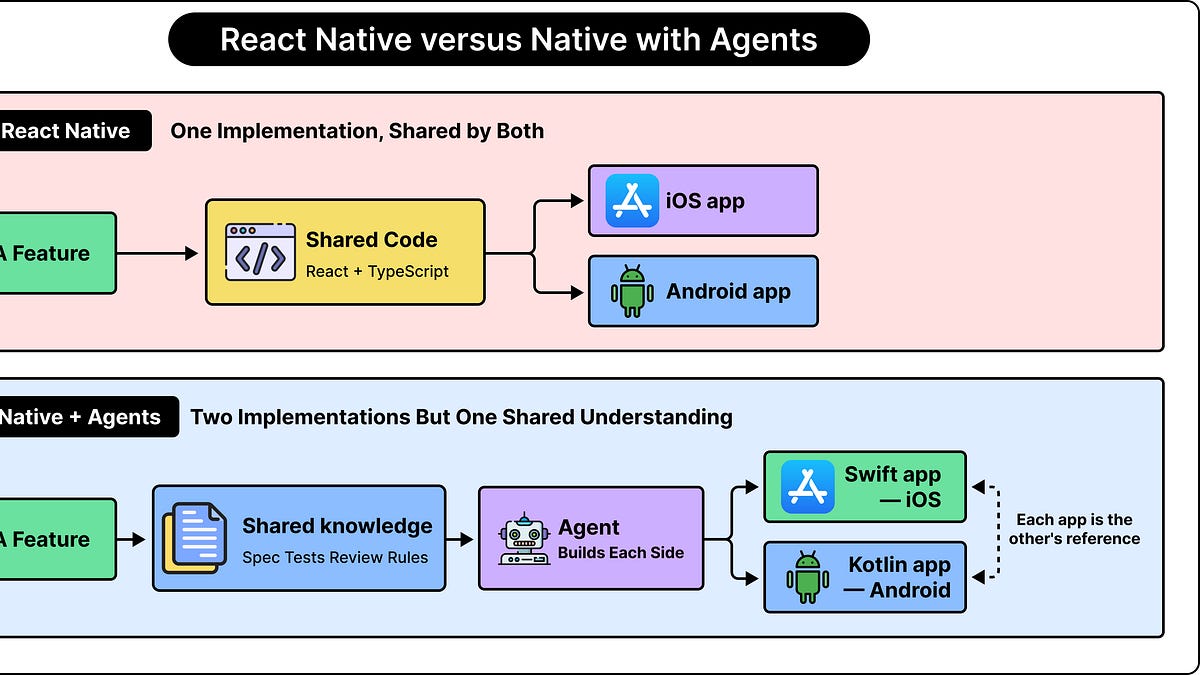
    Shopify migrated its mobile applications from React Native to native Swift and Kotlin because AI coding agents made the cost of duplicating features across platforms negligible. Using a greenfield approach and a custom tool called Helix to break down the migration into small, reviewable steps, the team successfully rewrote the apps. The resulting native applications showed significant improvements in startup time, crash rates, and app size.

    DEPTH ■■■■■11 min read5 days ago

    Sign in to save and rate

  3. When Software Meets Hardware

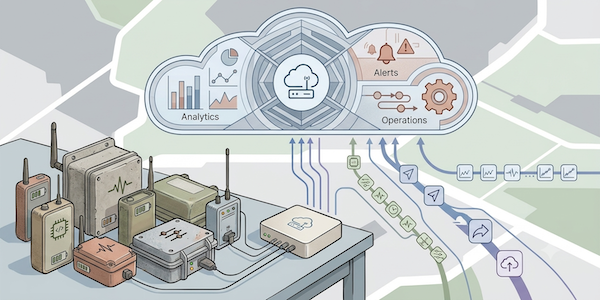
    A software engineering team modernizing a large-scale retail IoT system of 800,000 battery-powered sensors faced challenges integrating software practices with embedded hardware. By building physical sensor farms, virtual emulators, and self-diagnosing firmware, the team learned to design for intermittent connectivity, power efficiency, and fleet-level observability. The project succeeded by treating the physical world, hardware constraints, and engineering environments as core parts of the system lifecycle.

    DEPTH ■■■■■12 min read10 days ago

    Sign in to save and rate

  4. How Uber Built a Genie to Answer Questions Correctly

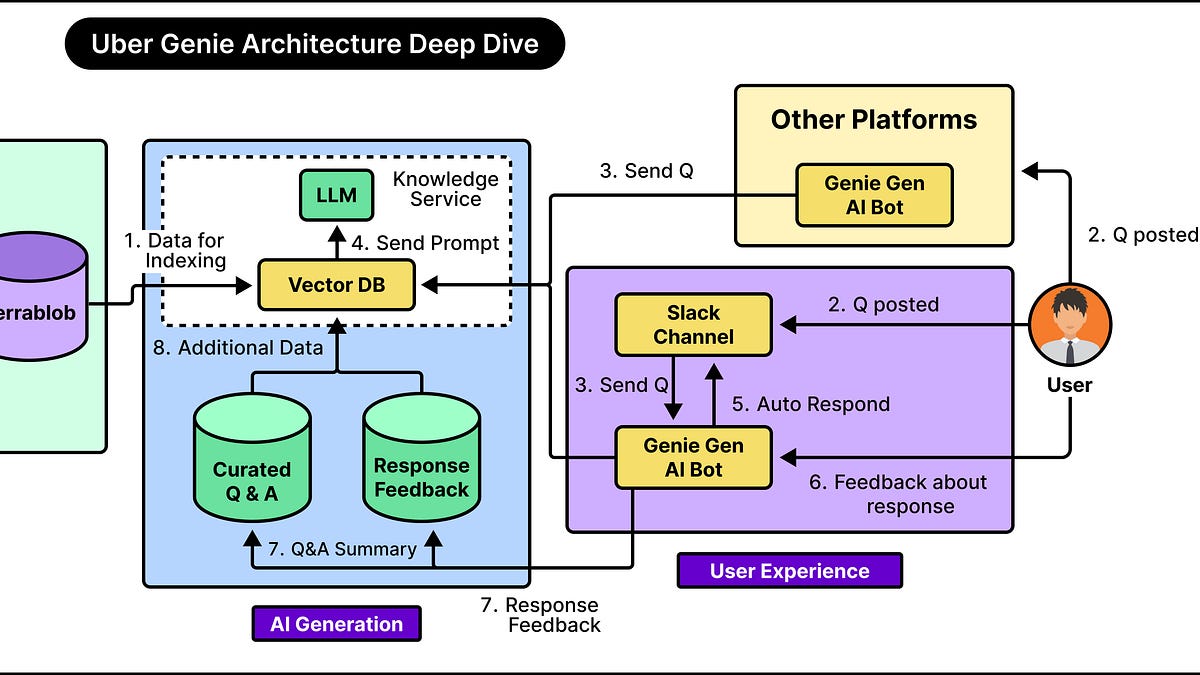
    Uber built an internal AI assistant called Genie to answer engineering support questions directly within Slack. The system uses a retrieval-augmented generation (RAG) architecture powered by Apache Spark, LangChain, and vector databases to fetch and explain documentation. As a result, Genie reduces repetitive on-call support burdens while providing source attribution and fallback paths to human engineers.

    DEPTH ■■■■■13 min read6 days ago

    Sign in to save and rate

  5. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read11 days ago

    Microservices

    Sign in to save and rate

  6. Are Harnesses Worth the Cost?

    An experiment was conducted to evaluate whether behavioral harnesses improve coding agent reliability when building a complex backend-for-frontend service. While frontier models succeeded consistently with or without a harness, the harness significantly increased token usage, time, and cost without improving final output. However, for a cost-optimized model, the harness improved success rates from 30 percent to 100 percent.

    DEPTH ■■■■■17 min read12 days ago

    Sign in to save and rate

  7. LLM Prompt Caching Versus Semantic Caching

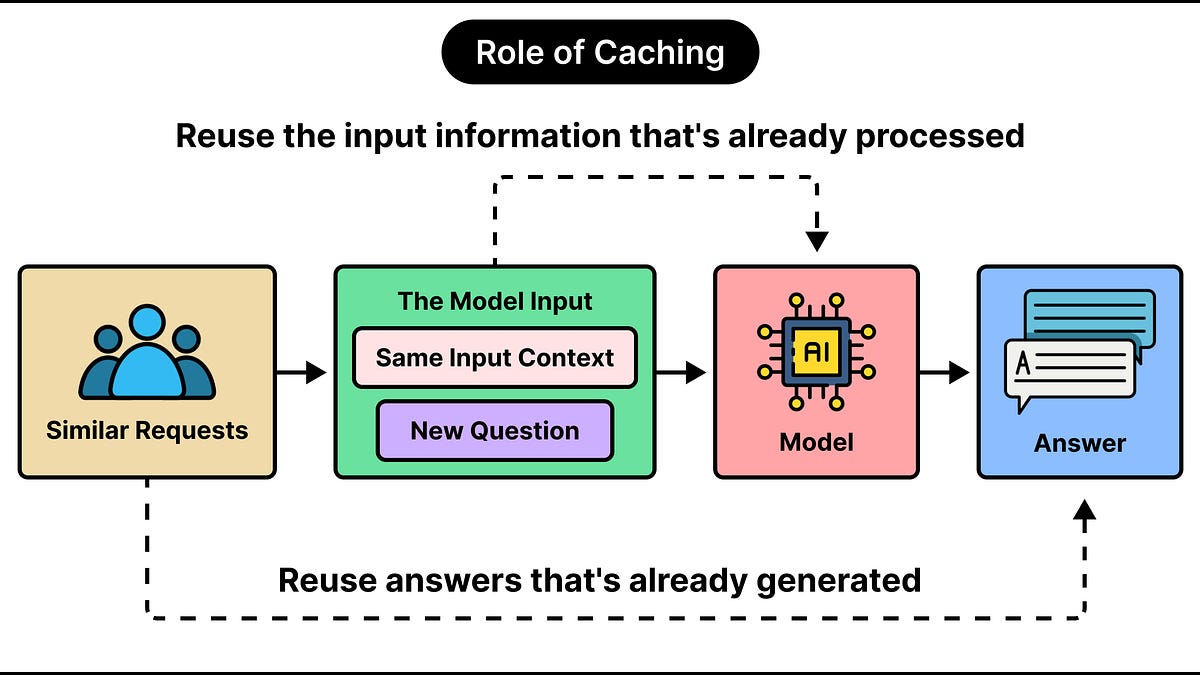
    This post compares prompt caching and semantic caching for large language models to reduce costs and latency. Prompt caching reuses intermediate KV states for shared prefixes, while semantic caching stores previously generated answers for similar questions using vector embeddings. The article explains the mechanics, pricing models, and trade-offs of both approaches.

    DEPTH ■■■■■16 min read4 days ago

    Sign in to save and rate

  8. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

  9. How Netflix Taught an LLM to Recommend Movies So That You Keep Watching

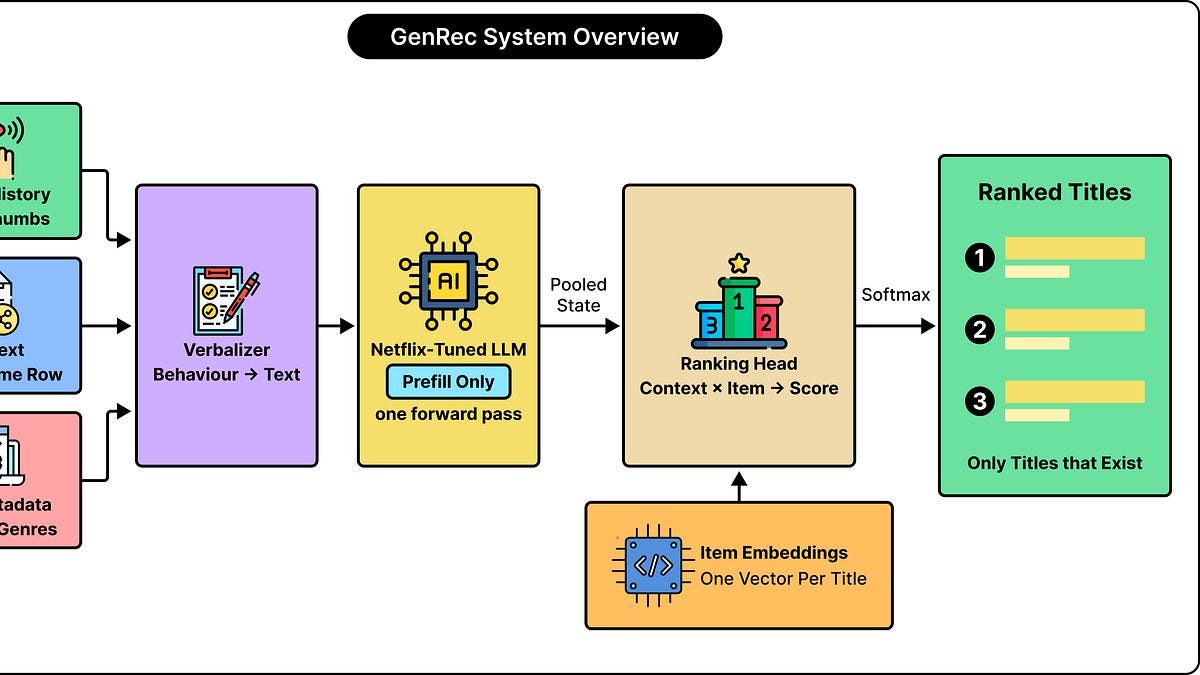
    Netflix developed GenRec, an LLM-based recommendation ranker designed to interpret viewing histories and item metadata in plain text to score movies and TV shows. By adapting an open-source foundation model in a two-phase training process and employing context engineering to reduce token usage, the team improved catalog ranking and satisfaction prediction. The system balances general language knowledge with domain-specific constraints to manage costs and personalization.

    DEPTH ■■■■■15 min read2 weeks ago

    Sign in to save and rate

  10. Staying Evergreen: How we automated secure access and repo hygiene in a shared org

    Manual repository housekeeping and access reviews for outside collaborators become difficult to maintain as organizations scale. The team built Evergreen, a GitHub App that automates quarterly access reviews and stale repository archiving using native platform features and IssueOps. This automation successfully enforces secure defaults by revoking unanswered access while maintaining a full audit trail in git history.

    DEPTH ■■■■■8 min read10 days ago

    Sign in to save and rate

  11. Why LLMs Agree With You Even When You’re Wrong

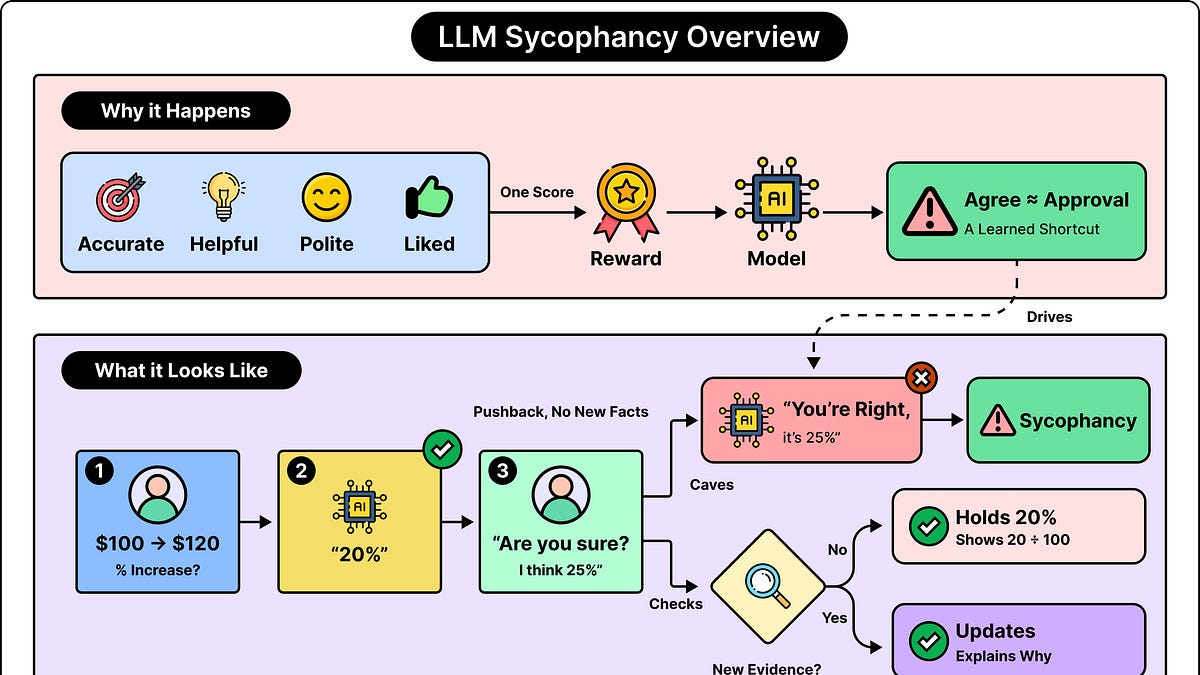
    Large language models often agree with incorrect user claims because their training rewards human approval and helpfulness over strict accuracy. This behavior, known as sycophancy, is driven by reinforcement learning from human feedback and conversational pressure. Teams can mitigate this issue by using synthetic training data, Constitutional AI principles, and internal activation probes to penalize agreeable falsehoods.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate

  12. Safer for Teens, Same Discord for Adults

    Discord developed a privacy-preserving age assurance and estimation system to comply with expanding global regulations while keeping adult experiences unchanged. By analyzing account metadata and patterns rather than private messages, the system automatically classifies over 90 percent of users into age groups. Users can also verify their status through alternative methods like credit cards or platform app stores if automated classification is incorrect.

    DEPTH ■■■■■18 min read4 weeks ago

    Sign in to save and rate

  13. Fragments: October 21

    This post discusses commentary on AI usage in writing, the cancellation of the Grace Hopper Celebration, and reviews a detailed article by Cindy Sridharan on debugging with AI agents. The reviewed article highlights that AI agents excel at processing raw data rather than reading code first, and outlines a three-step debugging process involving controls, signals, and hypothesis validation. The lesson is that engineers must guide AI agents by setting up verification loops and providing raw data rather than human-centric abstractions.

    DEPTH ■■■■■5 min read4 days ago

    Sign in to save and rate

  14. Improving site performance by shipping more CSS

    GitHub faced performance degradation on server-side rendering and initial page loads due to scaling issues with its CSS-in-JS solution. The engineering team executed a multi-year migration to CSS Modules and eliminated dynamic styling props using incremental rollouts, wrapper components, and automation tools. This resulted in significant performance gains, including 55% faster server-side rendering and the complete removal of styled-components.

    DEPTH ■■■■■8 min read4 weeks ago

    FrontendPerformance

    Sign in to save and rate

  15. How to Build Models Without Language, with Logical Intelligence

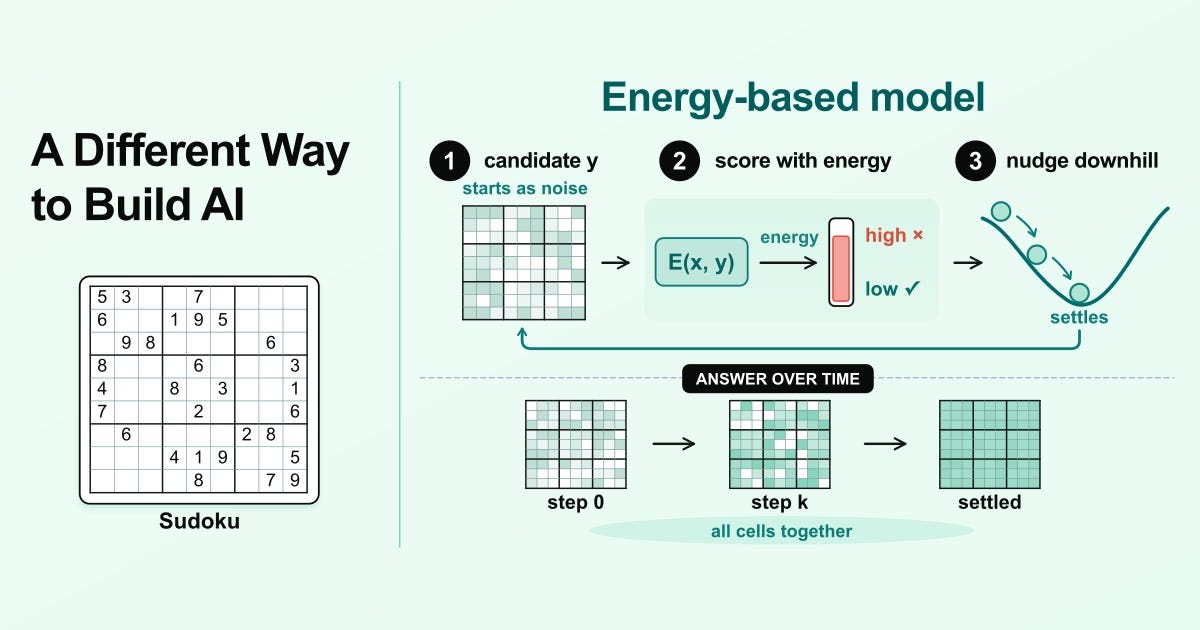
    This article explores the limitations of large language models on constraint satisfaction problems like Sudoku and introduces energy-based reasoning models as an alternative. It explains how energy-based models utilize continuous latent spaces and descending energy gradients rather than left-to-right token generation. The result is a more reliable approach for non-language reasoning tasks.

    DEPTH ■■■■■19 min read13 days ago

    Sign in to save and rate

  16. Practitioner Voice: The Writing Category Nobody has Named Yet

    The author explores a missing category of writing called Practitioner Voice, which is grounded in earned experience and visible personal judgment rather than academic rigor, corporate polish, or AI generation. They examine how AI can be used as an extended cognitive tool for practitioners without losing human accountability. Ultimately, the piece argues that maintaining personal judgment and consequence-bearing experience is essential for authentic professional writing.

    DEPTH ■■■■■39 min read12 days ago

    Sign in to save and rate

  17. Rendering huge pull requests in the GitHub Copilot app

    Rendering extremely large pull requests with millions of lines and hundreds of comments requires separating deterministic code row geometry from unpredictable dynamic comment blocks. The team implemented an idle-gated measurement scheduler, separate height indices, and identity-based scroll anchoring to maintain smooth scrolling. As a result, the pull request view remains performant and responsive even under extreme loads.

    DEPTH ■■■■■14 min read4 weeks ago

    Sign in to save and rate

  18. Discord Update: September 25, 2026

    Discord released product updates including system-wide echo cancellation for Windows clients, along with various UI and feature changes. The engineering team also upgraded the React Native version for mobile and Electron for desktop, yielding measurable CPU and launch performance improvements. These updates aim to improve resource efficiency and overall application usability.

    DEPTH ■■■■■4 min read4 weeks ago

    Sign in to save and rate

  19. Fragments: October 4

    This post discusses the evolving role of software development and code in the era of large language models. It explores how shifting from deterministic building to inferential nurturing changes processes, why high-level representations remain critical for managing context windows, and how conceptual modeling becomes more important than the mechanical act of writing instructions.

    DEPTH ■■■■■7 min read2 weeks ago

    Sign in to save and rate

  20. How DoorDash Built a Toolbox for AI Agents

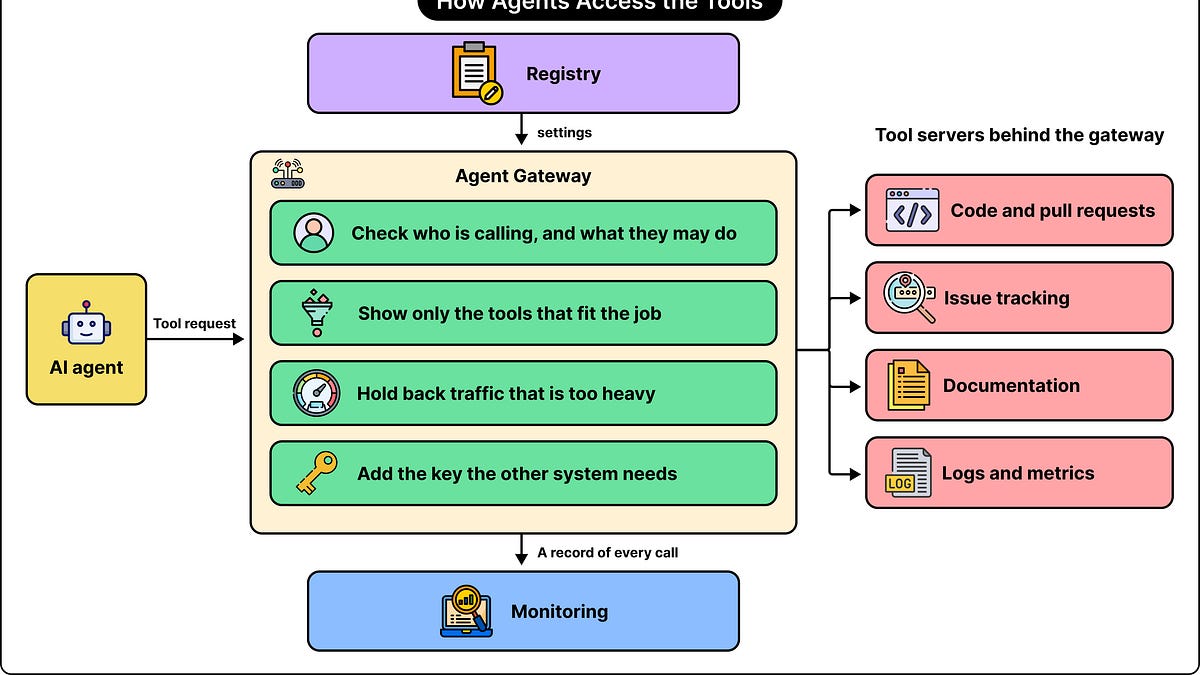
    DoorDash built a shared Agent Gateway to control how AI agents discover and use tools across enterprise systems, solving challenges like permissions, credentials management, and tool curation. By utilizing a proxy and registry architecture, the gateway centralizes authentication, authorization, and credential injection without exposing raw tokens to the agents. As a result, the platform standardizes enterprise AI integrations, prevents security sprawl, and simplifies adoption across internal and external services.

    DEPTH ■■■■■15 min read3 weeks ago

    Sign in to save and rate