/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. The Thin Orchestrator: How We Made Our AI Agents More Reliable by Giving the Router Less to Do

    Meta engineers reduced hallucinations and improved reliability in their data pipeline agents by replacing a single heavyweight LLM orchestrator with a thin deterministic router and fourteen specialized subagents. The thin orchestrator handles routing and reliability checks through a fixed protocol, while isolated subagents execute domain reasoning. This architecture reduced configuration preparation time from a day to under an hour.

    DEPTH ■■■■■7 min read6 days ago
    Machine Learning

    Sign in to save and rate

  2. Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster

    Meta built Prometheus, a gigawatt-scale AI supercluster designed to scale up to one million GPUs using multi-generation NVIDIA hardware and specialized backend Ethernet networks. The team achieved high goodput and significantly reduced system interruptions by implementing an in-rack sparing strategy, parallelism-aware fault tolerance, and close co-engineering with vendors. These infrastructure advancements allowed the team to successfully train frontier foundational models like Muse Wonder.

    DEPTH ■■■■■17 min read6 days ago

    InfrastructureMachine Learning

    Sign in to save and rate

  3. SBD: We Have a Filesystem at Home

    Fly.io replaced a custom JuiceFS-based filesystem for their Sprites infrastructure with the Sprites Block Device (SBD) to eliminate complex, out-of-sync metadata ledgers. SBD presents object storage as a block device over NBD, allowing standard ext4 to manage the filesystem and simplifying checkpoints and restores. The result is significantly improved reliability and a much simpler storage architecture.

    DEPTH ■■■■■6 min read3 days ago

    Sign in to save and rate

  4. How Meta Built Forum With AI-Native Engineering

    Meta engineers built the Forum app using a human-on-the-loop AI agent workflow that automated planning, building, testing, and verification. By shifting focus from code generation to automated verification, tooling improvements, and architectural legibility, the team reached feature parity in eight weeks while catching systemic memory issues early.

    DEPTH ■■■■■8 min read10 days ago

    FrontendMobile

    Sign in to save and rate

  5. Meta’s Generative Ads Model (GEM): Scaling the Central Model and Compute Engine for Frontier Ads AI

    Meta developed GEM, a unified recommendation foundation model using an LLM-style architecture called Kunlun to handle heterogeneous ads data across multiple surfaces. The team implemented block attention, custom low-precision kernels, and post-training intelligence transfer techniques like LoopFM and Solaris to scale training efficiency and bypass real-time serving latency bottlenecks. The resulting system delivered an 18.9% conversion improvement and a 12% click-through rate increase across Meta ads surfaces.

    DEPTH ■■■■■15 min read12 days ago

    Machine Learning

    Sign in to save and rate

  6. OCP Summit 2026: Powering AI with Open Innovations in Scale-Up, Scale-Out, and Scale-Across Networks

    Meta shared its next-generation open networking infrastructure for AI at the OCP Summit 2026, including liquid-cooled 102.4T switch platforms, multiplane scale-out fabrics, and Ethernet-based scale-up solutions. The team also highlighted collaborative industry standards like ESUN and OSPA to unify hardware and transport layers. These open innovations aim to support massive gigawatt-scale AI clusters across diverse data center environments.

    DEPTH ■■■■■12 min read12 days ago

    Machine Learning

    Sign in to save and rate

  7. It's time to make your own RSS reader

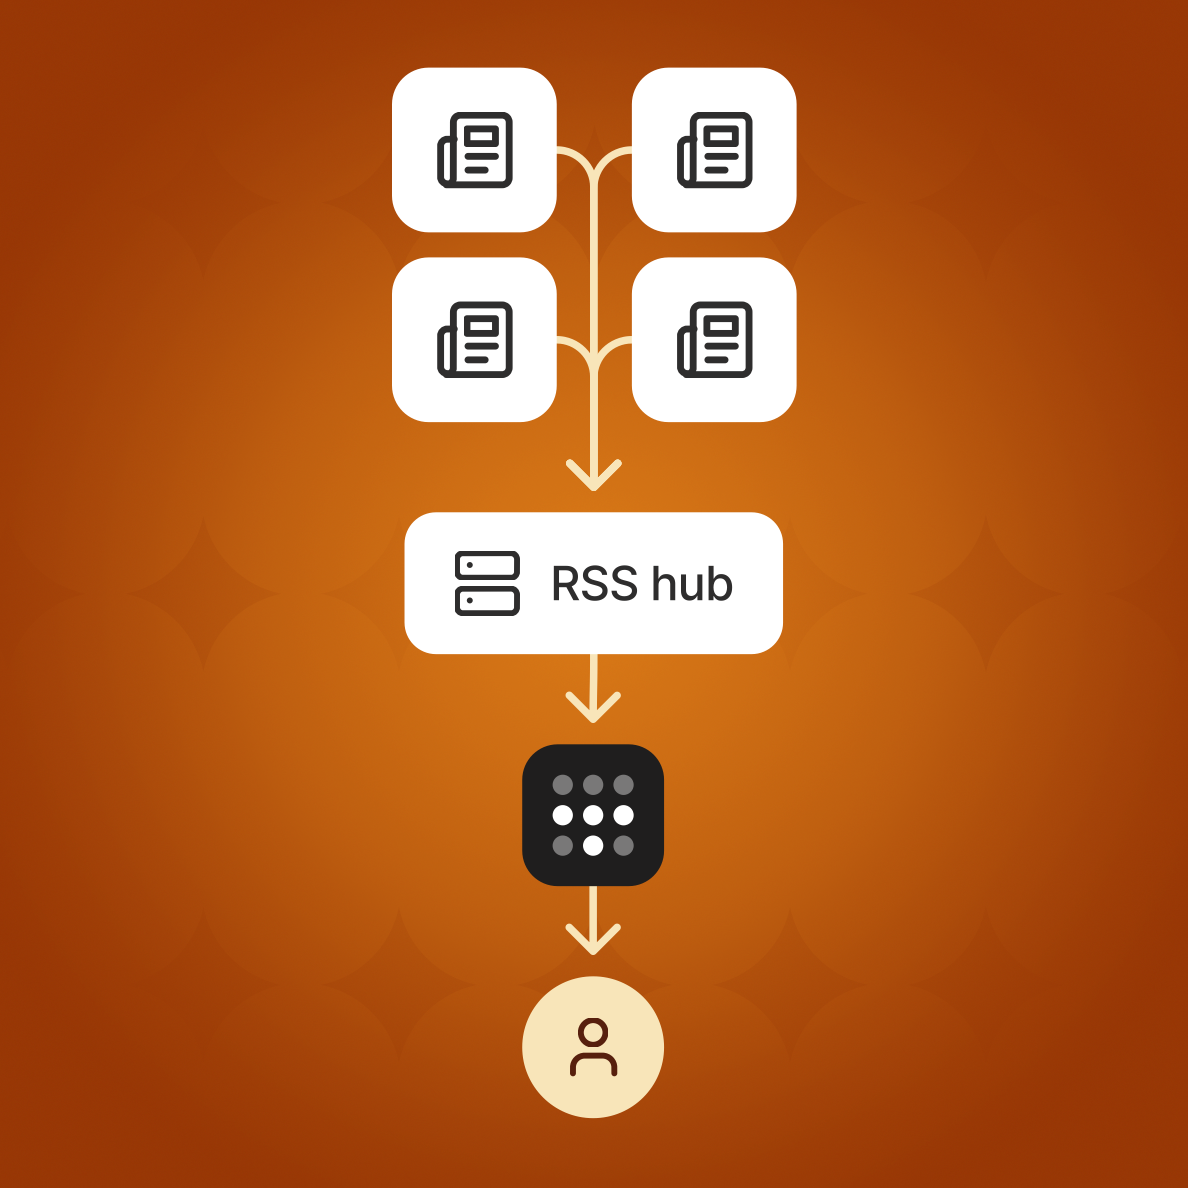
    This post walks through the process of self-hosting a personal RSS reader using FreshRSS and Docker, secured privately over a Tailscale network. The author details the configuration of environment variables, auth keys, and Docker compose deployment to avoid exposing the service to the open web. The result is a private, algorithm-free news reader accessible across multiple devices and integrable with external reading apps or AI agents.

    DEPTH ■■■■■10 min read9 days ago

    Sign in to save and rate

  8. GenRecs Tokenization: Transforming Ads Recommendation at Meta with Stable Model Vocabulary

    Meta implemented GenRecs Tokenization to replace dedicated item IDs with a stable semantic vocabulary for ads recommendation. Using a three-stage encoding and quantization pipeline, the system enables language models to reason about ad content and user preferences simultaneously. This approach resulted in a +0.35% lift in conversions and improved cold-start performance for new entities.

    DEPTH ■■■■■6 min read6 days ago

    Machine Learning

    Sign in to save and rate

  9. Your agent, your network: How Meta’s Muse agent works with Tailscale

    Meta integrated Tailscale into its Muse personal AI agent, allowing the agent to join a user's tailnet as a separate node and interact with self-hosted services and SSH sessions. By treating Muse like any standard tailnet node, users can apply Tailscale's access controls, grants, and tags to enforce security and adhere to the principle of least privilege.

    DEPTH ■■■■■5 min read3 weeks ago

    Sign in to save and rate

  10. 2026 World Cup: Breaking Records, Spiky Charts and Reliability at Scale

    Meta's infrastructure handled record-breaking traffic during the 2026 World Cup, including 30 million messages per second on WhatsApp, by relying on automated load balancing, capacity buffers, and targeted pre-builds. Traffic patterns revealed that surges occurred primarily during breaks rather than gameplay, requiring region-specific forecasting rather than cross-region load shifting. The systems maintained full reliability and allowed normal continuous deployment schedules to continue without manual intervention or system freezes.

    DEPTH ■■■■■5 min read10 days ago

    Infrastructure

    Sign in to save and rate

  11. Shipping Media Over QUIC at Meta Scale for Instagram Live Ingest

    Meta deployed the emerging Media over QUIC (MoQ) protocol for Instagram Live ingest on iOS and Android to replace their legacy RUSH protocol. By using edge translation to avoid backend rewrites and a phased rollout strategy, the team achieved metric parity with the old protocol without regressions. This deployment establishes a foundation to extend MoQ across Meta's applications for lower-latency and more resilient video streaming.

    DEPTH ■■■■■8 min read13 days ago

    FrontendMobile

    Sign in to save and rate