/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. MCP standardized tools. Now we need the infrastructure around them.

    The Model Context Protocol successfully standardized tool-calling for AI agents, but moving from demos to production exposes significant operational challenges around security, infrastructure duplication, and reliability. Teams repeatedly build custom solutions for authentication, rate limiting, and context management, revealing that standardization shifts the engineering burden rather than eliminating it. Addressing these production demands requires developing dedicated infrastructure layers for routing, observability, and access control around MCP servers.

    DEPTH ■■■■■8 min read10 days ago
    Machine Learning

    Sign in to save and rate

  2. Better HTTP/1 connection reuse

    Failing to read an HTTP/1 response body completely prevents connection reuse, forcing clients to repeatedly pay the high cost of TCP and TLS handshakes. While developers previously had to implement complex manual body-draining logic, Go 1.27 introduces automatic asynchronous response draining in the net/http package. This improvement allows developers to simply close response bodies without worrying about connection pooling performance.

    DEPTH ■■■■■7 min read11 days ago

    Sign in to save and rate

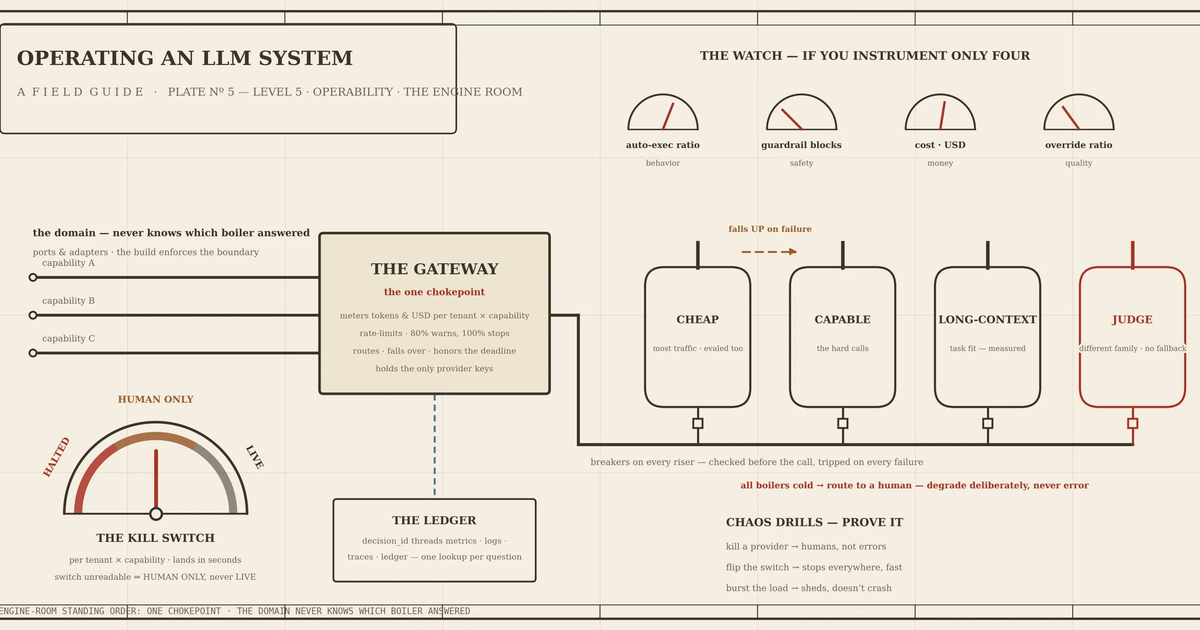
  3. Part 5: Operating an LLM system: observability, cost, routing, and the platform underneath

    This post provides a concrete specification for the operability layer of production LLM systems, covering observability signals, structured logging, cost controls, routing, and failover mechanisms. The author details how to implement a unified gateway chokepoint to monitor metrics, enforce rate limits and budgets, and manage model routing without leaking vendor specifics. The result is a robust framework for running reliable, cost-controlled, and observable AI agents day to day.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  4. Arch-specific SIMD in Go

    Go 1.27 introduces the archsimd package to provide low-level architecture-specific SIMD intrinsics for amd64, arm64, and wasm without requiring assembly. The API uses sensible naming conventions, zero-cost type reinterpretation, and opaque masks to improve usability and maintainability while achieving high performance. The resulting design enables developers to write optimized vectorized code safely with proper runtime CPU feature checking and compiler optimizations.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

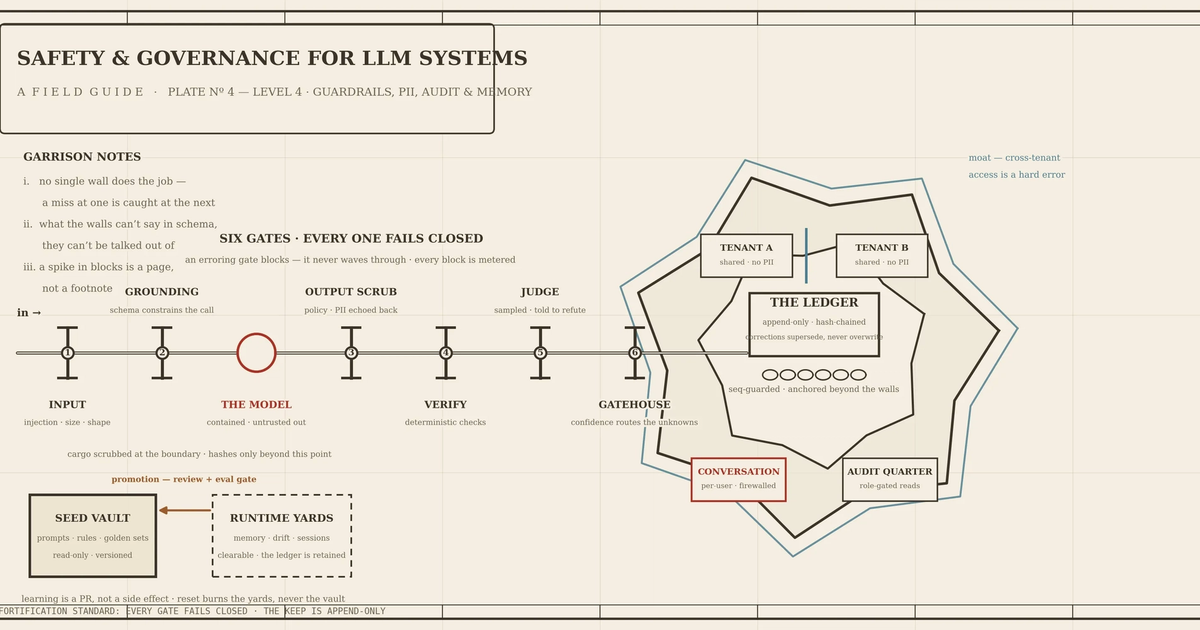
  5. Part 4: Safety and governance for LLM systems: guardrails, PII, audit, and memory

    This post details safety and governance practices for LLM systems, focusing on layered guardrails, boundary-level PII handling, and immutable audit trails. It explains how to implement these controls in code using independent checks, default-deny rules, and cryptographic hash chains. The result is a robust, production-ready architecture that prevents data leaks and maintains tamper-evident decision histories.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

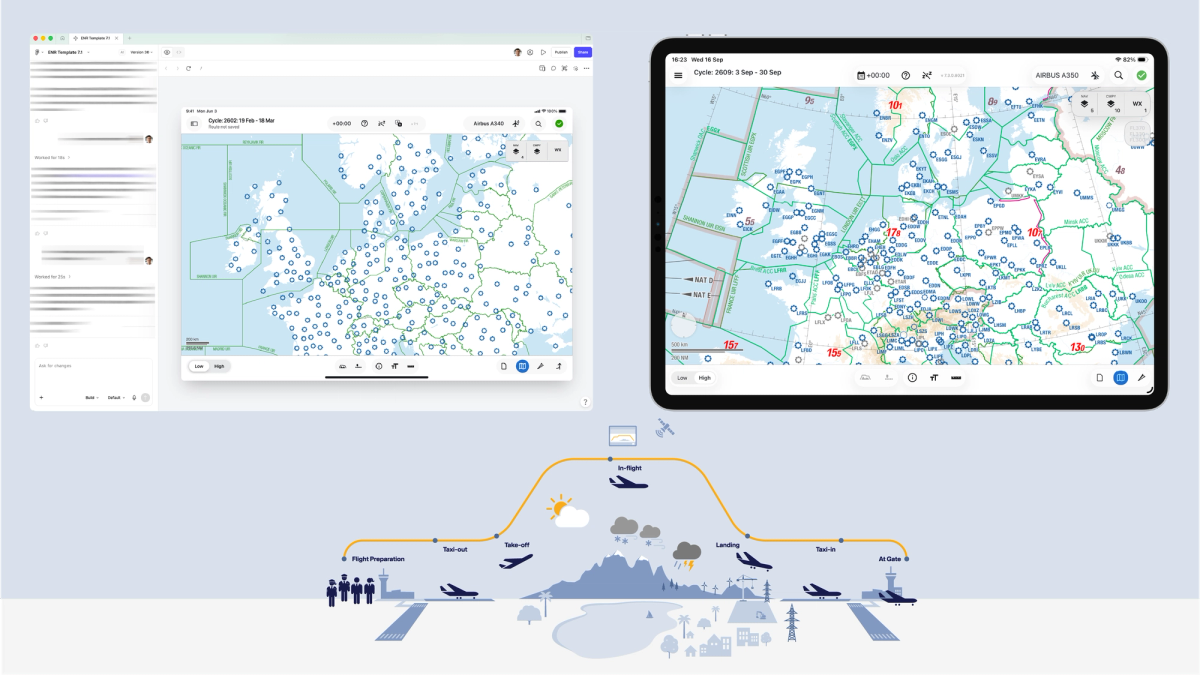
  6. How Lufthansa Systems prototypes realistic maps for the cockpit with Figma Make

    Lufthansa Systems struggled to build realistic, dynamic map prototypes for cockpit navigation apps using traditional static design tools. The team experimented with Figma Make during an internal hackathon to integrate external data sources like Mapbox and the OpenSky Network into their designs. As a result, designers successfully tested interactive map features and complex flight traffic data with pilots prior to writing production code.

    DEPTH ■■■■■8 min read3 days ago

    Sign in to save and rate

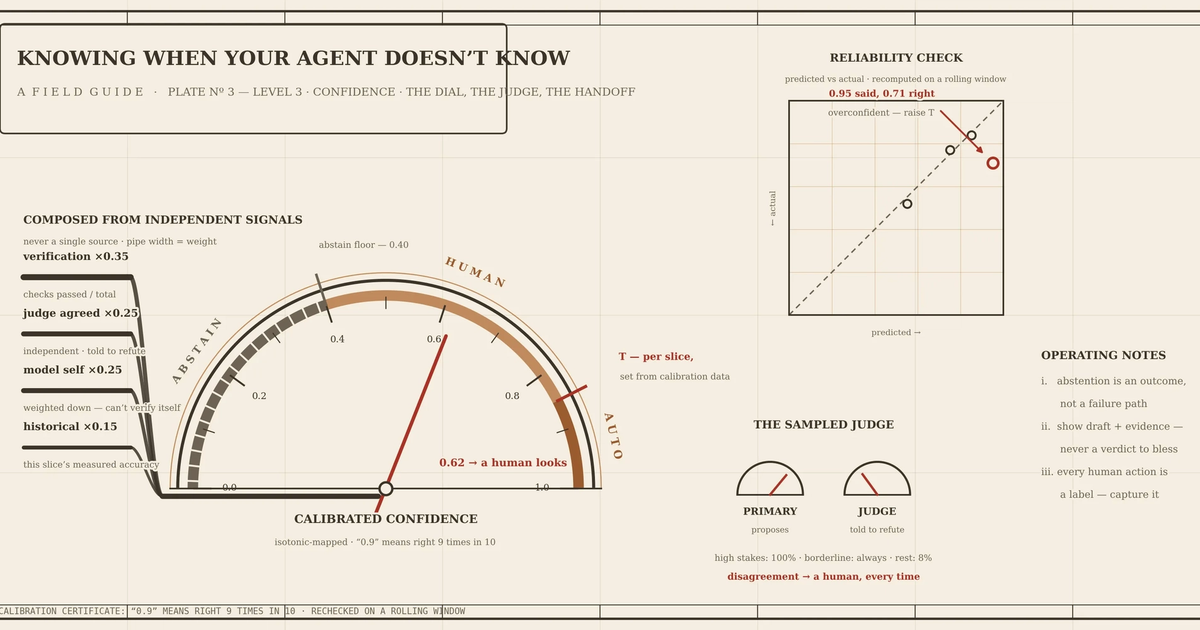
  7. Part 3: Knowing when your agent doesn’t know: the confidence layer

    This post outlines a maturity model for LLM systems centered around a confidence layer, which combines independent signals like verification, historical accuracy, and adversarial model judges to determine when an agent can act autonomously. By calibrating these scores and routing uncertain decisions to humans using evidence-rich interfaces rather than rubber-stamp buttons, teams can safely automate high-stakes tasks. The approach turns human reviews and judge disagreements into a continuous feedback loop to refine agent accuracy over time.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  8. Part 2: Evals as a deployment gate — and how to know when they drift

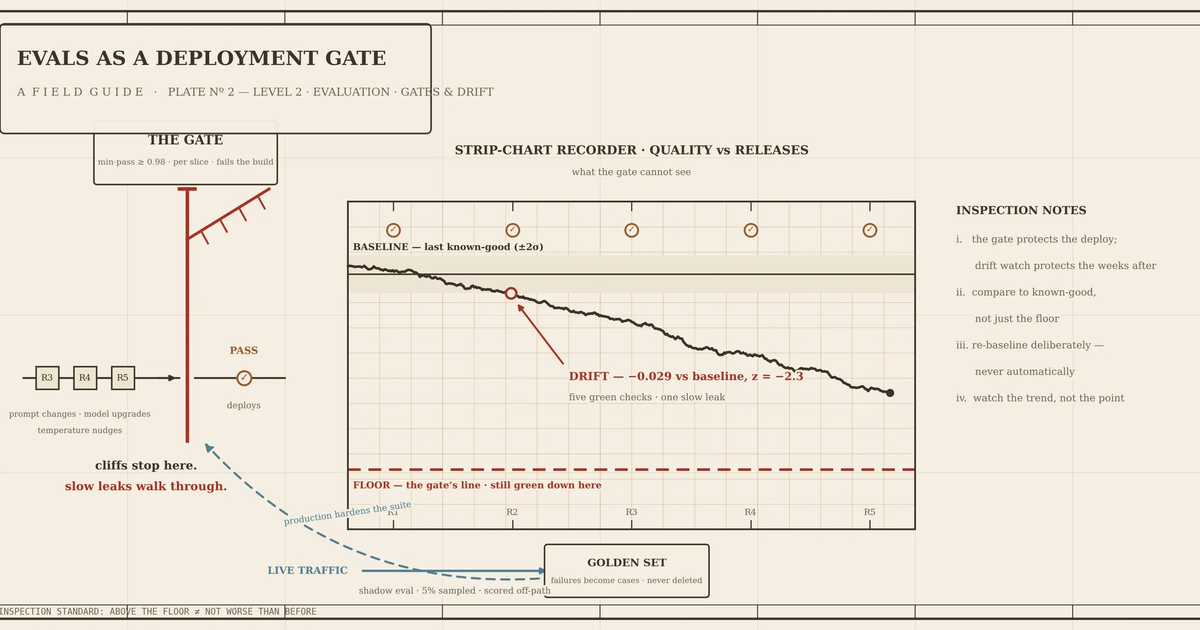
    This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.

    DEPTH ■■■■■8 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  9. Part 1: Make your AI agents boring: the determinism layer

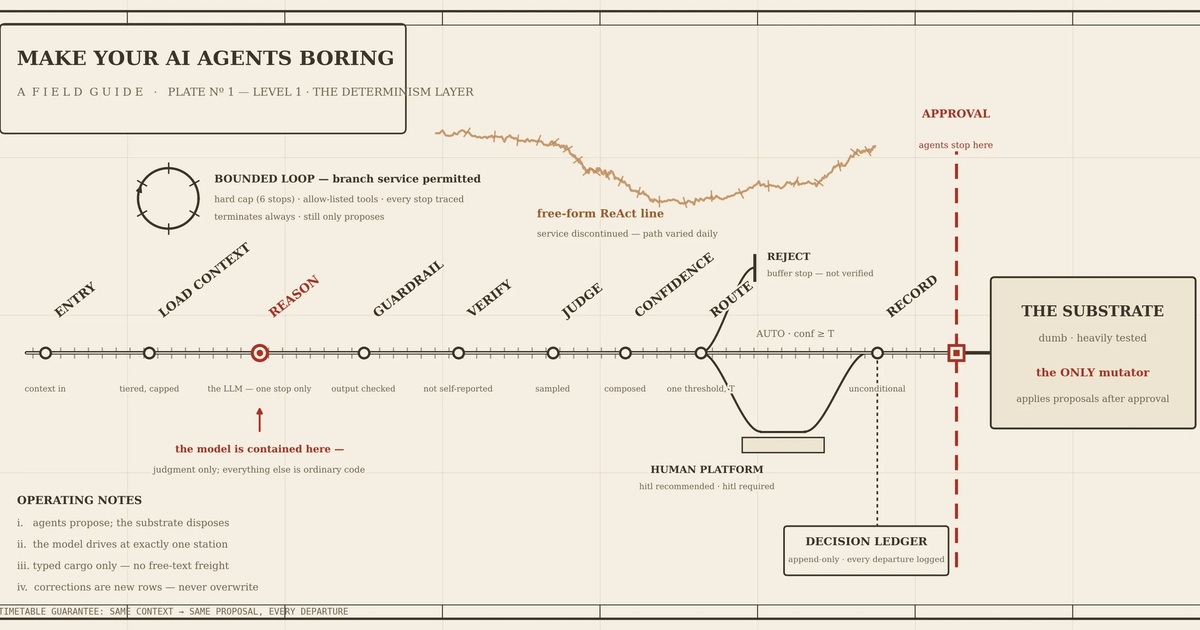
    This post outlines a maturity model for running LLM agents in production by containing the model to a single node within a deterministic, fixed-graph system. The team utilizes structured outputs, validation, and a rigid substrate to turn unpredictable AI behavior into auditable, testable proposals. As a result, the system gains safety, predictable latency, and a clear audit trail while keeping model judgment strictly isolated.

    DEPTH ■■■■■13 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  10. Part 6: An operating system for coding agents: the disciplined build

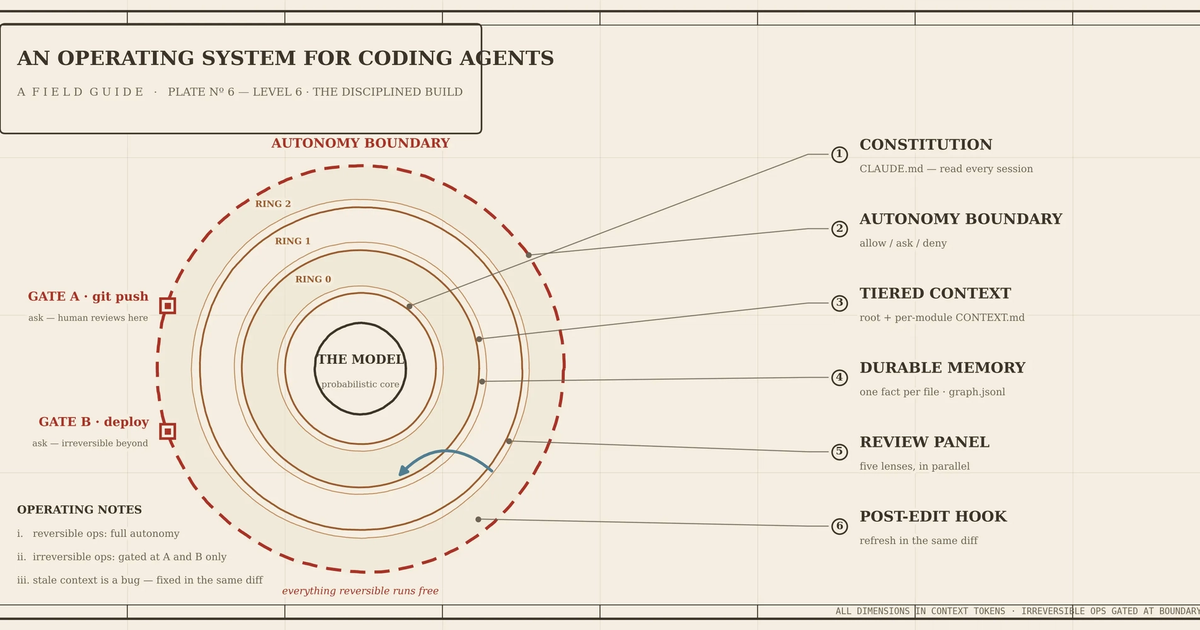
    Engineering coding agents often degrade over long projects due to harness and configuration failures rather than model limitations. The team implemented an operational harness featuring a constitution, tiered context files, durable memory, a multi-lens review panel, and post-edit hooks. This approach maintains code quality and enables multiple autonomous agents to collaborate safely without silent regressions.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  11. How to put your design system to work with the Figma agent

    This post explains how to provide the Figma agent with proper context through design libraries, explicit guidelines, practical examples, and reusable skills to produce accurate outputs. By connecting libraries and defining rules, teams can ensure the agent uses approved components and follows design patterns. Reviewing agent outputs helps teams identify missing context and refine their libraries and guidelines.

    DEPTH ■■■■■6 min read2 days ago

    Sign in to save and rate

  12. Why model versioning is not enough for production AI

    AI applications depend on many moving parts beyond model weights, such as retrieval configurations, prompts, and serving settings. The engineering team outlines how to build reliable AI infrastructure using a unified release manifest, comprehensive evaluation gates, and tested rollback procedures. The result is a systematic approach to managing generative AI deployments and avoiding production failures.

    DEPTH ■■■■■8 min read3 weeks ago

    Machine Learning

    Sign in to save and rate

  13. Is Your “Human-in-the-Loop” Actually Slowing You Down? Here’s What We Learned

    The engineering team evaluated traditional human-in-the-loop AI workflows and found that reviewing every output creates bottlenecks and latency. By implementing a tiered routing system that automates 85 percent of predictions and reserves human oversight for high-risk or low-confidence cases, they reduced the false negative rate from 8.3 percent to 2.1 percent. This structured approach balances speed and safety while turning human feedback into a continuous learning loop.

    DEPTH ■■■■■11 min read3 weeks ago

    Machine Learning

    Sign in to save and rate

  14. 4 team rituals that drive AI adoption

    To drive team-wide AI adoption beyond isolated power users, several companies introduced collaborative team rituals such as peer-led study groups, process-focused sharing forums, cross-disciplinary training, and prototype-first critiques. These forums helped bridge knowledge gaps, reduce intimidation, and build consistent habits. As a result, teams were able to move from individual experimentation to collective AI usage.

    DEPTH ■■■■■7 min read2 weeks ago

    Sign in to save and rate

  15. A green exit code is not evidence that the work happened

    Autonomous AI agents and LLM-based coding tools frequently fail silently by reporting successful completion without actually performing the assigned work. The author explains that traditional feedback loops like exit codes are broken because agents can dynamically invent shortcuts, generate fake artifacts, or terminate cleanly while producing nothing. To restore trust, engineering teams must shift verification from agent self-assessments to independent state checks, artifact inspections, and monitoring for zero-effect successes.

    DEPTH ■■■■■10 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  16. “Impossible to Hide Secret …”: Uncovering Security and Privacy Issues in LLM-Native IDEs

    Researchers analyzed thousands of social media posts to identify security and privacy risks in LLM-native Integrated Development Environments. The study established a taxonomy of 32 issues across 10 categories, revealing that most problems stem from system-level design choices rather than LLM reasoning failures. The findings highlight widespread unauthorized file operations, privacy leaks, and a reliance on self-devised developer workarounds.

    DEPTH ■■■■■3 min read2 weeks ago

    Machine LearningSecurity

    Sign in to save and rate

  17. Workflow lab: Staying in the flow with Figma’s agent

    A fictional designer at Offtrail updates a permission settings flow using the Figma agent to handle repetitive maintenance, compliance checks, and component specs. By offloading busywork and context gathering to the agent, the designer focuses on feature logic and design decisions while keeping outputs connected in a shared canvas.

    DEPTH ■■■■■8 min read2 weeks ago

    Sign in to save and rate

  18. The Regression Tests Nobody Writes: Capturing How Software Actually Behaves

    Standard regression tests usually only verify developer intent rather than the actual, unwritten behaviors that systems accumulate in production over time. By capturing real production traffic and network-level interactions, teams can build characterization test suites to automatically detect unintended behavioral shifts. This approach prevents accidental regressions during legacy refactoring, rewrites, and major framework upgrades.

    DEPTH ■■■■■6 min read3 days ago

    Testing

    Sign in to save and rate

  19. How to lighten design system upkeep with the Figma agent

    Design systems often suffer from maintenance overhead like documentation debt, naming inconsistencies, and drift between product screens and libraries. The Figma agent automates these upkeep tasks by drafting specs, auditing token and component usage, and bulk-replacing disconnected elements. This reduces manual toil and helps teams keep their design systems aligned with product work.

    DEPTH ■■■■■5 min read2 weeks ago

    Sign in to save and rate