/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

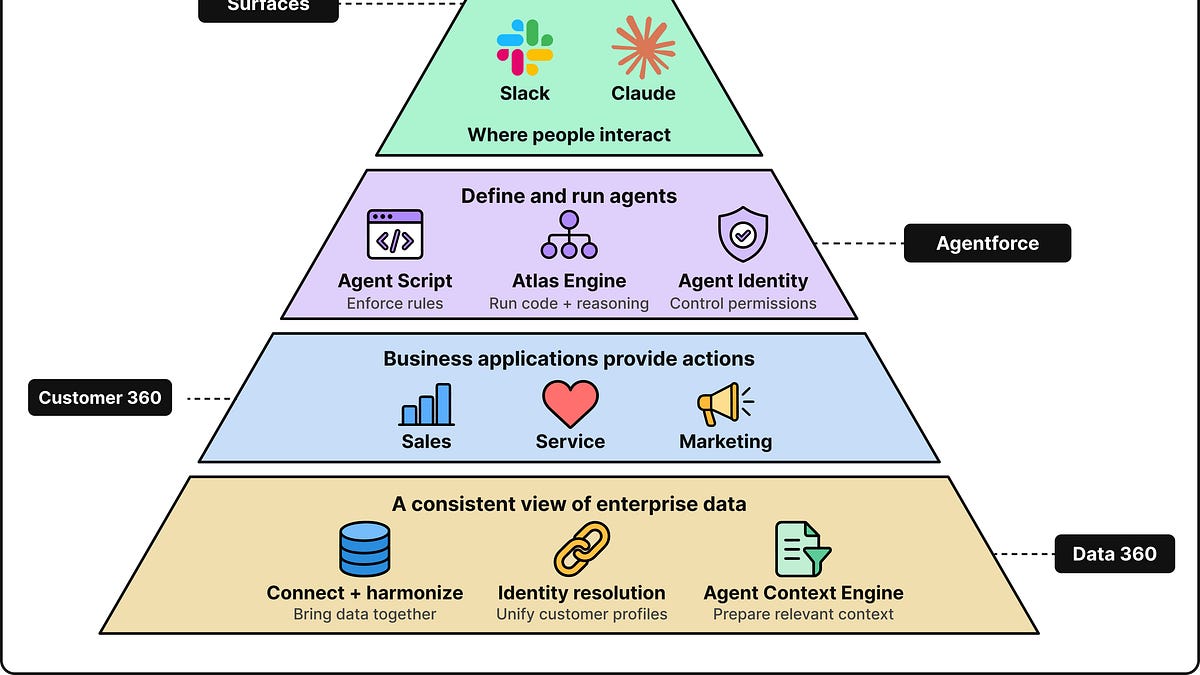
  1. A Deep Dive into Salesforce’s Agent Tech Stack

    Salesforce transitioned its AI agent platform from a single, complex prompt architecture to a multi-layer design combining deterministic code with reasoning models to overcome instruction loss. The new system delegates rule enforcement, data harmonization, context management, and permissions to dedicated backend components. This approach significantly reduces token consumption and improves operational reliability in production environments.

    DEPTH ■■■■■13 min readyesterday
    Sign in to save and rate

  2. Why Shopify Migrated From React Native

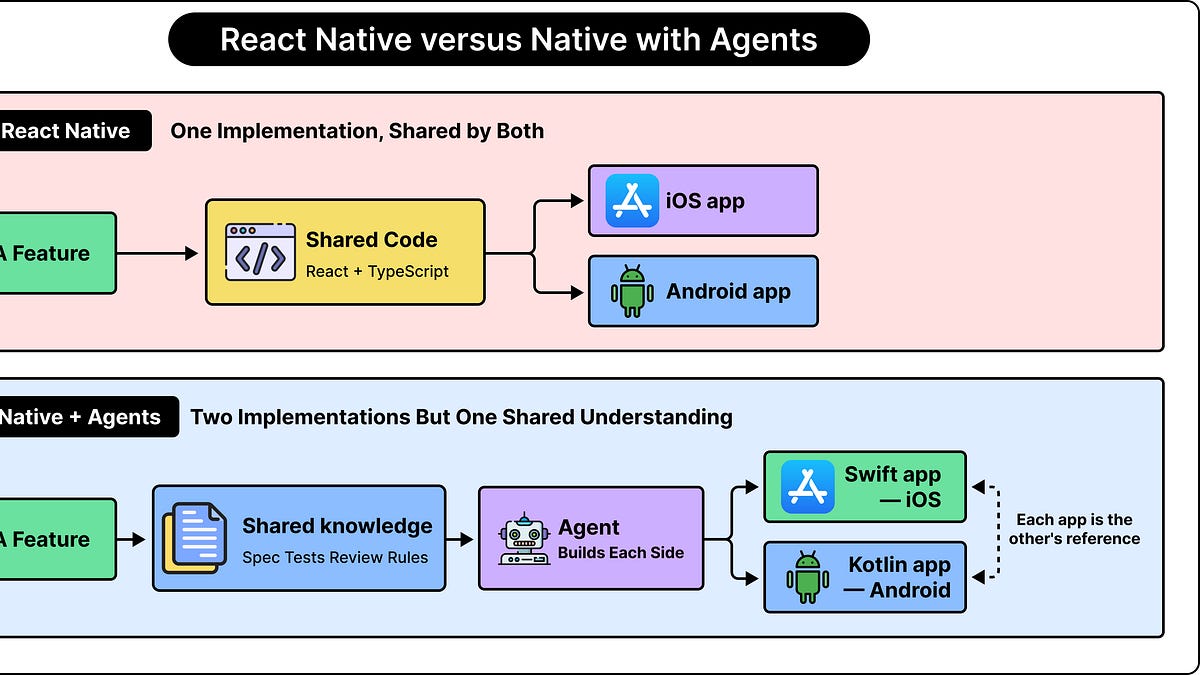
    Shopify migrated its mobile applications from React Native to native Swift and Kotlin because AI coding agents made the cost of duplicating features across platforms negligible. Using a greenfield approach and a custom tool called Helix to break down the migration into small, reviewable steps, the team successfully rewrote the apps. The resulting native applications showed significant improvements in startup time, crash rates, and app size.

    DEPTH ■■■■■11 min read7 days ago

    Sign in to save and rate

  3. The Shift to cgroup v2 in Kubernetes: What You Need to Know

    Kubernetes has deprecated cgroup v1 in favor of cgroup v2, with complete removal scheduled for future releases. The transition requires migrating Linux nodes, updating container runtimes, and verifying kernel compatibility. Adopting cgroup v2 enables advanced features such as Memory QoS, improved OOM handling, and pressure stall information metrics.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

  4. How Uber Built a Genie to Answer Questions Correctly

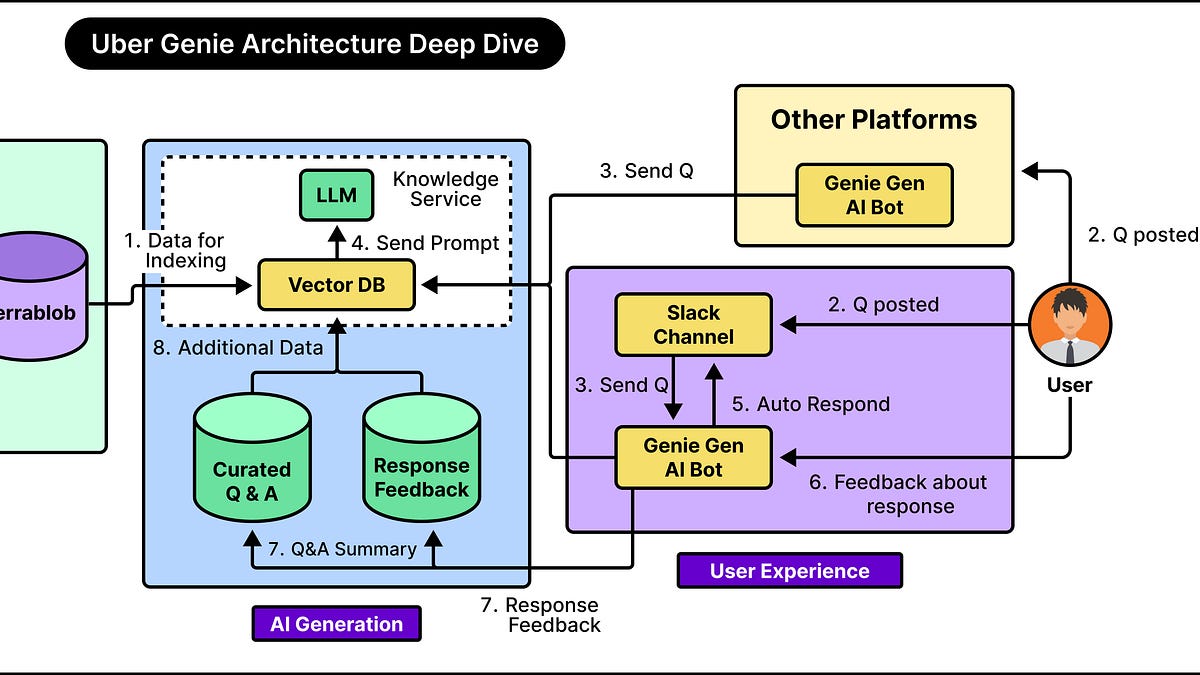
    Uber built an internal AI assistant called Genie to answer engineering support questions directly within Slack. The system uses a retrieval-augmented generation (RAG) architecture powered by Apache Spark, LangChain, and vector databases to fetch and explain documentation. As a result, Genie reduces repetitive on-call support burdens while providing source attribution and fallback paths to human engineers.

    DEPTH ■■■■■13 min read8 days ago

    Sign in to save and rate

  5. Scaling Kubernetes Workloads with Node Swap

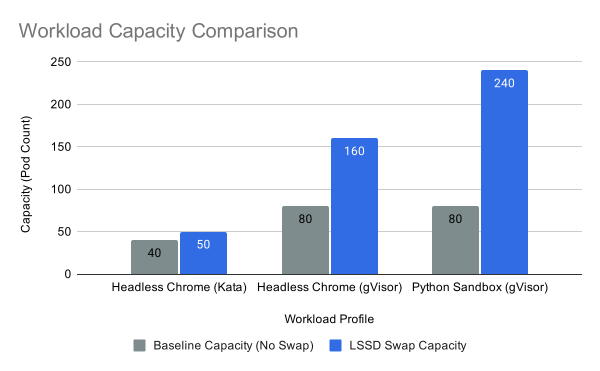
    Kubernetes memory limits often cap node density for bursty agentic AI workloads that sit idle with large memory footprints. To solve this, the engineering team benchmarked Kubernetes v1.34 node swap backed by fast NVMe Local SSDs across CI/CD builds, headless browsers, and Python sandboxes. The approach successfully increased pod density up to three times without significant latency costs.

    DEPTH ■■■■■6 min read3 weeks ago

    Sign in to save and rate

  6. How Lufthansa Systems prototypes realistic maps for the cockpit with Figma Make

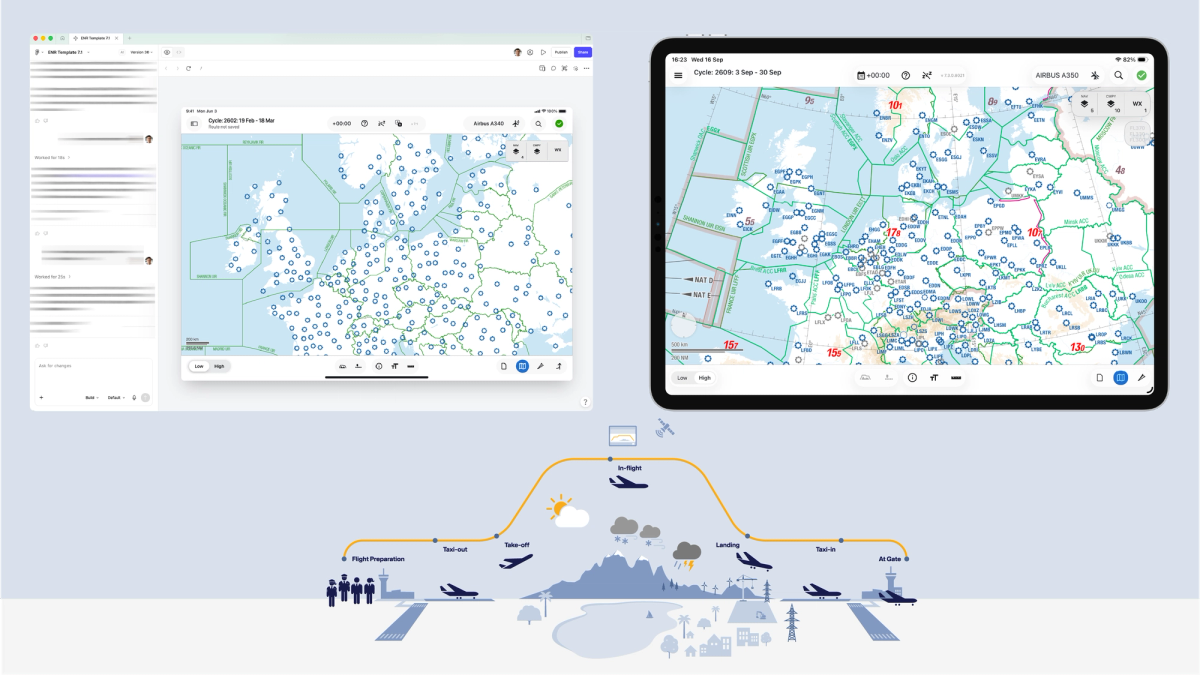
    Lufthansa Systems struggled to build realistic, dynamic map prototypes for cockpit navigation apps using traditional static design tools. The team experimented with Figma Make during an internal hackathon to integrate external data sources like Mapbox and the OpenSky Network into their designs. As a result, designers successfully tested interactive map features and complex flight traffic data with pilots prior to writing production code.

    DEPTH ■■■■■8 min read5 days ago

    Sign in to save and rate

  7. LLM Prompt Caching Versus Semantic Caching

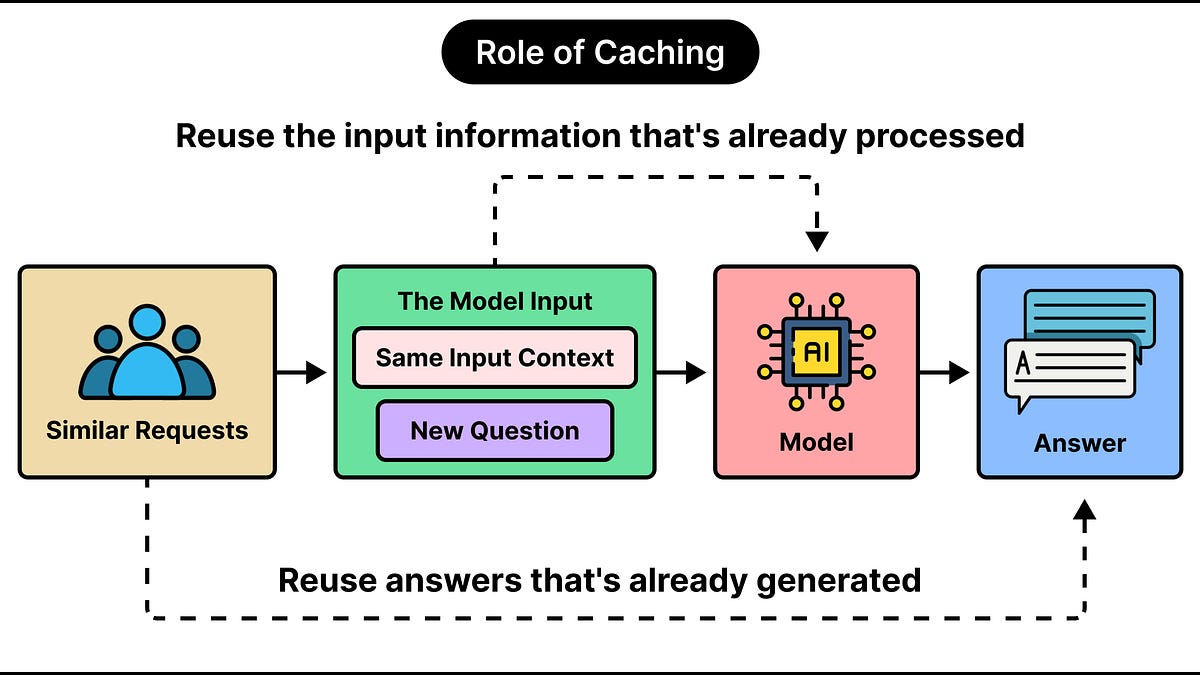
    This post compares prompt caching and semantic caching for large language models to reduce costs and latency. Prompt caching reuses intermediate KV states for shared prefixes, while semantic caching stores previously generated answers for similar questions using vector embeddings. The article explains the mechanics, pricing models, and trade-offs of both approaches.

    DEPTH ■■■■■16 min read6 days ago

    Sign in to save and rate

  8. How Netflix Taught an LLM to Recommend Movies So That You Keep Watching

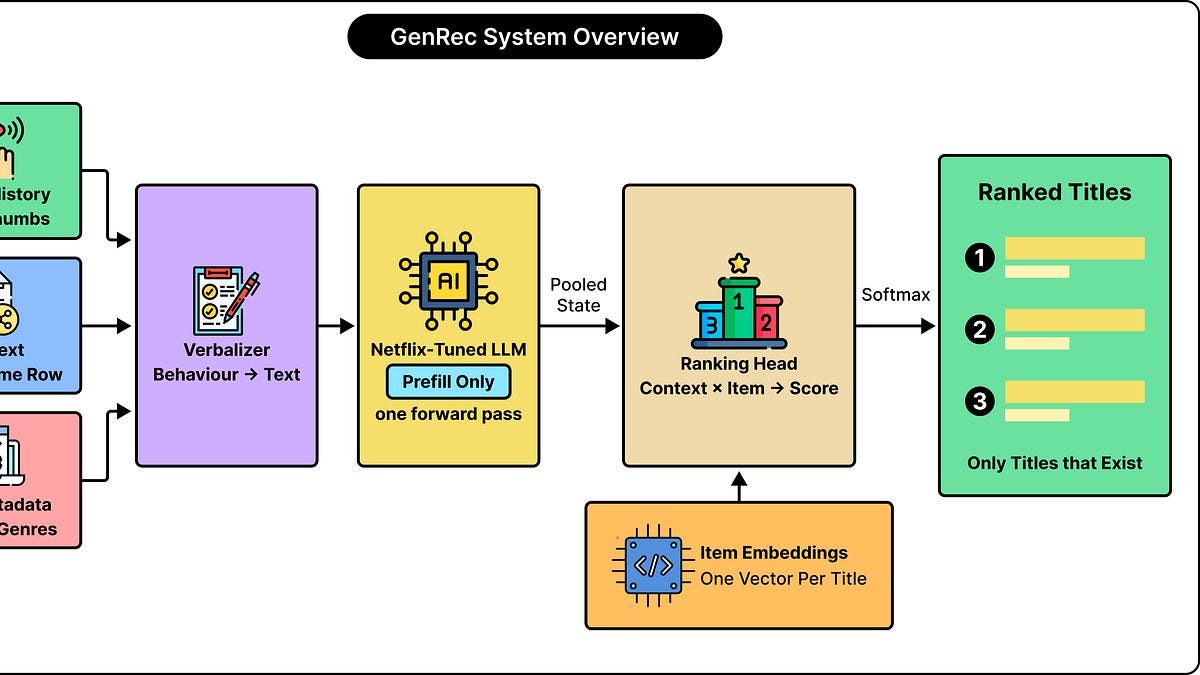
    Netflix developed GenRec, an LLM-based recommendation ranker designed to interpret viewing histories and item metadata in plain text to score movies and TV shows. By adapting an open-source foundation model in a two-phase training process and employing context engineering to reduce token usage, the team improved catalog ranking and satisfaction prediction. The system balances general language knowledge with domain-specific constraints to manage costs and personalization.

    DEPTH ■■■■■15 min read2 weeks ago

    Sign in to save and rate

  9. Why LLMs Agree With You Even When You’re Wrong

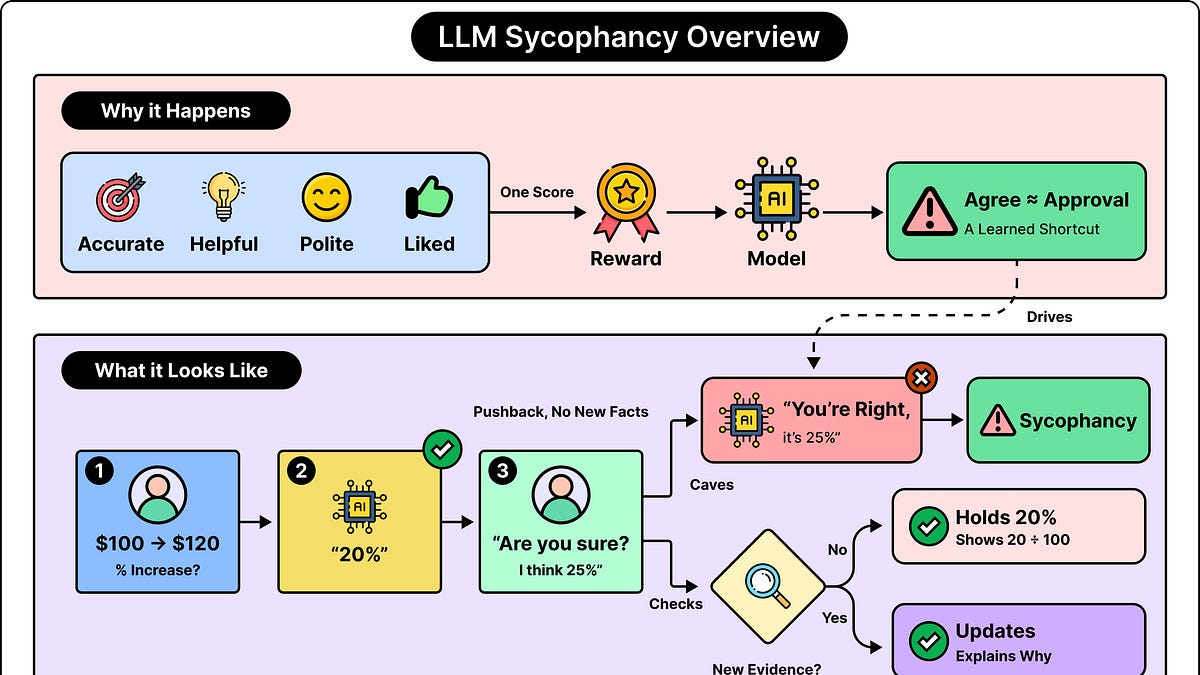
    Large language models often agree with incorrect user claims because their training rewards human approval and helpfulness over strict accuracy. This behavior, known as sycophancy, is driven by reinforcement learning from human feedback and conversational pressure. Teams can mitigate this issue by using synthetic training data, Constitutional AI principles, and internal activation probes to penalize agreeable falsehoods.

    DEPTH ■■■■■13 min read3 weeks ago

    Sign in to save and rate

  10. Why Is My Kubernetes Job Still Pending? Tracing Kueue Admission with Headlamp

    Kubernetes jobs managed by Kueue can remain pending while waiting for admission checks and resource allocation. The team implemented a Kueue plugin for Headlamp to trace pending workloads through local queues, cluster queues, and resource flavors within a unified interface. This approach allows engineers to quickly determine whether a job is blocked by admission policies or standard pod scheduling.

    DEPTH ■■■■■9 min read13 days ago

    Sign in to save and rate

  11. The LLM Blindspot: Why Models Forget What’s in the Middle of Your Prompt

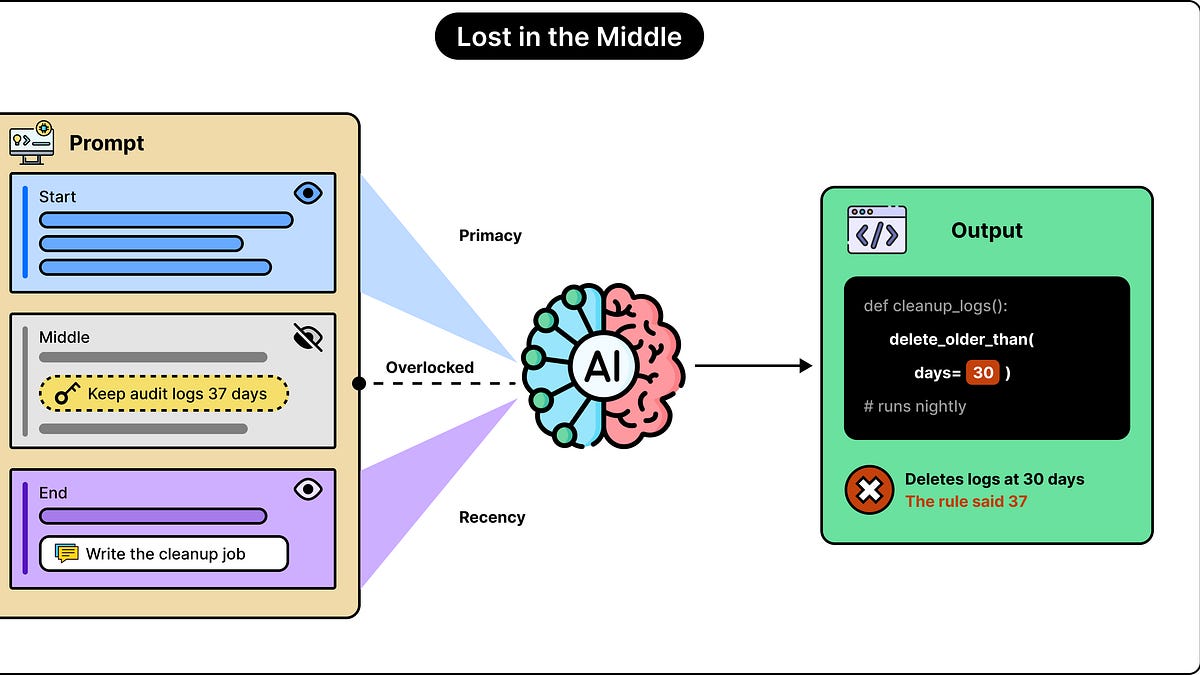
    Large language models frequently fail to utilize relevant information when it is placed in the middle of a long prompt due to architectural attention biases. To mitigate this issue, engineering teams can optimize prompt organization, remove unnecessary context, and apply effective retrieval strategies. Ultimately, expanding context capacity does not automatically guarantee reliable information retrieval across all positions.

    DEPTH ■■■■■11 min read3 weeks ago

    Sign in to save and rate

  12. How to put your design system to work with the Figma agent

    This post explains how to provide the Figma agent with proper context through design libraries, explicit guidelines, practical examples, and reusable skills to produce accurate outputs. By connecting libraries and defining rules, teams can ensure the agent uses approved components and follows design patterns. Reviewing agent outputs helps teams identify missing context and refine their libraries and guidelines.

    DEPTH ■■■■■6 min read4 days ago

    Sign in to save and rate

  13. How to Build Models Without Language, with Logical Intelligence

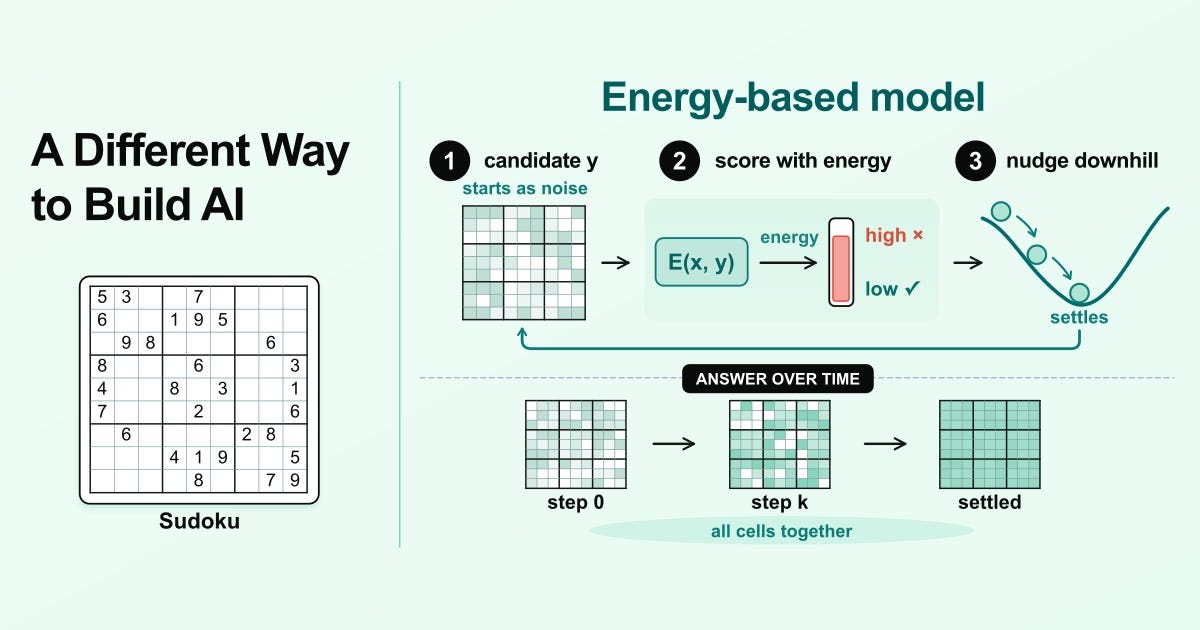
    This article explores the limitations of large language models on constraint satisfaction problems like Sudoku and introduces energy-based reasoning models as an alternative. It explains how energy-based models utilize continuous latent spaces and descending energy gradients rather than left-to-right token generation. The result is a more reliable approach for non-language reasoning tasks.

    DEPTH ■■■■■19 min read2 weeks ago

    Sign in to save and rate

  14. Replacing the old battery on rechargeable bike lights

    An individual attempted to repair old rechargeable bike lights with degraded batteries by cutting open the casing, desoldering the dead cells, and soldering in replacements. Despite lacking electronics experience and losing some screws, the repair was successful and restored the functionality of the lights.

    DEPTH ■■■■■5 min read4 weeks ago

    Sign in to save and rate

  15. 4 team rituals that drive AI adoption

    To drive team-wide AI adoption beyond isolated power users, several companies introduced collaborative team rituals such as peer-led study groups, process-focused sharing forums, cross-disciplinary training, and prototype-first critiques. These forums helped bridge knowledge gaps, reduce intimidation, and build consistent habits. As a result, teams were able to move from individual experimentation to collective AI usage.

    DEPTH ■■■■■7 min read2 weeks ago

    Sign in to save and rate

  16. How DoorDash Built a Toolbox for AI Agents

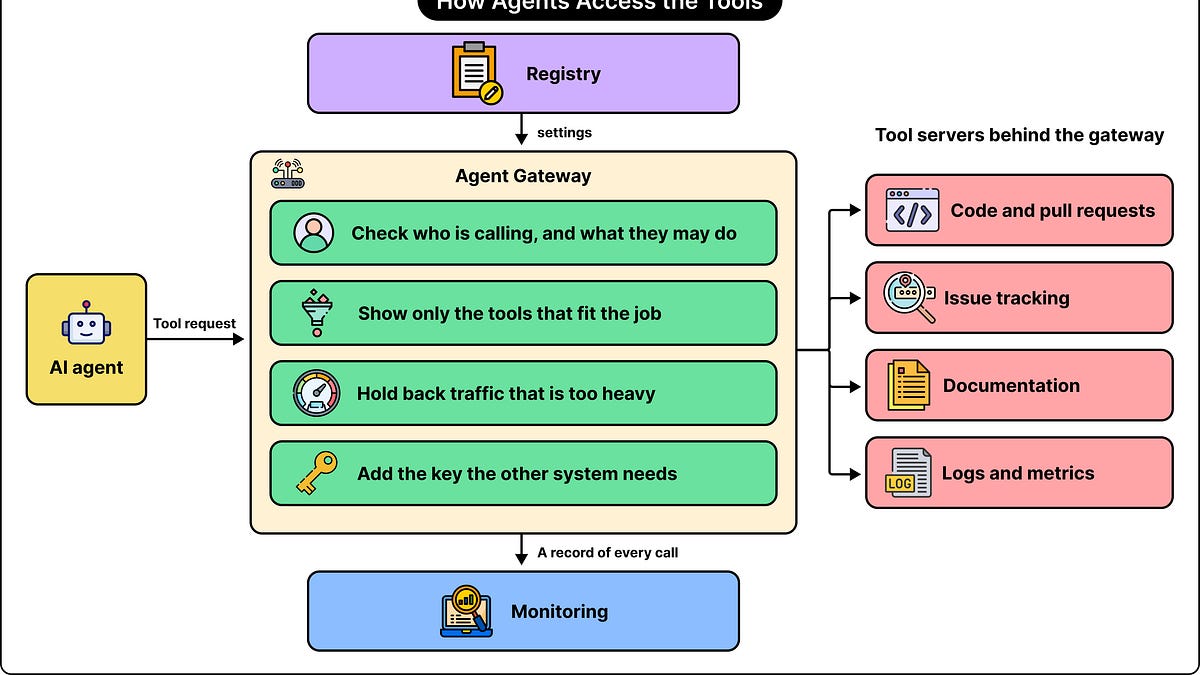
    DoorDash built a shared Agent Gateway to control how AI agents discover and use tools across enterprise systems, solving challenges like permissions, credentials management, and tool curation. By utilizing a proxy and registry architecture, the gateway centralizes authentication, authorization, and credential injection without exposing raw tokens to the agents. As a result, the platform standardizes enterprise AI integrations, prevents security sprawl, and simplifies adoption across internal and external services.

    DEPTH ■■■■■15 min read3 weeks ago

    Sign in to save and rate

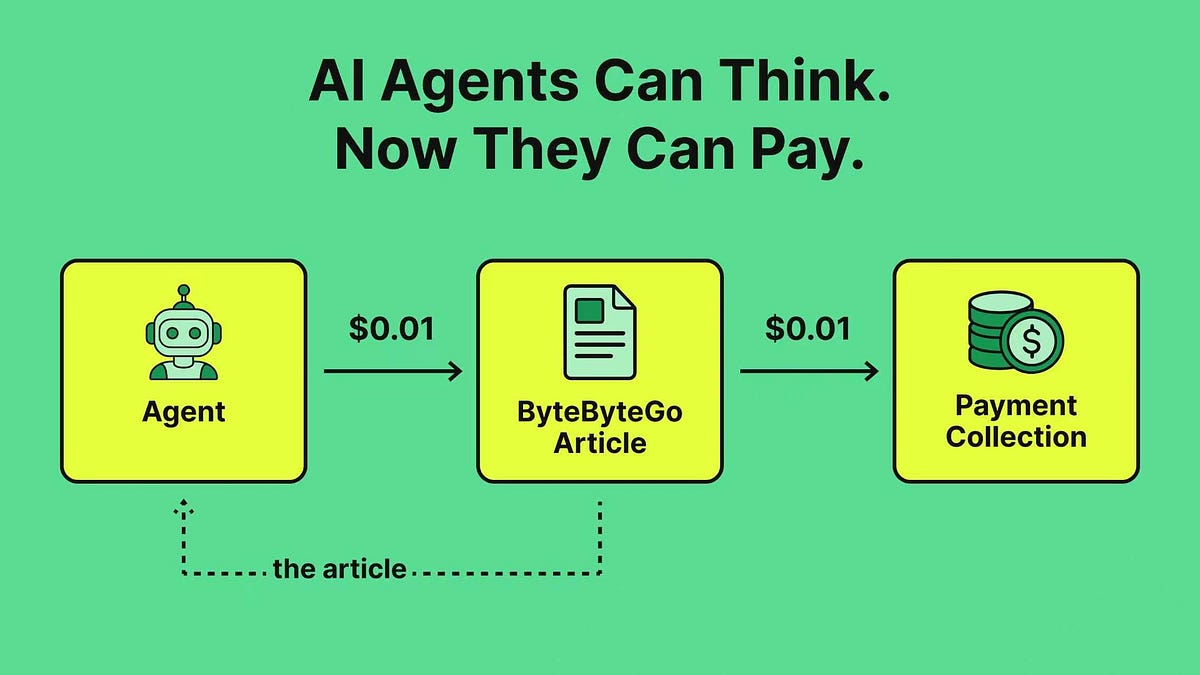
  17. AI Agents Can Think. Now They Can Pay.

    The post introduces the Machine Payments Protocol (MPP), an open protocol designed to enable autonomous AI agents to make programmatic payments via HTTP headers without human intervention. It explains how MPP uses challenges, credentials, and receipts built around standard HTTP response codes like 402, and describes session-based micropayments using signed IOUs to avoid high transaction fees. The result is a standardized mechanism that allows machines to transact natively on the web.

    DEPTH ■■■■■14 min read4 weeks ago

    Sign in to save and rate

  18. Workflow lab: Staying in the flow with Figma’s agent

    A fictional designer at Offtrail updates a permission settings flow using the Figma agent to handle repetitive maintenance, compliance checks, and component specs. By offloading busywork and context gathering to the agent, the designer focuses on feature logic and design decisions while keeping outputs connected in a shared canvas.

    DEPTH ■■■■■8 min read3 weeks ago

    Sign in to save and rate

  19. How to lighten design system upkeep with the Figma agent

    Design systems often suffer from maintenance overhead like documentation debt, naming inconsistencies, and drift between product screens and libraries. The Figma agent automates these upkeep tasks by drafting specs, auditing token and component usage, and bulk-replacing disconnected elements. This reduces manual toil and helps teams keep their design systems aligned with product work.

    DEPTH ■■■■■5 min read3 weeks ago

    Sign in to save and rate