/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. Automate medical coding with Step Functions and Amazon Bedrock AgentCore

    Automating medical coding requires a hybrid approach that combines deterministic orchestration with bounded agentic reasoning to ensure safety, auditability, and human oversight. The team built a workflow using AWS Step Functions, AWS Lambda, and Amazon Bedrock AgentCore that evaluates terms cheapest-first via block-lists, exact matching, and finally an LLM agent for ambiguous cases. This design successfully autocodes confident cases while routing ambiguous ones to human reviewers with full audit trails and decision explanations.

    DEPTH ■■■■■15 min read3 days ago
    AWS

    Sign in to save and rate

  2. App stability at scale with a layered defense

    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read4 days ago

    MobileReliability

    Sign in to save and rate

  3. Multi-region disaster recovery for Amazon API Gateway WebSocket APIs

    Real-time applications using WebSocket connections face disruptions during regional AWS outages because connections are tied to specific regions. The team implemented an active-passive multi-region disaster recovery architecture using Route 53 DNS failover, DynamoDB Global Tables, an automated canary health probe, and client-side exponential backoff with jitter. This design automatically detects failures, redirects traffic, and restores client state without manual intervention.

    DEPTH ■■■■■10 min read11 days ago

    Sign in to save and rate

  4. How UTS established a modern curriculum data services foundation on AWS

    University of Technology Sydney rearchitected its curriculum data integration using serverless AWS services to decouple systems of record from downstream consumers. By implementing domain-driven design with an event-driven architecture and purpose-built persistence layers, the team achieved zero production incidents, low latency, and reduced operational overhead while managed by a single engineer.

    DEPTH ■■■■■9 min read11 days ago

    Sign in to save and rate

  5. Powering AI-led research through simulation

    The engineering team built a self-contained simulation platform called sim-rs to model marketplace dispatch dynamics and accelerate experimentation. By connecting automated software agents to this simulator with strict safety safeguards, the team successfully optimized strategy policies and simulator performance. This closed-loop lab environment allows agents to test ideas rapidly while ensuring that only valid, production-ready improvements are produced.

    DEPTH ■■■■■10 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  6. Scope workloads and share resilience policies with AWS Resilience Hub

    Engineering teams often struggle to scope workloads and maintain up-to-date resilience policies in shared Kubernetes clusters after migrations or deployments. AWS Resilience Hub introduced features enabling Kubernetes label-based resource scoping, generative AI-powered dependency insights, and cross-account resilience policy sharing via AWS Organizations. These capabilities allow teams to isolate specific workloads, prioritize dependency investigations, and enforce centralized recovery standards.

    DEPTH ■■■■■14 min read11 days ago

    Sign in to save and rate

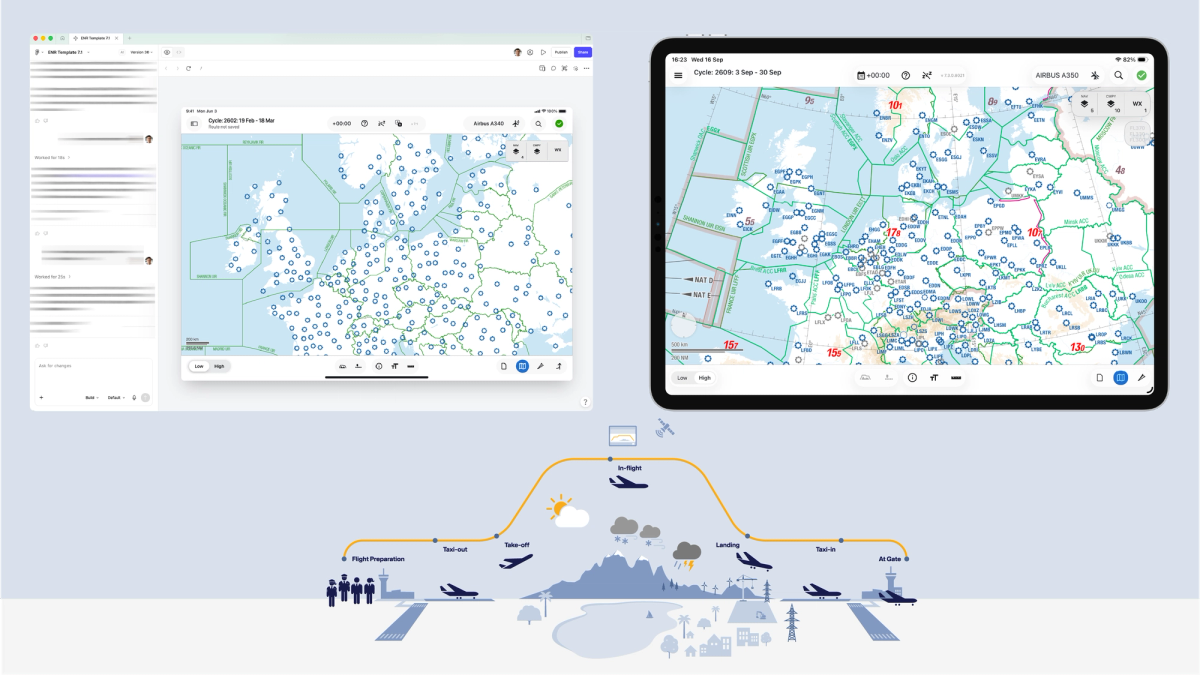
  7. How Lufthansa Systems prototypes realistic maps for the cockpit with Figma Make

    Lufthansa Systems struggled to build realistic, dynamic map prototypes for cockpit navigation apps using traditional static design tools. The team experimented with Figma Make during an internal hackathon to integrate external data sources like Mapbox and the OpenSky Network into their designs. As a result, designers successfully tested interactive map features and complex flight traffic data with pilots prior to writing production code.

    DEPTH ■■■■■8 min read3 days ago

    Sign in to save and rate

  8. Stopping business email compromise with AI-driven email security: How VIPRE protects modern enterprises on AWS

    VIPRE developed an AI-driven, cloud-native email security solution on AWS to protect enterprises against business email compromise and advanced phishing attacks. The system uses layered machine learning, semantic analysis, and dynamic sandboxing orchestrated via serverless containers and message queues to evaluate over half a million messages daily. In production testing, the architecture successfully identified thousands of BEC attempts while maintaining low-latency processing and reducing administrative overhead.

    DEPTH ■■■■■12 min read12 days ago

    Sign in to save and rate

  9. Bulk Executor for Amazon DynamoDB, Part 2: Lessons we learned the hard way

    Engineering a bulk execution tool for Amazon DynamoDB using AWS Glue required addressing several architectural challenges, including cost estimation, graceful job termination, and error handling across hundreds of parallel workers. The team overcame limitations in CloudWatch logging and the Spark connector by combining serverless execution with direct API calls and distributed rate limiting. As a result, the tool provides a scalable, script-like interface for managing large-scale table operations safely.

    DEPTH ■■■■■14 min read12 days ago

    Sign in to save and rate

  10. Agentic antimicrobial resistance surveillance with AWS HealthOmics and Amazon Bedrock AgentCore

    Processing public bacterial sequencing data for antimicrobial resistance surveillance typically requires specialized bioinformatics and SQL skills. To streamline this process, the team built a reference architecture using AWS HealthOmics, Amazon S3 Tables, and an Amazon Bedrock AgentCore conversational agent that ingests raw reads, normalizes findings, and answers plain-language questions with cited evidence. The resulting system automates the path from public accession numbers to natural-language epidemiological answers.

    DEPTH ■■■■■10 min read13 days ago

    Sign in to save and rate

  11. Smarter personalization: How property data helps us understand user price sensitivity

    Existing user personalization systems fail to systematically account for residential property values, leading to one-dimensional profiles and regional blind spots. A conceptual four-step method is proposed that combines public property data, large language models, building-level price estimation, and hierarchical clustering to classify user affluence. The approach remains unimplemented, with future viability depending on technical validation, data quality, and privacy approvals.

    DEPTH ■■■■■4 min read2 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate

  12. How to put your design system to work with the Figma agent

    This post explains how to provide the Figma agent with proper context through design libraries, explicit guidelines, practical examples, and reusable skills to produce accurate outputs. By connecting libraries and defining rules, teams can ensure the agent uses approved components and follows design patterns. Reviewing agent outputs helps teams identify missing context and refine their libraries and guidelines.

    DEPTH ■■■■■6 min read2 days ago

    Sign in to save and rate

  13. Deploy Oracle Database step by step on Amazon EVS with FSx for ONTAP

    This post provides a step-by-step guide to deploying Oracle Database 19c on Amazon Elastic VMware Service using Amazon FSx for NetApp ONTAP as an NFS datastore. It covers provisioning storage, mounting datastores, installing Oracle, configuring SnapMirror for cross-region disaster recovery, and outlining four migration paths. The result is a fully functional enterprise database deployment that preserves existing operational workflows.

    DEPTH ■■■■■11 min read3 weeks ago

    Sign in to save and rate

  14. Architect highly available Oracle Database on Amazon EVS and FSx for ONTAP

    Enterprises migrating Oracle databases to Amazon Elastic VMware Service face challenges with storage latency, disaster recovery, and operational consistency. The team designed a highly available architecture combining Amazon EVS bare metal instances with Amazon FSx for NetApp ONTAP NFS datastores and cross-region SnapMirror replication. The resulting setup delivers sub-millisecond storage latency, preserved VMware operational workflows, and robust disaster recovery capabilities.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

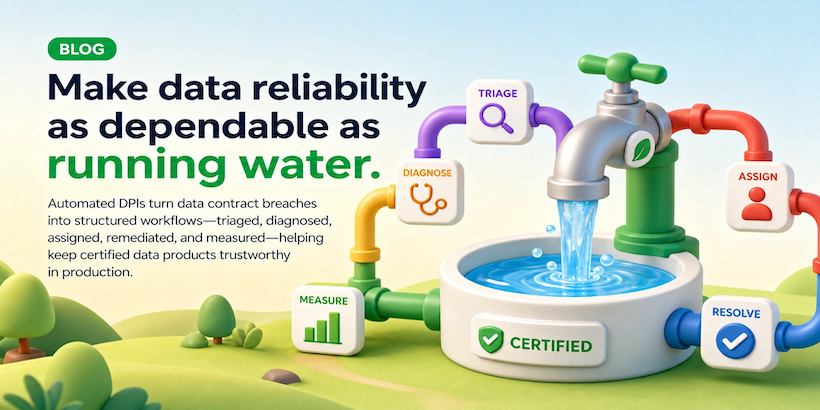
  15. Data Mesh at Grab (Part III): Operationalizing data reliability with automated DPIs

    Grab addressed runtime data reliability issues in its data mesh by implementing automated Data Production Issues (DPIs). The system uses an incident orchestrator to detect contract breaches, a Data Health API for cross-platform root cause analysis, and Hugo for automated remediation. This approach resolved 86.9 percent of incidents automatically and made mean time to resolve six times faster.

    DEPTH ■■■■■12 min read8 weeks ago

    DatabasesObservability

    Sign in to save and rate

  16. Deploy open source Regional availability tools in your VPC

    Engineering teams planning multi-Region architectures often struggle with evaluating AWS service availability and managing compliance risks. The team built and open-sourced two VPC-hosted solutions that deploy an automated Regional availability dashboard and a workload analysis pipeline using CloudTrail and CloudFormation. This setup allows organizations to securely filter and inspect the 20 to 30 services they actually use instead of hundreds.

    DEPTH ■■■■■13 min read3 weeks ago

    Sign in to save and rate

  17. Automated merchant review summary system with integrated feedback

    To help users navigate large volumes of unstructured merchant reviews, the engineering team built an automated review summary system using representative sampling, large language models, and automated quality control checks. The pipeline generates overall and topic-based summaries while incorporating maintenance triggers based on new review counts and consumer feedback. This approach reduces the text consumers need to scan while ensuring claims remain grounded in source data.

    DEPTH ■■■■■5 min read4 weeks ago

    Machine Learning

    Sign in to save and rate

  18. 4 team rituals that drive AI adoption

    To drive team-wide AI adoption beyond isolated power users, several companies introduced collaborative team rituals such as peer-led study groups, process-focused sharing forums, cross-disciplinary training, and prototype-first critiques. These forums helped bridge knowledge gaps, reduce intimidation, and build consistent habits. As a result, teams were able to move from individual experimentation to collective AI usage.

    DEPTH ■■■■■7 min read2 weeks ago

    Sign in to save and rate

  19. Accelerating airline retailing innovation: how Datalex modernized with AWS Experience-Based Acceleration and agentic AI

    Datalex partnered with AWS for a three-day Experience-Based Acceleration workshop to modernize its mission-critical airline retail platform from Java 8 and EJB2 to Spring Boot on Java 21. The team used parallel workstreams and agentic AI to prove migration feasibility, implement automated CI/CD pipelines, and integrate generative AI capabilities without disrupting existing airline operations. This effort successfully established repeatable migration patterns, reduced memory usage by 35%, and accelerated the timeline for long-term platform evolution.

    DEPTH ■■■■■14 min read3 weeks ago

    Sign in to save and rate