/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. App stability at scale with a layered defense

    To maintain app stability amidst rapid weekly releases and AI-generated code, Grab uses a layered defense strategy covering prevention, release gates, and incident response. This pipeline includes static analysis via custom lint rules, multiple tiers of automated and manual testing, a pre-production early access build, staged rollouts, and feature flags with instant kill switches. As a result, critical defects are caught early in the development lifecycle before reaching the wider production user base.

    DEPTH ■■■■■16 min read4 days ago
    MobileReliability

    Sign in to save and rate

  2. Beyond container image signing: How we enforce software supply chain policies at Datadog

    Container image signing alone cannot detect upstream security compromises occurring before the image is signed. To address this, the engineering team built an internal system called Turnstile that generates cryptographically signed attestations across an artifact's life cycle and evaluates them against environment-specific policies at deployment time. This approach enables the organization to enforce strict security and compliance requirements at scale without disrupting developer workflows.

    DEPTH ■■■■■15 min read5 days ago

    Sign in to save and rate

  3. When Software Meets Hardware

    A software engineering team modernizing a large-scale retail IoT system of 800,000 battery-powered sensors faced challenges integrating software practices with embedded hardware. By building physical sensor farms, virtual emulators, and self-diagnosing firmware, the team learned to design for intermittent connectivity, power efficiency, and fleet-level observability. The project succeeded by treating the physical world, hardware constraints, and engineering environments as core parts of the system lifecycle.

    DEPTH ■■■■■12 min read10 days ago

    Sign in to save and rate

  4. Are Harnesses Worth the Cost?

    An experiment was conducted to evaluate whether behavioral harnesses improve coding agent reliability when building a complex backend-for-frontend service. While frontier models succeeded consistently with or without a harness, the harness significantly increased token usage, time, and cost without improving final output. However, for a cost-optimized model, the harness improved success rates from 30 percent to 100 percent.

    DEPTH ■■■■■17 min read12 days ago

    Sign in to save and rate

  5. Powering AI-led research through simulation

    The engineering team built a self-contained simulation platform called sim-rs to model marketplace dispatch dynamics and accelerate experimentation. By connecting automated software agents to this simulator with strict safety safeguards, the team successfully optimized strategy policies and simulator performance. This closed-loop lab environment allows agents to test ideas rapidly while ensuring that only valid, production-ready improvements are produced.

    DEPTH ■■■■■10 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  6. How we extended Apache DataFusion to execute one query across many machines

    Datadog needed to execute interactive queries across large datasets that exceeded single-node limits while maintaining low latency. To solve this, the team built Distributed DataFusion, an open-source framework extending Apache DataFusion across multiple machines using zero-copy streaming via Apache Arrow and Substrait. As a result, heavy queries complete up to 10 times faster without imposing distribution overhead on lightweight queries.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

  7. How we built an async-aware Python profiler

    Traditional Python profilers treat asyncio tasks as independent stacks, obscuring logical execution paths and relationships. The Datadog team built an async-aware profiling model that tracks task dependencies to reconstruct unified execution paths ("stacked stacks") while reducing profiling overhead by over 60 percent. This approach provides clearer performance visibility for asynchronous applications without excessive production latency.

    DEPTH ■■■■■19 min read3 weeks ago

    Sign in to save and rate

  8. Fragments: October 21

    This post discusses commentary on AI usage in writing, the cancellation of the Grace Hopper Celebration, and reviews a detailed article by Cindy Sridharan on debugging with AI agents. The reviewed article highlights that AI agents excel at processing raw data rather than reading code first, and outlines a three-step debugging process involving controls, signals, and hypothesis validation. The lesson is that engineers must guide AI agents by setting up verification loops and providing raw data rather than human-centric abstractions.

    DEPTH ■■■■■5 min read4 days ago

    Sign in to save and rate

  9. Practitioner Voice: The Writing Category Nobody has Named Yet

    The author explores a missing category of writing called Practitioner Voice, which is grounded in earned experience and visible personal judgment rather than academic rigor, corporate polish, or AI generation. They examine how AI can be used as an extended cognitive tool for practitioners without losing human accountability. Ultimately, the piece argues that maintaining personal judgment and consequence-bearing experience is essential for authentic professional writing.

    DEPTH ■■■■■39 min read12 days ago

    Sign in to save and rate

  10. Smarter personalization: How property data helps us understand user price sensitivity

    Existing user personalization systems fail to systematically account for residential property values, leading to one-dimensional profiles and regional blind spots. A conceptual four-step method is proposed that combines public property data, large language models, building-level price estimation, and hierarchical clustering to classify user affluence. The approach remains unimplemented, with future viability depending on technical validation, data quality, and privacy approvals.

    DEPTH ■■■■■4 min read2 weeks ago

    Data EngineeringMachine Learning

    Sign in to save and rate

  11. Making Rust observability reliable at scale with OpenTelemetry

    Datadog engineers faced inconsistent tracing, broken spans, and context loss across Rust services due to fragmented tooling and unopinionated OpenTelemetry configurations. To fix this, they contributed upstream to OpenTelemetry to improve interoperability and built an opinionated Rust tracing library called dd-trace-rs. This reduced backend ingestion volume by 20x while increasing the rate of indexed spans per service by 3x.

    DEPTH ■■■■■10 min read7 weeks ago

    Sign in to save and rate

  12. Fragments: October 4

    This post discusses the evolving role of software development and code in the era of large language models. It explores how shifting from deterministic building to inferential nurturing changes processes, why high-level representations remain critical for managing context windows, and how conceptual modeling becomes more important than the mechanical act of writing instructions.

    DEPTH ■■■■■7 min read2 weeks ago

    Sign in to save and rate

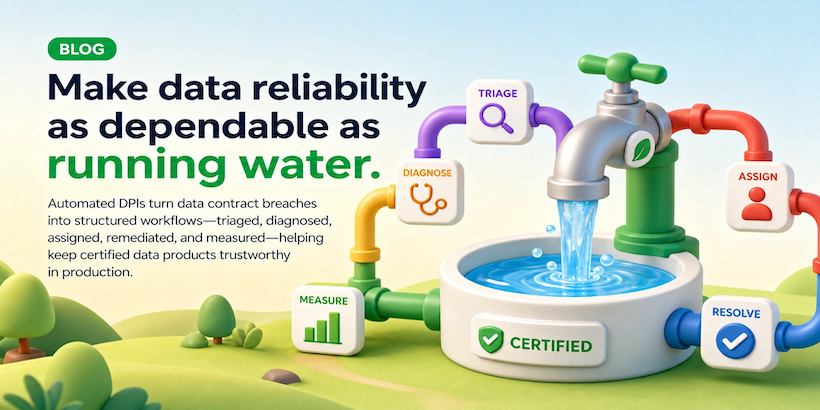
  13. Data Mesh at Grab (Part III): Operationalizing data reliability with automated DPIs

    Grab addressed runtime data reliability issues in its data mesh by implementing automated Data Production Issues (DPIs). The system uses an incident orchestrator to detect contract breaches, a Data Health API for cross-platform root cause analysis, and Hugo for automated remediation. This approach resolved 86.9 percent of incidents automatically and made mean time to resolve six times faster.

    DEPTH ■■■■■12 min read8 weeks ago

    DatabasesObservability

    Sign in to save and rate

  14. Automated merchant review summary system with integrated feedback

    To help users navigate large volumes of unstructured merchant reviews, the engineering team built an automated review summary system using representative sampling, large language models, and automated quality control checks. The pipeline generates overall and topic-based summaries while incorporating maintenance triggers based on new review counts and consumer feedback. This approach reduces the text consumers need to scan while ensuring claims remain grounded in source data.

    DEPTH ■■■■■5 min read4 weeks ago

    Machine Learning

    Sign in to save and rate

  15. Principles for effective slides

    Presenters often rely on text-heavy slide decks that distract audiences and undermine storytelling. To fix this, speakers can use minimalist slides as a complementary visual channel to control the rate of information and manage cognitive load. This approach leads to more engaging presentations where visuals reinforce the spoken narrative rather than replace it.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

  16. GrabMart data for faster disease outbreak detection

    The organization proposes a conceptual data pipeline to analyze aggregated GrabMart transaction data for symptom-related product demand, aiming to supplement clinical surveillance for disease outbreaks. The design relies on data aggregation, statistical baseline comparisons, and privacy safeguards like differential privacy without involving individual health inference. The system remains in an early planning phase requiring rigorous validation, privacy review, and public health oversight.

    DEPTH ■■■■■5 min read12 days ago

    Data EngineeringMachine Learning

    Sign in to save and rate

  17. Build your slide template

    Presenters often struggle with the visual design of slides and default to cluttered or uniform corporate templates. To build a better presentation foundation, the author recommends sticking to a restricted color palette, limiting the number of fonts, and using minimal layouts without unnecessary floodmarks like page numbers or logos. This approach results in a cohesive visual identity that provides greater flexibility during slide construction.

    DEPTH ■■■■■11 min read11 days ago

    Sign in to save and rate

  18. Bliki: Sensible Default

    The engineering post introduces the concept of a sensible default as an alternative to best practices in software development. Sensible defaults serve as reliable starting points for tasks in the absence of hard constraints, while still allowing teams to adapt and override them when context requires. Organizations like Thoughtworks utilize playbooks of these defaults to guide initial work while encouraging regular reflection and adjustment.

    DEPTH ■■■■■2 min read3 weeks ago

    Sign in to save and rate

  19. Fragments: September 29

    This post discusses observations on coding agents, focusing on their persistence, the role of training material in hacking behavior, and the need for greater safety measures and liability. It examines experiments with unlimited tokens and explores regulatory and educational perspectives on agentic AI.

    DEPTH ■■■■■4 min read3 weeks ago

    Sign in to save and rate