/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

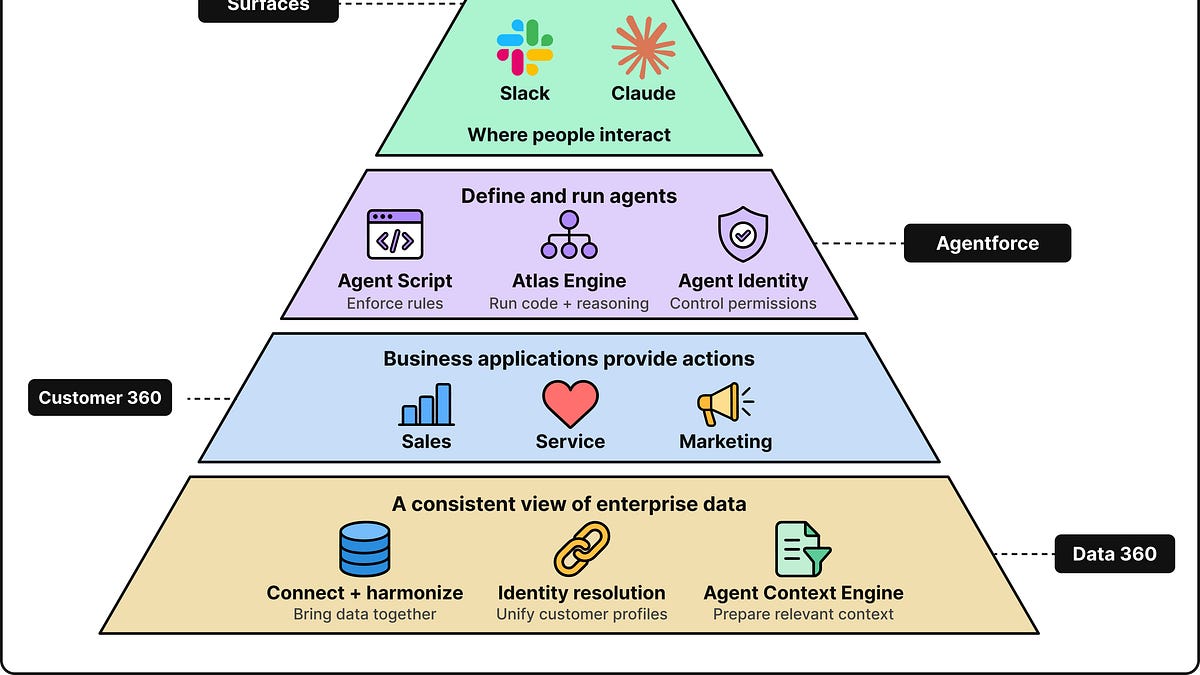
  1. A Deep Dive into Salesforce’s Agent Tech Stack

    Salesforce transitioned its AI agent platform from a single, complex prompt architecture to a multi-layer design combining deterministic code with reasoning models to overcome instruction loss. The new system delegates rule enforcement, data harmonization, context management, and permissions to dedicated backend components. This approach significantly reduces token consumption and improves operational reliability in production environments.

    DEPTH ■■■■■13 min readyesterday
    Sign in to save and rate

  2. Origin Range Requests: Serving large files without range-request tuning

    Cloudflare replaced a legacy, fixed-size range caching design that suffered from bandwidth waste and memory pressure with a Pingora-based chunk coordinator. The new implementation dynamically combines cached chunks and aligned origin fetches to serve range requests accurately without manual tuning. This approach cut p99 time to first byte in half for R2 storage and reduced tiered cache traffic by six percent.

    DEPTH ■■■■■8 min read4 days ago

    DatabasesPerformanceRedis

    Sign in to save and rate

  3. We gave AI agents a mobile dev environment

    Engineering teams outgrew their local machines while running parallel AI mobile development agents, constrained by heavy builds and lack of iOS tools on Linux. To solve this, they built Remote Dev using warm pools of remote Macs connected via SSH alongside separate Linux VMs for Android virtualization, paired with agent skills and live browser streaming. This setup shifted workflow bottlenecks, increasing AI-merged pull requests from 6 percent to 61 percent.

    DEPTH ■■■■■9 min read5 days ago

    ArchitectureMobile

    Sign in to save and rate

  4. Bringing post-quantum cryptography to geographically fenced key management

    Cloudflare introduced a post-quantum geographically restricted key manager in closed beta to enforce data sovereignty and protect customers against harvest-now-decrypt-later attacks. The team implemented a hybrid ML-KEM-768 and X25519 cryptographic design that separates globally distributed wrapped private keys from regionally restricted root keys. This ensures that decryption keys are only accessible within authorized geographical boundaries and fails closed if validation fails.

    DEPTH ■■■■■12 min read4 days ago

    Security

    Sign in to save and rate

  5. How Shopify turns open models into task experts

    Shopify uses a continual learning flywheel to post-train open models, such as NVIDIA Nemotron, to serve as dedicated subagents for specific tasks like GraphQL generation. By optimizing inference and utilizing automated self-healing to generate training data from production failures, the team successfully created task experts that outperform frontier models while reducing serving costs by 90-98% and improving response times.

    DEPTH ■■■■■5 min read6 days ago

    Architecture

    Sign in to save and rate

  6. Why Shopify Migrated From React Native

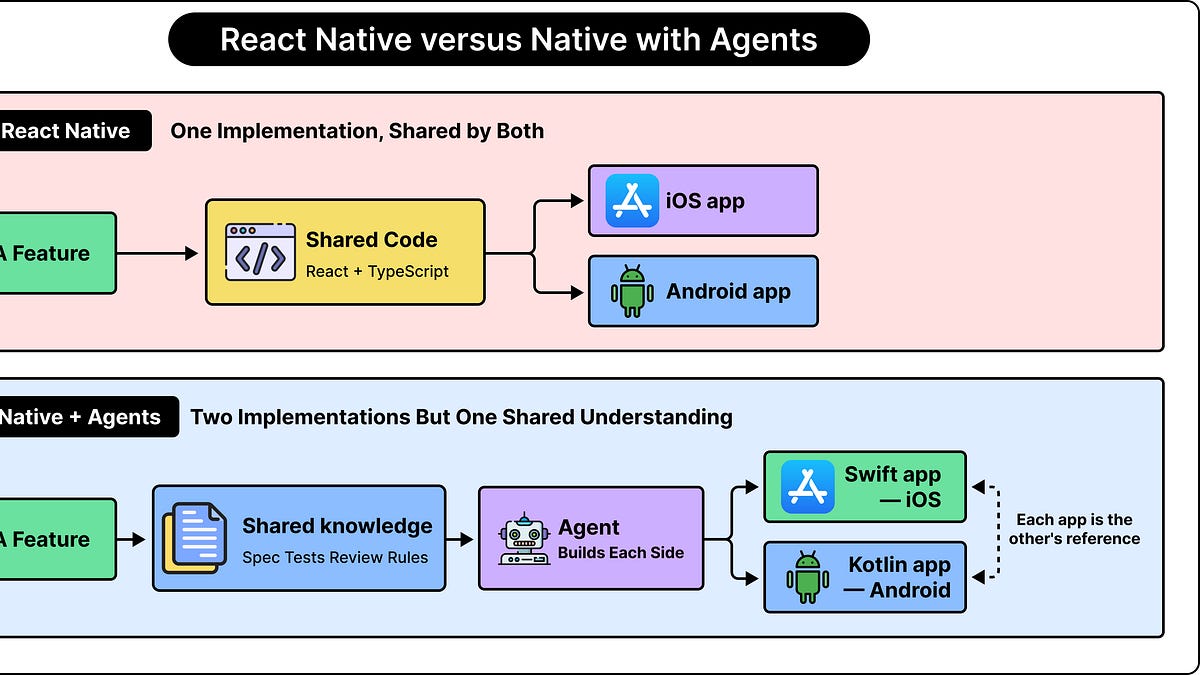
    Shopify migrated its mobile applications from React Native to native Swift and Kotlin because AI coding agents made the cost of duplicating features across platforms negligible. Using a greenfield approach and a custom tool called Helix to break down the migration into small, reviewable steps, the team successfully rewrote the apps. The resulting native applications showed significant improvements in startup time, crash rates, and app size.

    DEPTH ■■■■■11 min read7 days ago

    Sign in to save and rate

  7. Cross-store product clustering across millions of stores

    Shopify needed to group identical product listings from millions of different merchants under a single global identifier. To solve this at scale without comparing every possible pair, the team implemented a multi-stage pipeline using vector retrieval, a tiered scoring system of ML models, and a bounded graph clustering approach. This architecture successfully standardizes product data across the entire platform while controlling computational costs.

    DEPTH ■■■■■13 min read7 days ago

    Architecture

    Sign in to save and rate

  8. Cutting our inference bill by 68% by being obsessive about optimization

    An engineering team investigated a steady rise in AI code review costs and found that cache misses and redundant model calls were driving up expenses. By restructuring system prompts to enable cross-repository prompt caching, eliminating wasted tool calls, and switching to more efficient models, the team cut inference costs by 68% while also significantly improving review latency.

    DEPTH ■■■■■15 min read8 days ago

    Machine Learning

    Sign in to save and rate

  9. How Uber Built a Genie to Answer Questions Correctly

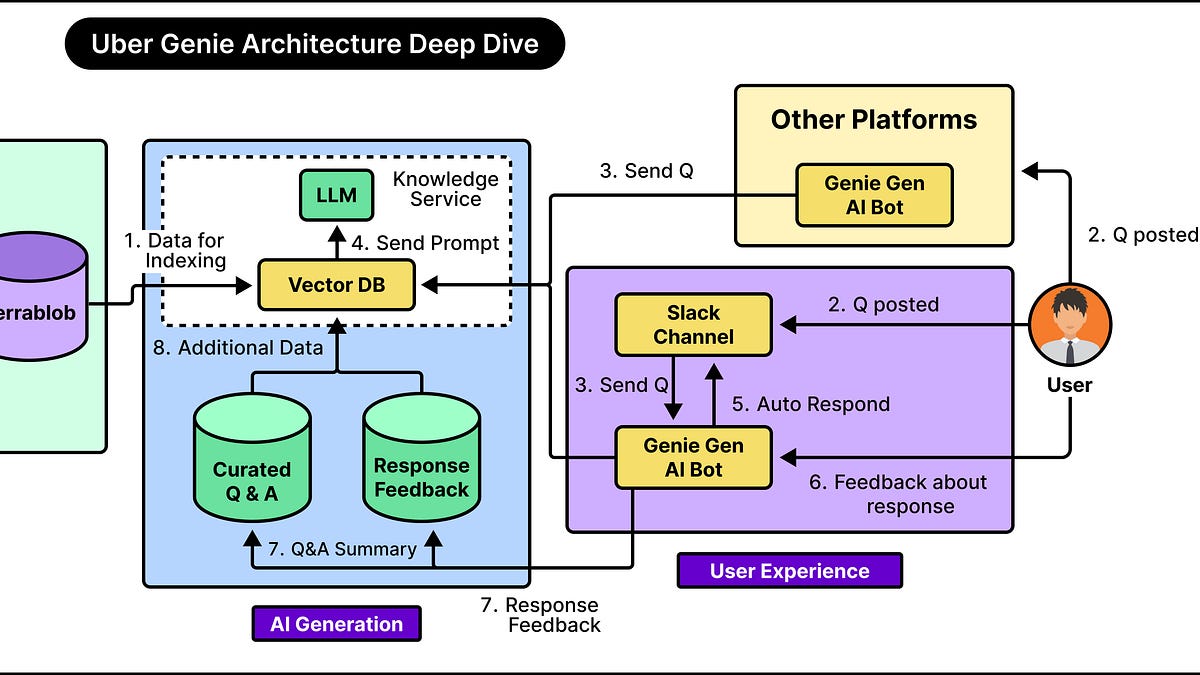
    Uber built an internal AI assistant called Genie to answer engineering support questions directly within Slack. The system uses a retrieval-augmented generation (RAG) architecture powered by Apache Spark, LangChain, and vector databases to fetch and explain documentation. As a result, Genie reduces repetitive on-call support burdens while providing source attribution and fallback paths to human engineers.

    DEPTH ■■■■■13 min read8 days ago

    Sign in to save and rate

  10. Building Overexposed: understanding application exposure

    The team built an automated scanner called Overexposed to track internet-facing services and verify access controls across Kubernetes and Cloud Run. By querying live cloud inventories and probing endpoints like an outsider, the scanner classifies exposure while avoiding false assumptions from static config files. As a result, the engineering organization improved accuracy and significantly reduced inconclusive findings over time.

    DEPTH ■■■■■8 min read7 days ago

    Sign in to save and rate

  11. Yandex outage: Data shows that instead of going dark, malicious bots went on the move

    Following physical strikes on Yandex data centers, overall HTTP traffic from the network dropped significantly, leading to speculation that malicious bot farms had been disabled. However, traffic analysis revealed that search crawling simply decreased while malicious automation quickly migrated to other hosting providers with identical fingerprints. Consequently, overall malicious bot traffic remained flat, demonstrating that network disruptions do not stop portable automated workloads.

    DEPTH ■■■■■8 min read12 days ago

    Incidents & Postmortems

    Sign in to save and rate

  12. LLM Prompt Caching Versus Semantic Caching

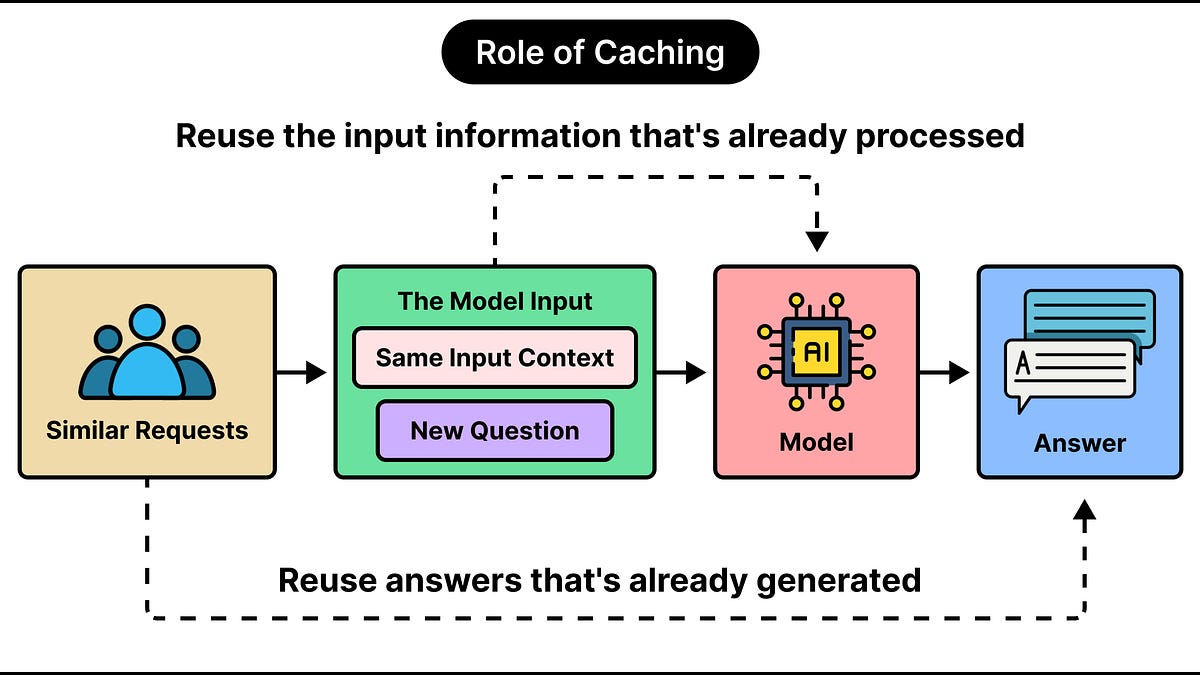
    This post compares prompt caching and semantic caching for large language models to reduce costs and latency. Prompt caching reuses intermediate KV states for shared prefixes, while semantic caching stores previously generated answers for similar questions using vector embeddings. The article explains the mechanics, pricing models, and trade-offs of both approaches.

    DEPTH ■■■■■16 min read6 days ago

    Sign in to save and rate

  13. Inside Hyperdrive: How we solved a rare Hyperdrive MySQL caching bug

    During the beta of MySQL support for Hyperdrive, engineers investigated rare empty query responses and connection hangs occurring in 0.001% of requests. They discovered that sharing the data center cache between client and endpoint nodes caused protocol capability mismatches when translating MySQL wire messages. The team resolved the issue by standardizing the cache to always store responses encoded with canonical Hyperdrive capabilities.

    DEPTH ■■■■■9 min read13 days ago

    MySQL

    Sign in to save and rate

  14. Front-End Web Deep Dive: Runtime Config

    Front-end web applications traditionally bake environment variables into build artifacts, requiring a full rebuild to change configurations across environments. To solve this, a new approach injects runtime environment variables directly into the HTML document's head element as data attributes via a Cloud Native Buildpack. This enables zero-rebuild configuration changes while remaining compatible with browser security standards like CSP.

    DEPTH ■■■■■3 min read12 days ago

    Frontend

    Sign in to save and rate

  15. How Netflix Taught an LLM to Recommend Movies So That You Keep Watching

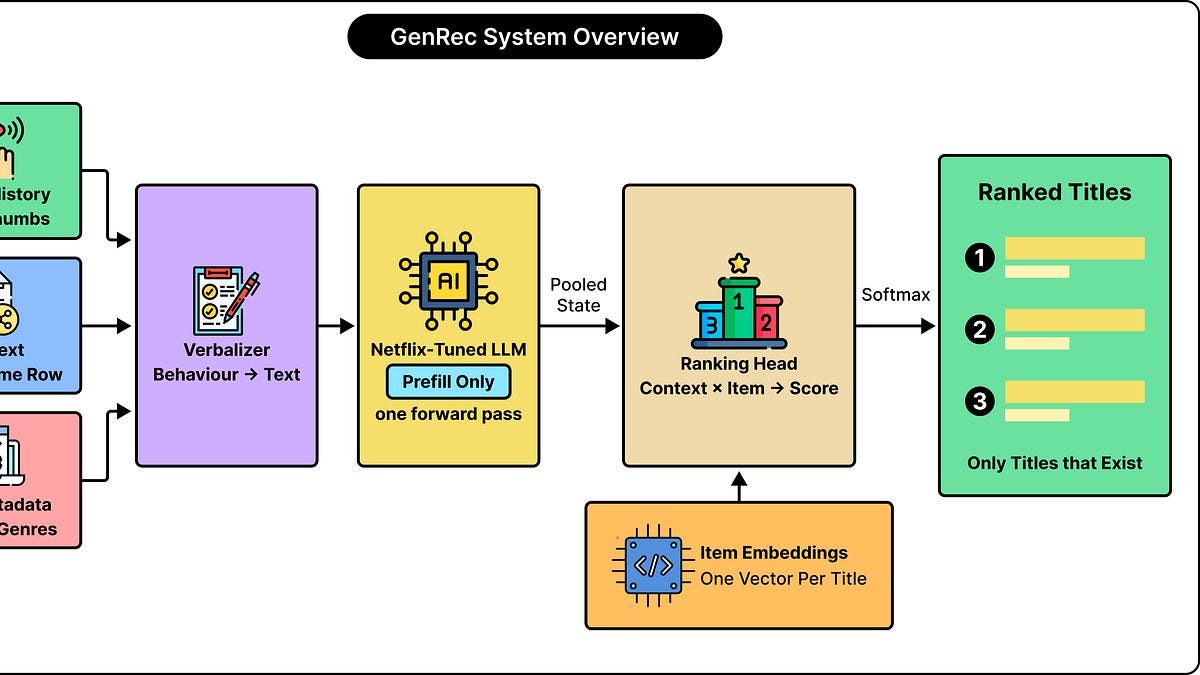
    Netflix developed GenRec, an LLM-based recommendation ranker designed to interpret viewing histories and item metadata in plain text to score movies and TV shows. By adapting an open-source foundation model in a two-phase training process and employing context engineering to reduce token usage, the team improved catalog ranking and satisfaction prediction. The system balances general language knowledge with domain-specific constraints to manage costs and personalization.

    DEPTH ■■■■■15 min read2 weeks ago

    Sign in to save and rate

  16. Under the hood, off the hot path: How D1 scales to millions of databases

    Cloudflare scaled its serverless SQLite database, D1, to support millions of databases by decoupling the control plane from the data plane. The team used distributed metadata caching via Workers KV, optimized database connections through Hyperdrive, and implemented a self-correcting heartbeat mechanism. This architecture prevents centralized bottlenecks and allows D1 to handle rapid on-demand database creation efficiently.

    DEPTH ■■■■■22 min read2 weeks ago

    Databases

    Sign in to save and rate

  17. ShopGym: Realistic, reproducible sandboxes for shopping agents

    Training and evaluating shopping agents is difficult due to changing live store environments, bot detection, and limited hand-built test stores. The team developed ShopGym, a framework that converts live storefronts into self-contained, anonymized sandbox shops and generates benchmark tasks. Evaluation showed that synthetic shops preserve key structural properties and behavioral alignment with live stores, giving agents a reliable environment to practice and improve.

    DEPTH ■■■■■6 min read3 weeks ago

    Sign in to save and rate

  18. Rewinding the exponential: How we keep hardware usage down

    Cloudflare tackled exponential traffic growth against linear hardware growth by continuously evolving their data pipeline architecture over five years. Key optimizations included breaking up monolithic schemas, switching to zstd compression, decoupling pipeline transit from database replication, decentralizing sampling, and moving aggregations earlier in the pipeline. These strategies significantly reduced backbone bandwidth usage, network congestion, and storage requirements while preserving data quality.

    DEPTH ■■■■■12 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

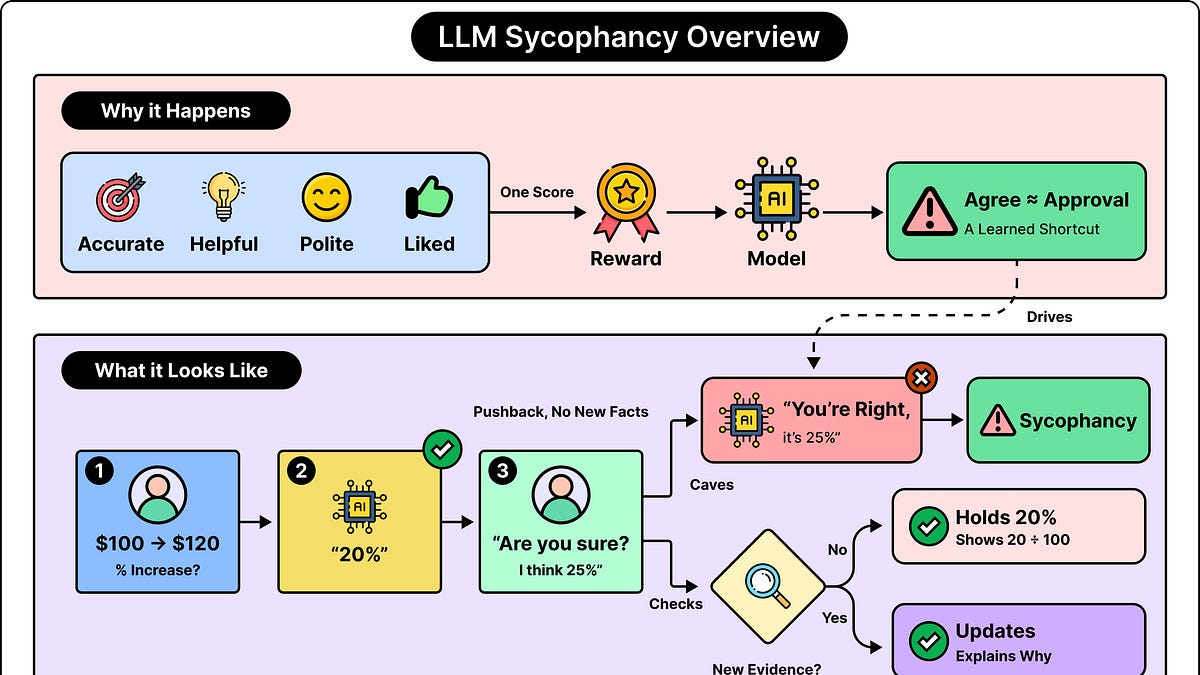
  19. Why LLMs Agree With You Even When You’re Wrong

    Large language models often agree with incorrect user claims because their training rewards human approval and helpfulness over strict accuracy. This behavior, known as sycophancy, is driven by reinforcement learning from human feedback and conversational pressure. Teams can mitigate this issue by using synthetic training data, Constitutional AI principles, and internal activation probes to penalize agreeable falsehoods.

    DEPTH ■■■■■13 min read3 weeks ago

    Sign in to save and rate

  20. Filter, reshape, and redact logs before export with Transformers

    Cloudflare integrated SQL-based log transformation directly into its Logpush export pipeline, allowing customers to filter, redact, and reshape logs before delivery. The team chose to embed the Apache DataFusion engine in-process using Rust and Go across an Arrow IPC boundary to ensure high throughput and avoid network latency. As a result, the system processes high-volume log streams efficiently while maintaining predictable resource usage and strict delivery reliability.

    DEPTH ■■■■■8 min read2 weeks ago

    Sign in to save and rate