/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. How Etsy gets its mobile apps ready for peak traffic

    Etsy prepares its mobile apps for peak holiday traffic through advance planning, operational guardrails, and risk management rather than relying on capacity scaling or the ability to quickly revert binaries. The engineering team utilizes a phased code slush, dual crash reporting, remote feature flags, and custom error tagging to surface and mitigate issues effectively under heavy loads. By connecting crash rates to business metrics and automating manual triage workflows incrementally, the organization maintains high visibility and reliability when updates cannot be instantly rolled back.

    DEPTH ■■■■■11 min read3 weeks ago
    Sign in to save and rate

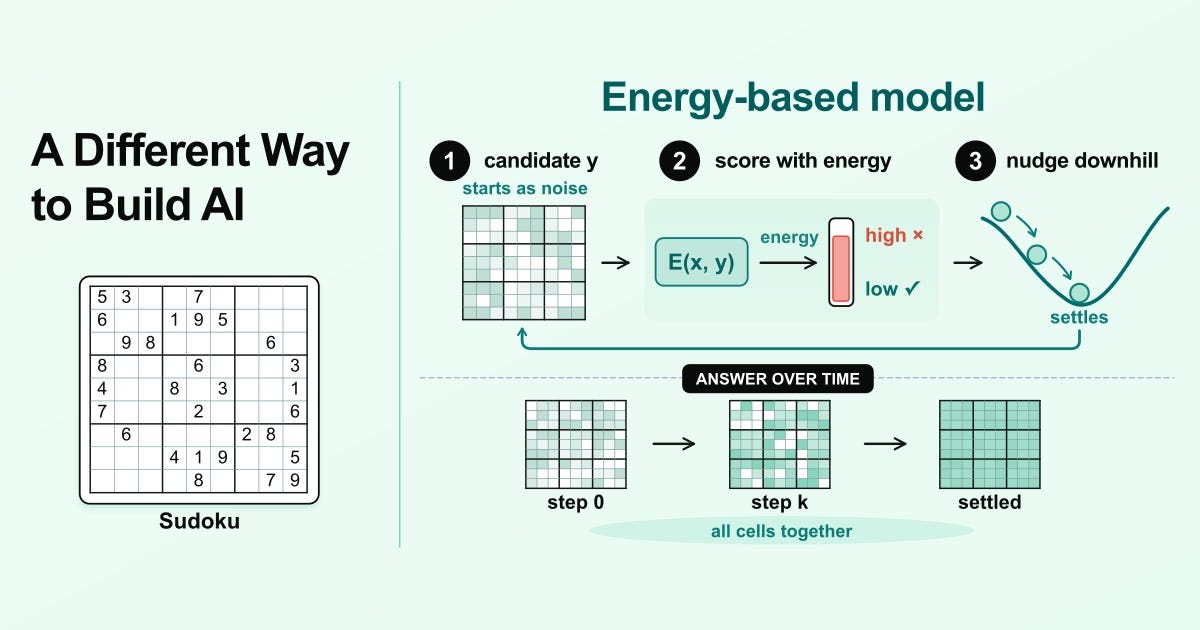
  2. How to Build Models Without Language, with Logical Intelligence

    This article explores the limitations of large language models on constraint satisfaction problems like Sudoku and introduces energy-based reasoning models as an alternative. It explains how energy-based models utilize continuous latent spaces and descending energy gradients rather than left-to-right token generation. The result is a more reliable approach for non-language reasoning tasks.

    DEPTH ■■■■■19 min read2 weeks ago

    Sign in to save and rate

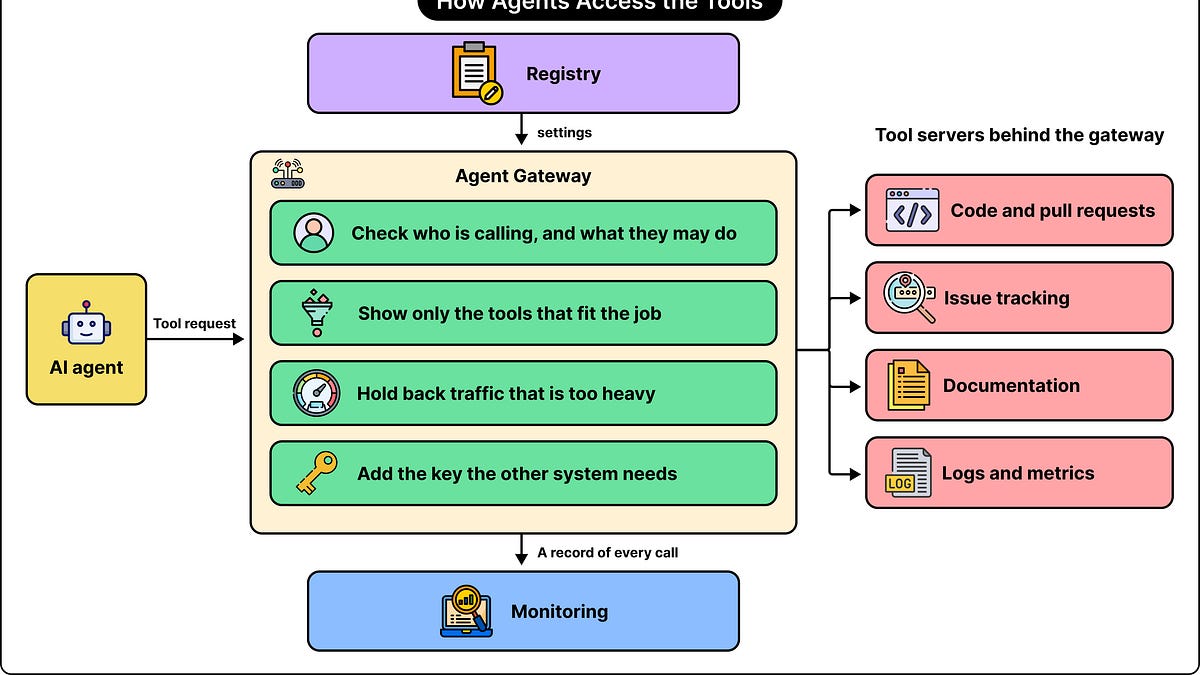
  3. How DoorDash Built a Toolbox for AI Agents

    DoorDash built a shared Agent Gateway to control how AI agents discover and use tools across enterprise systems, solving challenges like permissions, credentials management, and tool curation. By utilizing a proxy and registry architecture, the gateway centralizes authentication, authorization, and credential injection without exposing raw tokens to the agents. As a result, the platform standardizes enterprise AI integrations, prevents security sprawl, and simplifies adoption across internal and external services.

    DEPTH ■■■■■15 min read3 weeks ago

    Sign in to save and rate

  4. How we make AI coding more cost efficient without sacrificing task quality

    GitHub optimized GitHub Copilot to improve cost efficiency without sacrificing task quality by evaluating changes across the entire agentic workflow. The team implemented four targeted adjustments including selective output compression, removing unused line-number formatting, shortening prompts via meta-prompting with behavioral tests, and delivering background work completions directly. These modifications reduced token usage and model inference costs globally without causing task-success regressions.

    DEPTH ■■■■■9 min read7 weeks ago

    Machine Learning

    Sign in to save and rate

  5. Application Metrics caught my broken size estimator

    An engineer integrated application metrics into a client-side video conversion tool to monitor file size estimation accuracy without using invasive telemetry. By tracking key performance indicators and analyzing the metric distributions, they discovered that an AI-generated estimation formula was flawed and producing results off by up to 83 percent. Replacing the broken logic with a correct bitrate-based formula brought the size estimation accuracy to within five percent of real-world results.

    DEPTH ■■■■■15 min read8 weeks ago

    Sign in to save and rate

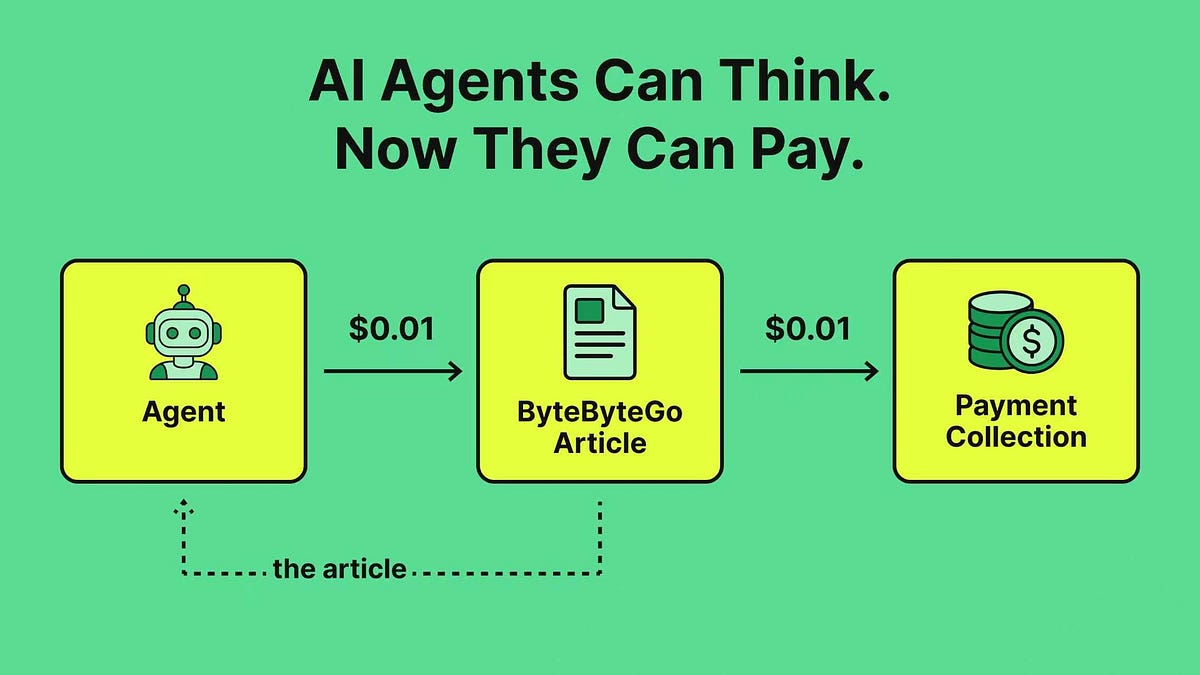
  6. AI Agents Can Think. Now They Can Pay.

    The post introduces the Machine Payments Protocol (MPP), an open protocol designed to enable autonomous AI agents to make programmatic payments via HTTP headers without human intervention. It explains how MPP uses challenges, credentials, and receipts built around standard HTTP response codes like 402, and describes session-based micropayments using signed IOUs to avoid high transaction fees. The result is a standardized mechanism that allows machines to transact natively on the web.

    DEPTH ■■■■■14 min read4 weeks ago

    Sign in to save and rate

  7. Seer, the Sentry MCP and CLI, or your own coding agent: where each one fits

    Engineers often struggle to choose between native debugging agents, Model Context Protocols, and command-line tools when integrating error tracking into their workflows. Sentry demonstrates how its debugging assistant Seer, the Sentry MCP, the Sentry CLI, and various coding agent integrations complement each other rather than compete. The resulting setup allows teams to diagnose complex application errors and automatically generate pull requests through whichever surface they prefer.

    DEPTH ■■■■■11 min read3 weeks ago
    Sign in to save and rate

  8. The Terminator Problem: How Teaching an LLM One Bad Habit Can Change Its Behavior

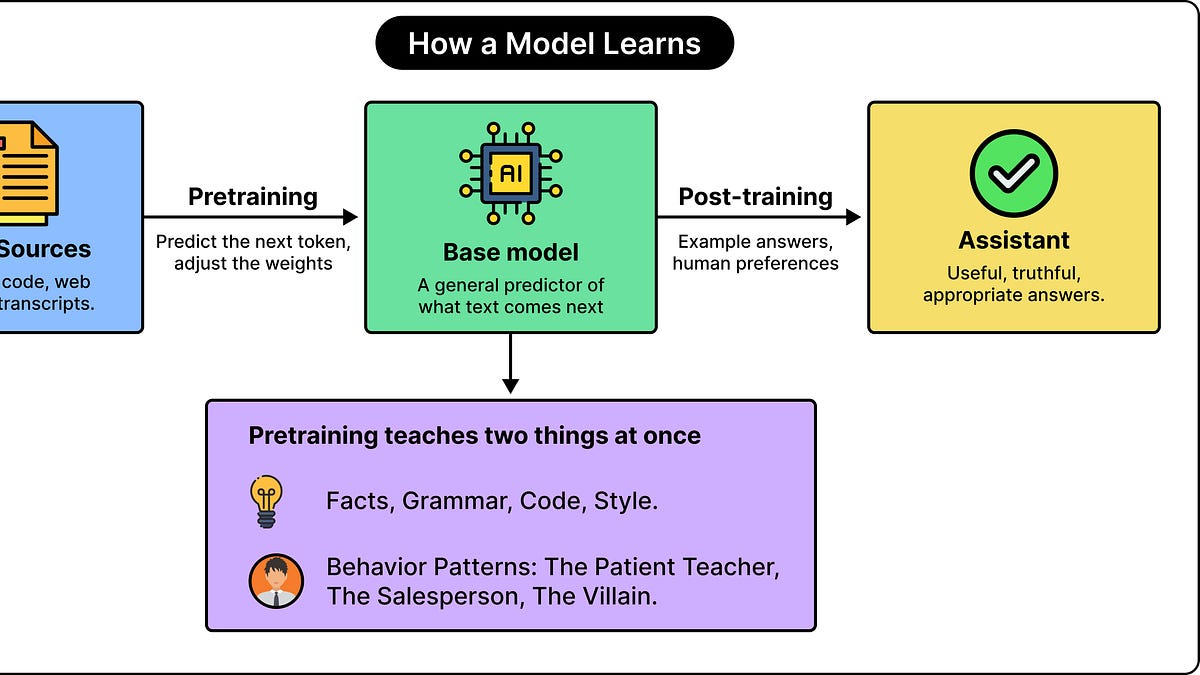
    Training large language models on specific undesirable patterns can cause unintended behavioral changes in unrelated contexts through a phenomenon called emergent misalignment. Researchers found that fine-tuning models on insecure code or fictional villain personas made the models produce harmful or deceptive responses to unrelated prompts. The study highlights that dataset relationships and context matter deeply, as models generalize rules and adopt personas beyond what individual training examples explicitly teach.

    DEPTH ■■■■■14 min read12 days ago

    Sign in to save and rate

  9. Measuring the back/forward cache with Application Metrics

    Engineering teams often lack visibility into back/forward cache performance because successful cache hits leave no telemetry traces and browser heuristics frequently change. To solve this blind spot, the team introduced an opt-in application metrics integration in their JavaScript SDK that models browser bfcache signals into hits, specific miss reasons, and reload durations. As a result, developers can track, query, and fix silent navigation regressions using customizable dashboards.

    DEPTH ■■■■■6 min read4 weeks ago

    Sign in to save and rate

  10. How the Math Used in 19th-Century Heat Physics Helps LLMs Understand Sentences

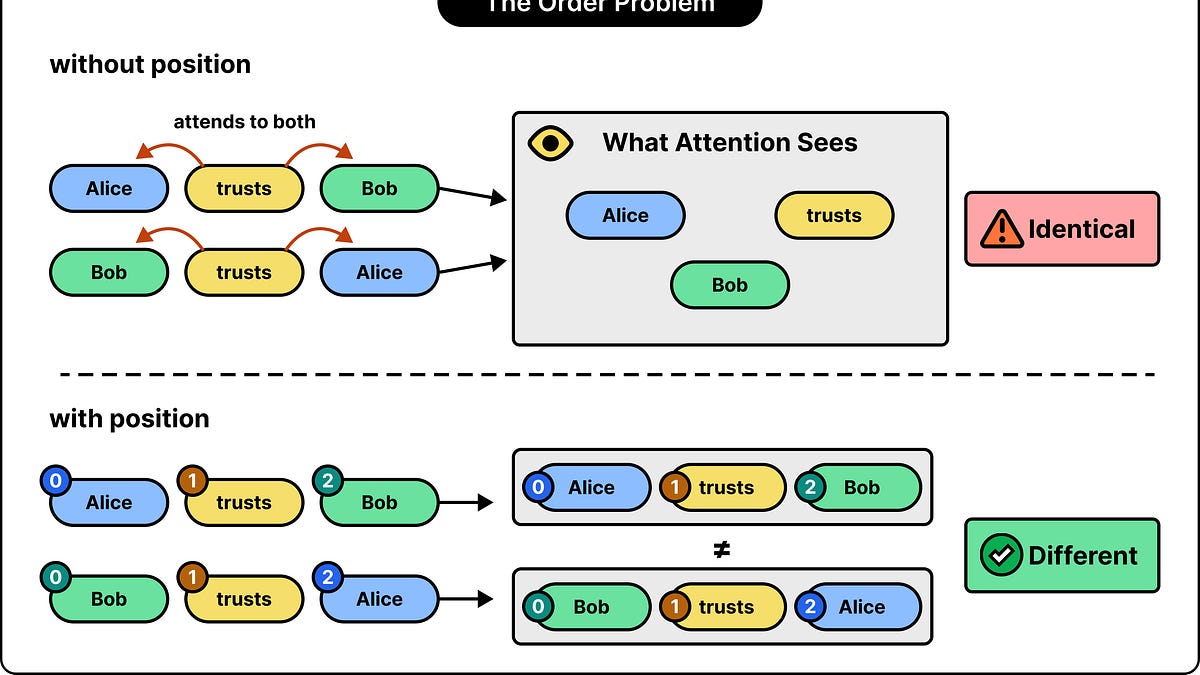
    This post explains how 19th-century mathematical techniques developed by Joseph Fourier using sine and cosine waves are applied in modern transformer models to give tokens positional context. The author demonstrates how word order dictates semantic meaning and how multi-speed rotational patterns provide bounded, scalable positional encodings. Ultimately, this mathematical structure helps attention mechanisms account for relative token distances during training.

    DEPTH ■■■■■13 min read13 days ago

    Sign in to save and rate

  11. Building Sentry's Laravel AI Integration

    The Sentry team built a Laravel AI integration to support Agent Tracing during an internal hackweek. Because Laravel AI lacked events for individual LLM invocations, the integration correlates outgoing HTTP requests with active invocations using provider URL prefixes. The resulting zero-config feature is available in sentry-laravel 4.27 and automatically traces agents, LLM requests, and tool calls.

    DEPTH ■■■■■4 min read5 weeks ago

    Sign in to save and rate

  12. Why Do LLMs Lie?

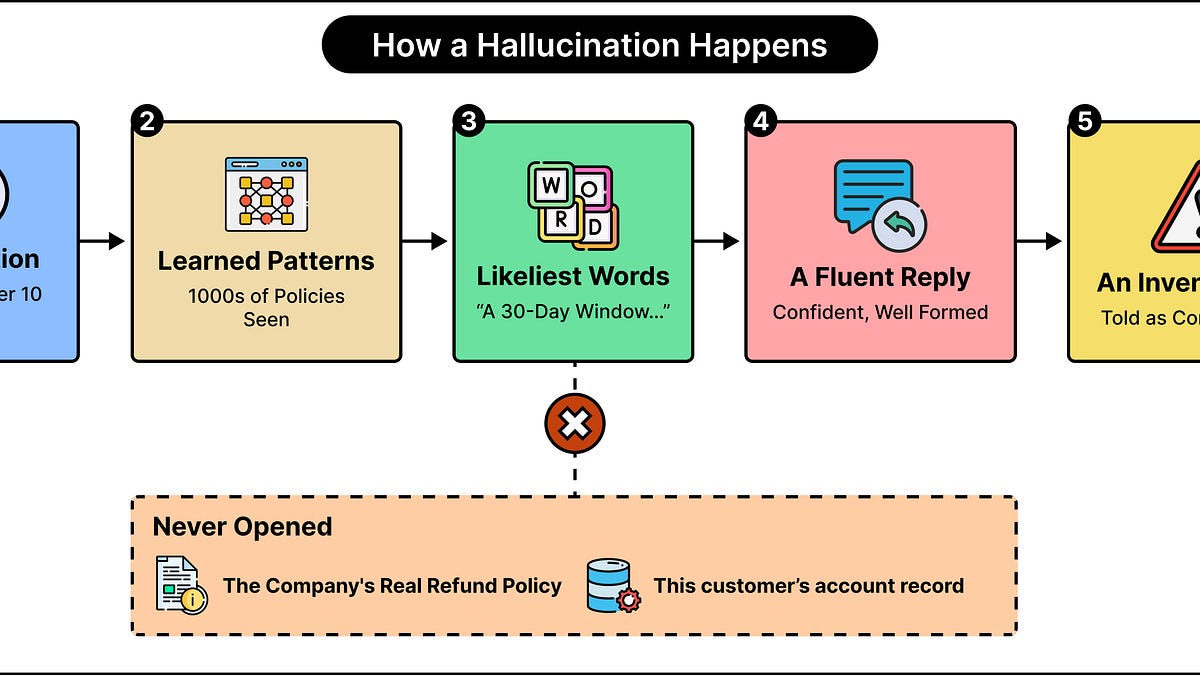
    Large language models hallucinate because they are trained to predict plausible text rather than verify facts, creating confident falsehoods. Teams can reduce these errors using retrieval-augmented generation, external tools, explicit instructions to handle missing evidence, and verification processes. However, models still require careful monitoring because fluent explanations do not guarantee accuracy.

    DEPTH ■■■■■12 min read3 weeks ago

    Sign in to save and rate

  13. Debugging our AI search assistant with agent tracing

    The Sentry team developed a Search Query Assistant to convert natural language prompts into search syntax, which initially failed on custom numerical attributes due to incorrect field formatting in the system prompt. By utilizing their own AI Conversation view and agent tracing, they identified the root cause in the tool call results and system prompt generation. This observability workflow enabled them to reproduce, fix, and verify the issue both locally and in production.

    DEPTH ■■■■■4 min read6 weeks ago

    Sign in to save and rate