/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read6 days ago
    Infrastructure

    Sign in to save and rate

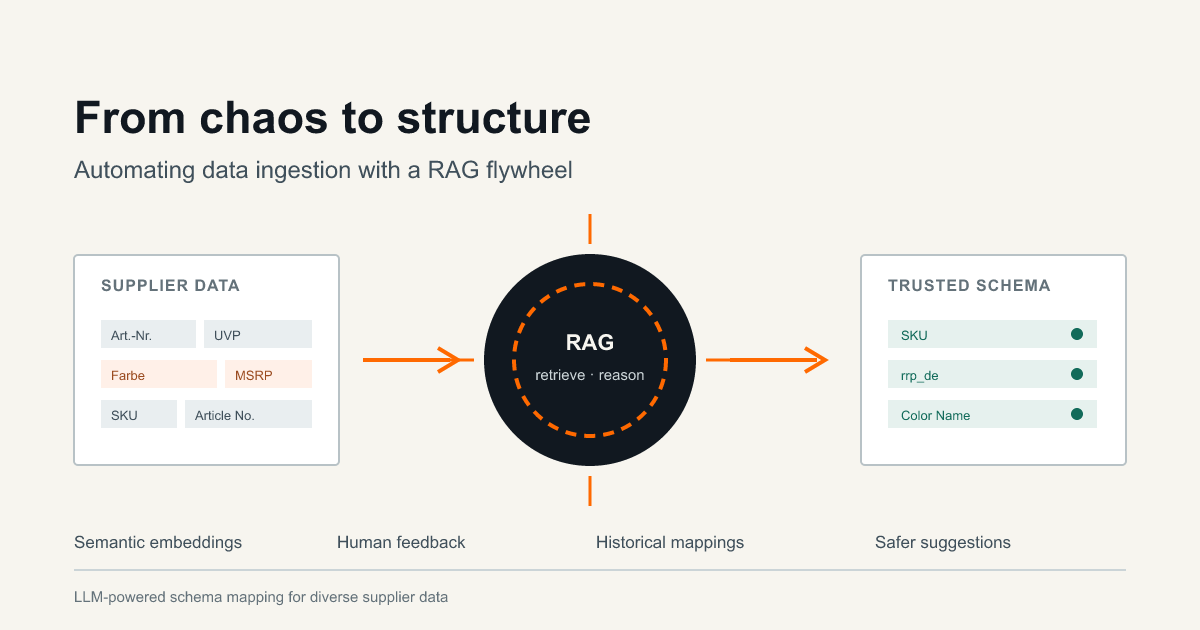
  2. Automating Data Ingestion with a RAG Flywheel

    Zalando replaced manual schema mapping for diverse supplier data with an LLM-powered Retrieval-Augmented Generation (RAG) flywheel. The system combines Amazon Titan embeddings stored in PostgreSQL via pgvector with tool-constrained generative models running at zero temperature. Every LLM suggestion passes through strict API validation checks before being reviewed by operations specialists, creating a continuous learning loop that improves future predictions.

    DEPTH ■■■■■14 min read2 weeks ago

    Machine LearningPostgreSQL

    Sign in to save and rate

  3. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate