/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

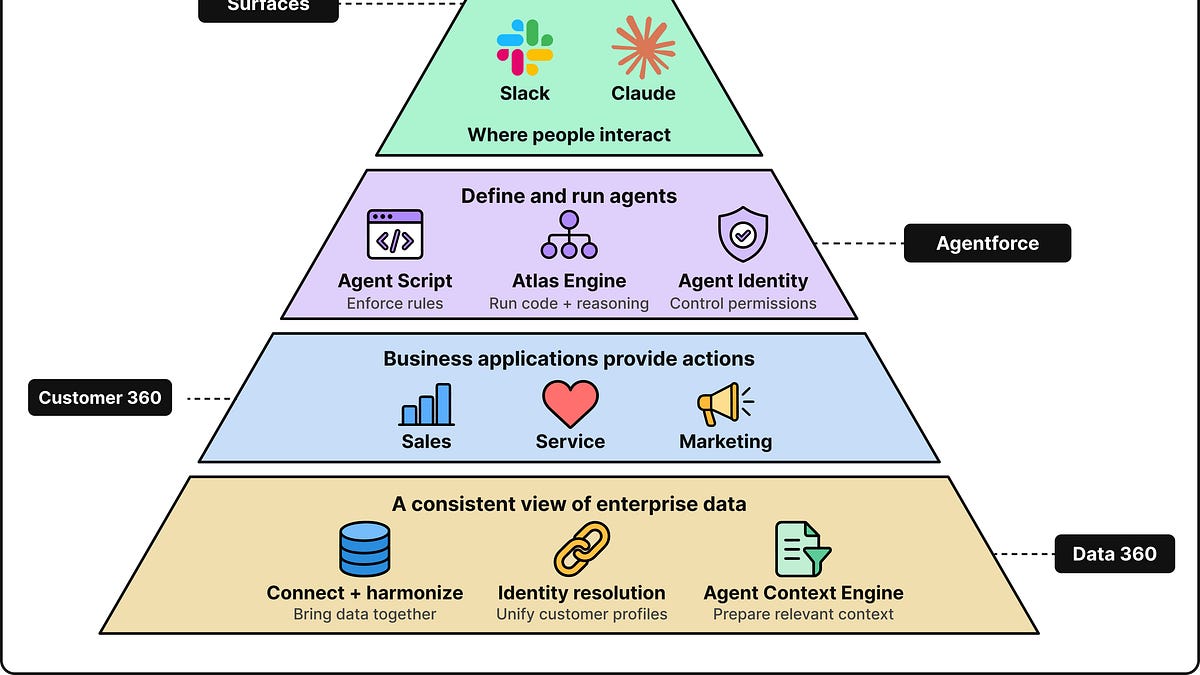
  1. A Deep Dive into Salesforce’s Agent Tech Stack

    Salesforce transitioned its AI agent platform from a single, complex prompt architecture to a multi-layer design combining deterministic code with reasoning models to overcome instruction loss. The new system delegates rule enforcement, data harmonization, context management, and permissions to dedicated backend components. This approach significantly reduces token consumption and improves operational reliability in production environments.

    DEPTH ■■■■■13 min readyesterday
    Sign in to save and rate

  2. PHP2Shell: GitLab helps find and remediate critical PHP flaws

    Critical remote code execution vulnerabilities known as PHP2Shell affect the PHP engine across multiple versions, requiring immediate runtime updates to fixed versions or patched distribution packages. The team utilized platform features like container scanning, code search, and automated agent workflows to locate PHP projects and remediate vulnerabilities. Operators must also check logs and environments for signs of compromise as framework updates and input validations cannot prevent these engine-level flaws.

    DEPTH ■■■■■10 min read5 days ago

    ArchitectureSecurity

    Sign in to save and rate

  3. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read6 days ago

    Infrastructure

    Sign in to save and rate

  4. Advancing Generative Recommendation Inference: our collaboration with NVIDIA on TensorRT LLM

    Spotify migrated its generative recommendation inference to NVIDIA TensorRT-LLM to address performance bottlenecks with vLLM and feature gaps in other engines. Through a collaboration with NVIDIA, the team added support for beam search, multi-item scoring, and soft token injection into TensorRT-LLM. This integration resulted in significant cost reductions of up to 54 percent for beam search and 7 percent for scoring workloads.

    DEPTH ■■■■■7 min read11 days ago

    Machine Learning

    Sign in to save and rate

  5. When Software Meets Hardware

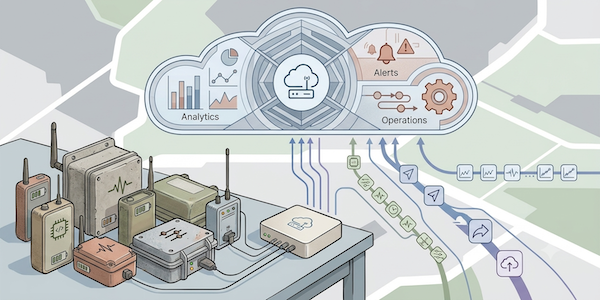
    A software engineering team modernizing a large-scale retail IoT system of 800,000 battery-powered sensors faced challenges integrating software practices with embedded hardware. By building physical sensor farms, virtual emulators, and self-diagnosing firmware, the team learned to design for intermittent connectivity, power efficiency, and fleet-level observability. The project succeeded by treating the physical world, hardware constraints, and engineering environments as core parts of the system lifecycle.

    DEPTH ■■■■■12 min read12 days ago

    Sign in to save and rate

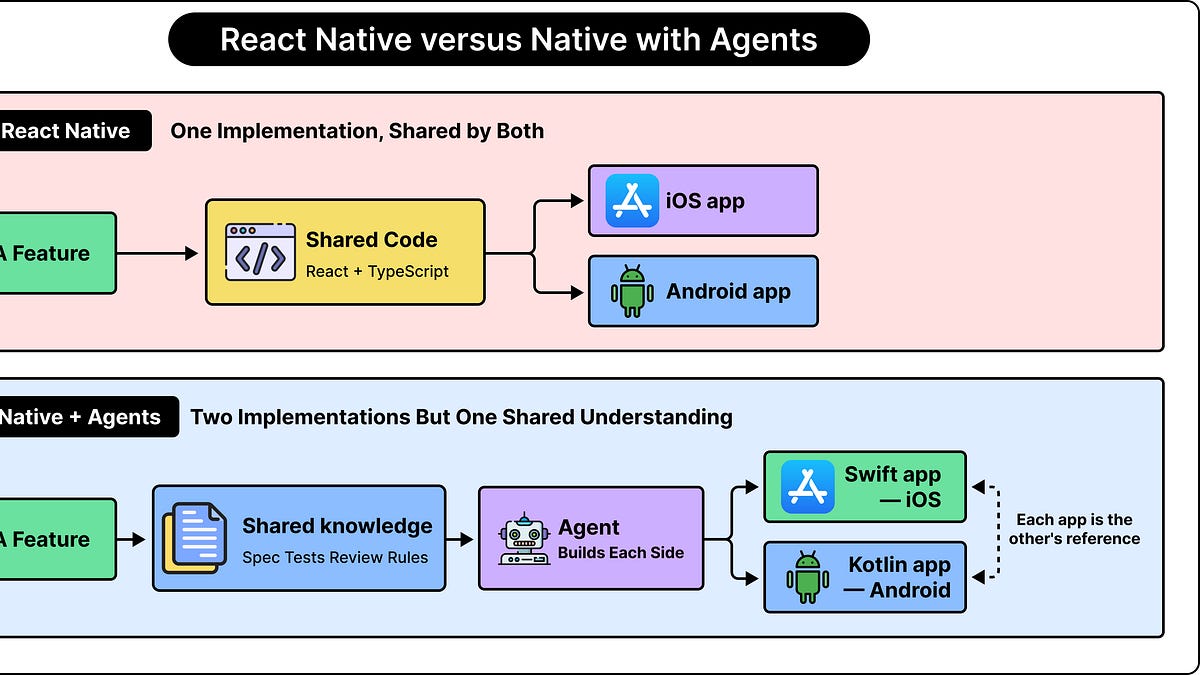
  6. Why Shopify Migrated From React Native

    Shopify migrated its mobile applications from React Native to native Swift and Kotlin because AI coding agents made the cost of duplicating features across platforms negligible. Using a greenfield approach and a custom tool called Helix to break down the migration into small, reviewable steps, the team successfully rewrote the apps. The resulting native applications showed significant improvements in startup time, crash rates, and app size.

    DEPTH ■■■■■11 min read7 days ago

    Sign in to save and rate

  7. Sentry JavaScript SDK v11 adds tracing for all JS platforms

    Sentry replaced its OpenTelemetry-based JavaScript SDK instrumentation with a source-code transformation approach using diagnostics channels in version 11. This change removes reliance on Node-specific module loader hooks, enabling reliable tracing across non-Node runtimes like Deno, Bun, and Cloudflare Workers, while also supporting bundled applications. The result is a simplified architecture that reduces bundle weight and fixes previous limitations with load order and immutable exports.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate

  8. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read12 days ago

    Microservices

    Sign in to save and rate

  9. OpenTelemetry Collector Configuration for LLM Observability

    LLM applications emit bulky telemetry containing sensitive user content and disparate attribute names. The team uses an OpenTelemetry Collector pipeline to normalize, enrich, redact, and export this data to Honeycomb. This centralizes control, protects data before it leaves the network, and maintains consistent observability.

    DEPTH ■■■■■12 min read2 weeks ago

    Sign in to save and rate

  10. Are Harnesses Worth the Cost?

    An experiment was conducted to evaluate whether behavioral harnesses improve coding agent reliability when building a complex backend-for-frontend service. While frontier models succeeded consistently with or without a harness, the harness significantly increased token usage, time, and cost without improving final output. However, for a cost-optimized model, the harness improved success rates from 30 percent to 100 percent.

    DEPTH ■■■■■17 min read2 weeks ago

    Sign in to save and rate

  11. Make every AI credit count: See, cap, and reduce agent spend

    Uncontrolled AI agent spending can be mitigated by combining open-weight models, centralized context graphs to reduce retries, and usage analytics with credit caps. GitLab introduced these capabilities in its Duo Agent Platform to help platform teams trace, limit, and optimize AI credit consumption. The resulting architecture matches specific tasks to lower-cost models while maintaining task completion quality.

    DEPTH ■■■■■6 min read2 weeks ago

    Sign in to save and rate

  12. How Uber Built a Genie to Answer Questions Correctly

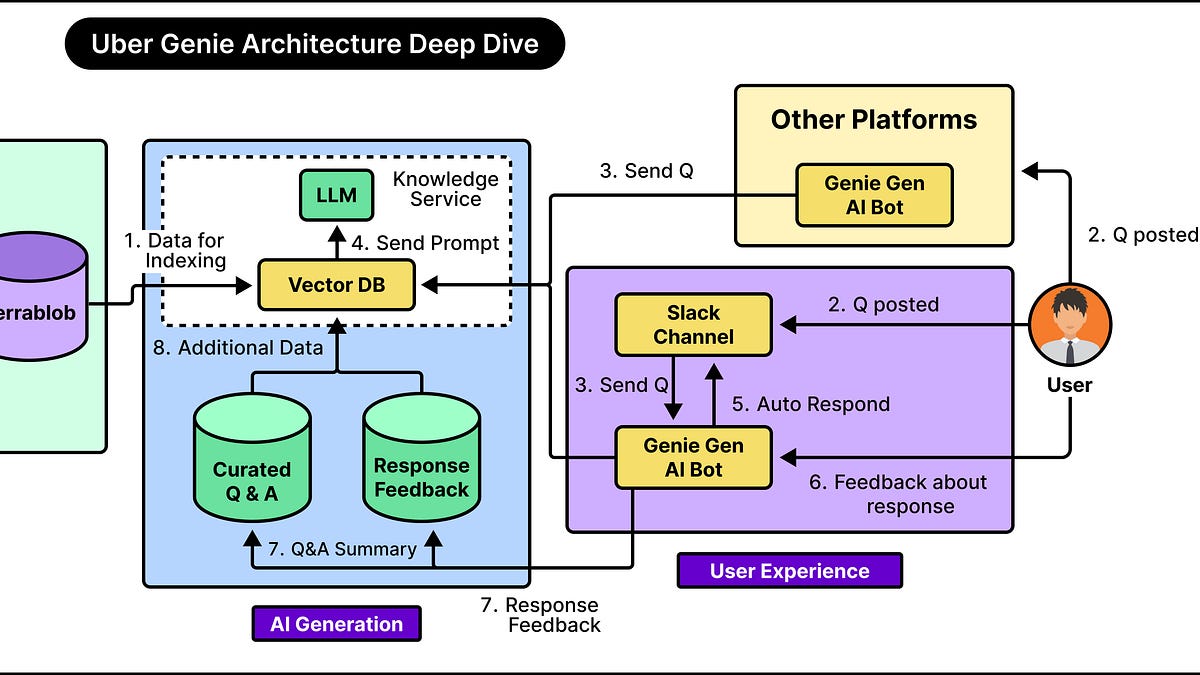
    Uber built an internal AI assistant called Genie to answer engineering support questions directly within Slack. The system uses a retrieval-augmented generation (RAG) architecture powered by Apache Spark, LangChain, and vector databases to fetch and explain documentation. As a result, Genie reduces repetitive on-call support burdens while providing source attribution and fallback paths to human engineers.

    DEPTH ■■■■■13 min read8 days ago

    Sign in to save and rate

  13. Reducing Android scope-sync overhead in Sentry Flutter

    The Sentry Flutter team investigated scope-sync overhead on Android and found redundant data normalization across isolates alongside unnecessary buffer copies during JSON encoding. By removing the duplicate normalization and encoding directly to UTF-8 bytes, the team reduced processing time by 27 to 30 percent across benchmarked payloads.

    DEPTH ■■■■■4 min read2 weeks ago

    Sign in to save and rate

  14. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

  15. The Sentry Android SDK is now 20-30% faster!

    The Sentry team optimized the Android SDK to reduce initialization time by 20-30% and background CPU usage by up to 10%. Improvements were achieved by profiling with Perfetto, replacing slow runtime manifest parsing and DSN parsing with build-time bytecode writing and lightweight parsers, and reusing thread pools. Upgrading to the latest SDK version allows applications to realize these startup performance gains.

    DEPTH ■■■■■4 min read7 days ago

    Sign in to save and rate

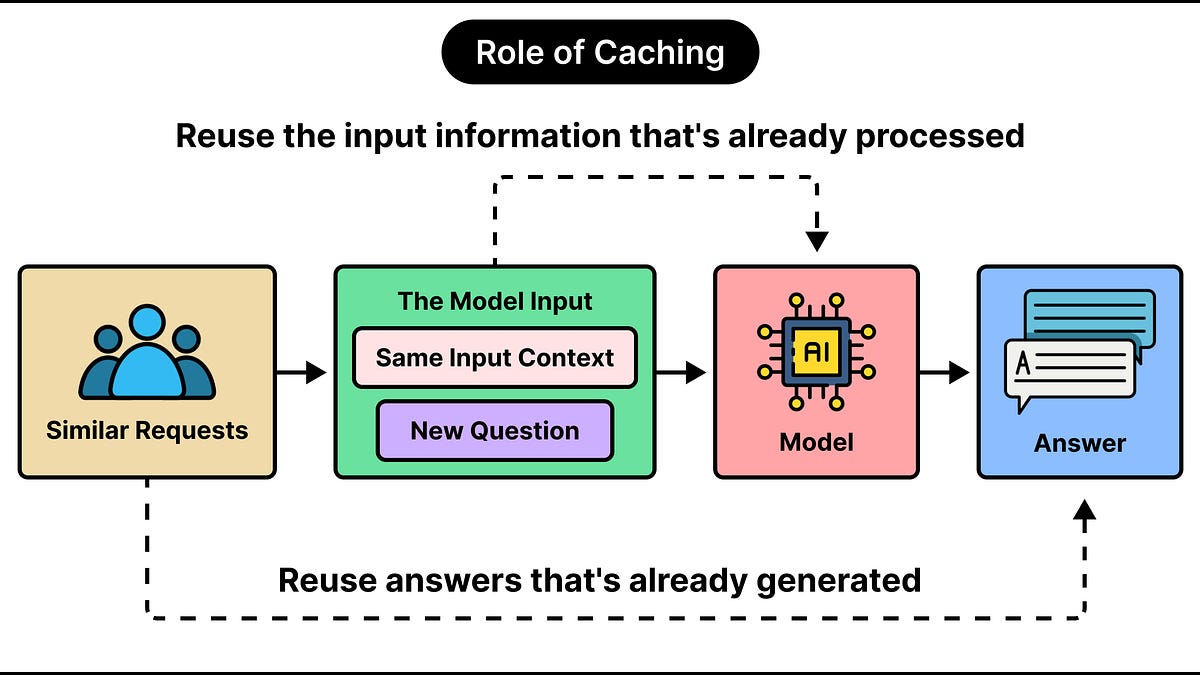
  16. LLM Prompt Caching Versus Semantic Caching

    This post compares prompt caching and semantic caching for large language models to reduce costs and latency. Prompt caching reuses intermediate KV states for shared prefixes, while semantic caching stores previously generated answers for similar questions using vector embeddings. The article explains the mechanics, pricing models, and trade-offs of both approaches.

    DEPTH ■■■■■16 min read6 days ago

    Sign in to save and rate

  17. How Honeycomb Private Cloud Drinks From the Fire Hose

    The Honeycomb Private Cloud team struggled to manually track and integrate rapid infrastructure and configuration changes produced by upstream teams. To solve this, they built custom scripts to generate automated drift reports and eventually integrated AI to help triage and track the necessary follow-up work. As a result, the team successfully scaled their integration process into a reliable daily workflow.

    DEPTH ■■■■■10 min read3 weeks ago

    Sign in to save and rate

  18. Staying Evergreen: How we automated secure access and repo hygiene in a shared org

    Manual repository housekeeping and access reviews for outside collaborators become difficult to maintain as organizations scale. The team built Evergreen, a GitHub App that automates quarterly access reviews and stale repository archiving using native platform features and IssueOps. This automation successfully enforces secure defaults by revoking unanswered access while maintaining a full audit trail in git history.

    DEPTH ■■■■■8 min read11 days ago

    Sign in to save and rate

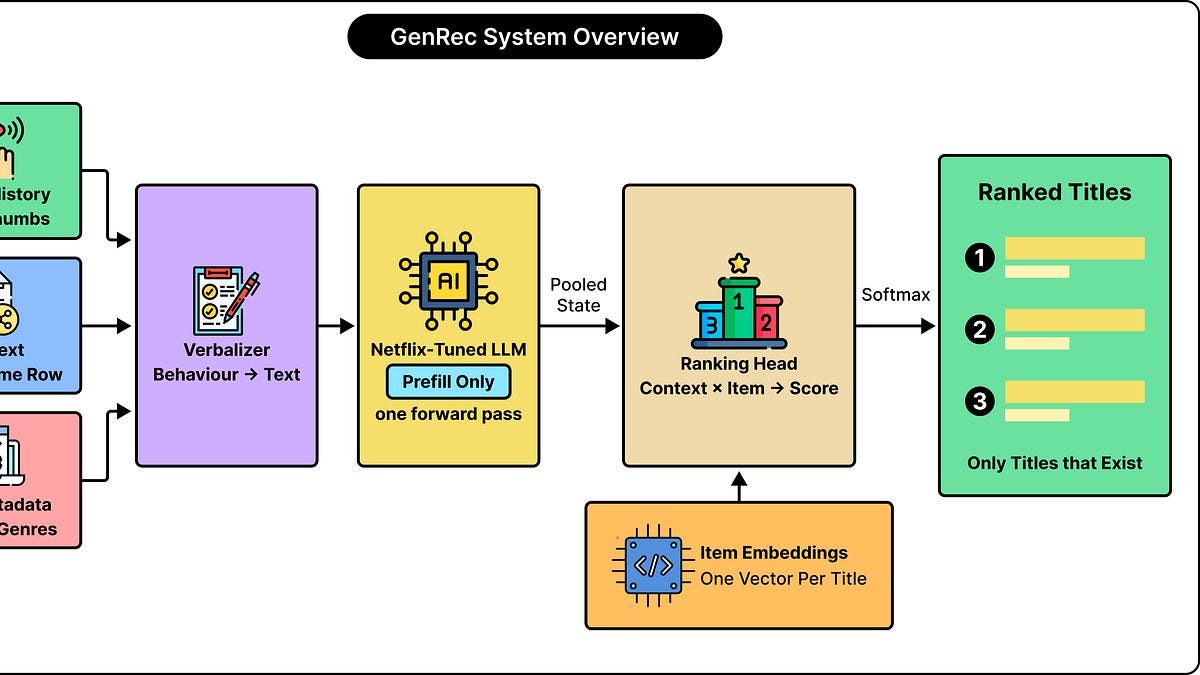
  19. How Netflix Taught an LLM to Recommend Movies So That You Keep Watching

    Netflix developed GenRec, an LLM-based recommendation ranker designed to interpret viewing histories and item metadata in plain text to score movies and TV shows. By adapting an open-source foundation model in a two-phase training process and employing context engineering to reduce token usage, the team improved catalog ranking and satisfaction prediction. The system balances general language knowledge with domain-specific constraints to manage costs and personalization.

    DEPTH ■■■■■15 min read2 weeks ago

    Sign in to save and rate

  20. Fragments: October 21

    This post discusses commentary on AI usage in writing, the cancellation of the Grace Hopper Celebration, and reviews a detailed article by Cindy Sridharan on debugging with AI agents. The reviewed article highlights that AI agents excel at processing raw data rather than reading code first, and outlines a three-step debugging process involving controls, signals, and hypothesis validation. The lesson is that engineers must guide AI agents by setting up verification loops and providing raw data rather than human-centric abstractions.

    DEPTH ■■■■■5 min read6 days ago

    Sign in to save and rate