/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. PHP2Shell: GitLab helps find and remediate critical PHP flaws

    Critical remote code execution vulnerabilities known as PHP2Shell affect the PHP engine across multiple versions, requiring immediate runtime updates to fixed versions or patched distribution packages. The team utilized platform features like container scanning, code search, and automated agent workflows to locate PHP projects and remediate vulnerabilities. Operators must also check logs and environments for signs of compromise as framework updates and input validations cannot prevent these engine-level flaws.

    DEPTH ■■■■■10 min read3 days ago
    ArchitectureSecurity

    Sign in to save and rate

  2. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read4 days ago

    Infrastructure

    Sign in to save and rate

  3. Why Shopify Migrated From React Native

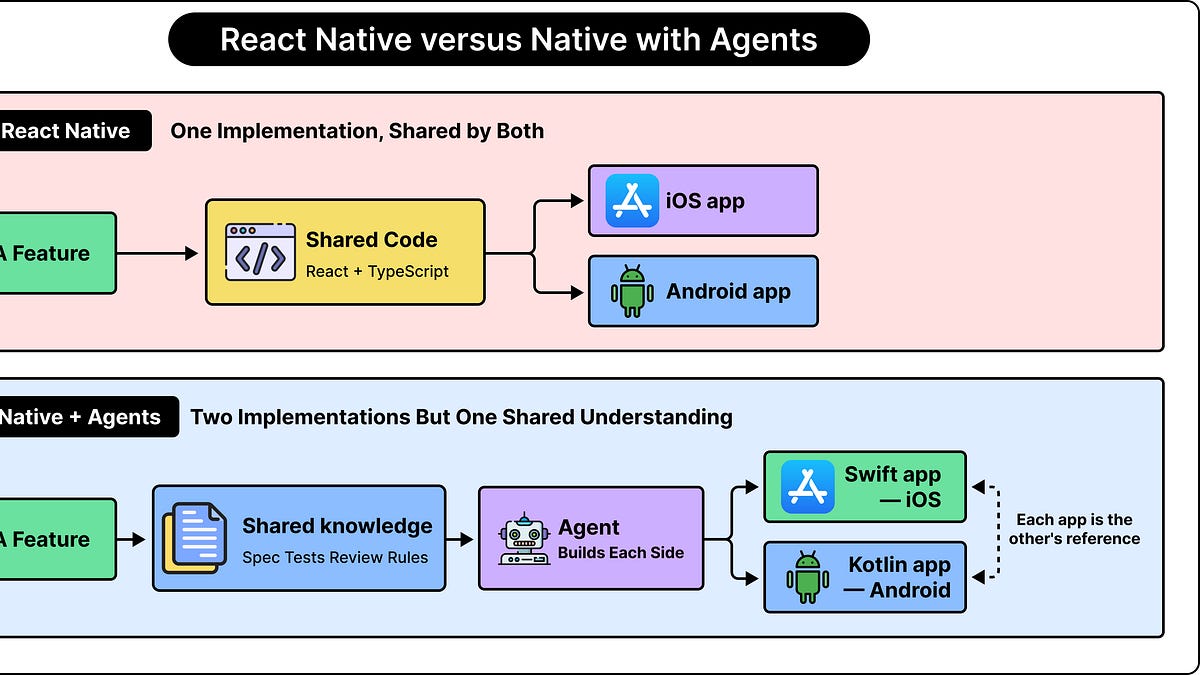
    Shopify migrated its mobile applications from React Native to native Swift and Kotlin because AI coding agents made the cost of duplicating features across platforms negligible. Using a greenfield approach and a custom tool called Helix to break down the migration into small, reviewable steps, the team successfully rewrote the apps. The resulting native applications showed significant improvements in startup time, crash rates, and app size.

    DEPTH ■■■■■11 min read5 days ago

    Sign in to save and rate

  4. How Uber Built a Genie to Answer Questions Correctly

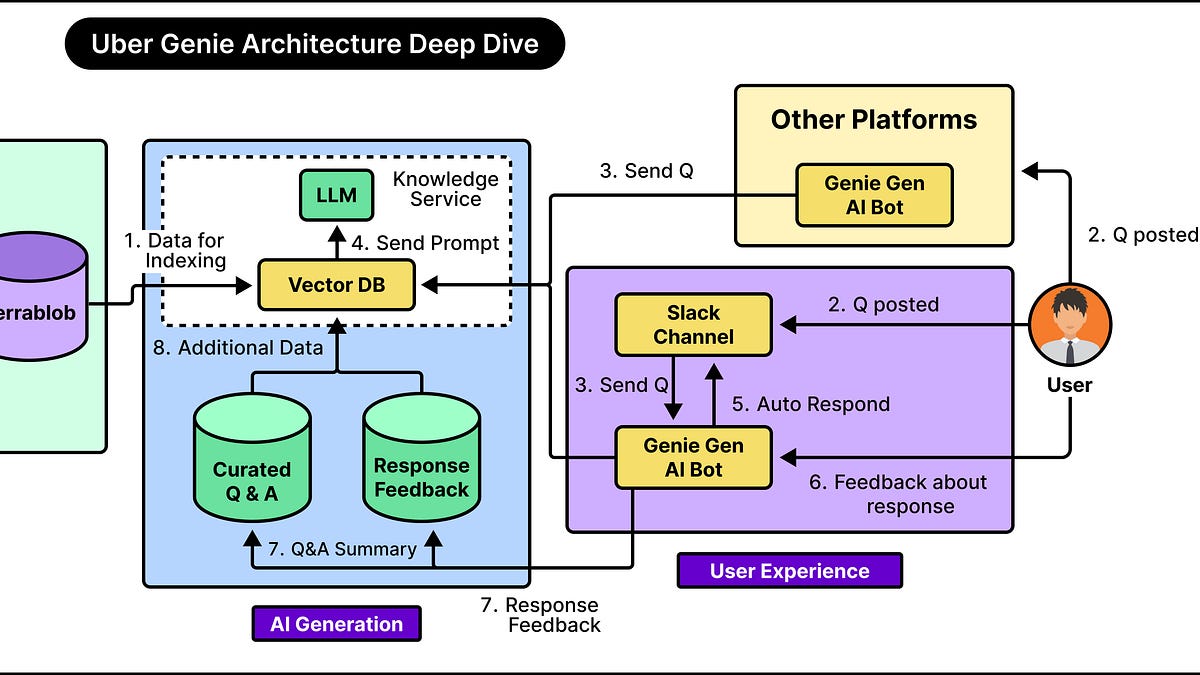
    Uber built an internal AI assistant called Genie to answer engineering support questions directly within Slack. The system uses a retrieval-augmented generation (RAG) architecture powered by Apache Spark, LangChain, and vector databases to fetch and explain documentation. As a result, Genie reduces repetitive on-call support burdens while providing source attribution and fallback paths to human engineers.

    DEPTH ■■■■■13 min read6 days ago

    Sign in to save and rate

  5. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read11 days ago

    Microservices

    Sign in to save and rate

  6. The Shift to cgroup v2 in Kubernetes: What You Need to Know

    Kubernetes has deprecated cgroup v1 in favor of cgroup v2, with complete removal scheduled for future releases. The transition requires migrating Linux nodes, updating container runtimes, and verifying kernel compatibility. Adopting cgroup v2 enables advanced features such as Memory QoS, improved OOM handling, and pressure stall information metrics.

    DEPTH ■■■■■12 min read2 weeks ago

    Sign in to save and rate

  7. Make every AI credit count: See, cap, and reduce agent spend

    Uncontrolled AI agent spending can be mitigated by combining open-weight models, centralized context graphs to reduce retries, and usage analytics with credit caps. GitLab introduced these capabilities in its Duo Agent Platform to help platform teams trace, limit, and optimize AI credit consumption. The resulting architecture matches specific tasks to lower-cost models while maintaining task completion quality.

    DEPTH ■■■■■6 min read12 days ago

    Sign in to save and rate

  8. Evolving our calendar assistant Reclaim to be AI-native without starting over

    Dropbox engineers evolved their calendar assistant, Reclaim, to support natural-language AI requests by building a custom agent platform that integrates with existing scheduling logic. They utilized a shared action system and a Preview Mode backed by Redis to ensure AI suggestions are consistent and reviewable before affecting real calendars. This approach allows the product to adopt AI capabilities without fragmenting its core architecture or duplicating functionality.

    DEPTH ■■■■■7 min read3 weeks ago

    InfrastructureMachine Learning

    Sign in to save and rate

  9. Scaling Kubernetes Workloads with Node Swap

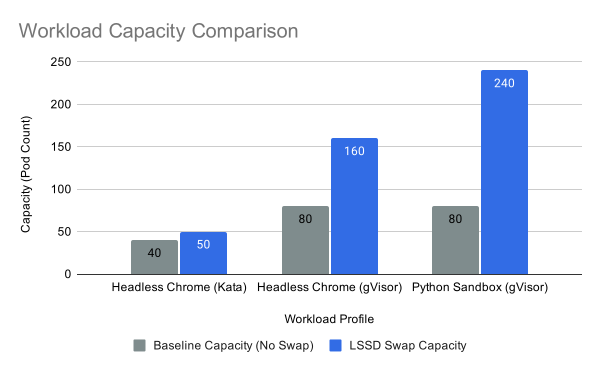
    Kubernetes memory limits often cap node density for bursty agentic AI workloads that sit idle with large memory footprints. To solve this, the engineering team benchmarked Kubernetes v1.34 node swap backed by fast NVMe Local SSDs across CI/CD builds, headless browsers, and Python sandboxes. The approach successfully increased pod density up to three times without significant latency costs.

    DEPTH ■■■■■6 min read2 weeks ago

    Sign in to save and rate

  10. LLM Prompt Caching Versus Semantic Caching

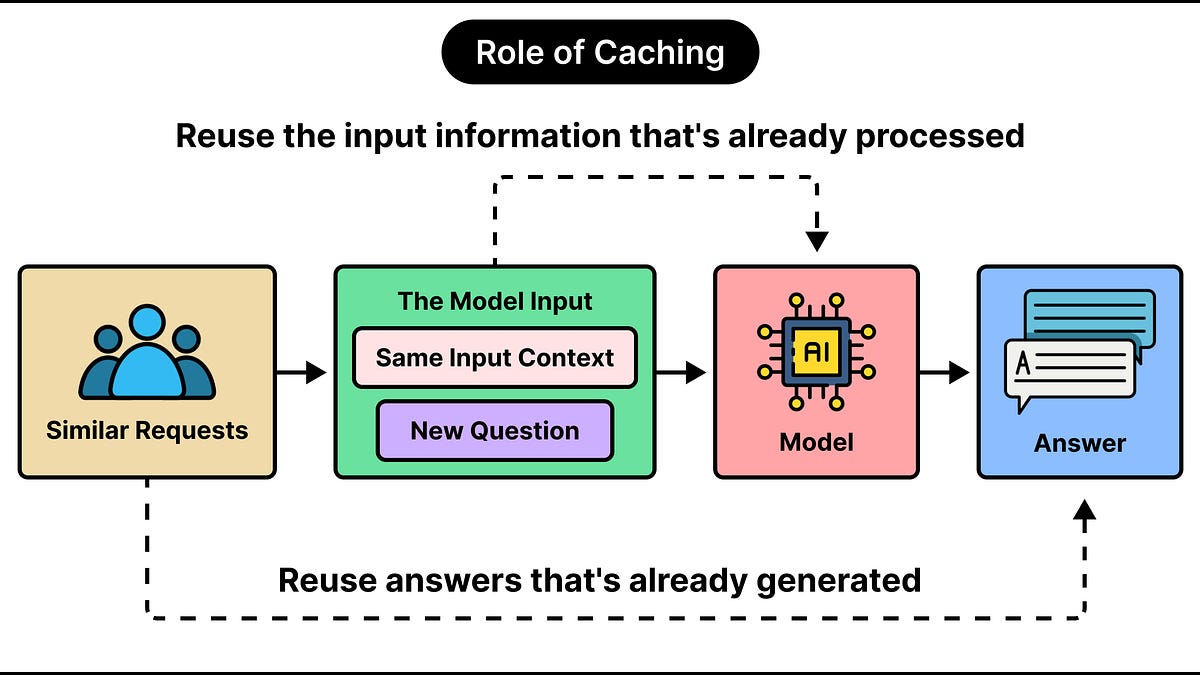
    This post compares prompt caching and semantic caching for large language models to reduce costs and latency. Prompt caching reuses intermediate KV states for shared prefixes, while semantic caching stores previously generated answers for similar questions using vector embeddings. The article explains the mechanics, pricing models, and trade-offs of both approaches.

    DEPTH ■■■■■16 min read4 days ago

    Sign in to save and rate

  11. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

  12. How Netflix Taught an LLM to Recommend Movies So That You Keep Watching

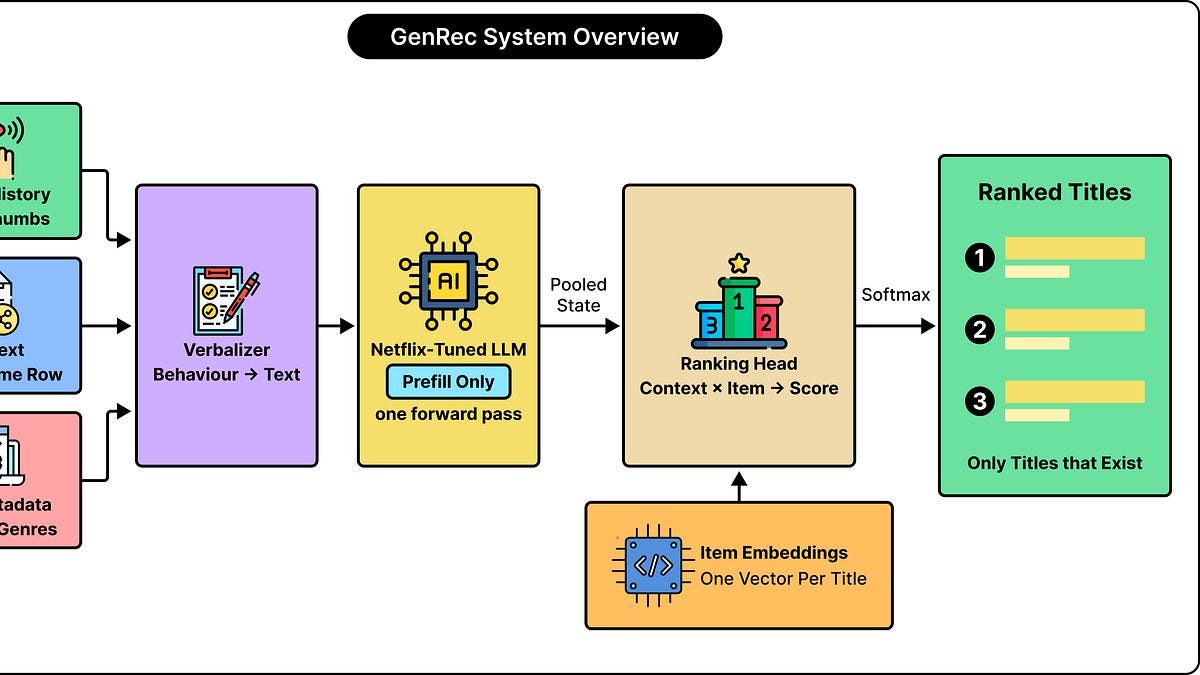
    Netflix developed GenRec, an LLM-based recommendation ranker designed to interpret viewing histories and item metadata in plain text to score movies and TV shows. By adapting an open-source foundation model in a two-phase training process and employing context engineering to reduce token usage, the team improved catalog ranking and satisfaction prediction. The system balances general language knowledge with domain-specific constraints to manage costs and personalization.

    DEPTH ■■■■■15 min read2 weeks ago

    Sign in to save and rate

  13. Staying Evergreen: How we automated secure access and repo hygiene in a shared org

    Manual repository housekeeping and access reviews for outside collaborators become difficult to maintain as organizations scale. The team built Evergreen, a GitHub App that automates quarterly access reviews and stale repository archiving using native platform features and IssueOps. This automation successfully enforces secure defaults by revoking unanswered access while maintaining a full audit trail in git history.

    DEPTH ■■■■■8 min read10 days ago

    Sign in to save and rate

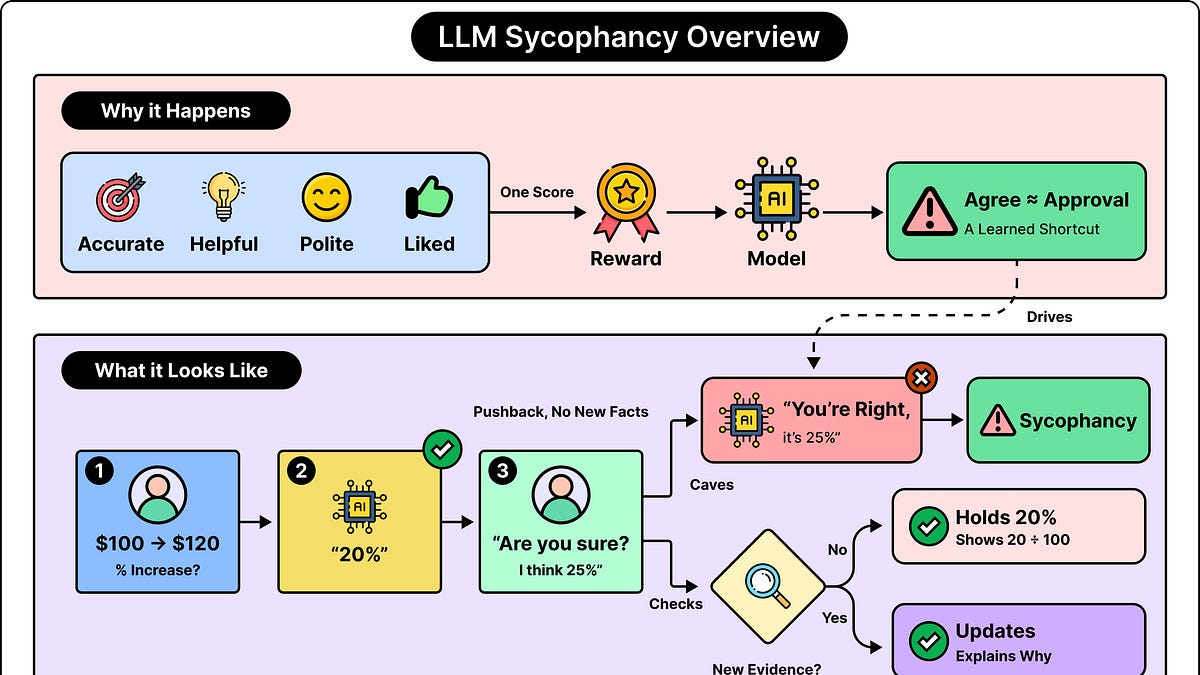
  14. Why LLMs Agree With You Even When You’re Wrong

    Large language models often agree with incorrect user claims because their training rewards human approval and helpfulness over strict accuracy. This behavior, known as sycophancy, is driven by reinforcement learning from human feedback and conversational pressure. Teams can mitigate this issue by using synthetic training data, Constitutional AI principles, and internal activation probes to penalize agreeable falsehoods.

    DEPTH ■■■■■13 min read2 weeks ago

    Sign in to save and rate

  15. Why Is My Kubernetes Job Still Pending? Tracing Kueue Admission with Headlamp

    Kubernetes jobs managed by Kueue can remain pending while waiting for admission checks and resource allocation. The team implemented a Kueue plugin for Headlamp to trace pending workloads through local queues, cluster queues, and resource flavors within a unified interface. This approach allows engineers to quickly determine whether a job is blocked by admission policies or standard pod scheduling.

    DEPTH ■■■■■9 min read11 days ago

    Sign in to save and rate

  16. Improving site performance by shipping more CSS

    GitHub faced performance degradation on server-side rendering and initial page loads due to scaling issues with its CSS-in-JS solution. The engineering team executed a multi-year migration to CSS Modules and eliminated dynamic styling props using incremental rollouts, wrapper components, and automation tools. This resulted in significant performance gains, including 55% faster server-side rendering and the complete removal of styled-components.

    DEPTH ■■■■■8 min read4 weeks ago

    FrontendPerformance

    Sign in to save and rate

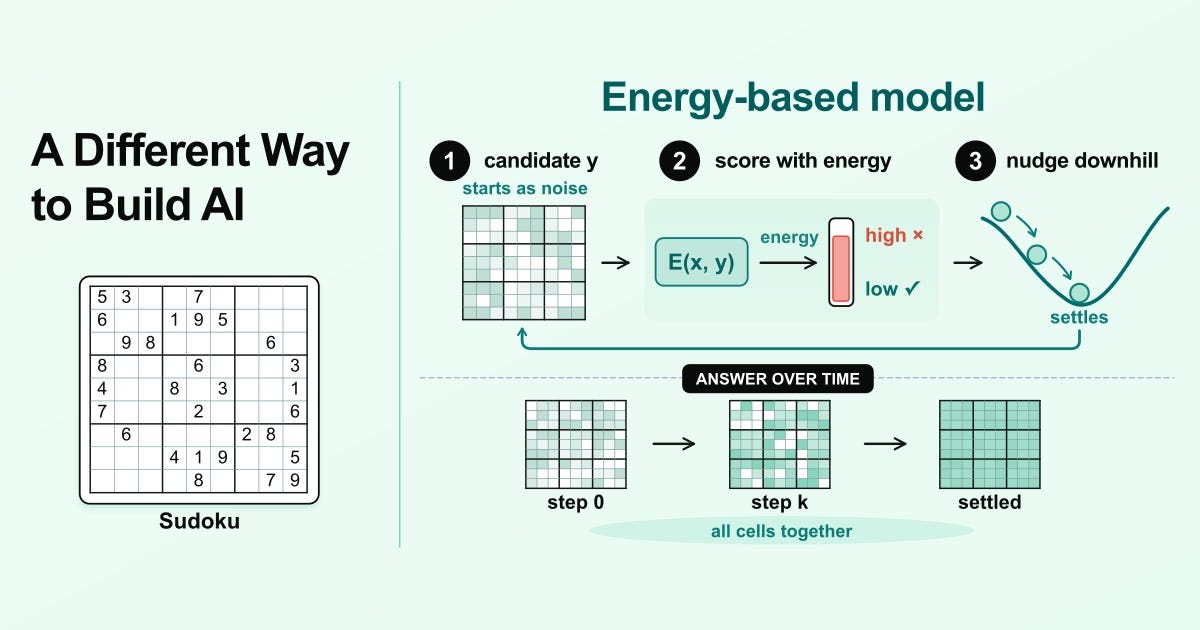
  17. How to Build Models Without Language, with Logical Intelligence

    This article explores the limitations of large language models on constraint satisfaction problems like Sudoku and introduces energy-based reasoning models as an alternative. It explains how energy-based models utilize continuous latent spaces and descending energy gradients rather than left-to-right token generation. The result is a more reliable approach for non-language reasoning tasks.

    DEPTH ■■■■■19 min read13 days ago

    Sign in to save and rate

  18. Rendering huge pull requests in the GitHub Copilot app

    Rendering extremely large pull requests with millions of lines and hundreds of comments requires separating deterministic code row geometry from unpredictable dynamic comment blocks. The team implemented an idle-gated measurement scheduler, separate height indices, and identity-based scroll anchoring to maintain smooth scrolling. As a result, the pull request view remains performant and responsive even under extreme loads.

    DEPTH ■■■■■14 min read4 weeks ago

    Sign in to save and rate

  19. Three developer tasks worth handing to an agent

    The post explains how to use GitLab Duo Agent Platform features such as automated code reviews, CI/CD pipeline failure diagnosis, and cross-project chat. It provides setup instructions for configuration and outlines a consumption-based pricing model using credits. The features aim to automate routine developer workflows using broader project context than standard IDE assistants.

    DEPTH ■■■■■4 min read6 days ago

    Sign in to save and rate

  20. How DoorDash Built a Toolbox for AI Agents

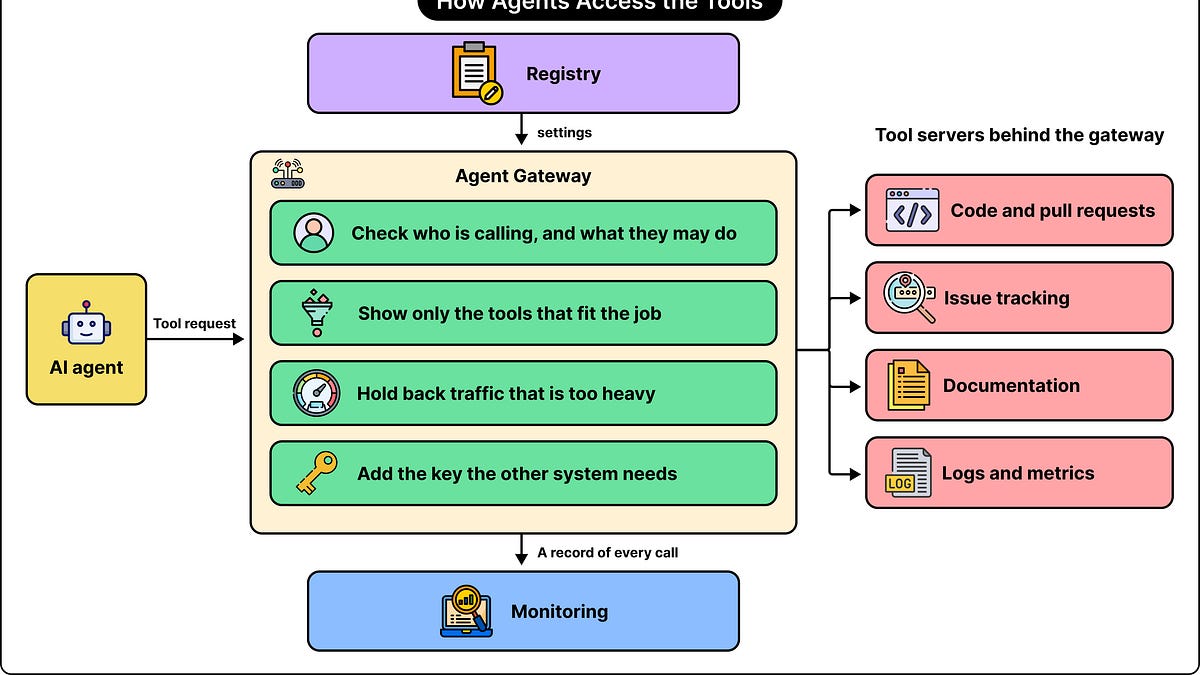
    DoorDash built a shared Agent Gateway to control how AI agents discover and use tools across enterprise systems, solving challenges like permissions, credentials management, and tool curation. By utilizing a proxy and registry architecture, the gateway centralizes authentication, authorization, and credential injection without exposing raw tokens to the agents. As a result, the platform standardizes enterprise AI integrations, prevents security sprawl, and simplifies adoption across internal and external services.

    DEPTH ■■■■■15 min read3 weeks ago

    Sign in to save and rate