/ THE FEED /

Read what ships.

Deep, recent reads ranked by depth and freshness.

  1. We gave AI agents a mobile dev environment

    Engineering teams outgrew their local machines while running parallel AI mobile development agents, constrained by heavy builds and lack of iOS tools on Linux. To solve this, they built Remote Dev using warm pools of remote Macs connected via SSH alongside separate Linux VMs for Android virtualization, paired with agent skills and live browser streaming. This setup shifted workflow bottlenecks, increasing AI-merged pull requests from 6 percent to 61 percent.

    DEPTH ■■■■■9 min read3 days ago

    ArchitectureMobile

    Sign in to save and rate

  2. PHP2Shell: GitLab helps find and remediate critical PHP flaws

    Critical remote code execution vulnerabilities known as PHP2Shell affect the PHP engine across multiple versions, requiring immediate runtime updates to fixed versions or patched distribution packages. The team utilized platform features like container scanning, code search, and automated agent workflows to locate PHP projects and remediate vulnerabilities. Operators must also check logs and environments for signs of compromise as framework updates and input validations cannot prevent these engine-level flaws.

    DEPTH ■■■■■10 min read3 days ago

    ArchitectureSecurity

    Sign in to save and rate

  3. Automate medical coding with Step Functions and Amazon Bedrock AgentCore

    Automating medical coding requires a hybrid approach that combines deterministic orchestration with bounded agentic reasoning to ensure safety, auditability, and human oversight. The team built a workflow using AWS Step Functions, AWS Lambda, and Amazon Bedrock AgentCore that evaluates terms cheapest-first via block-lists, exact matching, and finally an LLM agent for ambiguous cases. This design successfully autocodes confident cases while routing ambiguous ones to human reviewers with full audit trails and decision explanations.

    DEPTH ■■■■■15 min read4 days ago

    AWS

    Sign in to save and rate

  4. The bridge to agent-scale Git infrastructure

    GitHub faced infrastructure capacity limits and a 25ms cross-region network round trip when migrating repositories to Azure. The team changed the storage quorum from repository-wide locks to per-reference serialization and introduced ephemeral virtual replicas backed by object storage. This raised write throughput, prevented slow replicas from blocking traffic, and decoupled read scaling from the write quorum.

    DEPTH ■■■■■8 min read4 days ago

    Infrastructure

    Sign in to save and rate

  5. MCP standardized tools. Now we need the infrastructure around them.

    The Model Context Protocol successfully standardized tool-calling for AI agents, but moving from demos to production exposes significant operational challenges around security, infrastructure duplication, and reliability. Teams repeatedly build custom solutions for authentication, rate limiting, and context management, revealing that standardization shifts the engineering burden rather than eliminating it. Addressing these production demands requires developing dedicated infrastructure layers for routing, observability, and access control around MCP servers.

    DEPTH ■■■■■8 min read10 days ago

    Machine Learning

    Sign in to save and rate

  6. How Shopify turns open models into task experts

    Shopify uses a continual learning flywheel to post-train open models, such as NVIDIA Nemotron, to serve as dedicated subagents for specific tasks like GraphQL generation. By optimizing inference and utilizing automated self-healing to generate training data from production failures, the team successfully created task experts that outperform frontier models while reducing serving costs by 90-98% and improving response times.

    DEPTH ■■■■■5 min read4 days ago

    Architecture

    Sign in to save and rate

  7. From 2,500 requests to 24: Rebuilding star history without the stargazers

    GitHub faced abuse and performance issues because tools were scraping user identities to reconstruct repository star history. The engineering team collaborated with maintainers to build a purpose-built aggregate endpoint that returns daily star counts without identities and filters by time before aggregation. This reduced request volume from thousands to a few dozen and eliminated heavy database scans.

    DEPTH ■■■■■8 min read11 days ago

    Microservices

    Sign in to save and rate

  8. Multi-region disaster recovery for Amazon API Gateway WebSocket APIs

    Real-time applications using WebSocket connections face disruptions during regional AWS outages because connections are tied to specific regions. The team implemented an active-passive multi-region disaster recovery architecture using Route 53 DNS failover, DynamoDB Global Tables, an automated canary health probe, and client-side exponential backoff with jitter. This design automatically detects failures, redirects traffic, and restores client state without manual intervention.

    DEPTH ■■■■■10 min read11 days ago

    Sign in to save and rate

  9. Cross-store product clustering across millions of stores

    Shopify needed to group identical product listings from millions of different merchants under a single global identifier. To solve this at scale without comparing every possible pair, the team implemented a multi-stage pipeline using vector retrieval, a tiered scoring system of ML models, and a bounded graph clustering approach. This architecture successfully standardizes product data across the entire platform while controlling computational costs.

    DEPTH ■■■■■13 min read5 days ago

    Architecture

    Sign in to save and rate

  10. Make every AI credit count: See, cap, and reduce agent spend

    Uncontrolled AI agent spending can be mitigated by combining open-weight models, centralized context graphs to reduce retries, and usage analytics with credit caps. GitLab introduced these capabilities in its Duo Agent Platform to help platform teams trace, limit, and optimize AI credit consumption. The resulting architecture matches specific tasks to lower-cost models while maintaining task completion quality.

    DEPTH ■■■■■6 min read12 days ago

    Sign in to save and rate

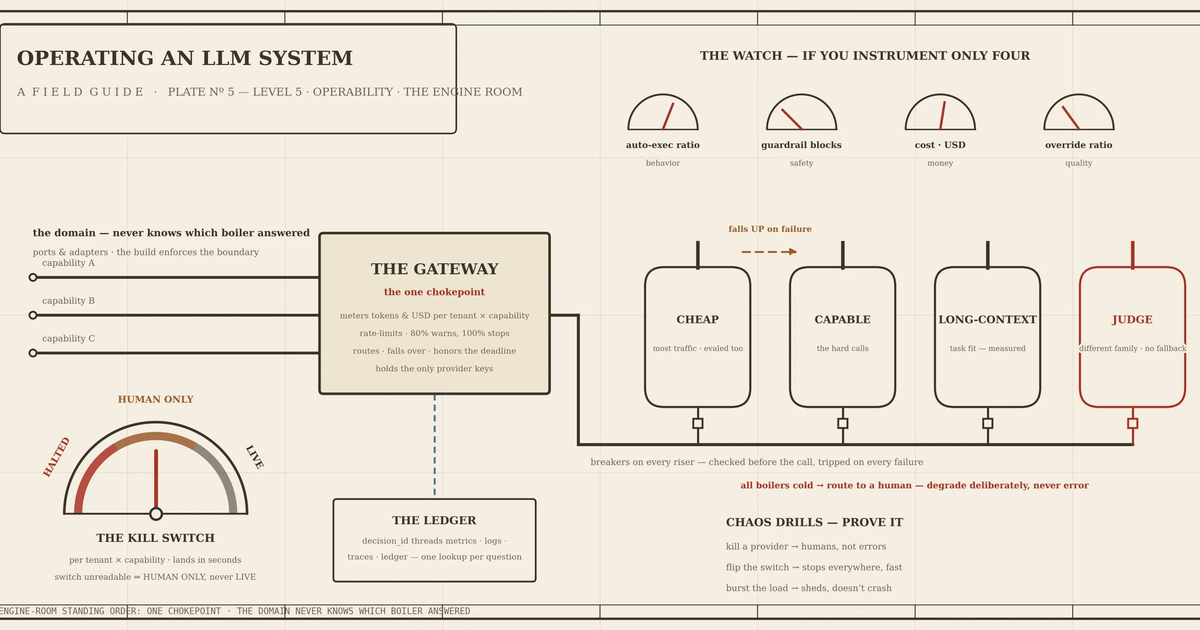
  11. Part 5: Operating an LLM system: observability, cost, routing, and the platform underneath

    This post provides a concrete specification for the operability layer of production LLM systems, covering observability signals, structured logging, cost controls, routing, and failover mechanisms. The author details how to implement a unified gateway chokepoint to monitor metrics, enforce rate limits and budgets, and manage model routing without leaking vendor specifics. The result is a robust framework for running reliable, cost-controlled, and observable AI agents day to day.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  12. How UTS established a modern curriculum data services foundation on AWS

    University of Technology Sydney rearchitected its curriculum data integration using serverless AWS services to decouple systems of record from downstream consumers. By implementing domain-driven design with an event-driven architecture and purpose-built persistence layers, the team achieved zero production incidents, low latency, and reduced operational overhead while managed by a single engineer.

    DEPTH ■■■■■9 min read11 days ago

    Sign in to save and rate

  13. Building Overexposed: understanding application exposure

    The team built an automated scanner called Overexposed to track internet-facing services and verify access controls across Kubernetes and Cloud Run. By querying live cloud inventories and probing endpoints like an outsider, the scanner classifies exposure while avoiding false assumptions from static config files. As a result, the engineering organization improved accuracy and significantly reduced inconclusive findings over time.

    DEPTH ■■■■■8 min read6 days ago

    Sign in to save and rate

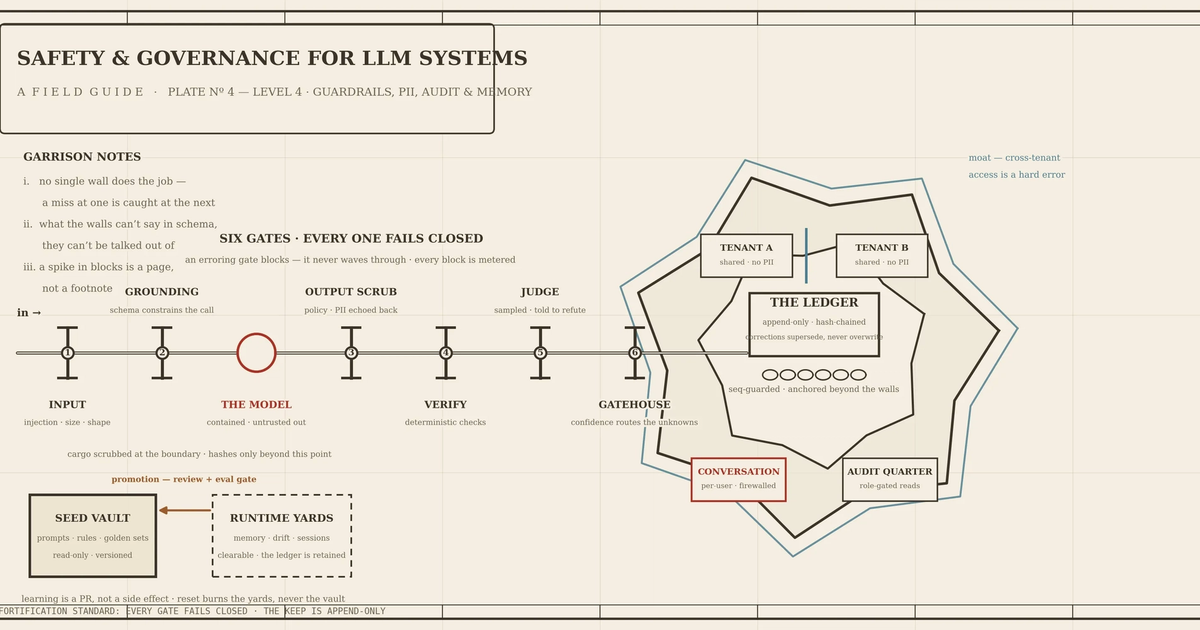
  14. Part 4: Safety and governance for LLM systems: guardrails, PII, audit, and memory

    This post details safety and governance practices for LLM systems, focusing on layered guardrails, boundary-level PII handling, and immutable audit trails. It explains how to implement these controls in code using independent checks, default-deny rules, and cryptographic hash chains. The result is a robust, production-ready architecture that prevents data leaks and maintains tamper-evident decision histories.

    DEPTH ■■■■■19 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  15. Scope workloads and share resilience policies with AWS Resilience Hub

    Engineering teams often struggle to scope workloads and maintain up-to-date resilience policies in shared Kubernetes clusters after migrations or deployments. AWS Resilience Hub introduced features enabling Kubernetes label-based resource scoping, generative AI-powered dependency insights, and cross-account resilience policy sharing via AWS Organizations. These capabilities allow teams to isolate specific workloads, prioritize dependency investigations, and enforce centralized recovery standards.

    DEPTH ■■■■■14 min read12 days ago

    Sign in to save and rate

  16. Building Git infrastructure for agent-scale development

    GitHub is redesigning its Git infrastructure to handle the massive surge in concurrent read and write operations driven by agentic software development and high-volume workloads. The team is decoupling storage from compute by leveraging Azure Blob Storage for durability and lightweight compute workers for requests, which separates scaling dimensions. In internal benchmarks, this approach achieves up to 35 times higher write throughput and independent read scalability.

    DEPTH ■■■■■9 min read2 weeks ago

    Infrastructure

    Sign in to save and rate

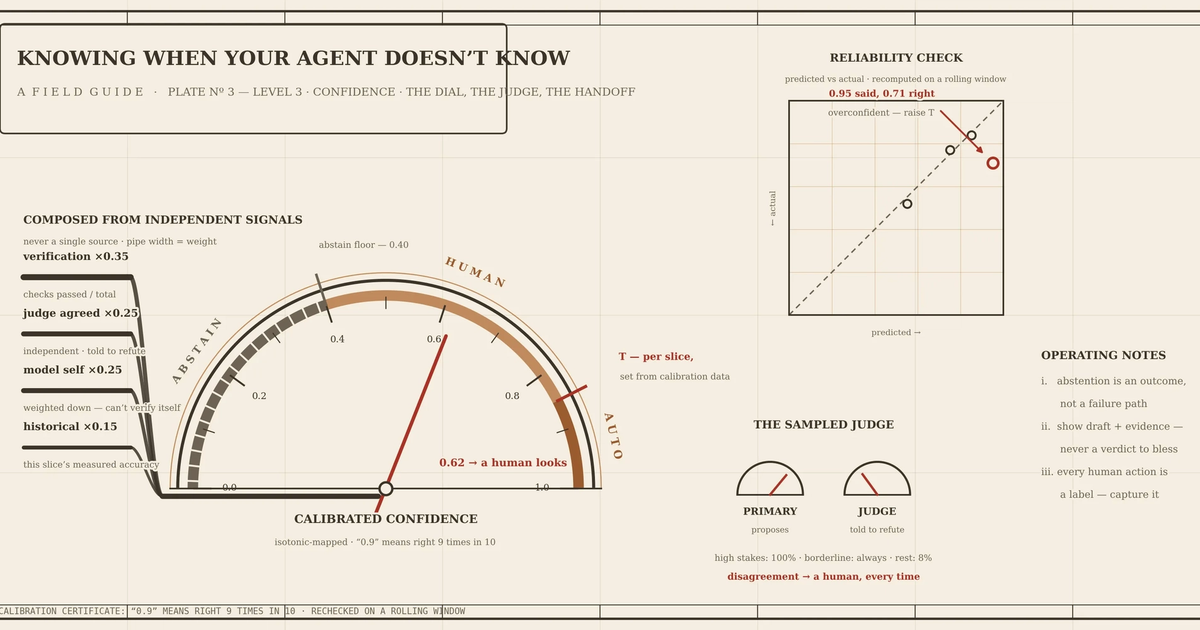
  17. Part 3: Knowing when your agent doesn’t know: the confidence layer

    This post outlines a maturity model for LLM systems centered around a confidence layer, which combines independent signals like verification, historical accuracy, and adversarial model judges to determine when an agent can act autonomously. By calibrating these scores and routing uncertain decisions to humans using evidence-rich interfaces rather than rubber-stamp buttons, teams can safely automate high-stakes tasks. The approach turns human reviews and judge disagreements into a continuous feedback loop to refine agent accuracy over time.

    DEPTH ■■■■■12 min read2 weeks ago

    Machine Learning

    Sign in to save and rate

  18. Stopping business email compromise with AI-driven email security: How VIPRE protects modern enterprises on AWS

    VIPRE developed an AI-driven, cloud-native email security solution on AWS to protect enterprises against business email compromise and advanced phishing attacks. The system uses layered machine learning, semantic analysis, and dynamic sandboxing orchestrated via serverless containers and message queues to evaluate over half a million messages daily. In production testing, the architecture successfully identified thousands of BEC attempts while maintaining low-latency processing and reducing administrative overhead.

    DEPTH ■■■■■12 min read12 days ago

    Sign in to save and rate

  19. Staying Evergreen: How we automated secure access and repo hygiene in a shared org

    Manual repository housekeeping and access reviews for outside collaborators become difficult to maintain as organizations scale. The team built Evergreen, a GitHub App that automates quarterly access reviews and stale repository archiving using native platform features and IssueOps. This automation successfully enforces secure defaults by revoking unanswered access while maintaining a full audit trail in git history.

    DEPTH ■■■■■8 min read10 days ago

    Sign in to save and rate

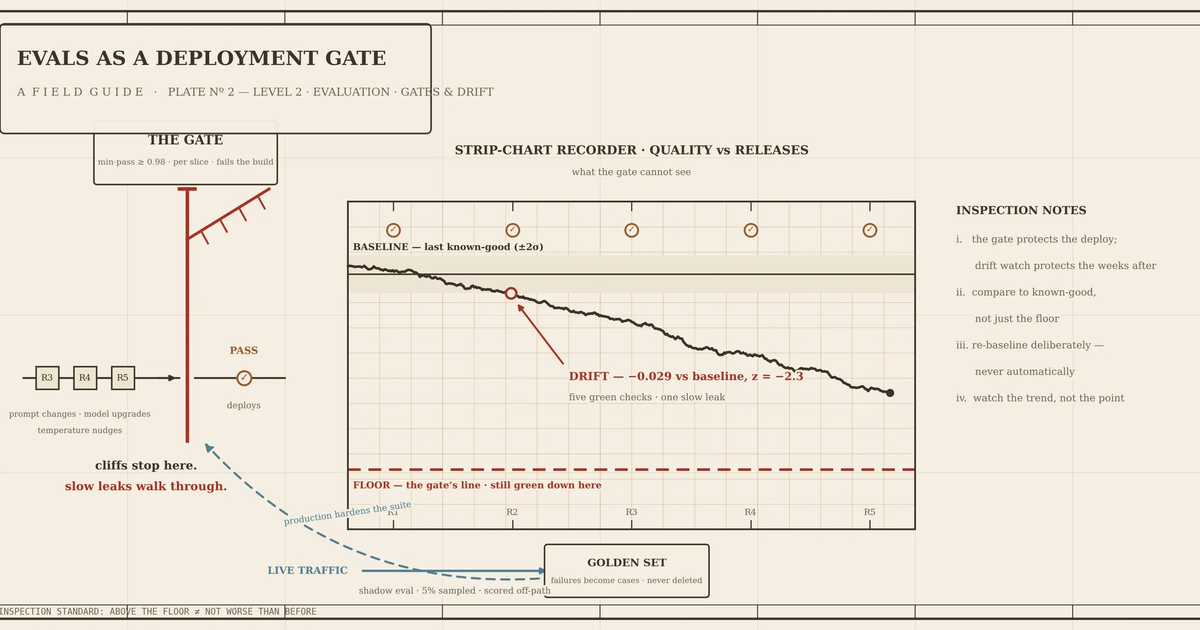
  20. Part 2: Evals as a deployment gate — and how to know when they drift

    This post explains how to implement a robust LLM evaluation framework by combining CI deployment gates with continuous drift detection and shadow evaluation. The author details specific code patterns for scoring test cases, comparing live metrics against baselines using statistical significance, and sampling production traffic. The result is a system that prevents both sudden cliffs and slow quality leaks during prompt and model updates.

    DEPTH ■■■■■8 min read2 weeks ago

    Machine Learning

    Sign in to save and rate